A worked example, generalization, and bias and variance
Last modified: 2026-10-28
biCrime = (await FileAttachment("data/crime.csv").csv({typed: true})).map((d) => [d.x, d.y])
// The simulated world of the bias-variance explorer, which needs a known true mean function:
// this function, plus Gaussian noise with standard deviation biSigma, on inputs in [0.05, 0.95].
biTruth = (x) => 0.55 - 0.9 * x + 0.6 * Math.sin(6 * x)
biSigma = 0.1
biXlo = 0.05
biXhi = 0.95
// The real data of the train, cross-validation and nearest-neighbour figures:
// the 392 cars of the Auto data, as (horsepower, mpg) pairs.
// Horsepower is rescaled to [0, 1], which the polynomial basis below assumes,
// and mpg is standardized to mean 0 and standard deviation 1,
// so that a squared error is a fraction of the variance of mpg.
// biHpAxis, biMpgAxis and biMpgUnits below turn both back into horsepower and mpg
// wherever a figure labels an axis or a number.
biAuto = FileAttachment("data/auto.csv").csv({typed: true})
biHpRange = d3.extent(biAuto, (d) => d.horsepower)
biMpgMean = d3.mean(biAuto, (d) => d.mpg)
biMpgSd = d3.deviation(biAuto, (d) => d.mpg)
biCars = biAuto.map((d) => [
(d.horsepower - biHpRange[0]) / (biHpRange[1] - biHpRange[0]),
(d.mpg - biMpgMean) / biMpgSd
])
// Axes in the original units, drawn on the scaled data.
// Every axis shows ticks in the units the variable was measured in,
// however the model is parametrized: the scaled value x sits at the tick
// labelled with its horsepower, and the standardized value y at its mpg.
biHpAxis = ({
label: "horsepower",
ticks: d3.range(50, biHpRange[1] + 1e-9, 50)
.map((hp) => (hp - biHpRange[0]) / (biHpRange[1] - biHpRange[0])),
tickFormat: (x) => Math.round(biHpRange[0] + x * (biHpRange[1] - biHpRange[0]))
})
biMpgAxis = ({
label: "mpg",
ticks: d3.range(10, 51, 10).map((mpg) => (mpg - biMpgMean) / biMpgSd),
tickFormat: (y) => Math.round(biMpgMean + y * biMpgSd)
})
// An RMSE in standardized units, converted to miles per gallon.
biMpgUnits = (v) => v * biMpgSd
// An interval printed as [lo, hi] in miles per gallon, to two decimals.
biFmtCIMpg = (ci) => `[${biMpgUnits(ci.lo).toFixed(2)}, ${biMpgUnits(ci.hi).toFixed(2)}]`
// n cars chosen at random as a training set, reproducibly from an integer seed;
// the held-out set is every car not chosen.
biCarSplit = (n, seed) => {
const order = d3.shuffler(d3.randomLcg(seed))(d3.range(biCars.length));
return {
train: order.slice(0, n).map((i) => biCars[i]),
held: order.slice(n).map((i) => biCars[i])
};
}
// An evenly spaced grid of horsepower values, for drawing curves over the cars.
biCarGrid = d3.range(0, 1 + 1e-9, 1 / 200)
// Least-squares polynomial of the given degree, returned as a function of x.
// The basis is Chebyshev polynomials of t = 2x - 1, and the system is solved by
// Householder QR, so degrees up to about 10 stay well conditioned on [0, 1].
biBasis = (x, degree) => {
const t = 2 * x - 1;
const row = [1, t];
for (let j = 2; j <= degree; j++) row.push(2 * t * row[j - 1] - row[j - 2]);
return row.slice(0, degree + 1);
}
// A degree of n - 1 or more interpolates n points, so it is capped there.
biPolyfit = (pts, deg) => {
const n = pts.length;
const degree = Math.min(deg, n - 1);
const p = degree + 1;
const a = pts.map(([x]) => biBasis(x, degree));
const b = pts.map(([, y]) => y);
for (let k = 0; k < p; k++) {
let norm = 0;
for (let i = k; i < n; i++) norm += a[i][k] ** 2;
norm = Math.sqrt(norm);
if (norm === 0) continue;
const alpha = a[k][k] > 0 ? -norm : norm;
const v = [];
for (let i = k; i < n; i++) v.push(a[i][k]);
v[0] -= alpha;
const vv = v.reduce((s, e) => s + e * e, 0);
if (vv === 0) continue;
for (let j = k; j < p; j++) {
let s = 0;
for (let i = k; i < n; i++) s += v[i - k] * a[i][j];
for (let i = k; i < n; i++) a[i][j] -= 2 * v[i - k] * s / vv;
}
let s = 0;
for (let i = k; i < n; i++) s += v[i - k] * b[i];
for (let i = k; i < n; i++) b[i] -= 2 * v[i - k] * s / vv;
}
const c = new Array(p).fill(0);
for (let k = p - 1; k >= 0; k--) {
let s = b[k];
for (let j = k + 1; j < p; j++) s -= a[k][j] * c[j];
c[k] = a[k][k] === 0 ? 0 : s / a[k][k];
}
return (x) => biBasis(x, degree).reduce((s, e, j) => s + e * c[j], 0);
}
// Mean squared error of a prediction function h on a set of points.
biMse = (h, pts) => d3.mean(pts, ([x, y]) => (h(x) - y) ** 2)
// A 95% confidence interval for the risk of h (its mean squared error over the population),
// from the squared errors of h on points it was not fitted to.
// By the central limit theorem the mean of n squared errors is close to normal,
// with standard error sd / sqrt(n), so the interval is the mean plus or minus 1.96 standard errors.
// The held-out sets here have at least 190 cars, so 1.96 stands in for the t quantile.
// It is not meant for points the model was fitted to, whose errors are not independent draws.
biMseCI = (h, pts) => {
const errs = pts.map(([x, y]) => (h(x) - y) ** 2);
const m = d3.mean(errs);
const half = 1.96 * d3.deviation(errs) / Math.sqrt(errs.length);
return {mean: m, lo: m - half, hi: m + half};
}
// The root mean squared error (RMSE) of h on a set of points, in the units of the response,
// and the same interval as biMseCI with its endpoints square-rooted.
biRmse = (h, pts) => Math.sqrt(biMse(h, pts))
biRmseCI = (h, pts) => {
const ci = biMseCI(h, pts);
return {mean: Math.sqrt(ci.mean), lo: Math.sqrt(Math.max(ci.lo, 0)), hi: Math.sqrt(ci.hi)};
}
// The RMSE interval for a short list of squared errors, one per case, by the percentile bootstrap:
// resample the errors with replacement 1,000 times, take the root of each resample's mean,
// and keep the 2.5th and 97.5th percentiles of those roots.
// Cross-validation uses it on the held-out squared errors, one per point.
// With so few skewed errors, the interval 1.96 standard errors either side of the mean
// can reach below zero, which a root mean squared error cannot do; the bootstrap never does.
// The seed fixes the resamples, so the interval does not change when the page redraws.
biRmseCIBoot = (sq, seed = 1) => {
const rand = d3.randomLcg(seed);
const n = sq.length;
const roots = d3.range(1000).map(() =>
Math.sqrt(d3.mean(d3.range(n), () => sq[Math.floor(rand() * n)])));
roots.sort(d3.ascending);
return {mean: Math.sqrt(d3.mean(sq)), lo: d3.quantileSorted(roots, 0.025),
hi: d3.quantileSorted(roots, 0.975)};
}
// Print an interval as [lo, hi] to four decimals.
biFmtCI = (ci) => `[${ci.lo.toFixed(4)}, ${ci.hi.toFixed(4)}]`
// Tick marks for a log axis: the powers of ten from lo to hi, printed in plain
// decimals (0.001, 1,000), never in scientific notation.
// Plot's default log ticks label every minor tick, which crowds a short axis.
biPow10 = (lo, hi) => d3.range(Math.round(Math.log10(lo)), Math.round(Math.log10(hi)) + 1)
.map((e) => 10 ** e)
biExp = (v) => d3.format(",.8~f")(v)Source
Adapted from Brian Hutchinson’s Fall 2025 lecture notes, which supplied the crime-and-income example, the five data points, the generalization argument and the bias-variance decomposition. The figure the notes marked draw figure is Figure 1; the two the notes marked plot are Figure 7 and Figure 9. Every fitted coefficient printed here is computed on the page from those same five points, and tools/make_big_ideas_figures.py fits the curves in the figures from them too. Logan Sizemore’s Spring 2025 lecture on generalization is the basis of the cross-validation section. The contrast between stochastic and deterministic noise follows the treatment of overfitting in Abu-Mostafa et al. [1, Ch. 4]; the example and its numbers are new.
The bias-variance derivation is rewritten to assume only that the noise has mean zero, finite variance, and is independent of the training set, where the notes assumed it Gaussian; see Theorem 6. The wider reading is Hastie et al. [2], Chapter 2, and James et al. [3], Chapter 2.
Course Overview is the companion chapter and comes first: it asks what machine learning is and defines the vocabulary, where this one asks how one concrete instance of it works. Where the two meet, this page recaps with a short exercise and links back to the definition.
Exercise 1 (The parts of a learning system)
Exercise 1 (The parts of a learning system) Course Overview named the parts every learning system has. Without looking back, name them, and say which step happens once and which happens every time the system is used.
Solution 1. Figure 1 draws them. The training data go into a learning algorithm (the figure’s training algorithm), and running it, training, produces the model \(\modmem\). The model then maps each new input \(x\) to a prediction \(\modmemf{x}\).
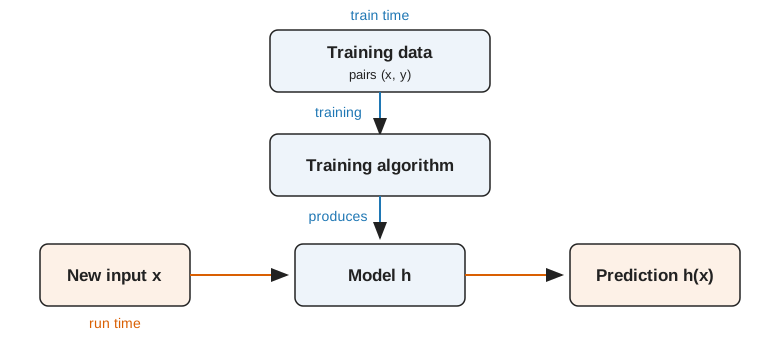
Training, the blue arrows, happens once, at train time. Prediction, the orange arrows, happens every time the system is used, at run time. The difference matters for cost: a cost paid at train time is paid once, and a cost paid at run time is paid on every prediction forever.
We work with a data set, which the statistics notes define as \(n\) pairs of an input vector and its outcome. They also define its input matrix \(\mpredvar\), whose rows are the input vectors, and its outcome vector \(\voutvar\), whose entries are the outcomes. As that page notes, the “set” in training set, validation set and test set is short for a subset of the data set.
Remark 1 (The data set in matrix form)
Remark 1 (The data set in matrix form). Row \(i\) of \(\mpredvar\) and entry \(i\) of \(\voutvar\) together are the \(i\)-th pair of the data set, so \(\mpredvar\) and \(\voutvar\) hold the same information as \(\dataset\) in a tabular form.
Example 1 (The Auto data as an input matrix)
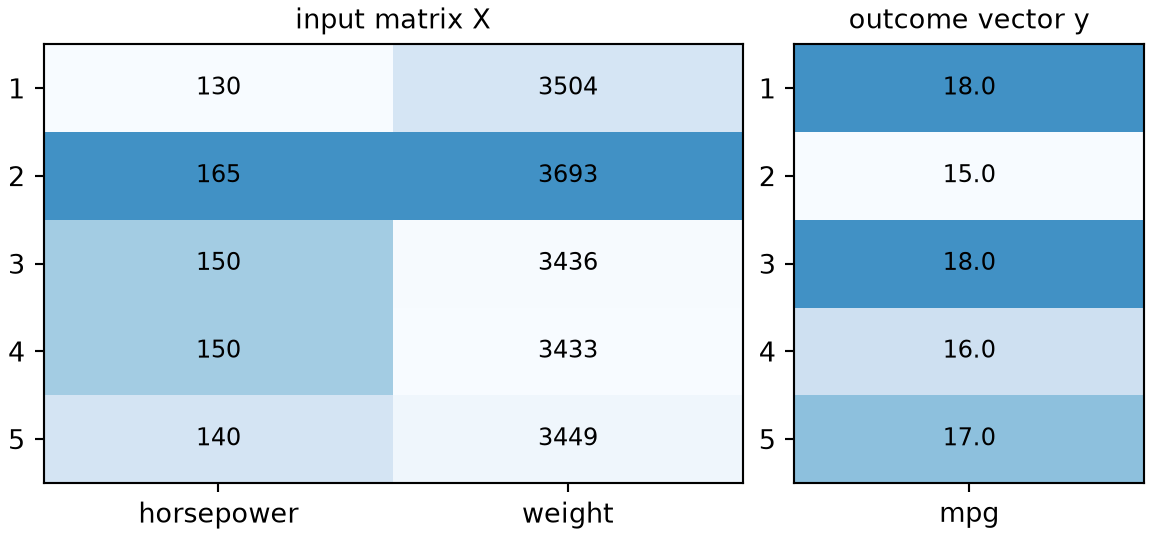
Example 1 (The Auto data as an input matrix) Take the first five cars of the Auto data [3], with horsepower and weight as the \(\ninputvars = 2\) inputs and miles per gallon (mpg) as the outcome. Then \(\mpredvar\) has five rows and two columns, and \(\voutvar\) has five entries.
# Build the input matrix and outcome vector from the first five cars with a recorded horsepower.
import numpy as np
import pandas as pd
auto_five = pd.read_csv("data/auto.csv").dropna(subset=["horsepower"]).iloc[:5]
X_data = auto_five[["horsepower", "weight"]].to_numpy(dtype=float)
y_data = auto_five["mpg"].to_numpy(dtype=float)
print(X_data.shape, y_data.shape)(5, 2) (5,)
Figure 2 draws the two arrays side by side. Row \(i\) of the left array and entry \(i\) of the right array are the same car.
import matplotlib.pyplot as plt
def show_array(ax, values, col_labels, title, fmt):
"""Draw a small array as a grid of cells, printing each value inside its cell."""
# Shade each column on its own scale, because horsepower and weight differ by orders of magnitude.
scaled = (values - values.min(axis=0)) / np.ptp(values, axis=0)
ax.imshow(scaled, cmap="Blues", aspect="auto", vmin=0, vmax=1.6);
for i in range(values.shape[0]):
for j in range(values.shape[1]):
ax.text(j, i, fmt.format(values[i, j]), ha="center", va="center", fontsize=9);
ax.set_xticks(range(len(col_labels)), col_labels);
ax.set_yticks(range(values.shape[0]), [f"{i + 1}" for i in range(values.shape[0])]);
ax.set_title(title, fontsize=10);
fig, axes = plt.subplots(
1, 2, figsize=(6, 2.8), layout="constrained",
gridspec_kw={"width_ratios": [2, 1]},
)
show_array(axes[0], X_data, ["horsepower", "weight"], "input matrix X", "{:.0f}")
show_array(axes[1], y_data.reshape(-1, 1), ["mpg"], "outcome vector y", "{:.1f}")
plt.show()The first car, for example, has input vector \(\vpredvar_1 = (130, 3504)\) and outcome \(\outvar_1 = 18\), and these fill the first row of the matrix and the first entry of the vector.
Definition 1 (Parameter (weight, coefficient))
Definition 1 (Parameter (weight, coefficient)) A parameter of a prediction function family is a number that identifies one member of the family.
Other names: parameters are also called weights, and the parameters of a linear model are also called coefficients.
Example 2 (The parameters of a line)
Example 2 (The parameters of a line) The straight line \(\modmemf{x} = mx + b\) has two parameters, the slope \(m\) and the intercept \(b\). Each pair of values for \(m\) and \(b\) picks out exactly one line.
Remark 2 (Training chooses the parameters)
Remark 2 (Training chooses the parameters). Training chooses the values of the parameters.
Definition 2 (Training set)
Definition 2 (Training set) Given a data set \(\dataset\) of \(n\) pairs, a training set is the subset of \(\dataset\) whose pairs are indexed by a set \(\trainidx \subseteq \set{1, \ldots, n}\) to which we apply the fitting procedure, that is, the pairs from which the model’s parameters are estimated [4]:
\[ \trainset \eqdef \set{(\vpredvar_i, \outvar_i) : i \in \trainidx} \subseteq \dataset . \tag{1}\]
Example 3 (Estimating a crime rate from income)
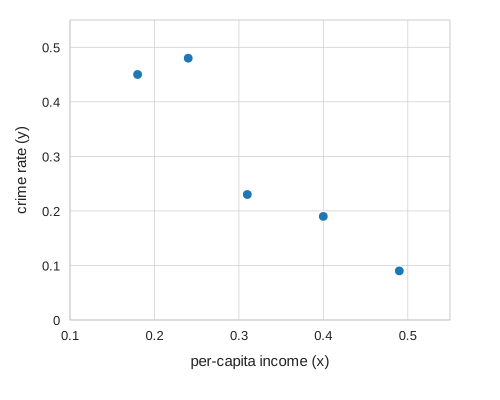
Example 3 (Estimating a crime rate from income) Suppose a city wants to estimate the crime rate in a neighbourhood from that neighbourhood’s per-capita income. An estimate would help it send police, outreach and services before the need appears in the data rather than after.
The city’s data form a labelled data set of \(n\) pairs, written
\[ \dataset = \set{ \paren{\predvar_1, \outvar_1}, \ldots, \paren{\predvar_n, \outvar_n} } \]
and here \(n = 5\). Until we hold some pairs out, all of them form the training set, so \(\trainset = \dataset\):
| per-capita income \(x\) | crime rate \(y\) |
|---|---|
| 0.49 | 0.09 |
| 0.18 | 0.45 |
| 0.31 | 0.23 |
| 0.40 | 0.19 |
| 0.24 | 0.48 |
Exercise 2 (What has the city already decided?)
Exercise 2 (What has the city already decided?) Before any model is fitted, the city’s setup has already made several choices that are not facts about the world. Name three, and say what each one rules out or risks.
Solution 2.
The goal is prediction, not description. We are not asking whether income causes crime, and nothing in this chapter justifies that interpretation. James et al. [3], Section 2.1.1, makes the same distinction between prediction and inference.
Income is the only input. It is almost certainly not the best one, and the model can only be as good as what it is shown.
The city sampled five neighbourhoods. Five is a small number, and most of what goes wrong in this chapter goes wrong because of it.
Exercise 3 (What kind of task is this?)
Exercise 3 (What kind of task is this?) The outputs in Table 1 are crime rates. Say whether this is a regression task or a classification task, and say what about the table settles it.
Solution 3. Regression. The column of outputs holds numbers on a continuous scale, and the quantity we want back from the model is a number of the same kind. Had the city instead sorted neighbourhoods into “high” and “low” crime, the same five neighbourhoods would have posed a classification task.
The split is about the output, not about the inputs and not about the method. The inputs here are numbers too, and that is irrelevant; classification problems routinely have numeric inputs.
Exercise 4 (Propose a model)
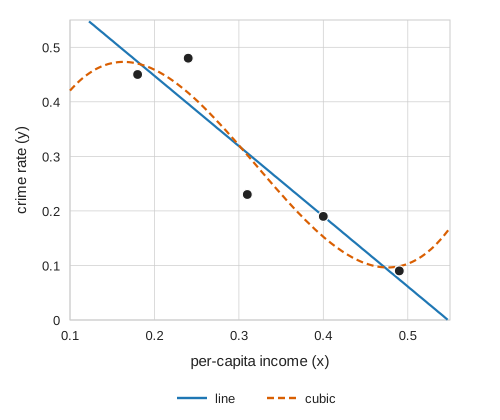
Exercise 4 (Propose a model) Look at Figure 3. Propose a family of functions \(\modmem\) to predict \(y\) from \(x\), and say how many numbers have to be chosen to specify one member of your family.
Solution 4. The five points fall roughly along a line, so a reasonable family is the straight lines
\[ \modmemf{x} = mx + b \]
and two numbers identify exactly one: the slope \(m\) and the intercept \(b\).
Nothing yet says which \(m\) and \(b\) to pick; The next section, “Measuring how well a model fits”, starts on that.
Definition 3 (Mean-function model family)
Definition 3 (Mean-function model family) A mean-function model family is a set of mean functions that training chooses from. It is defined in the notes on model validation.
Example 4 (The family of straight lines)
Example 4 (The family of straight lines) The straight lines
\[ \modmemf{x} = mx + b \tag{2}\]
form a mean-function model family, one line for each choice of the slope \(m\) and the intercept \(b\). Training on the five points picks one line from this family. No member of the family can bend, so a curved pattern in the data is out of its reach.
Definition 4 (Parametric model)
Definition 4 (Parametric model) A parametric model is a model family described by a fixed, finite list of parameters (Definition 1), whose length does not depend on the number of training points \(n\) [5].
Example 5 (A line keeps two numbers however many cars it sees)
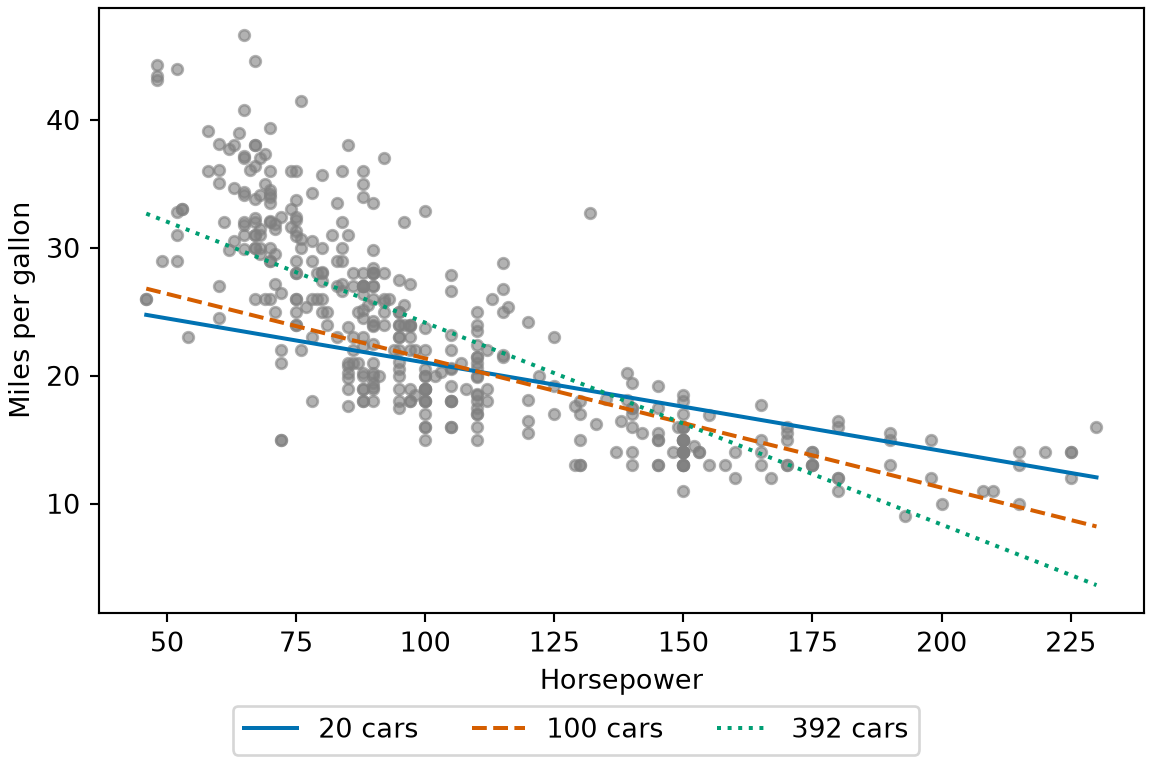
Example 5 (A line keeps two numbers however many cars it sees) In the Auto data [3], fit the straight line of mpg on horsepower (Equation 2) to the first 20, the first 100 and then all 392 cars. Count the parameters of the fitted model each time:
import numpy as np
import pandas as pd
auto_pm = pd.read_csv("data/auto.csv").dropna(subset=["horsepower"])
hp_pm = auto_pm["horsepower"].to_numpy(float)
mpg_pm = auto_pm["mpg"].to_numpy(float)
# np.polyfit returns the slope and the intercept: the line's whole description.
for n_pm in (20, 100, 392):
coef_pm = np.polyfit(hp_pm[:n_pm], mpg_pm[:n_pm], 1)
print(n_pm, len(coef_pm), coef_pm.round(3))20 2 [-0.069 27.936]
100 2 [-0.101 31.46 ]
392 2 [-0.158 39.936]
20 100 392
(Intercept) 27.936 31.460 39.936
horsepower -0.069 -0.101 -0.158
With 20 cars the slope is -0.069 miles per gallon per horsepower, and with all 392 it is -0.158. The values of the parameters change with the data, but the model keeps 2 of them whether it was fit to 20 cars or to 392. That fixed length makes the family of lines parametric (Definition 4).
library(ggplot2)
pmf_n <- c(20, 100, 392)
pmf_lines <- data.frame(
cars = factor(pmf_n),
intercept = fits_pm[1, ],
slope = fits_pm[2, ]
)
ggplot(auto_pm, aes(horsepower, mpg)) +
geom_point(colour = "grey60", alpha = 0.6) +
geom_abline(
data = pmf_lines,
aes(intercept = intercept, slope = slope, colour = cars, linetype = cars)
) +
scale_colour_manual(values = c("20" = "#0072B2", "100" = "#D55E00", "392" = "#009E73")) +
scale_linetype_manual(values = c("20" = "solid", "100" = "dashed", "392" = "dotted")) +
labs(x = "Horsepower", y = "Miles per gallon", colour = "Cars used", linetype = "Cars used")import matplotlib.pyplot as plt
import numpy as np
fig, ax = plt.subplots(figsize=(6, 4), layout="constrained")
ax.plot(hp_pm, mpg_pm, color="grey", marker="o", linestyle="", alpha=0.6, markersize=4);
grid_pmf = np.array([hp_pm.min(), hp_pm.max()])
for n_pmf, colour, style in [(20, "#0072B2", "-"), (100, "#D55E00", "--"), (392, "#009E73", ":")]:
slope_pmf, intercept_pmf = np.polyfit(hp_pm[:n_pmf], mpg_pm[:n_pmf], 1)
ax.plot(grid_pmf, intercept_pmf + slope_pmf * grid_pmf, color=colour, linestyle=style,
label=f"{n_pmf} cars");
ax.set_xlabel("Horsepower");
ax.set_ylabel("Miles per gallon");
fig.legend(loc="outside lower center", ncol=3);
plt.show()Example 6 (Straight lines are a parametric model)
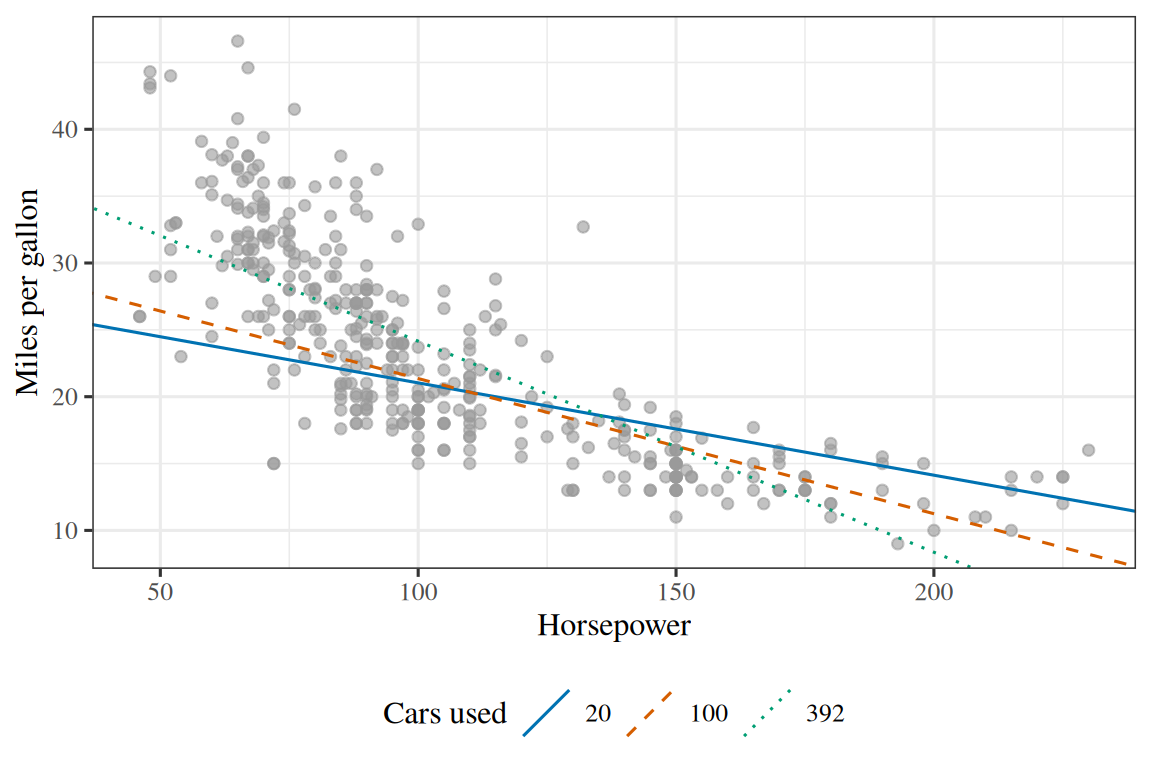
Example 6 (Straight lines are a parametric model) The straight lines of Equation 2 form a parametric model with two parameters.
Exercise 5 (What should a loss function do?)
Exercise 5 (What should a loss function do?) A loss function \(L(y, \hy)\) takes the true value \(y\) and a prediction \(\hy\) and returns one number saying how bad that prediction was. Before choosing a formula, decide what the formula has to satisfy.
Name two properties any such function needs, and for each one, name what goes wrong without it.
Solution 5. It is never negative. Without that, errors in opposite directions cancel in the average, and a model can get a lower loss for being wrong in the other direction. A signed error \(\hy - y\) does not satisfy this: a model that overshoots one point by 10 and undershoots the next by 10 averages to zero, which is the score a perfect model gets.
It is zero exactly when the prediction is right. Without that, “smaller is better” no longer has its usual meaning, and a perfect prediction can cost more than an imperfect one.
Two functions satisfy both:
\[ L_{2}(y, \hy) \eqdef (y - \hy)^2 \qquad\text{and}\qquad L_{1}(y, \hy) \eqdef \abs{ y - \hy } \tag{3}\]
We use squared error, \(L_2\), throughout this chapter. It has a third property the other lacks, and that property is about solving the problem rather than about stating it: squared error is differentiable everywhere, while absolute error has no derivative at the one point where the prediction is exact. The methods that search for a minimum step by step, starting with Gradient Descent, need that derivative.
Definition 5 (Loss function)
Definition 5 (Loss function) A loss function \(\lossf{y, \hy}\) takes the true value \(y\) and a prediction \(\hy\) and returns a number, never negative, saying how bad that prediction was [7].
Remark 3 (Which properties a loss needs, and what a loss scores)
Remark 3 (Which properties a loss needs, and what a loss scores). The two losses of Equation 3 also have the second property of Solution 5: they are zero exactly when \(\hy = y\). The definition of a loss function asks only for the first, because some losses later in these notes do not have the second: the hinge loss is zero for every score beyond the margin, and the log loss is never exactly zero.
A loss scores one prediction. For the \(i\)-th example, that prediction is the fitted value \(\hy_i = \modmemf{x_i}\), the value the model \(\modmem\) returns at \(x_i\), so the example’s loss is \(L(y_i, \hy_i)\). Other sources call an average of losses over many examples the cost or the objective.
# HTML formats get an interactive plotly figure (hover for values, click the
# legend to hide a curve); the handout and other formats get the same curves
# as a static SVG from tools/make_big_ideas_figures.py.
if (knitr::is_html_output()) {
library(plotly)
# Squared error and absolute error on a grid of errors.
error <- seq(-2, 2, length.out = 401)
widget <- plot_ly() |>
add_trace(
x = error, y = error^2, type = "scatter", mode = "lines",
name = "squared error", line = list(color = "#1f77b4")
) |>
add_trace(
x = error, y = abs(error), type = "scatter", mode = "lines",
name = "absolute error", line = list(color = "#d95f02", dash = "dash")
) |>
layout(
xaxis = list(title = "prediction minus truth"),
yaxis = list(title = "loss", range = c(0, 4)),
legend = list(orientation = "h", y = -0.2),
margin = list(t = 10)
) |>
config(displaylogo = FALSE, responsive = TRUE)
# The alt text: a plotly widget has none of its own.
htmltools::div(
role = "img",
`aria-label` = paste(
"Interactive plot of squared error and absolute error against the error.",
"Both are zero only at zero error; squared error is a smooth U and",
"absolute error is a V with a corner at zero."
),
widget
)
} else {
knitr::include_graphics("../images/big-ideas/losses.svg")
}Exercise 6 (Who chooses the loss?)
Exercise 6 (Who chooses the loss?) A frost alarm predicts, each evening, whether tonight will freeze. A false alarm (predict frost, no frost comes) costs one unit, the price of lighting the heaters. A missed frost (predict no frost, frost comes) costs a different amount that depends on what is growing. Over 100 evenings, 10 of which had frost, two alarms scored as follows:
| Alarm | Frosts caught | False alarms |
|---|---|---|
| Cautious | 10 of 10 | 20 of 90 |
| Relaxed | 6 of 10 | 5 of 90 |
A commercial orchard loses 50 units to a missed frost. A balcony gardener loses 2. Compute the total cost of each alarm for each owner.
Solution 6. Each alarm’s cost is its missed frosts times the miss cost plus its false alarms times one. The Cautious alarm misses none; the Relaxed alarm misses four.
import pandas as pd
# Counts from the table: [missed frosts, false alarms] for each alarm.
mistakes_wc = pd.DataFrame({"Cautious": [10 - 10, 20], "Relaxed": [10 - 6, 5]},
index=["missed", "false alarm"])
# The only thing that differs between owners is the cost of a missed frost;
# a false alarm costs 1 for both.
miss_cost_wc = {"Orchard": 50, "Balcony": 2}
costs_wc = pd.DataFrame({
owner: mistakes_wc.loc["missed"] * miss + mistakes_wc.loc["false alarm"] * 1
for owner, miss in miss_cost_wc.items()
})
print(costs_wc) Orchard Balcony
Cautious 20 20
Relaxed 205 13
# Counts from the table: missed frosts and false alarms for each alarm.
missed_wc <- c(Cautious = 10 - 10, Relaxed = 10 - 6)
false_alarms_wc <- c(Cautious = 20, Relaxed = 5)
# The only thing that differs between owners is the cost of a missed frost;
# a false alarm costs 1 for both.
miss_cost_wc <- c(Orchard = 50, Balcony = 2)
costs_wc <- sapply(miss_cost_wc, function(miss) missed_wc * miss + false_alarms_wc * 1)
costs_wc Orchard Balcony
Cautious 20 20
Relaxed 205 13
The orchard prefers the Cautious alarm, at 20 units to the Relaxed alarm’s 205. The balcony gardener prefers the Relaxed alarm, at 13 units to the Cautious alarm’s 20.
Exercise 7 (Who chooses the loss? (part 2))
Exercise 7 (Who chooses the loss? (part 2)) Use the setup of Exercise 6.
The two owners rank the alarms differently. What does that say about who should pick the loss function for a model that makes this prediction?
Solution 7. The two alarms and their predictions are the same for both owners, so the ranking cannot be a fact about the alarms. It comes from the costs, which belong to whoever lives with the mistakes. That is why a loss function is something the user sets: the formula should say how much each kind of mistake matters in the application, and only the user knows that. Accuracy, which counts a missed frost and a false alarm alike, would pick the Relaxed alarm for both owners (91 correct nights against 80), which is the right answer for the balcony and a costly one for the orchard.
Definition 6 (Plausible loss)
Definition 6 (Plausible loss) A loss function is plausible for a model of the data when it follows from an assumption about how the data arise: minimizing it gives the maximum likelihood fit under that assumption.
Example 7 (Squared error is plausible under Gaussian noise)
Example 7 (Squared error is plausible under Gaussian noise) Suppose the noise terms \(\noise\) of Equation 20 are independent across observations, each with a Gaussian distribution with mean zero and variance \(\varpar\). The negative log-likelihood of the observations is then the sum of their squared errors divided by \(2 \varpar\), plus a constant that does not depend on the model. Minimizing the squared error therefore gives the maximum likelihood fit, so squared error is plausible under this assumption. For a binary outcome modelled as conditionally Bernoulli, the same maximum-likelihood argument yields the log loss.
Definition 7 (Friendly loss)
Definition 7 (Friendly loss) A loss function is friendly for a model family when the model that minimizes it can be found reliably and cheaply.
Example 8 (Squared error and convex losses are friendly)
Example 8 (Squared error and convex losses are friendly) For a linear model, squared error has a closed-form solution, so no search is needed. More generally, every local minimum of a convex loss is a global one, so gradient descent cannot get stuck at a worse model. Both cases are friendly in the sense of Definition 7.
Remark 4 (When nobody specifies the loss)
Remark 4 (When nobody specifies the loss). Often the user cannot say what each mistake costs, or the costs are unknown when the model is fitted. Two other reasons then decide the loss: a plausible loss matches an assumption about the data, and a friendly loss is easy to optimize. Squared error is both, for the reasons in Example 7 and Example 8. A loss chosen for these reasons is a convenience, not a statement of what the errors cost, so it is worth checking the finished model against the costs that matter (Exercise 6).
This follows the discussion of error measures in Abu-Mostafa et al. [1, Ch. 1].
Exercise 8 (Score a model on data it has not seen)
Exercise 8 (Score a model on data it has not seen) The loss function scores a model on one pair at a time. A model is useful only if it also does well on points it has not seen. Suppose a new input–output pair \((X, Y)\) is drawn at random from the same population that produced the training data.
For a fixed model \(\modmem\), write the average loss that \(\modmem\) would incur over all such new pairs, as an expectation.
Solution 8. Average the loss over the distribution \(P(\predvar, \outvar)\) of inputs and outputs in the population:
\[ \Ep_{(\Predvar, \Outvar)} \sb{ \lossf{\Outvar, \modmemf{\Predvar}} } . \]
Exercise 9 (Score a model on data it has not seen (part 2))
Exercise 9 (Score a model on data it has not seen (part 2)) Use the setup of Exercise 8.
Which parts of your expression do you know, and which do you not know?
Solution 9. The loss function \(L\) is known, because we chose it, and the model \(\modmem\) is known, because we fitted it. The distribution \(P(\predvar, \outvar)\) is unknown, so the expectation cannot be computed. If we knew \(P(\predvar, \outvar)\), we would not need data to build a model.
Definition 8 (Risk (expected loss, population risk, true risk, generalization error, expected prediction error))
Definition 8 (Risk (expected loss, population risk, true risk, generalization error, expected prediction error)) The risk of a model \(\modmem\) is its expected loss (Definition 5) on a new input–output pair \((X, Y)\) drawn from the joint distribution \(P(x, y)\) of the population:
\[ \popriskf{\modmem} \eqdef \Ep_{(X, Y)} \sb{ \lossf{Y, \modmemf{X}} } . \tag{4}\]
Other names: the risk is also called the expected loss, the population risk, the true risk, or the generalization error. The Elements of Statistical Learning calls it the expected prediction error [2, Sec. 2.4].
Example 9 (Fitting a line to the crime data)
Example 9 (Fitting a line to the crime data) Fitting a line to the crime data, for example, is an attempt to pick the line \(\modmem\) whose squared error on neighbourhoods we have not yet seen is small on average.
Remark 5 (The risk cannot be computed)
Remark 5 (The risk cannot be computed). The risk cannot be computed, because it needs the distribution the data came from, which we do not know. It can only be estimated from the data in hand.
The risk measures how well a model predicts neighbourhoods outside the sample.
Every method in these notes tries to make \(\popriskf{\modmem}\) small.
The probability notes define risk for a prediction \(\hy\), which can be a constant or a function of \(X\). Here \(\hy = \modmemf{X}\).
Definition 9 (Empirical risk)
Definition 9 (Empirical risk) The empirical risk of a model \(\modmem\) on a data set \(\dataset\) is the average loss of \(\modmem\)’s predictions over the \(n\) pairs \((x_{(i)}, y_{(i)})\) of \(\dataset\):
\[ \empriskf{\modmem; \dataset} \eqdef \avgin \lossf{y_{(i)}, \modmemf{x_{(i)}}} . \tag{5}\]
Remark 6 (The empirical risk names its data set)
Remark 6 (The empirical risk names its data set). In the empirical risk, \(\dataset\) can be any data set: the training set the fitted model was fitted to, or data that played no part in the fit. The same model has a different empirical risk on each, so the notation always names the set.
Definition 10 (Training error)
Definition 10 (Training error) The training error [2, Sec. 7.2] of a model \(\modmem\) is its empirical risk on the training set, \(\empriskf{\modmem; \trainset}\).
See training error in the statistics notes.
Example 10 (Two models, scored on the same five neighbourhoods)
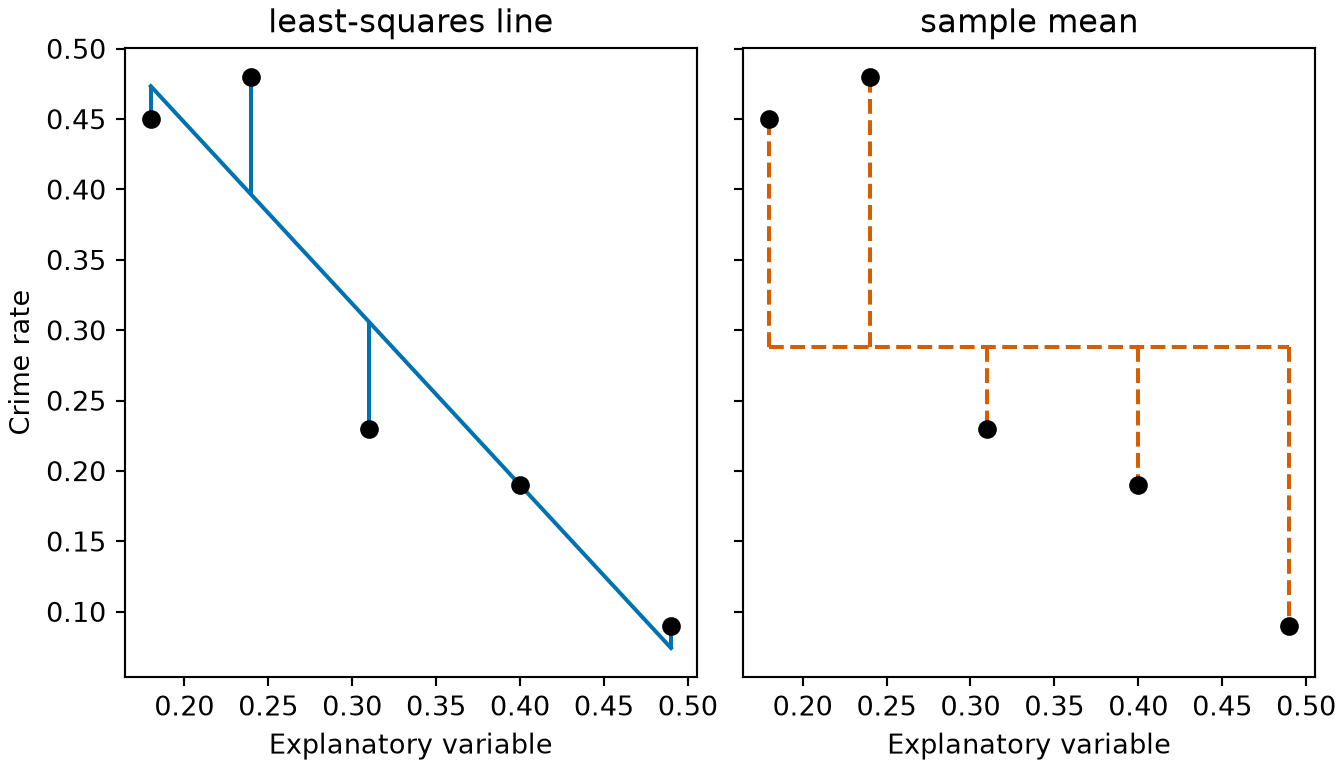
Example 10 (Two models, scored on the same five neighbourhoods) Score two models on the five neighbourhoods of Table 1 under squared error: the least-squares line, and the constant that always predicts the sample mean crime rate.
import numpy as np
# The five neighbourhoods of the crime table, read once in the first example.
x = crime["x"].to_numpy()
y = crime["y"].to_numpy()
m, b = np.polyfit(x, y, 1)
emprisk_line = np.mean((m * x + b - y) ** 2)
emprisk_const = np.mean((y.mean() - y) ** 2)
print(round(emprisk_line, 6), round(emprisk_const, 6))0.002721 0.023056
The line’s empirical risk is \(0.002721\) and the constant’s is \(0.023056\). The line scores better on these five neighbourhoods. Both models were fitted to them, so these are training errors, and the line fits the training set better. It says nothing yet about neighbourhoods outside the sample, which the risk (Definition 8) measures.
library(ggplot2)
erf_fit <- lm(y ~ x, data = crime)
erf_levels <- c("least-squares line", "sample mean")
erf_models <- data.frame(
model = factor(erf_levels, levels = erf_levels),
intercept = c(coef(erf_fit)[[1]], mean(crime$y)),
slope = c(coef(erf_fit)[[2]], 0)
)
erf_points <- merge(crime, erf_models)
erf_points$predicted <- erf_points$intercept + erf_points$slope * erf_points$x
ggplot(erf_points, aes(x, y)) +
geom_abline(
data = erf_models,
aes(intercept = intercept, slope = slope, colour = model, linetype = model)
) +
geom_segment(aes(xend = x, yend = predicted, colour = model, linetype = model)) +
geom_point(size = 2.5) +
facet_wrap(vars(model)) +
scale_colour_manual(values = c("least-squares line" = "#0072B2", "sample mean" = "#D55E00")) +
scale_linetype_manual(values = c("least-squares line" = "solid", "sample mean" = "dashed")) +
guides(colour = "none", linetype = "none") +
labs(x = "Explanatory variable", y = "Crime rate")import matplotlib.pyplot as plt
import numpy as np
x_erf = crime["x"].to_numpy()
y_erf = crime["y"].to_numpy()
m_erf, b_erf = np.polyfit(x_erf, y_erf, 1)
grid_erf = np.array([x_erf.min(), x_erf.max()])
fig, axes = plt.subplots(1, 2, figsize=(7, 4), sharey=True, layout="constrained")
for ax, title, colour, style, intercept, slope in [
(axes[0], "least-squares line", "#0072B2", "-", b_erf, m_erf),
(axes[1], "sample mean", "#D55E00", "--", y_erf.mean(), 0),
]:
predicted = intercept + slope * x_erf
ax.plot(grid_erf, intercept + slope * grid_erf, color=colour, linestyle=style);
ax.vlines(x_erf, predicted, y_erf, color=colour, linestyle=style);
ax.plot(x_erf, y_erf, color="black", marker="o", linestyle="");
ax.set_title(title);
ax.set_xlabel("Explanatory variable");
axes[0].set_ylabel("Crime rate");
plt.show()Remark 7 (Empirical risk estimates the risk)
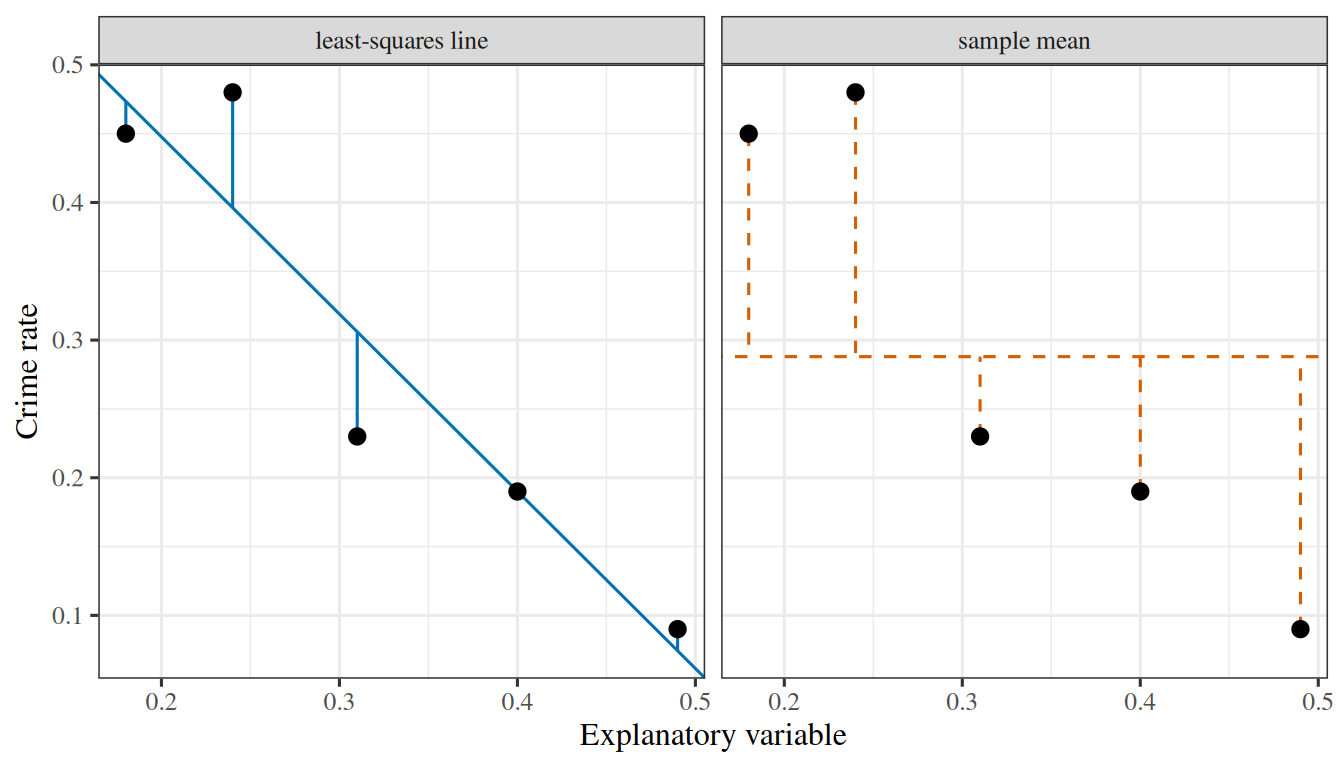
Remark 7 (Empirical risk estimates the risk). The empirical risk has a hat because it estimates the risk \(\popriskf{\modmem}\) of Equation 4 from the sample at hand: the sample average replaces the expectation. That average is over the empirical distribution of the pairs in the data set, which is what “empirical” refers to. On the training set the estimate tends to be too optimistic, because the model was fitted to those very pairs; Section 3 estimates the risk from pairs held out of the fit. Exercise 10, below, works the case of squared error and five points.
Unlike the risk, the empirical risk can be computed, because it needs only the data in hand and not the distribution they came from.
Theorem 1 (Under squared-error loss, the empirical risk is the sample mean squared error (sMSE))
Theorem 1 (Under squared-error loss, the empirical risk is the sample mean squared error (sMSE)) Let \(\lossf{\outvar, \eoutvar} = \sqf{\err}\) be the squared-error loss of Equation 3, where \(\err = \eoutvar - \outvar\) is the prediction error. For every model \(\modmem\) and every training set \(\trainset\) of \(n\) pairs, the empirical risk of \(\modmem\) on \(\trainset\) equals the sample mean squared error (sMSE) of \(\modmem\)’s predictions on \(\trainset\):
\[ \empriskf{\modmem; \trainset} = \sMSE{\modmem; \trainset} . \tag{6}\]
Proof
Proof. The empirical risk of Equation 5 is the average loss over the pairs of \(\trainset\). For example \(i\), the prediction error is \(\err_{(i)} = \modmemf{\predvar_{(i)}} - \outvar_{(i)}\). Substituting the squared-error loss into that average gives
\[ \empriskf{\modmem; \trainset} = \avgin \sqf{\err_{(i)}} . \]
The sMSE is the average of the squared differences between each label and its prediction, which are the squared prediction errors. The right-hand side above is exactly that average.
Example 11 (The empirical risk and the sMSE of the least-squares line agree)
Example 11 (The empirical risk and the sMSE of the least-squares line agree) Compute the empirical risk of the least-squares line of Example 10 two ways: by averaging the squared-error loss example by example, and by applying the sMSE formula to the vector of residuals.
import numpy as np
# The five neighbourhoods of the crime table, read once in the first example.
x = crime["x"].to_numpy()
y = crime["y"].to_numpy()
m, b = np.polyfit(x, y, 1)
# Empirical risk: average the loss of each example separately.
def squared_error(y_true, y_pred):
return (y_true - y_pred) ** 2
emprisk_by_loss = np.mean([squared_error(y_i, m * x_i + b) for x_i, y_i in zip(x, y)])
# MSE: square the residual vector, then average.
residuals = y - (m * x + b)
mse_by_residuals = np.sum(residuals ** 2) / len(y)
print(round(emprisk_by_loss, 6), round(mse_by_residuals, 6))0.002721 0.002721
The two computations give \(0.002721\) and \(0.002721\), as Theorem 1 says they must. They differ only in how the arithmetic is organized.
Definition 11 (Empirical risk minimization)
Definition 11 (Empirical risk minimization) Empirical risk minimization is choosing the \(\modmem\) that makes the empirical risk smallest [8].
Exercise 10 (Score a whole model, not one prediction)
Exercise 10 (Score a whole model, not one prediction) Equation 3 scores one prediction. Write an expression that scores a candidate \(\modmem\) against the whole training set \(\trainset\) of Table 1, using squared error.
Solution 10. Average the loss over the training points. That average is the empirical risk (Definition 9):
\[ \empriskf{\modmem; \trainset} \eqdef \avgin \lossf{y_{(i)}, \modmemf{x_{(i)}}} = \frac{1}{5} \sumto{i}{5} \paren{\modmemf{x_{(i)}} - y_{(i)}}^2 \tag{7}\]
Exercise 11 (Score a whole model, not one prediction (part 2))
Exercise 11 (Score a whole model, not one prediction (part 2)) Use the setup of Exercise 10.
Say which symbols in your expression are fixed and which are free to vary.
Solution 11. The \(x_{(i)}\) and \(y_{(i)}\) are fixed: they are the data, and they do not change. What can vary is \(\modmem\) — and since Equation 2 says \(\modmem\) is fixed by \(m\) and \(b\), Equation 7 is a function of those two numbers alone. Writing it that way turns the modelling question into an optimization problem:
\[ \hat{m}, \hat{b} \eqdef \argmin_{m, b} \empriskf{\modmem; \trainset} \tag{8}\]
These notes call solving Equation 8 training the model, also called learning.
Exercise 12 (Score a whole model, not one prediction (part 3))
Exercise 12 (Score a whole model, not one prediction (part 3)) Use the setup of Exercise 10.
Compare your expression with the risk of Equation 4. What does it use in place of the expectation?
Solution 12. Compared with the risk of Equation 4, the empirical risk replaces the expectation over \(P(x, y)\) with an average over the \(n\) points of \(\trainset\). Those points are the only draws from \(P(x, y)\) that we have.
Watch
Hutchinson works one example in which a model, a loss and the empirical risk appear, Machine Learning Example (21 min) [9]. The video site requires a login, which enrolled students find in the syllabus.
Read
GeeksforGeeks explains:
Exercise 13 (Fit the line)
Exercise 13 (Fit the line) Solve Equation 8 for the five points of Table 1.
You do not need to do it by hand: every language these notes use has a least-squares routine. Report \(\hat{m}\), \(\hat{b}\), and the empirical risk the fitted line achieves.
Hint
In Python, numpy.polyfit(x, y, 1). In R, lm(y ~ x).
Solution 13.
Both return the same fit,
\[ \emodmemf{x} = -1.2877\,x + 0.7052 \tag{9}\]
at an empirical risk of \(0.002721\). Figure 9 draws it.
# The empirical risk of the line m x + b on a grid of slopes and intercepts,
# for the five neighbourhoods the chapter fits. Both drawings below read it.
# The five neighbourhoods of @tbl-crime-data, read once in @exm-crime-task.
x <- crime$x
y <- crime$y
m_grid <- seq(-2.4, -0.2, by = 0.04)
b_grid <- seq(0.35, 1.05, by = 0.02)
risk_of <- function(m, b) mean((m * x + b - y)^2)
risk <- outer(m_grid, b_grid, Vectorize(risk_of))
# The least-squares line, the lowest point of the surface.
fit <- lm(y ~ x)
best_m <- coef(fit)[["x"]]
best_b <- coef(fit)[["(Intercept)"]]
best_risk <- risk_of(best_m, best_b)
# The levels of the contour lines, the same on the surface and in the plot.
levels <- c(0.004, 0.012, 0.030, 0.060, 0.100)# The 3D surface of the empirical risk. HTML formats get an interactive plotly
# widget; the handout and other formats get the same surface from persp().
# The handout hides this code (echo above): a figure with its listing inside is
# taller than a page, and LaTeX then drops the float. The website folds it.
# Contour lines at the levels of the 2D plot below, drawn on the surface.
# contourLines() traces each level; NA rows separate the separate curves.
curves <- contourLines(m_grid, b_grid, risk, levels = levels)
lines <- do.call(rbind, lapply(curves, function(curve) {
n <- length(curve$x)
data.frame(
m = c(curve$x, NA), b = c(curve$y, NA), risk = c(rep(curve$level, n), NA)
)
}))
if (knitr::is_html_output()) {
library(plotly)
# What a hover shows, for the surface and for the minimum.
hover <- paste0(
"slope m: %{x:.3f}<br>intercept b: %{y:.3f}",
"<br>empirical risk: %{z:.4f}<extra></extra>"
)
widget <- plot_ly() |>
add_surface(
x = m_grid, y = b_grid, z = t(risk), colorscale = "YlGnBu",
colorbar = list(title = "empirical risk", len = 0.7),
hovertemplate = hover
) |>
add_trace(
data = lines, x = ~m, y = ~b, z = ~risk,
type = "scatter3d", mode = "lines",
line = list(color = "#222222", width = 3), hoverinfo = "skip"
) |>
add_trace(
x = best_m, y = best_b, z = best_risk,
type = "scatter3d", mode = "markers",
marker = list(
size = 6, color = "#d95f02", line = list(color = "#ffffff", width = 1)
),
hovertemplate = sub("<extra></extra>", "<extra>minimum</extra>", hover)
) |>
layout(
showlegend = FALSE,
margin = list(l = 0, r = 0, t = 0, b = 0),
paper_bgcolor = "rgba(0,0,0,0)",
scene = list(
xaxis = list(title = "slope m"), yaxis = list(title = "intercept b"),
zaxis = list(title = "empirical risk"),
camera = list(eye = list(x = 1.5, y = -1.7, z = 0.9))
)
) |>
config(displaylogo = FALSE, responsive = TRUE)
# The alt text: a plotly widget has none of its own.
htmltools::div(
role = "img",
`aria-label` = paste(
"Interactive 3D surface of the empirical risk over the slope and the",
"intercept, a bowl with contour lines and one lowest point marked in",
"orange. Drag to rotate and scroll to zoom."
),
widget
)
} else {
# persp() returns the matrix that maps a point of the surface to the page,
# which trans3d() applies to the contour lines and the minimum.
z_hi <- 0.55
shade <- colorRampPalette(c("#ffffcc", "#41b6c4", "#253494"))(50)
# Colour each facet by the mean risk at its four corners.
nr <- length(m_grid)
nc <- length(b_grid)
corner_mean <- (risk[-nr, -nc] + risk[-1, -nc] + risk[-nr, -1] + risk[-1, -1]) / 4
facet_col <- shade[cut(corner_mean, 50, labels = FALSE)]
par(mar = c(0, 0, 0, 0))
view <- persp(
m_grid, b_grid, pmin(risk, z_hi), zlim = c(0, z_hi), col = facet_col,
border = NA, theta = 55, phi = 32, expand = 0.7, ticktype = "detailed", nticks = 4, cex.axis = 0.7,
xlab = "slope m", ylab = "intercept b", zlab = "empirical risk"
)
segments_xy <- trans3d(lines$m, lines$b, pmin(lines$risk, z_hi), view)
lines(segments_xy, col = "#222222", lwd = 1.5)
points(trans3d(best_m, best_b, best_risk, view), pch = 21, bg = "#d95f02", col = "white", cex = 1.8)
}# The same contours in 2D: each blue curve joins the lines with one
# empirical risk, and they close in on the least-squares line (orange).
par(mar = c(4.2, 4.2, 2.2, 1))
contour(
m_grid, b_grid, risk,
levels = levels, col = "#1f77b4", lwd = 1.3,
xlab = "slope m", ylab = "intercept b", drawlabels = FALSE
)
points(best_m, best_b, pch = 21, bg = "#d95f02", col = "white", cex = 1.8)
mtext(
sprintf("minimum (orange): m = %.2f, b = %.2f", best_m, best_b),
side = 3, col = "#d95f02"
)Exercise 14 (Read the surface)
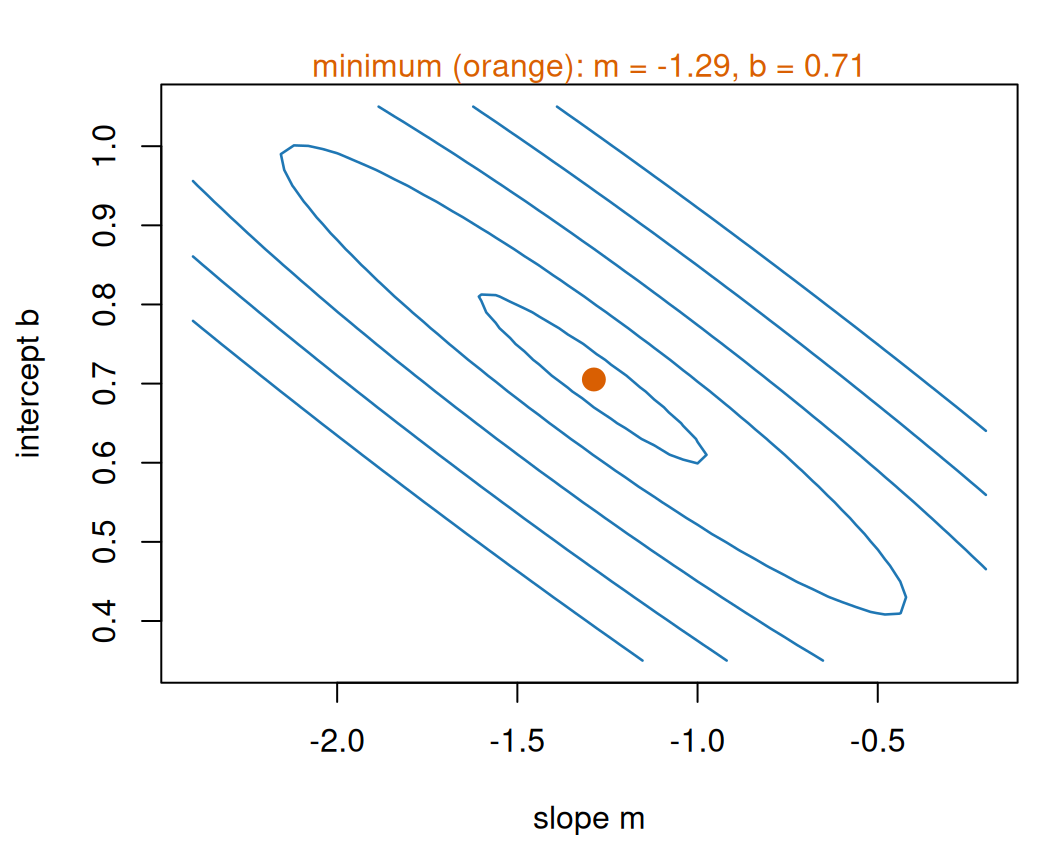
Exercise 14 (Read the surface) Equation 8 asks for the lowest point of a surface. For the straight lines of Equation 2 that surface is plotted over two axes, \(m\) and \(b\), and Figure 7 draws it.
How many points on the surface are lower than every other point?
Solution 14. One. The contours shrink to a single point, and every straight-line slice through that point has its minimum there too. That point has lower risk than every other point in the whole plane, so it is the surface’s global minimizer, and \((\hat{m}, \hat{b})\) in Equation 8 is the single element of the argmin.
Exercise 15 (Read the surface (part 2))
Exercise 15 (Read the surface (part 2)) Use the setup of Exercise 14.
Would a search for the lowest point give a different answer depending on where it started?
Solution 15. No: the surface has no other local minimizer that a search could stop at, so wherever a search starts it ends at the same point. So both languages in Solution 13 agree without anyone choosing a starting guess.
reRisk = (m, b) => biMse((x) => m * x + b, biCrime)
// The least-squares line, for the checkbox that reveals it.
reBest = {
const xm = d3.mean(biCrime, (d) => d[0]);
const ym = d3.mean(biCrime, (d) => d[1]);
const m = d3.sum(biCrime, ([x, y]) => (x - xm) * (y - ym)) /
d3.sum(biCrime, ([x]) => (x - xm) ** 2);
return {m, b: ym - m * xm};
}
reShowBest = reShow.includes("least-squares line")Slide the line in Figure 8 until its empirical risk is as small as you can make it, and watch the dot on the contour map move as you go.
Plot.plot({
ariaLabel: 'The five neighbourhoods, crime rate against per-capita income, ' +
'with the chosen line drawn in blue ' +
'and a red segment from each point to the line showing its residual.',
width: 300, height: 280, grid: true,
x: {domain: [0, 0.6], label: "per-capita income x"},
y: {domain: [-0.2, 0.8], label: "crime rate y"},
marks: [
Plot.link(biCrime, {x1: (d) => d[0], y1: (d) => d[1], x2: (d) => d[0],
y2: (d) => reM * d[0] + reB, stroke: "#d62728", strokeWidth: 2}),
Plot.line([0, 0.6], {x: (x) => x, y: (x) => reM * x + reB, stroke: "#1f77b4",
strokeWidth: 2.5, clip: true}),
reShowBest ? Plot.line([0, 0.6], {x: (x) => x, y: (x) => reBest.m * x + reBest.b,
stroke: "#555", strokeDasharray: "5,4", clip: true}) : null,
Plot.dot(biCrime, {x: (d) => d[0], y: (d) => d[1], r: 5, fill: "#222"})
]
})Plot.plot({
ariaLabel: 'Contour map of the empirical risk over the slope m and the intercept b, ' +
'darker where the risk is smaller, ' +
'with a dot at the chosen line.',
width: 300, height: 280, marginLeft: 45,
x: {domain: [-3, 0.5], label: "slope m"},
y: {domain: [0, 1.2], label: "intercept b"},
color: {type: "log", scheme: "YlGnBu", reverse: true, label: "empirical risk", legend: true,
ticks: [0.01, 0.1, 1], tickFormat: (v) => String(v)},
marks: [
Plot.contour({x1: -3, y1: 0, x2: 0.5, y2: 1.2, fill: reRisk,
thresholds: d3.range(-2.2, 0.01, 0.2).map((e) => 10 ** e),
stroke: "#fff", strokeOpacity: 0.4}),
reShowBest ? Plot.dot([reBest], {x: "m", y: "b", r: 6, symbol: "cross",
stroke: "#d62728", strokeWidth: 2.5}) : null,
Plot.dot([0], {x: reM, y: reB, r: 5, fill: "#222", stroke: "#fff"})
]
})Exercise 16 (Now fit a cubic)
Exercise 16 (Now fit a cubic) Nothing in Equation 5 mentions straight lines. Repeat Exercise 13 with the cubic polynomial
\[ \modmemf{x} = m_3 x^3 + m_2 x^2 + m_1 x + b \tag{10}\]
and report its empirical risk beside the line’s.
Then continue: fit polynomials of degree 2 and 4 as well, and tabulate degree, number of parameters, and empirical risk.
Solution 16. Change one argument, and run it over a range of values:
import numpy as np
# The five neighbourhoods of the crime table, read once in the first example.
x = crime["x"].to_numpy()
y = crime["y"].to_numpy()
for degree in (1, 2, 3, 4):
coeffs = np.polyfit(x, y, degree)
risk = np.mean((np.polyval(coeffs, x) - y) ** 2)
print(degree, degree + 1, round(risk, 6))1 2 0.002721
2 3 0.002608
3 4 0.002234
4 5 0.0
# The Python fits again, kept for the equation, the table and the prose.
fits = {degree: np.polyfit(x, y, degree) for degree in (1, 2, 3, 4)}
risks = [float(np.mean((np.polyval(fits[d], x) - y) ** 2)) for d in (1, 2, 3, 4)]
cubic = [float(c) for c in fits[3]]
quartic_max_resid = float(np.max(np.abs(np.polyval(fits[4], x) - y)))risks <- py$risks
cubic <- py$cubic
# A signed term of the fitted polynomial, for display math: "- 23.6095\,x^2".
term <- function(coef, power) {
sign <- if (coef < 0) "-" else "+"
x <- c("", "\\,x", "\\,x^2", "\\,x^3")[power + 1]
sprintf("%s %.4f%s", sign, abs(coef), x)
}
e6 <- function(v) sprintf("%.6f", v)
risk_cut <- round(100 * (1 - risks[3] / risks[1]))
# The quartic's risk prints as 0.000000 at six decimals; check that its
# largest residual is below the last printed place, so the table's zero is honest.
max_resid <- py$quartic_max_resid
stopifnot(max_resid < 1e-6)The cubic comes out at
\[ \emodmemf{x} = 24.6063\,x^3 - 23.6095\,x^2 + 5.7443\,x + 0.0576 \tag{11}\]
and the four fits compare like this:
| degree | parameters | empirical risk |
|---|---|---|
| 1 | 2 | 0.002721 |
| 2 | 3 | 0.002608 |
| 3 | 4 | 0.002234 |
| 4 | 5 | 0.000000 |
Two things in Table 2 are worth examining closely.
Among the fits that do not pass through every point, the cubic has the lowest risk, but it improves on the line by very little: \(0.002234\) against \(0.002721\) is a reduction of 18%, obtained by using twice as many parameters. Figure 9 shows what that 18% looks like.
The quartic has the lowest risk, scoring exactly zero. That is not a good model; it is five parameters fitted to five points, so it passes through every one of them by construction and would do so whatever the numbers had been.
Watch
Hastie and Tibshirani compare structured and flexible models [6], video 2.2.
Raise the degree in Figure 10 and watch the empirical risk fall.
Plot.plot({
ariaLabel: 'The five neighbourhoods, crime rate against per-capita income, ' +
'with the least-squares polynomial of the chosen degree drawn through them.',
width: 300, height: 260, grid: true,
x: {domain: [0.1, 0.55], label: "per-capita income x"},
y: {domain: [-0.2, 0.8], label: "crime rate y"},
marks: [
Plot.line(d3.range(0.1, 0.5501, 0.0025), {x: (x) => x, y: deFit.h,
stroke: "#1f77b4", strokeWidth: 2.5, clip: true}),
Plot.dot(biCrime, {x: (d) => d[0], y: (d) => d[1], r: 5, fill: "#222"})
]
})Plot.plot({
ariaLabel: 'Empirical risk of the least-squares fit for each degree from 0 to 4, ' +
'on a log scale, as bars, with the chosen degree highlighted.',
width: 260, height: 260, marginLeft: 80,
x: {label: "degree", type: "band"},
y: {type: "log", domain: [1e-8, 0.1], label: "empirical risk (log scale)",
ticks: biPow10(1e-8, 0.1), tickFormat: biExp},
marks: [
Plot.barY(deFits, {x: "degree", y1: 1e-8, y2: (d) => Math.max(d.risk, 1e-8),
fill: (d) => d.degree === deDegree ? "#ff7f0e" : "#9ecae1"}),
Plot.text(deFits.filter((d) => d.risk < 1e-8), {x: "degree", y: 1e-8, text: () => "0",
dy: -8, fontWeight: "bold"})
]
})Exercise 17 (Which model was actually better?)
Exercise 17 (Which model was actually better?) Table 2 ranks the four fits, and the quartic comes first. Say why that ranking is not a reason to prefer it, and name what you would have to measure instead.
Solution 17. Because the ranking is computed on the very points the models were fitted to. Any flexibility a model has can be used to fit those points closely, so Equation 5 rewards flexibility and accuracy alike and does not distinguish them. The quartic makes that visible by reaching zero: with as many parameters as data points it interpolates, and interpolation is available to it regardless of whether the data has any pattern at all.
What we want is the loss on points the model has not seen. That quantity is the risk (Definition 8), and it can only ever be estimated; Section 3 says how.
Every honest estimate of it rests on data held out of the fitting.
Definition 12 (Interpolation)
Example 12 (The quartic passes through all five neighbourhoods)
Example 12 (The quartic passes through all five neighbourhoods) Predict the five neighbourhoods of Table 1 with the quartic of Table 2, and compare each prediction with the observed crime rate.
[0.09 0.45 0.23 0.19 0.48]
[0.09 0.45 0.23 0.19 0.48]
The two rows agree, and the largest residual is 8.7e-14, which is floating-point rounding error. The quartic has five parameters, and the five neighbourhoods have distinct inputs, so it can pass through all of them: it interpolates the training set, and its training error under squared-error loss is zero. The line, the quadratic and the cubic have positive training errors in Table 2, so none of them interpolates.
Exercise 18 (What we made easy)
Exercise 18 (What we made easy) We took three easy steps in the crime example: we found the lowest point of the risk surface, we chose a model family, and we scored the fitted models. For each step, say what about this example made it easy for us, and what would make it hard on a larger problem.
Solution 18. We made each step easy on purpose, and later chapters remove each simplification.
We found the minimum exactly. We can minimize a paraboloid by solving a linear system. We cannot do that for a neural network’s risk surface, so we reduce the risk step by step instead. That is why the derivative of the loss matters so much. Gradient Descent starts on that.
We chose the model by eye. Five points and one input let us look at the scatter plot. With many inputs there is nothing to look at, so we have to argue for the choice of family and then check it.
We computed the score on the training data. Solution 17 says why that is not a measurement of anything we care about. Section 3 says what to do instead.
Watch
Hutchinson covers generalization, bias, variance and overfitting, Generalization (31 min) [9].
Definition 13 (Objective function (objective, cost function))
Definition 13 (Objective function (objective, cost function)) An objective function, or objective for short [13, Sec. 1.1] and 4.1, is the quantity a training procedure minimizes (or maximizes) as the model’s parameters vary. It is a function of the parameters alone, with the data held fixed. For a model \(\modmemof{\param}\) with parameters \(\param\) and a training set \(\trainset\), the objective that is the empirical risk (Equation 5) is
\[ J(\param) \eqdef \empriskf{\modmemof{\param}; \trainset} , \tag{12}\]
and training minimizes \(J(\param)\) over \(\param\).
Other names: the objective is also called the cost function, though that name is also used for the loss and for the empirical risk, so it identifies nothing on its own.
Example 13 (The objective as a function of the slope and intercept)
Example 13 (The objective as a function of the slope and intercept) For the crime data of Table 1, the objective is the empirical risk as a function of the pair \((m, b)\).
[1] 0.023056 0.002721
The flat line \((m, b) = (0, \bar y)\) has objective value \(0.023056\), and the least-squares pair \((\hat m, \hat b) = (-1.2877, 0.7052)\) has the smaller value \(0.002721\). Training searches over \((m, b)\) for the pair with the smallest value.
Remark 8 (The empirical risk is one objective among many)
Remark 8 (The empirical risk is one objective among many). So far the only objective in these notes is the empirical risk, which Equation 8 minimizes over the slope and intercept. Later chapters change the objective without changing the loss: whatever is handed to the optimizer is the objective, and the empirical risk is only one thing it can be made from.
Exercise 19 (Estimate what cannot be computed)
Exercise 19 (Estimate what cannot be computed) Equation 4 cannot be evaluated and Equation 5 can. Solution 17 rules out reporting the second in place of the first.
Describe a procedure that uses only the available data and returns an honest estimate of Equation 4, and say what the procedure costs.
Solution 19. Set some data aside. Split \(\trainset\) before fitting anything; fit on one part; score on the other. The scored part played no role in choosing the model’s parameters, so its average loss is an unbiased estimate of Equation 4: over repeated draws of the held-out points, it equals the risk on average, neither systematically above nor below.
The cost is the data itself. Points moved into the held-out set are points the model never learns from, so the model is worse than it needed to be, and the estimate depends on however few points were set aside and is noisy in proportion.
The usual arrangement is three sets rather than two:
A training set (Definition 2), which the fitting procedure sees.
A validation set (Definition 14; also called a development or dev set), scored repeatedly while choosing between models, tuning their settings, and deciding when to stop.
A test set (Definition 16), scored exactly once, at the end, on the model finally chosen. It stays unused until then.
The third set exists because of what the second one does. A validation set consulted a hundred times is a set a hundred decisions have been fitted to, and its score stops being honest about a model those decisions selected. Section 3.1 covers what to do when there is not enough data for all three.
Example 14 (Splitting the Auto data)
Example 14 (Splitting the Auto data) Split the cars of the Auto data [3] at random, 60% for training, 20% for validation and the rest for testing.
# Draw the three index sets from one shuffled list of cars, so that they cannot overlap.
import numpy as np
import pandas as pd
auto_split = pd.read_csv("data/auto.csv").dropna(subset=["horsepower"])
n_cars = len(auto_split)
shuffled = np.random.default_rng(571).permutation(n_cars)
n_train = int(0.6 * n_cars)
n_val = int(0.2 * n_cars)
idx_train = shuffled[:n_train]
idx_val = shuffled[n_train:n_train + n_val]
idx_test = shuffled[n_train + n_val:]
print(n_train, n_val, len(idx_test))235 78 79
Of the 392 cars with a recorded horsepower, 235 form the training set, which is all the fitting procedure sees, and the other 157 are held out of the fit.
Definition 14 (Validation set)
Definition 14 (Validation set) A validation set is a subset of the data set, the pairs indexed by a set \(\validx\) that shares no index with \(\trainidx\), and that we use for model selection among candidate models fitted to the training set [4]:
\[ \valset \eqdef \set{(\vpredvar_i, \outvar_i) : i \in \validx} \subseteq \dataset, \quad \validx \cap \trainidx = \emptyset . \tag{13}\]
The model with the smallest empirical risk on the validation set is the one we keep.
Definition 15 (Validation error)
Definition 15 (Validation error) The validation error of a model \(\modmem\) is its empirical risk on the validation set, \(\empriskf{\modmem; \valset}\).
See validation error in the statistics notes.
Example 15 (Choosing a polynomial degree)
Example 15 (Choosing a polynomial degree) Fit polynomials of degree 1 to 9 to the 235 training cars of Example 14, predicting mpg from horsepower, and score each on the 78 validation cars.
# Scale horsepower to 0 to 1 so that high degrees are numerically stable.
hp = auto_split["horsepower"].to_numpy(dtype=float)
hp = (hp - hp.min()) / (hp.max() - hp.min())
mpg = auto_split["mpg"].to_numpy(dtype=float)
def mse(coef, idx):
return np.mean((np.polyval(coef, hp[idx]) - mpg[idx]) ** 2)
degrees = range(1, 10)
fits = {d: np.polyfit(hp[idx_train], mpg[idx_train], d) for d in degrees}
val_mse = {d: mse(fits[d], idx_val) for d in degrees}
train_mse = {d: mse(fits[d], idx_train) for d in degrees}
best_degree = min(val_mse, key=val_mse.get)
train_mse_9 = train_mse[9]
val_mse_9 = val_mse[9]
val_mse_best = val_mse[best_degree]
def mse_ci(coef, idx):
# Normal-approximation 95% interval for the mean of the squared errors.
sq = (np.polyval(coef, hp[idx]) - mpg[idx]) ** 2
se = sq.std(ddof=1) / np.sqrt(len(sq))
return sq.mean() - 1.96 * se, sq.mean() + 1.96 * se
val_ci_best = mse_ci(fits[best_degree], idx_val)
val_ci_9 = mse_ci(fits[9], idx_val)
print(best_degree, round(val_mse[best_degree], 3), round(train_mse_9, 3), round(val_mse_9, 3))2 18.006 16.78 19.559
[12.012 23.999] [11.9 27.218]
The degree with the smallest validation error, 2, is the one we keep. The training cars could not make this choice, because the training error keeps falling as the degree grows: the degree-9 fit has training error 16.78 and validation error 19.56. The chosen degree’s validation error, 18.01, has a 95% confidence interval of 12.01 to 24.00, and the degree-9 fit’s has 11.90 to 27.22. Each interval comes from the 78 validation cars alone, and the chosen degree’s is optimistic, because the same cars picked the degree.
Definition 16 (Test set)
Definition 16 (Test set) A test set is a subset of the data set, the pairs indexed by a set \(\testidx\) that shares no index with \(\trainidx\) or \(\validx\), and that we use only once, after the model is chosen, to estimate the risk of the chosen model \(\modmem\) by its empirical risk on the test set, \(\empriskf{\modmem; \testset}\):
\[ \testset \eqdef \set{(\vpredvar_i, \outvar_i) : i \in \testidx} \subseteq \dataset, \quad \testidx \cap \paren{\trainidx \cup \validx} = \emptyset . \tag{14}\]
Definition 17 (Test error)
Definition 17 (Test error) The test error of a model \(\modmem\) is its empirical risk on the test set, \(\empriskf{\modmem; \testset}\).
See test error in the statistics notes.
Example 16 (Reporting the chosen degree’s error)
Example 16 (Reporting the chosen degree’s error) Having chosen degree 2 on the validation cars of Example 15, score that one model on the 79 test cars.
# Refit the chosen degree on the training cars of @exm-training-set (scaled horsepower hp, mpg),
# so this chunk does not lean on the fits table of the validation example.
chosen_coef = np.polyfit(hp[idx_train], mpg[idx_train], best_degree)
# A normal-approximation 95% interval: the mean of the squared errors
# plus or minus 1.96 standard errors.
test_sq = (np.polyval(chosen_coef, hp[idx_test]) - mpg[idx_test]) ** 2
test_mse = np.mean(test_sq)
test_se = test_sq.std(ddof=1) / np.sqrt(len(test_sq))
test_lo, test_hi = test_mse - 1.96 * test_se, test_mse + 1.96 * test_se
print(round(test_mse, 3), round(test_lo, 3), round(test_hi, 3))24.232 14.183 34.281
The estimate of the chosen model’s risk is 24.23, with a 95% confidence interval of 14.18 to 34.28. The test cars played no part in the fit or the choice, so the choice did not tune this estimate to them. If it disappoints and we go back to choose again, the test cars have become a validation set.
Definition 18 (Generalization gap)
Definition 18 (Generalization gap) The generalization gap of a model \(\modmem\) on a training set \(\trainset\) is its risk minus its training error [14, Sec. 5.2]:
\[ \popriskf{\modmem} - \empriskf{\modmem; \trainset} . \tag{15}\]
Example 17 (Estimating the chosen degree’s gap)
Example 17 (Estimating the chosen degree’s gap) The risk in Equation 15 cannot be computed, so estimate it by the test error of Example 16, and subtract the training error of the same degree-2 fit.
17.693 24.232 6.539
The training error is 17.69 and the test error is 24.23, so the estimated gap is 6.54. The estimate is noisy: the 95% interval for the test error in Example 16 runs from 14.18 to 34.28, and it contains the training error, so these cars alone do not show that the gap is positive.
Remark 9 (The three sets together)
Remark 9 (The three sets together). The three index sets \(\trainidx\), \(\validx\) and \(\testidx\) are disjoint and together cover \(1, \ldots, n\), so the training, validation and test sets are disjoint subsets that together make up the data set \(\dataset\), which is why Example 14 draws them from one shuffled list. The sets are not interchangeable: the first is for fitting, the second for choosing among fits, and the third for reporting. Data used for one job gives an optimistic answer to the next, as Figure 11 shows. Any pairs kept out of the fit are called held-out, so validation and test sets are both held-out sets.
The statistics notes define the same three sets formally: the training set, the validation set, and the test set. They use a different symbol for the training set and a plain observation index, but the same three-way split.
Remark 10 (What the validation and test errors estimate)
Remark 10 (What the validation and test errors estimate). Like the training error, the validation error and the test error are empirical risks, and they differ only in the set that scores the model. The model was not fitted to the validation or test set, so each estimates the risk \(\popriskf{\modmem}\) without the optimism of the training error. We choose the model with the smallest validation error, so the validation error of the chosen model is still optimistic. We compute the test error once, after the choice, so it is not.
Some textbooks use “test error” for the expected error of the fitted model on a new observation, which is the risk of the fitted model, not a number computed from a test set [2, Sec. 7.2]. Here the test error is the number computed from the test set, and the risk is what it estimates.
These ideas hold for any loss, not only squared error. Each error is the average loss on the set that scores the model: the training error, the validation error and the test error. The expected loss of the fitted model on a new observation is its generalization error, the risk of the fitted model. Averaging the generalization error over training sets gives the expected generalization error.
tvSplit = biCarSplit(tvN, 2100 + tvDraw)
tvTrain = tvSplit.train
tvHeld = tvSplit.held
tvDegrees = d3.range(0, 10)
// Every degree's fit to the training sample, scored on both samples.
tvScores = tvDegrees.map((degree) => {
const h = biPolyfit(tvTrain, degree);
return {degree, h, train: biRmse(h, tvTrain), held: biRmse(h, tvHeld), heldCI: biRmseCI(h, tvHeld)};
})
tvFit = tvScores[tvDegree]
tvLong = tvScores.flatMap((d) => [
{degree: d.degree, set: "training points", rmse: biMpgUnits(d.train)},
{degree: d.degree, set: "held-out points", rmse: biMpgUnits(d.held),
lo: Math.max(biMpgUnits(d.heldCI.lo), 1e-1), hi: biMpgUnits(d.heldCI.hi)}
])In Figure 11, change the degree and the number of training points, and compare the two error curves.
md`Degree ${tvDegree}, fitted to ${tvN} training points.
Root mean squared error (RMSE) on the training points: **${biMpgUnits(tvFit.train).toFixed(2)} mpg**;
on the ${tvHeld.length} held-out cars: **${biMpgUnits(tvFit.held).toFixed(2)} mpg**,
with a 95% confidence interval of **${biFmtCIMpg(tvFit.heldCI)}** mpg.`Plot.plot({
ariaLabel: 'The held-out cars as light grey dots, the training cars as black dots, ' +
'and the least-squares polynomial of the chosen degree as a solid blue curve, ' +
'with horsepower on the horizontal axis and mpg on the vertical axis.',
width: 300, height: 260, grid: true,
x: {domain: [0, 1], ...biHpAxis},
y: {domain: [-2, 3.5], ...biMpgAxis},
marks: [
Plot.dot(tvHeld, {x: (d) => d[0], y: (d) => d[1], r: 2, fill: "#bbb"}),
Plot.line(biCarGrid, {x: (x) => x, y: tvFit.h, stroke: "#1f77b4", strokeWidth: 2.5, clip: true}),
Plot.dot(tvTrain, {x: (d) => d[0], y: (d) => d[1], r: 4, fill: "#222"})
]
})Plot.plot({
ariaLabel: 'Root mean squared error in miles per gallon, on a log scale, against polynomial degree from 0 to 9, ' +
'one curve for the training points and one for the held-out points, ' +
'with a 95% confidence interval drawn around each held-out point, ' +
'and the chosen degree marked by a vertical line.',
width: 300, height: 260, marginLeft: 50, grid: true,
x: {domain: [0, 9], label: "degree", ticks: tvDegrees},
y: {type: "log", domain: [1e-1, 1e2], clamp: true, label: "RMSE (mpg, log scale)",
ticks: biPow10(1e-1, 1e2), tickFormat: biExp},
color: {domain: ["training points", "held-out points"], range: ["#1f77b4", "#ff7f0e"],
legend: true},
marks: [
Plot.ruleX([tvDegree], {stroke: "#888"}),
// The 95% confidence interval of each held-out error, as a vertical bar.
Plot.ruleX(tvLong.filter((d) => d.set === "held-out points"),
{x: "degree", y1: "lo", y2: "hi", stroke: "set", strokeWidth: 1.5}),
Plot.line(tvLong, {x: "degree", y: "rmse", stroke: "set", strokeWidth: 2}),
Plot.dot(tvLong, {x: "degree", y: "rmse", fill: "set", r: 3})
]
})Remark 11 (Reading the figure on training and held-out error)
Remark 11 (Reading the figure on training and held-out error). The polynomials are fitted with horsepower scaled to run from 0 to 1 and mpg standardized, but every axis and number here is in the original units, horsepower and miles per gallon. The sRMSE is the square root of the sample mean squared error, so it is in the units of the response, here miles per gallon (why we report sRMSE). The vertical bars on the held-out curve and the interval in the readout are 95% confidence intervals for the held-out sRMSE: the mean of the squared errors plus or minus 1.96 standard errors, from the central limit theorem, with the endpoints square-rooted. It is rough when a high-degree fit makes a few squared errors enormous, and it describes the risk of this fitted polynomial, not of the fitting method. The training error has no interval: the fit was chosen to make those errors small, so they are not independent draws and their mean is biased low as an estimate of the risk, and an interval around it would be centred in the wrong place.
Exercise 20 (How far can a held-out score be trusted?)
Exercise 20 (How far can a held-out score be trusted?) A spam filter \(\modmem\) was trained on one set of emails and then scored on a fresh held-out set \(\mathcal{V}\) of \(n\) emails, drawn independently from the same distribution as the emails it will face. Its held-out score \(\empriskf{\modmem; \mathcal{V}}\) is the fraction of those emails it labels wrong, and its risk \(\popriskf{\modmem}\) is its error rate on the population.
Find an upper bound on the chance that the held-out score misses the risk by more than some \(\tolout > 0\), using only the mean and variance of the held-out score.
Solution 20. Write \(Z_i\) for the loss on the \(i\)th held-out email: 1 if \(\modmem\) labels it wrong, and 0 if right. The filter was fixed before \(\mathcal{V}\) was drawn, so the \(Z_i\) are independent, and each is 1 with probability \(\popriskf{\modmem}\). The held-out score is their average, \(\empriskf{\modmem; \mathcal{V}} = \avgin Z_i\), so its mean is \(\popriskf{\modmem}\).
Its variance is the variance of one \(Z_i\) divided by \(n\). A 0/1 variable that is 1 with probability \(R\) has variance \(R(1 - R)\), and that is never more than \(\frac{1}{4}\):
\[ R(1 - R) = \frac{1}{4} - \paren{ R - \frac{1}{2} }^2 \le \frac{1}{4} . \]
So \(\Var{\empriskf{\modmem; \mathcal{V}}} \le \frac{1}{4n}\), whatever the filter’s error rate is. Chebyshev’s inequality bounds the chance of a miss by the variance divided by the square of the miss:
\[ P\paren{ \abs{ \empriskf{\modmem; \mathcal{V}} - \popriskf{\modmem} } > \tolout } \le \frac{\Var{\empriskf{\modmem; \mathcal{V}}}}{\tolout^2} \le \frac{1}{4 n \tolout^2} . \]
Exercise 21 (How far can a held-out score be trusted? (part 2))
Exercise 21 (How far can a held-out score be trusted? (part 2)) Use the setup of Exercise 20.
How does your bound change as \(n\) grows?
Solution 21. The bound shrinks in proportion to \(1/n\): ten times as many held-out emails make a miss of a given size at most a tenth as likely.
For example, with \(n = 1000\) and \(\tolout = 0.05\), the chance of a miss is at most \(1 / (4 n \tolout^2) = 0.1\).
Chebyshev uses only the variance, and the 0/1 range entered only through the cap of \(\frac{1}{4}\) on it. Using the range itself, that each \(Z_i\) lies between 0 and 1, gives a much sharper bound, one that shrinks exponentially in \(n\) rather than in proportion to \(1/n\).
Theorem 2 (Hoeffding’s inequality for a held-out set)
Theorem 2 (Hoeffding’s inequality for a held-out set) Score a classifier \(\modmem\) with the misclassification loss. Let \(\valset\) be a held-out set of \(n\) points drawn independently from the same distribution \(P(x, y)\), and let \(\empriskf{\modmem; \valset}\) be the fraction of them \(\modmem\) gets wrong, as in Equation 5. If \(\modmem\) is fixed before \(\valset\) is drawn, then for every \(\tolout > 0\) [15],
\[ P\paren{ \abs{ \empriskf{\modmem; \valset} - \popriskf{\modmem} } > \tolout } \le 2 e^{-2 \tolout^2 n} . \tag{16}\]
Proof
Proof. The misclassification loss of \(\modmem\) on the \(i\)th held-out point, \(\lossf{y_{(i)}, \modmemf{x_{(i)}}}\), is 1 when \(\modmem\) gets the point wrong and 0 otherwise. Because \(\modmem\) is fixed before \(\valset\) is drawn, each loss is the same function of one of \(n\) independent draws from \(P(x, y)\). So the \(n\) losses are IID random variables in \([0, 1]\). Their common mean is \(\popriskf{\modmem}\) by Equation 4, and their average is \(\empriskf{\modmem; \valset}\) by Equation 5. Hoeffding’s inequality for an average of IID variables in \([0, 1]\) bounds the chance that the average misses the mean by at least \(\tolout\) by \(2 e^{-2 \tolout^2 n}\). The event “misses by more than \(\tolout\)” is part of that event, so its chance is at most as large.
Remark
Remark 12 (Reading Hoeffding’s inequality)
Remark 12 (Reading Hoeffding’s inequality). The misclassification loss is 1 when \(\modmemf{x} \neq y\) and 0 otherwise, so \(\popriskf{\modmem}\) in Equation 4 is the classifier’s error rate on the population. The probability in Equation 16 is over the draw of \(\mathcal{V}\); \(\popriskf{\modmem}\) is unknown but not random.
Exercise 22 (How many held-out emails are enough?)
Exercise 22 (How many held-out emails are enough?) A spam filter was trained on one set of emails, and you will estimate its error rate on a fresh held-out set. Say the estimate misses when it differs from the filter’s true error rate by more than 0.05.
How many held-out emails make the chance of a miss at most 0.05?
Solution 22. In Exercise 22, the filter was fixed before the held-out set was drawn, so Equation 16 applies. Write \(\tolout\) for the allowed miss and \(\tolin\) for the allowed chance. The chance of a miss is at most \(\tolin\) whenever the bound is:
\[ \begin{aligned} 2 \e{-2 \tolout^2 \nobs} &\le \tolin \\ \e{-2 \tolout^2 \nobs} &\le \frac{\tolin}{2} \\ -2 \tolout^2 \nobs &\le \ln \frac{\tolin}{2} \\ 2 \tolout^2 \nobs &\ge -\ln \frac{\tolin}{2} = \ln \frac{2}{\tolin} \\ \nobs &\ge \frac{\ln (2 / \tolin)}{2 \tolout^2} . \end{aligned} \]
The fourth line multiplies both sides by \(-1\), which flips the inequality, and the fifth divides by \(2 \tolout^2\).
With \(\tolout = 0.05\) and \(\tolin = 0.05\), that is \(\nobs \ge 738\) emails. The bound is loose, so fewer emails may well do, but 738 are enough whatever the filter’s error rate is.
Exercise 23 (How many held-out emails are enough? (part 2))
Exercise 23 (How many held-out emails are enough? (part 2)) Use the setup of Exercise 22.
Suppose instead that 100 different filters, all trained before the held-out set was drawn, are scored on the same held-out set, and you keep the one with the lowest score. How many held-out emails make the chance that the kept filter’s estimate misses at most 0.05?
Solution 23. In Exercise 23, the kept filter was chosen by its held-out score, so it was not fixed before the held-out set was drawn, and Equation 16 does not apply to it directly.
It does apply to each of the \(M = 100\) filters \(\modmemof{1}, \ldots, \modmemof{M}\), since each was trained before the held-out set was drawn. The kept filter’s estimate can miss only if at least one filter’s estimate does, and the chance that at least one of several events happens is at most the sum of their chances. So
\[ \begin{aligned} P\paren{ \text{the kept filter misses} } &\le P\paren{ \text{some } \modmemof{m} \text{ misses} } \\ &\le \sumto{m}{M} P\paren{ \abs{ \empriskf{\modmemof{m}; \mathcal{V}} - \popriskf{\modmemof{m}} } > \tolout } \\ &\le \sumto{m}{M} 2 \e{-2 \tolout^2 \nobs} \\ &= 2 M \e{-2 \tolout^2 \nobs} , \end{aligned} \]
where the third line applies Equation 16 to each term.
Repeating the steps of Solution 22 with \(2M\) in place of 2 gives \(\nobs \ge \ln (2M / \tolin) / (2 \tolout^2)\), which is 1659 emails, about 2.2 times as many as for one filter.
Both answers are sufficient sizes, not required ones, since they come from an upper bound. Two things still follow for Solution 19’s three sets. The sufficient \(\nobs\) is proportional to \(1 / \tolout^2\), so halving the allowed miss quadruples it: with \(\tolout = 0.025\), Solution 22 needs 2952 emails rather than 738. And a validation set on which a fixed list of \(M\) models is compared needs the size from Solution 23 for that \(M\), \(\ln (2M / \tolin) / (2 \tolout^2)\), while a test set scored once on one model needs only the size from Solution 22. The union bound covers only a finite list of models; tuning a setting that can take infinitely many values needs the further analysis that Abu-Mostafa et al. [1] defers to its chapter 2.
# HTML formats get an interactive plotly figure; the handout and other formats
# get the same curves as a static SVG from tools/make_big_ideas_figures.py.
if (knitr::is_html_output()) {
library(plotly)
# Hoeffding's bound 2 exp(-2 tol^2 n), capped at 1 because a probability
# cannot exceed 1.
n_held_out <- seq(0, 2000, length.out = 401)
bound <- function(tol) pmin(1, 2 * exp(-2 * tol^2 * n_held_out))
widget <- plot_ly() |>
add_trace(
x = n_held_out, y = bound(0.1), type = "scatter", mode = "lines",
name = "tolerance 0.1", line = list(color = "#1f77b4")
) |>
add_trace(
x = n_held_out, y = bound(0.05), type = "scatter", mode = "lines",
name = "tolerance 0.05", line = list(color = "#d95f02", dash = "dash")
) |>
add_trace(
x = n_held_out, y = bound(0.02), type = "scatter", mode = "lines",
name = "tolerance 0.02", line = list(color = "#1b9e77", dash = "dot")
) |>
layout(
xaxis = list(title = "held-out set size n"),
yaxis = list(title = "bound on the chance of a miss", range = c(0, 1.02)),
legend = list(orientation = "h", y = -0.2),
margin = list(t = 10)
) |>
config(displaylogo = FALSE, responsive = TRUE)
# The alt text: a plotly widget has none of its own.
htmltools::div(
role = "img",
`aria-label` = paste(
"Interactive plot of Hoeffding's bound against held-out set size for",
"tolerances 0.1, 0.05 and 0.02. Each curve starts at 1 and falls toward",
"0, and a smaller tolerance falls later."
),
widget
)
} else {
knitr::include_graphics("../images/big-ideas/hoeffding.svg")
}Exercise 24 (Use every point twice)
Exercise 24 (Use every point twice) The three sets of Solution 19 are practical only when we have a lot of data. Setting aside a tenth of the data for validation and a tenth for testing leaves the model fitting on the remaining eighty percent, and on a small dataset that costs twice: the model is worse for having seen less, and the held-out estimate is noisy because it is based on so few points.
Design a procedure in which every point is scored by a model that was not fitted to it, and every point also helps fit a model.
Solution 24. Divide the \(n\) points at random into \(k\) groups of roughly equal size. For each group in turn, fit the model on the other \(k-1\) groups and score it on the group left out. Average the \(k\) scores.
This is \(k\)-fold cross-validation (Definition 20), and the groups are its folds.
Exercise 25 (Use every point twice (part 2))
Exercise 25 (Use every point twice (part 2)) Use the setup of Exercise 24.
In your procedure, how many times is each point scored?
Solution 25. Each point belongs to exactly one group, so it is scored exactly once, by the one model that did not see it.
Exercise 26 (Use every point twice (part 3))
Exercise 26 (Use every point twice (part 3)) Use the setup of Exercise 24.
In your procedure, how many times is each point trained on?
Exercise 27 (Use every point twice (part 4))
Exercise 27 (Use every point twice (part 4)) Use the setup of Exercise 24.
What does the procedure cost?
Definition 19 (Folds)
Definition 19 (Folds) Given a data set of \(n\) pairs, \(k\) folds \(I_1, \ldots, I_k\) are a random partition of the indices \(\set{1, \ldots, n}\) into \(k\) index sets of roughly equal size.
See folds in the statistics notes.
Definition 20 (\(k\)-fold cross-validation)
Definition 20 (\(k\)-fold cross-validation) Given a data set of \(n\) pairs and a learning algorithm, \(k\)-fold cross-validation splits the pairs into \(k\) folds \(I_1, \ldots, I_k\) [16]. For each fold \(I_j\), the algorithm is fit to the pairs outside that fold, which gives the model \(\fitmodf{-j}\).
Definition 21 (\(k\)-fold cross-validation estimate)
Definition 21 (\(k\)-fold cross-validation estimate) The \(k\)-fold cross-validation estimate of the risk scores each pair by the model \(\fitmodf{-j}\) that did not see it (the model fit outside fold \(I_j\) in \(k\)-fold cross-validation), and averages those scores over all \(n\) pairs:
\[ \hR_{k\text{-fold}} \eqdef \frac{1}{n} \sum_{j=1}^{k} \sum_{i \in I_j} \lossf{y_{(i)}, \fitmodf{-j}\paren{x_{(i)}}} . \tag{17}\]
Definition 22 (Leave-one-out cross-validation)
Definition 22 (Leave-one-out cross-validation) Leave-one-out cross-validation is \(k\)-fold cross-validation with \(k = n\) [16]: each pair is a fold of its own, and the model \(\fitmodf{-i}\) is fitted to the other \(n - 1\) pairs. Its estimate of the risk is
\[ \hR_{\text{LOO}} \eqdef \frac{1}{n} \sumin \lossf{y_{(i)}, \fitmodf{-i}\paren{x_{(i)}}} . \tag{18}\]
Example 18 (Leave-one-out on the five neighbourhoods)
Example 18 (Leave-one-out on the five neighbourhoods) With \(n = 5\) neighbourhoods, \(k\)-fold cross-validation with \(k = n\) puts each neighbourhood in a fold of its own. This is leave-one-out cross-validation (Definition 22): five fits, each on four neighbourhoods and scored on the fifth. Fit the least-squares line to each training set of four, and score it by its squared error on the neighbourhood left out:
import numpy as np
# The five neighbourhoods of the crime table, read once in the first example.
x_loo = crime["x"].to_numpy()
y_loo = crime["y"].to_numpy()
loo_py = []
for i_loo in range(5):
# Train on every neighbourhood except i_loo, so the fit never sees the one it is scored on.
keep_loo = np.arange(5) != i_loo
m_loo, b_loo = np.polyfit(x_loo[keep_loo], y_loo[keep_loo], 1)
# Score the line on the held-out neighbourhood alone.
loo_py.append((m_loo * x_loo[i_loo] + b_loo - y_loo[i_loo]) ** 2)
loo_py = np.array(loo_py)
# A 95% interval for the mean of the five errors; 2.776 is the t quantile for 4 degrees of freedom,
# which replaces 1.96 because five errors are too few for the normal approximation.
loo_se_py = loo_py.std(ddof=1) / np.sqrt(5)
print(loo_py.round(4), loo_py.mean().round(4), (2.776 * loo_se_py).round(4))[0.002 0.0026 0.0091 0. 0.015 ] 0.0057 0.0077
# The five neighbourhoods of the crime table, read once in the first example.
crime_loo <- crime
x_loo <- crime$x
y_loo <- crime$y
loo_r <- sapply(1:5, function(i) {
# Train on every neighbourhood except i, so the fit never sees the one it is scored on.
fit <- lm(y ~ x, data = crime_loo[-i, ])
# Score the line on the held-out neighbourhood alone.
(predict(fit, crime_loo[i, ]) - crime_loo$y[i])^2
})
# The same interval, with the t quantile for 4 degrees of freedom.
loo_se_r <- sd(loo_r) / sqrt(5)
loo_half_r <- qt(0.975, df = 4) * loo_se_r
print(round(c(loo_r, mean = mean(loo_r), half_width = loo_half_r), 4)) 1 2 3 4 5 mean half_width
0.0020 0.0026 0.0091 0.0000 0.0150 0.0057 0.0077
Figure 13 shows the five splits. Each panel lists the neighbourhoods in a small table, with the one held out shaded, and plots the same neighbourhoods, with that one in a different colour and shape. The line is fitted to the four blue circles alone.
import matplotlib.pyplot as plt
# Okabe-Ito colours, which stay distinct under the common colour-vision deficiencies;
# the circle against the diamond keeps the two groups apart in greyscale too.
train_col, held_col = "#0072B2", "#D55E00"
grid_loo = np.linspace(0.1, 0.55, 50)
fig, axes = plt.subplots(2, 5, figsize=(10, 4.2), layout="constrained",
height_ratios=[1.1, 1.4])
for i_loo in range(5):
keep_loo = np.arange(5) != i_loo
m_loo, b_loo = np.polyfit(x_loo[keep_loo], y_loo[keep_loo], 1)
# Top row: the data as a table, with the held-out row shaded and labelled.
top = axes[0, i_loo]
top.axis("off");
top.set_xlim(0, 1);
top.set_ylim(0, 6.4);
top.set_title(f"Split {i_loo + 1}", fontsize=10);
top.text(0.05, 5.7, "x", fontsize=8, fontweight="bold");
top.text(0.40, 5.7, "y", fontsize=8, fontweight="bold");
for j in range(5):
row_y = 4.7 - j
if j == i_loo:
top.fill_between([0, 1], row_y - 0.35, row_y + 0.85, color=held_col, alpha=0.25);
top.text(0.05, row_y, f"{x_loo[j]:.2f}", fontsize=8);
top.text(0.40, row_y, f"{y_loo[j]:.2f}", fontsize=8);
top.text(0.72, row_y, "held out" if j == i_loo else "train", fontsize=7,
fontweight="bold" if j == i_loo else "normal");
# Bottom row: the same neighbourhoods as a scatterplot, with the fitted line.
bot = axes[1, i_loo]
bot.plot(grid_loo, m_loo * grid_loo + b_loo, color="grey", linewidth=1.5);
bot.scatter(x_loo[keep_loo], y_loo[keep_loo], color=train_col, marker="o", s=30,
label="train");
bot.scatter(x_loo[~keep_loo], y_loo[~keep_loo], color=held_col, marker="D", s=50,
label="held out");
bot.set_xlim(0.1, 0.55);
bot.set_ylim(0, 0.6);
bot.set_xlabel("per-capita income $x$", fontsize=8);
if i_loo == 0:
bot.set_ylabel("crime rate $y$", fontsize=8);
bot.text(0.12, 0.03, f"error {loo_py[i_loo]:.3f}", fontsize=8);
bot.tick_params(labelsize=7);
# One key for all five panels, in a row along the bottom of the figure.
fig.legend(*axes[1, 0].get_legend_handles_labels(), fontsize=8,
loc="outside lower center", ncol=2);
plt.show()The five squared errors are 0.002, 0.003, 0.009, 0.000, 0.015, and their mean, the leave-one-out estimate of the risk, is \(0.006\), with a 95% confidence interval of \(-0.002\) to \(0.013\). The interval is wide because five errors say little about their mean, and it is not a valid interval: the five errors share training points, so they are not independent, and squared errors are skewed, so a t interval fits them poorly. It reaches below zero, which a mean of squared errors cannot, so treat it as a rough guide to the uncertainty. Every neighbourhood is scored once, by a line that never saw it, and every neighbourhood helps fit four of the five lines. The largest error, 0.015, is in split 5, and the next largest, 0.009, is in split 3. Those two neighbourhoods have incomes 0.24 and 0.31, on either side of the steep drop in crime rate that a straight line fitted without one of them smooths over.
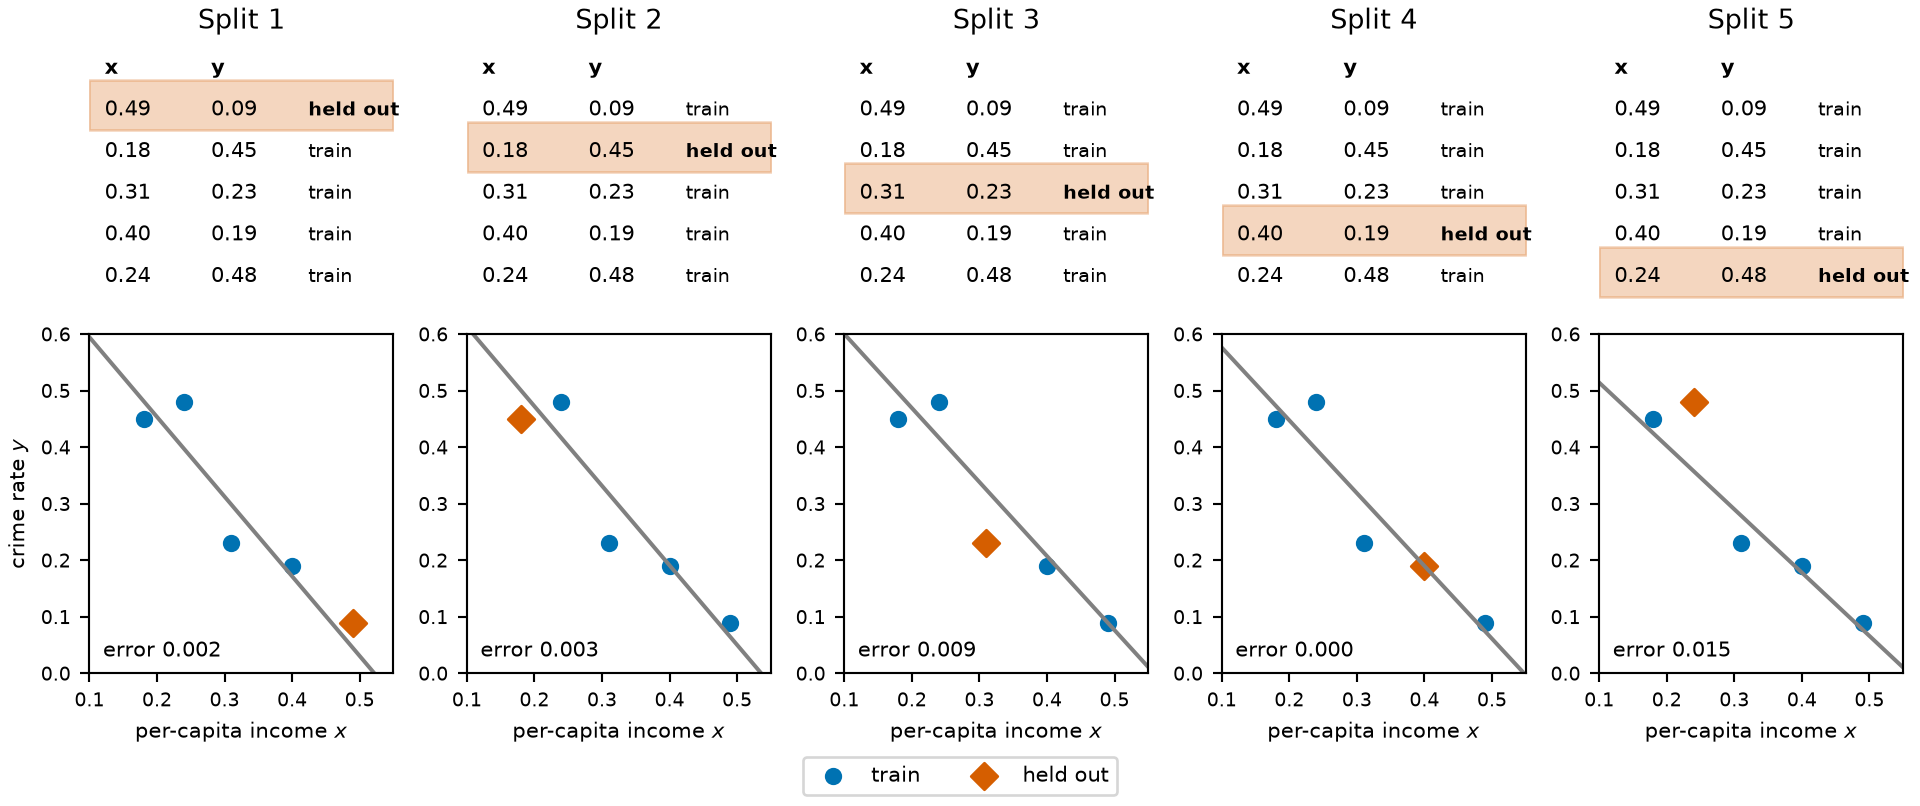
Watch
Hutchinson covers train, dev and test sets and cross-validation, Generalization, part 2 (11 min) [9]. The chapter Model Selection puts its cross-validation videos beside each method.
Watch
Starmer explains cross-validation [17].
Read
GeeksforGeeks explains cross-validation [18].
# The constants of this figure live here, so the widget, the static plot and the prose agree.
cv_n <- 40 # points drawn, and so held-out squared errors
cv_k <- 5 # folds of the static plot
cv_degree <- 3 # degree of the static plot
cv_fresh_n <- 2000 # fresh points the static plot scores
cv_sd <- 0.1 # standard deviation of the noise in the static plotcvSplit = biCarSplit(cvN, 3100 + cvDraw)
cvData = cvSplit.train
cvHeld = cvSplit.held
// Deal the points into k folds at random: shuffle, then fold = position mod k.
cvFold = {
const order = d3.shuffler(d3.randomLcg(4100 + cvDraw))(d3.range(cvN));
const fold = new Array(cvN);
order.forEach((i, pos) => { fold[i] = pos % cvK; });
return fold;
}
// The k-fold estimate for one degree: fit on k - 1 folds, score the one left out.
cvScore = (degree) => {
const sq = [];
const perFold = d3.range(cvK).map((f) => {
const train = cvData.filter((_, i) => cvFold[i] !== f);
const test = cvData.filter((_, i) => cvFold[i] === f);
const h = biPolyfit(train, degree);
// Every point is scored exactly once, by the fit that left it out.
test.forEach(([x, y]) => sq.push((h(x) - y) ** 2));
return {fold: f + 1, rmse: biRmse(h, test)};
});
// The k-fold estimate of the RMSE is the root of the average of the fold MSEs,
// which is the root of the mean of all n held-out squared errors when the folds are equal.
// Its interval is the bootstrap interval for that mean of squared errors, square-rooted.
// It is approximate: the n errors are not independent, since each fit shares most of its
// training points with the others, so the true interval is somewhat wider (see the caption).
const ci = biRmseCIBoot(sq, 7);
return {perFold, mean: Math.sqrt(d3.mean(perFold, (d) => d.rmse ** 2)), ci};
}
cvNow = cvScore(cvDegree)
// For comparison: the model fitted to all cvN cars, scored on the other cars.
cvFresh = (degree) => biRmse(biPolyfit(cvData, degree), cvHeld)
cvFreshCI = (degree) => biRmseCI(biPolyfit(cvData, degree), cvHeld)
cvCurve = d3.range(0, 9).flatMap((degree) => {
const score = cvScore(degree);
const fresh = cvFreshCI(degree);
// Each series is drawn a little to one side of the degree, so the two bars do not overlap.
return [
{degree, x: degree - 0.1, what: "k-fold estimate", rmse: biMpgUnits(score.mean),
lo: Math.max(biMpgUnits(score.ci.lo), 1e-1), hi: biMpgUnits(score.ci.hi)},
{degree, x: degree + 0.1, what: "error on fresh points", rmse: biMpgUnits(fresh.mean),
lo: Math.max(biMpgUnits(fresh.lo), 1e-1), hi: biMpgUnits(fresh.hi)}
];
})
// One row per fold, one column per point (sorted by x): scored or trained on.
cvCells = {
const byX = d3.sort(d3.range(cvN), (i) => cvData[i][0]);
return d3.range(cvK).flatMap((f) => byX.map((i, col) => ({
fold: f + 1, col: col + 1, role: cvFold[i] === f ? "scored" : "trained on"
})));
}Change \(k\) and the degree in Figure 14, and compare the \(k\)-fold estimate with the error on fresh points.
md`${cvK} fits, each on ${cvN - cvN / cvK} points and scored on the other ${cvN / cvK}.
The RMSE on each held-out fold, in mpg, is ${cvNow.perFold.map((d) => `${d.fold}: ${biMpgUnits(d.rmse).toFixed(2)}`).join("; ")}.
The overall ${cvK}-fold cross-validation RMSE for degree ${cvDegree} is **${biMpgUnits(cvNow.mean).toFixed(2)} mpg**,
with an approximate 95% confidence interval of ${biFmtCIMpg(cvNow.ci)};
the degree-${cvDegree} fit to all ${cvN} points scores **${biMpgUnits(cvFresh(cvDegree)).toFixed(2)} mpg** on the other ${cvHeld.length} cars,
with a 95% confidence interval of ${biFmtCIMpg(cvFreshCI(cvDegree))}.`Plot.plot({
ariaLabel: 'The fold assignment as a grid: one row per fold, the fit that leaves it out, ' +
'one column per data point sorted by x, ' +
'each cell orange where that fit scores the point and light blue where it trains on it.',
width: 320, height: Math.min(40 + 14 * cvK, 200), marginLeft: 40,
x: {label: "data point, sorted by x", ticks: []},
y: {label: "fold", ticks: cvK <= 10 ? d3.range(1, cvK + 1) : [1, 5, 10, 15, 20]},
color: {domain: ["trained on", "scored"], range: ["#c6dbef", "#ff7f0e"], legend: true},
marks: [
Plot.cell(cvCells, {x: "col", y: "fold", fill: "role", inset: 0.5})
]
}){
// A log axis spanning whole powers of ten around everything drawn,
// so that its power-of-ten ticks all fall inside it.
// `shown` holds the k fold scores, then their mean, then the fresh-point error,
// converted to miles per gallon and floored at 1e-6 because a log scale cannot place a zero.
const shown = [...cvNow.perFold.map((d) => d.rmse), cvNow.mean, cvFresh(cvDegree),
cvNow.ci.lo, cvNow.ci.hi].map((v) => Math.max(biMpgUnits(v), 1e-6));
const yDomain = [10 ** Math.floor(Math.log10(d3.min(shown))), 10 ** Math.ceil(Math.log10(d3.max(shown)))];
return Plot.plot({
ariaLabel: 'The root mean squared error on each held-out fold as a dot, ' +
'with a solid line at their root-mean-square, the k-fold estimate, ' +
'a pale band for its approximate 95% confidence interval, ' +
'and a dashed line at the error on fresh points.',
width: 320, height: 150, marginLeft: 50, grid: true,
x: {label: "fold", ticks: cvK <= 10 ? d3.range(1, cvK + 1) : [1, 5, 10, 15, 20],
tickFormat: "d"},
y: {type: "log", domain: yDomain, label: "fold RMSE (mpg, log scale)",
ticks: biPow10(...yDomain), tickFormat: biExp},
marks: [
// The approximate 95% confidence interval of the k-fold estimate, as a pale band.
Plot.rectY([{lo: shown[cvK + 2], hi: shown[cvK + 3]}],
{x1: 0.5, x2: cvK + 0.5, y1: "lo", y2: "hi", fill: "#ff7f0e", fillOpacity: 0.2}),
Plot.ruleY([shown[cvK]], {stroke: "#ff7f0e", strokeWidth: 2}),
Plot.ruleY([shown[cvK + 1]], {stroke: "#222", strokeDasharray: "5,4"}),
Plot.dot(cvNow.perFold, {x: "fold", y: (_, i) => shown[i], r: 4, fill: "#ff7f0e"})
]
});
}Plot.plot({
ariaLabel: 'The k-fold estimate and the error on fresh points, ' +
'against polynomial degree from 0 to 8, on a log scale, ' +
'with a 95% confidence interval drawn around each error, ' +
'and the chosen degree marked by a vertical line.',
width: 320, height: 200, marginLeft: 50, grid: true,
x: {domain: [-0.4, 8.4], label: "degree", ticks: d3.range(0, 9)},
y: {type: "log", domain: [1e-1, 1e2], clamp: true, label: "RMSE (mpg, log scale)",
ticks: biPow10(1e-1, 1e2), tickFormat: biExp},
color: {domain: ["k-fold estimate", "error on fresh points"], range: ["#ff7f0e", "#222"],
legend: true},
marks: [
Plot.ruleX([cvDegree], {stroke: "#888"}),
// The 95% confidence interval of each error, as a vertical bar.
Plot.ruleX(cvCurve, {x: "x", y1: "lo", y2: "hi", stroke: "what", strokeWidth: 1.5}),
Plot.line(cvCurve, {x: "x", y: "rmse", stroke: "what", strokeWidth: 2}),
Plot.dot(cvCurve, {x: "x", y: "rmse", fill: "what", r: 3})
]
})Remark 13 (Cross-validation replaces the validation set)
Remark 13 (Cross-validation replaces the validation set). Used to choose between models, cross-validation takes the place of the validation set, the one used again and again, and not of the final test set, which stays unused. Whichever scheme picked the model, the data used to pick it cannot also be the data used to report how good it is. If cross-validation picks the polynomial degree in Figure 14, for example, the cross-validation error of the winning degree is optimistic, because that degree won partly by fitting this sample’s noise well; an honest estimate needs points that took no part in the choice.
Exercise 28 (What is random when a model predicts)
Exercise 28 (What is random when a model predicts) Section 3 says the risk cannot be computed, only estimated. A different question about the same quantity is where it comes from: given a model that predicts badly, what are the distinguishable reasons it could be predicting badly?
Start with the pieces. Choose an input value \(x\), fit a model, and predict the output at \(x\). For that process, list each thing that is random.
Solution 28. Three things.
Exercise 29 (What is random when a model predicts (part 2))
Exercise 29 (What is random when a model predicts (part 2)) Use the setup of Exercise 28.
Say what makes each one random.
Solution 29.
The output itself. The world supplies a true mean function \(\truemean\) and noise: an input \(x\) has output \(Y = \truemeanf{x} + \noise\), where \(\noise\) is mean-zero noise independent of the training set (the noise model, Definition 25).
The training set \(\trainset\). It is a finite sample, and a different sample would have been just as possible.
The fitted model. The learning algorithm turns \(\trainset\) into a model, written \(\fitmodf{\trainset}\). Because \(\trainset\) is random, so is \(\fitmodf{\trainset}\).
Definition 23 (True mean function)
Definition 23 (True mean function) The true mean function \(\truemean\) is the mean function of the outcome \(\Outvar\) given the input \(\predvar\), taken over the whole population and not over a training set: \(\truemeanf{\predvar} = \condE{\Outvar}{\predvar}\).
Example 19 (The true mean function of house prices)
Example 19 (The true mean function of house prices) Let the outcome \(\Outvar\) be the sale price of a house, and let the input \(\predvar\) be its floor area. The value of the true mean function at a floor area \(\predvar\) is the average sale price of all houses with that floor area. Two houses with the same floor area can sell for different prices, so the price of one house is not \(\truemeanf{\predvar}\) exactly.
Definition 24 (Noise)
Definition 24 (Noise) Noise \(\noise\) is the deviation of an observed outcome \(\Outvar\) from the value \(\truemeanf{\predvar}\) of the true mean function at the same input \(\predvar\):
\[ \noise \eqdef \Outvar - \truemeanf{\predvar} . \]
Example 20 (The noise of one car)
Example 20 (The noise of one car) When the 392 cars of the Auto data [3] form the population, with input \(\predvar\) equal to cylinders and outcome \(\Outvar\) equal to mpg, the true mean function value at \(\predvar = 4\) cylinders is \(\truemeanf{4} = 29.28\), the population mean of mpg for the 199 four-cylinder cars. The 1970 Datsun PL510 has \(\Outvar = 27.0\) mpg, so the noise for that car is \(\noise = 27.0 - 29.28 = -2.28\) mpg. The 1971 Toyota Corolla 1200 has \(\Outvar = 31.0\) mpg, so the noise for that car is \(\noise = 31.0 - 29.28 = 1.72\) mpg.
Theorem 3 (The noise has population mean zero)
Theorem 3 (The noise has population mean zero) At any input \(\predvar\), the noise \(\noise\) has conditional expectation (population mean at \(\predvar\)) equal to \(0\):
\[ \condE{\noise}{\predvar} = 0 . \tag{19}\]
Proof
Proof. For the outcome \(\Outvar\) and noise \(\noise\) at input \(\predvar\), the true mean function value \(\truemeanf{\predvar}\) does not vary once \(\predvar\) is fixed, so its conditional expectation given \(\predvar\) is \(\truemeanf{\predvar}\).
\[ \begin{aligned} \condE{\noise}{\predvar} &= \condE{\Outvar - \truemeanf{\predvar}}{\predvar} && \text{(definition of the noise)} \\ &= \condE{\Outvar}{\predvar} - \truemeanf{\predvar} && \text{(linearity of expectation)} \\ &= \truemeanf{\predvar} - \truemeanf{\predvar} && \text{(definition of the true mean function)} \\ &= 0 && \text{(a number minus itself is zero)} . \end{aligned} \]
Example 21 (Noise in a count outcome)
Example 21 (Noise in a count outcome) Suppose the outcome \(\Outvar\) at input \(\predvar\) is a count with a Poisson distribution whose population mean is the true mean function value \(\truemeanf{\predvar}\). The noise \(\noise = \Outvar - \truemeanf{\predvar}\) has population mean \(0\), by Theorem 3. The variance of \(\noise\) at \(\predvar\) is \(\Var{\noise} = \truemeanf{\predvar}\), so the noise has larger variance at an input \(\predvar\) where \(\truemeanf{\predvar}\) is larger. The distribution of \(\noise\) at \(\predvar\) is also skewed: \(\noise\) cannot fall below \(-\truemeanf{\predvar}\) and has no upper bound. A gamma outcome behaves the same way: the noise is skewed, and the noise variance grows with the population mean \(\truemeanf{\predvar}\).
Remark 14 (The noise can depend on the input)
Remark 14 (The noise can depend on the input). The distribution of the noise \(\noise\) at an input \(\predvar\) can change with \(\predvar\) (Example 21). That distribution can be skewed, and the variance of \(\noise\) need not be the same at every input. Only the population mean of \(\noise\) at \(\predvar\) must be zero (Theorem 3).
Definition 25 (Noise model)
Definition 25 (Noise model) In the noise model, an input \(\predvar\) has outcome \(\Outvar\)
\[ \Outvar = \truemeanf{\predvar} + \noise, \qquad \E{\noise} = 0, \qquad \Var{\noise} = \varpar , \tag{20}\]
where \(\truemeanf{\predvar}\) is the value of the true mean function at \(\predvar\), \(\noise\) is the noise with population mean \(\E{\noise} = 0\), and \(\varpar\) is the finite variance of \(\noise\) at \(\predvar\).
Remark 15 (Independent noise draws across observations)
Remark 15 (Independent noise draws across observations). The noise \(\noise\) is a fresh random draw each time an outcome \(\Outvar\) is observed. Each outcome \(\Outvar_i\) in the training set \(\trainset\) at input \(\predvar_i\) is \(\Outvar_i = \truemeanf{\predvar_i} + \noise_i\), with true mean function value \(\truemeanf{\predvar_i}\) and noise draw \(\noise_i\), and a new outcome \(\Outvar\) at \(\predvar\) has a new draw \(\noise\). Once the inputs are fixed, \(\noise_i = \Outvar_i - \truemeanf{\predvar_i}\) and \(\noise = \Outvar - \truemeanf{\predvar}\) shift the outcomes by the fixed values \(\truemeanf{\predvar_i}\) and \(\truemeanf{\predvar}\), so conditional independence of the outcomes given the inputs is equivalent to conditional independence of the noise draws given the inputs. Under that conditional independence, when the distribution of \(\noise\) given \(\predvar\) does not change with \(\predvar\), the noise draws are independent of the inputs and of one another. When the distribution of \(\noise\) given \(\predvar\) changes with \(\predvar\) (Remark 14), a new observation drawn independently of \(\trainset\) still has a new draw \(\noise\) at the fixed input \(\predvar\) that is independent of \(\trainset\).
Remark 16 (The noise model in the probability notes)
Remark 16 (The noise model in the probability notes). For a single observation of the outcome \(\Outvar\) at input \(\predvar\) with true mean function value \(\truemeanf{\predvar}\) and finite variance \(\varpar\), Equation 20 is a consequence of Definition 24 (\(\Outvar = \truemeanf{\predvar} + \noise\) for the noise \(\noise\)) and Theorem 3 (conditional expectation \(\condE{\noise}{\predvar} = 0\)), not an additional assumption. Only the noise’s population mean and variance matter here. The variance \(\varpar\) is the variance of \(\noise\) at the input \(\predvar\) under discussion, and that variance can change with \(\predvar\) (Remark 14). The probability notes call Equation 20 the mean-zero noise model.
The noise model fixes only two components of a distribution model for the outcome: the mean function is \(\truemeanf{\predvar}\), and the variance is \(\varpar\). Any distribution model with that mean function and that variance satisfies the noise model, such as the normal distribution model with mean function \(\truemeanf{\predvar}\) and variance \(\varpar\).
Definition 26 (Fitted model)
Definition 26 (Fitted model) The fitted model \(\fitmodf{\trainset}\) is the model that a learning algorithm returns when it is applied to the training set \(\trainset\). It is a member of the mean-function model family, and it depends on \(\trainset\), so a different training set gives a different fitted model.
Example 22 (A line fitted to the five neighbourhoods)
Example 22 (A line fitted to the five neighbourhoods) Let the learning algorithm fit a straight line by least squares, and let \(\trainset\) be the five neighbourhoods of Table 1. The line that results is the fitted model \(\fitmodf{\trainset}\). Five other neighbourhoods would give a different line, which is why the fitted model is random whenever the training set is.
Definition 27 (Prediction rule )
Definition 27 (Prediction rule ) A prediction rule is a fitted model \(\fitmodf{\trainset}\) that is used to predict the outcome at a new covariate value \(\predvar\). Its prediction is \(\predvalf{\predvar}\).
In words, the prediction rule takes a new covariate value and returns the fitted model’s value there.
See prediction rule in the statistics notes.
Example 23 (The fitted line as a prediction rule )
Example 23 (The fitted line as a prediction rule ) Take the line \(\fitmodf{\trainset}\) fitted to the five neighbourhoods of Table 1 (Example 22). Using it to predict the crime rate of a sixth neighbourhood makes it a prediction rule. Using the same line only to describe the five neighbourhoods makes no prediction, so there it is a fitted model and not a prediction rule.
Definition 28 (Average fit)
Definition 28 (Average fit) The average fit at \(\predvar\) is the prediction \(\predvalf{\predvar}\) of the fitted model at \(\predvar\), averaged over every training set \(\trainset\) it might have been fitted to, where \(\Ep_{\trainset}\) denotes that average over training sets. It is the population expectation \[ \avgfitf{\predvar} \eqdef \Epredvalf{\predvar} , \tag{21}\] a fixed function of \(\predvar\) that nothing estimates, so it carries no hat. It is written like the true mean function, with the model as the subscript.
Example 24 (The average fit of a line on cylinders)
Example 24 (The average fit of a line on cylinders) Treat the 392 cars of the Auto data [3] as the whole world of cars. A training set is 30 cars drawn at random from it, and the learning algorithm fits the line of mpg on cylinders. Draw 2000 training sets, fit a line to each, and record each line’s intercept, slope and prediction at 4 cylinders. Both tabs draw with the SyncRNG package [20], a random number generator with the same algorithm in R and Python, from the same seed, so they pick the same cars:
import numpy as np
import pandas as pd
from SyncRNG import SyncRNG
auto_af = pd.read_csv("data/auto.csv").dropna(subset=["horsepower"])
cyl_af = auto_af["cylinders"].to_numpy(float)
mpg_af = auto_af["mpg"].to_numpy(float)
rng_af = SyncRNG(seed=1)
coefs_af = np.empty((2000, 2))
for s_af in range(2000):
# One training set: the first 30 rows of a shuffle of all the rows (Python counts from 0), and the line fitted to it.
pick_af = rng_af.shuffle(list(range(len(mpg_af))))[:30]
slope_af, intercept_af = np.polyfit(cyl_af[pick_af], mpg_af[pick_af], 1)
coefs_af[s_af] = intercept_af, slope_af
preds_af = coefs_af[:, 0] + coefs_af[:, 1] * 4
# The average fit at 4 cylinders is the mean of those predictions.
# The Monte Carlo standard error of that mean is the spread of the predictions over sqrt(2000).
mc_se_af = preds_af.std(ddof=1) / np.sqrt(2000)
print(preds_af.mean().round(2), preds_af.min().round(2), preds_af.max().round(2), mc_se_af.round(3))28.72 23.89 32.74 0.031
auto_af <- read.csv("data/auto.csv")
auto_af <- na.omit(auto_af[, c("mpg", "cylinders", "horsepower")])
# SyncRNG is a random number generator with the same algorithm in R and Python, so the draws match the Python tab.
library(SyncRNG)
rng_af <- SyncRNG(seed = 1)
coefs_af <- t(replicate(2000, {
# One training set: the first 30 rows of a shuffle of all the rows, and the line fitted to it.
rows <- rng_af$shuffle(seq_len(nrow(auto_af)))[1:30]
coef(lm(mpg ~ cylinders, data = auto_af[rows, ]))
}))
preds_af <- coefs_af[, 1] + coefs_af[, 2] * 4
# The average fit at 4 cylinders is the mean of those predictions.
# The Monte Carlo standard error of that mean is the spread of the predictions over sqrt(2000).
mc_se_af <- sd(preds_af) / sqrt(2000)
c(round(c(mean = mean(preds_af), min = min(preds_af), max = max(preds_af)), 2), mc_se = round(mc_se_af, 3)) mean min max mc_se
28.720 23.890 32.740 0.031
No single training set produces the average fit. The 2000 lines predict anywhere from 23.9 to 32.7 miles per gallon for a four-cylinder car, and their mean, 28.7, is the average fit \(\avgfitf{4}\) of Equation 21, with a 95% Monte Carlo confidence interval of 28.66 to 28.78 (1.96 Monte Carlo standard errors either side). The two tabs print the same numbers up to rounding.
Figure 15 plots 100 of the 2000 lines, their pointwise average, and the true mean function:
import numpy as np
import matplotlib.pyplot as plt
grid_af = np.arange(3, 9)
# The pointwise average fit is the mean of the fitted lines at each cylinder count.
avg_af = (coefs_af[:, [0]] + coefs_af[:, [1]] * grid_af).mean(axis=0)
# The true mean function is the mean mpg of the cars with each cylinder count.
truth_af = auto_af.groupby("cylinders")["mpg"].mean()
fig, ax = plt.subplots(figsize=(6, 3.5), layout="constrained")
for intercept_af, slope_af in coefs_af[:100]:
ax.plot(grid_af, intercept_af + slope_af * grid_af, color="grey", alpha=0.3, linewidth=0.8);
# One legend entry for the 100 grey lines, with a solid line to stand for them.
ax.plot([], [], color="grey", label="One fitted line (100 shown)");
ax.plot(grid_af, avg_af, color="steelblue", linewidth=2.5, label="Average fit");
ax.plot(truth_af.index, truth_af.values, color="darkorange", linewidth=2.5, marker="o", label="True mean function");
ax.set_xlabel("cylinders");
ax.set_ylabel("miles per gallon");
fig.legend(loc="outside lower center", ncol=3, frameon=False);
plt.show()library(ggplot2)
grid_af <- 3:8
# One row per fitted line and cylinder count; the pointwise average fit is the mean over lines.
lines_af <- data.frame(
line = rep(seq_len(nrow(coefs_af)), each = length(grid_af)),
cylinders = grid_af,
fit = as.vector(t(coefs_af[, 1] + outer(coefs_af[, 2], grid_af)))
)
avg_af <- aggregate(fit ~ cylinders, data = lines_af, FUN = mean)
# The true mean function is the mean mpg of the cars with each cylinder count.
truth_af <- aggregate(mpg ~ cylinders, data = auto_af, FUN = mean)
ggplot() +
geom_line(data = subset(lines_af, line <= 100), aes(cylinders, fit, group = line, colour = "One fitted line (100 shown)"), alpha = 0.3) +
geom_line(data = avg_af, aes(cylinders, fit, colour = "Average fit"), linewidth = 1.5) +
geom_line(data = truth_af, aes(cylinders, mpg, colour = "True mean function"), linewidth = 1.5) +
geom_point(data = truth_af, aes(cylinders, mpg, colour = "True mean function"), size = 3) +
scale_colour_manual(
values = c("One fitted line (100 shown)" = "grey60", "Average fit" = "steelblue", "True mean function" = "darkorange"),
breaks = c("One fitted line (100 shown)", "Average fit", "True mean function")
) +
guides(colour = guide_legend(override.aes = list(alpha = 1))) +
labs(x = "cylinders", y = "miles per gallon", colour = NULL) +
theme(legend.position = "bottom")Definition 29 (Bias of a prediction)
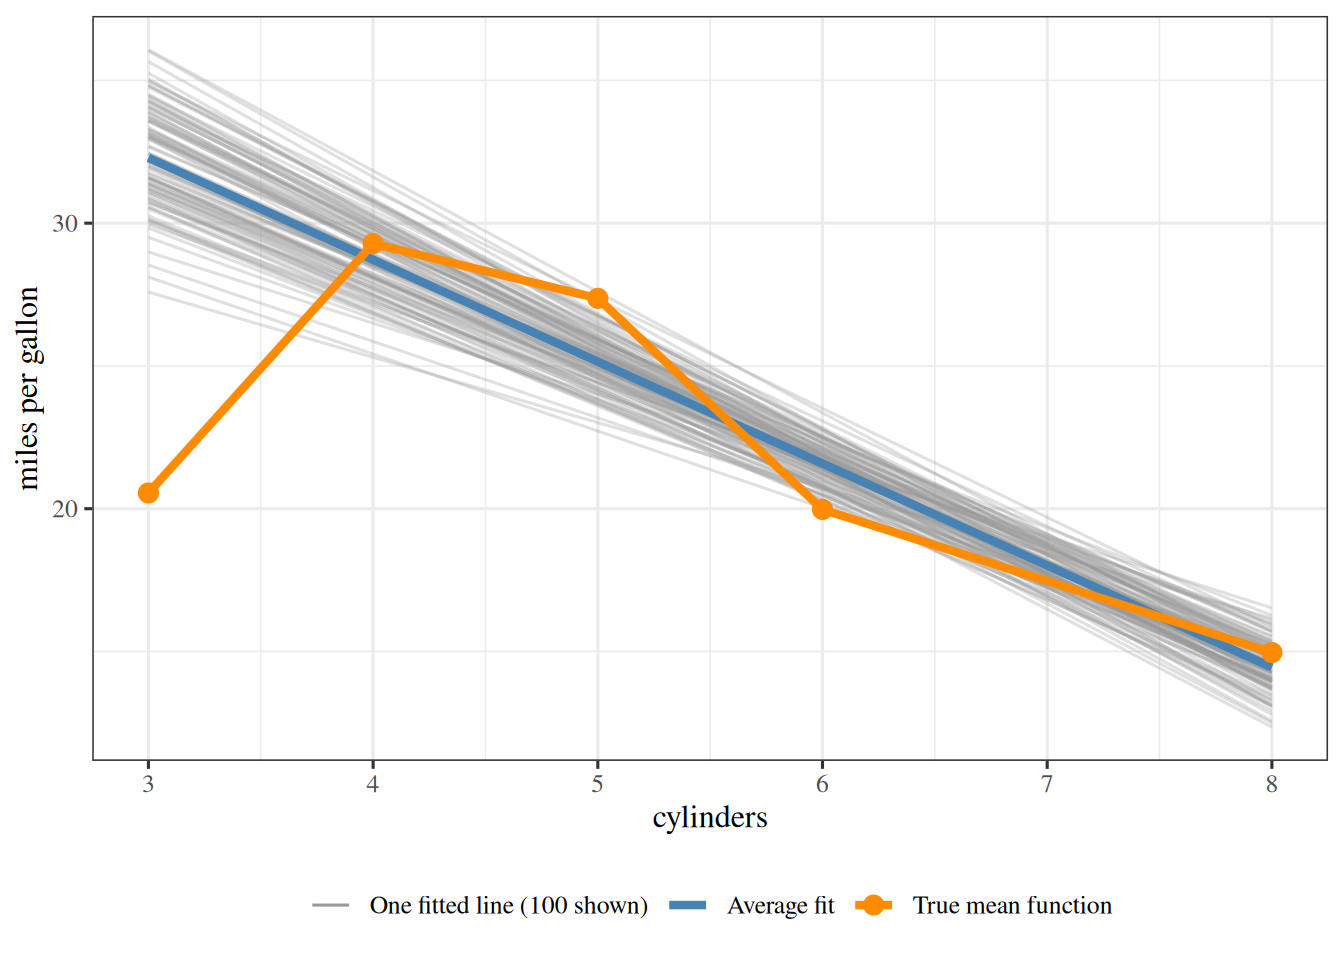
Definition 29 (Bias of a prediction) The bias of a prediction at \(\predvar\) is the expected prediction error of the prediction at \(\predvar\). The outcome in the error is a new outcome \(\Outvar\) at \(\predvar\) in the noise model, independent of the training set \(\trainset\), so the error is \(\prederr = \devof{\predval}{\Outvar}\). The expectation averages over training sets \(\trainset\) and over the noise in \(\Outvar\):
\[ \bias{\predval} \eqdef \Ep_{\trainset, \Outvar}\sb{\prederr} . \tag{22}\]
Remark 17 (The bias is signed, not squared)
Remark 17 (The bias is signed, not squared). The bias is an expected prediction error, so it is signed, not squared. It is not the expected squared prediction error (the risk). The risk also adds the variance of the prediction and the noise variance.
Definition 30 (Variance of a prediction)
Definition 30 (Variance of a prediction) The variance of a prediction at \(\predvar\) is the expected square of the deviation of the prediction at \(\predvar\) from its population mean over training sets \(\trainset\), which is the average fit \(\avgfitf{\predvar}\):
\[ \Var{\predval} = \Expfc{\trainset}{\sqf{\popdevf{\predval}}} , \quad \text{where } \popdevf{\predval} = \predval - \Epredval . \tag{23}\]
Example 25 (The bias and variance of the cylinders line at four cylinders)
Example 25 (The bias and variance of the cylinders line at four cylinders) Continue Example 24 with the same 2000 fitted lines. At \(x = 4\) cylinders, the value \(\truemeanf{4}\) of the true mean function in the noise model is the mean mpg of the four-cylinder cars. Compute the bias (Equation 22) and the variance (Equation 23) of the line:
import numpy as np
# mu(4) is the mean mpg of the four-cylinder cars.
f4_bv = mpg_af[cyl_af == 4].mean()
# Bias: the average fit minus the truth.
bias_bv = preds_af.mean() - f4_bv
# Variance: how far one fitted line sits from the average fit, on average.
var_bv = np.mean((preds_af - preds_af.mean()) ** 2)
print(np.round([bias_bv, var_bv], 2))[-0.56 1.86]
# mu(4) is the mean mpg of the four-cylinder cars.
f4_bv <- mean(auto_af$mpg[auto_af$cylinders == 4])
# Bias: the average fit minus the truth.
bias_bv <- mean(preds_af) - f4_bv
# Variance: how far one fitted line sits from the average fit, on average.
var_bv <- mean((preds_af - mean(preds_af))^2)
round(c(bias = bias_bv, variance = var_bv), 2) bias variance
-0.56 1.86
The average fit is 0.56 miles per gallon below the truth, so the bias is -0.56, and one fitted line differs from the average fit by 1.86 squared miles per gallon on average. The two tabs print the same numbers up to rounding.
Figure 16 shows the 2000 predictions with their average and the true mean function at four cylinders:
import matplotlib.pyplot as plt
fig, ax = plt.subplots(figsize=(6, 3.5), layout="constrained")
ax.hist(preds_af, bins=40, color="lightgrey", edgecolor="white");
ax.axvline(preds_af.mean(), color="steelblue", linewidth=2);
ax.axvline(f4_bv, color="darkorange", linewidth=2);
ax.set_xlabel("predicted miles per gallon at 4 cylinders");
ax.set_ylabel("training sets");
plt.show()library(ggplot2)
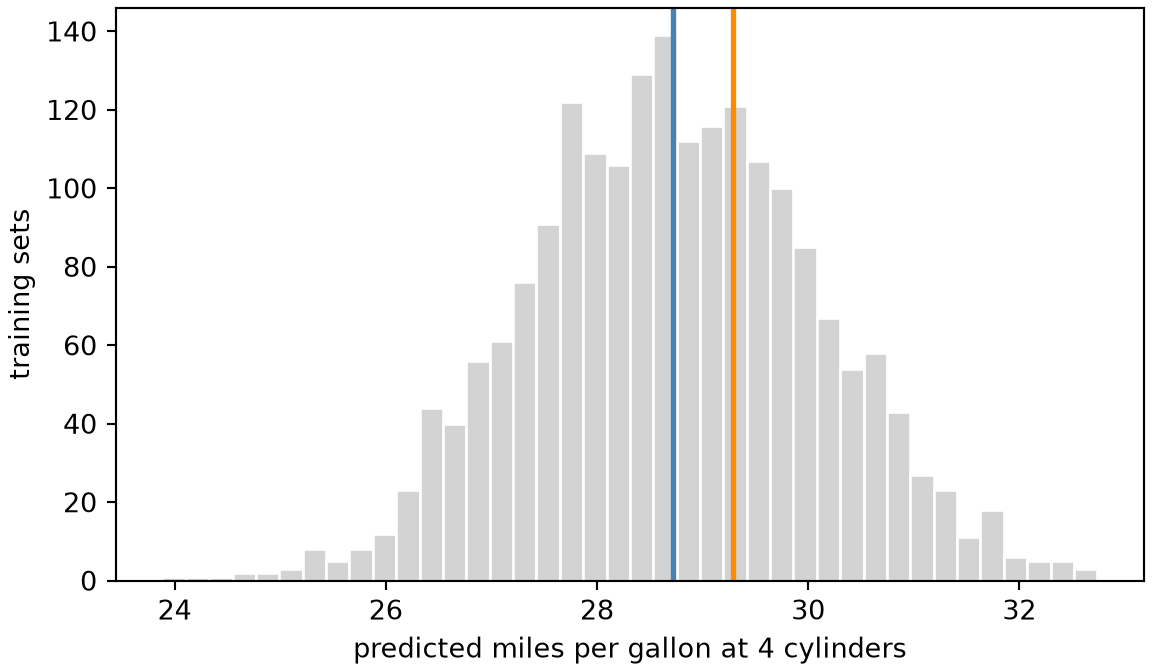
ggplot(data.frame(prediction = preds_af), aes(prediction)) +
geom_histogram(bins = 40, fill = "grey70", colour = "white") +
geom_vline(xintercept = mean(preds_af), colour = "steelblue", linewidth = 1.2) +
geom_vline(xintercept = f4_bv, colour = "darkorange", linewidth = 1.2) +
labs(x = "predicted miles per gallon at 4 cylinders", y = "training sets")Remark 18 (The variance of a fitted model’s prediction is the variance of a random variable)
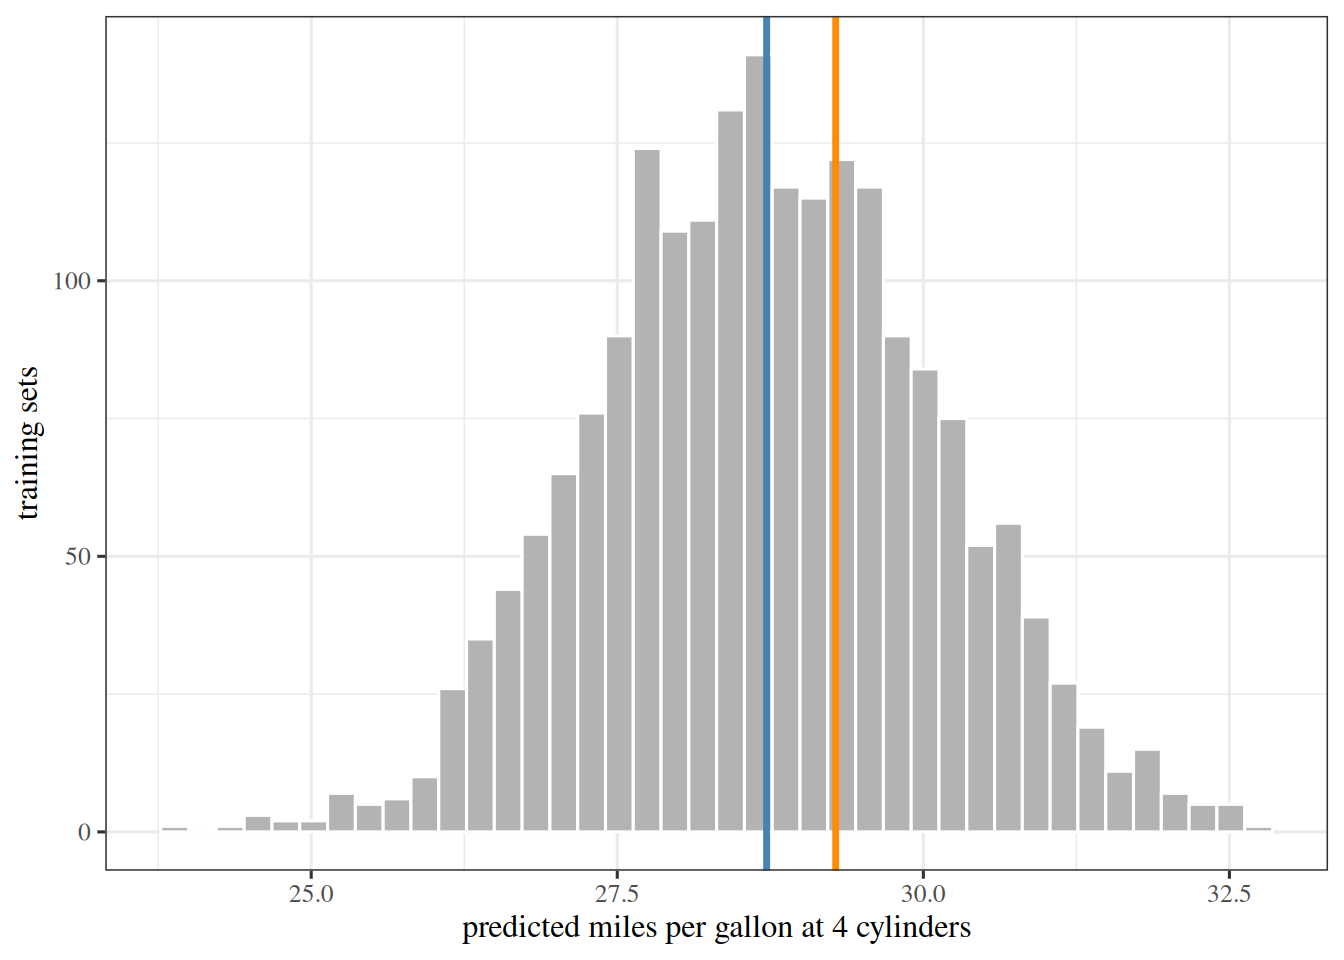
Remark 18 (The variance of a fitted model’s prediction is the variance of a random variable). The prediction of the fitted model at \(\predvar\) is a random variable, because it depends on the training set \(\trainset\). The variance of that prediction is therefore the variance of that random variable.
Theorem 4 (The bias as the average fit minus the true mean function)
Theorem 4 (The bias as the average fit minus the true mean function) The bias of the prediction at \(\predvar\) equals the average fit minus the true mean function value:
\[ \bias{\predval} = \avgfitf{\predvar} - \truemeanf{\predvar} . \]
Proof
Proof. The new outcome \(\Outvar\) is independent of \(\trainset\), and its mean is the true mean function value \(\truemeanf{\predvar}\) because the noise has mean zero by Equation 20.
\[ \begin{aligned} \bias{\predval} &= \Ep_{\trainset, \Outvar}\sb{\prederr} && \text{(definition of bias)} \\ &= \Ep_{\trainset, \Outvar}\sb{\devof{\predval}{\Outvar}} && \text{(definition of prediction error)} \\ &= \Epredval - \Ep_{\Outvar}\sb{\Outvar} && \text{(linearity of expectation; $\Outvar$ is independent of $\trainset$)} \\ &= \Epredval - \truemeanf{\predvar} && \text{(the noise has mean zero)} \\ &= \avgfitf{\predvar} - \truemeanf{\predvar} && \text{(definition of the average fit)} . \end{aligned} \]
Example 26 (The bias as the average fit minus the true mean function at four cylinders)
Example 26 (The bias as the average fit minus the true mean function at four cylinders) Continue Example 25 with the same 2000 fitted lines. The bias is the expected prediction error against a new outcome (Equation 22). The new outcome has mean \(\truemeanf{4}\), so the bias equals the average estimation error of the lines. Compute that average, and compare it with the average fit minus the truth:
[-0.56 -0.56]
# The bias from its definition: the mean error over the lines, taking the new outcome at its mean.
bias_def_baf <- mean(preds_af - f4_bv)
# The bias from the theorem: the average fit minus the truth.
bias_thm_baf <- mean(preds_af) - f4_bv
round(c(definition = bias_def_baf, theorem = bias_thm_baf), 2)definition theorem
-0.56 -0.56
Both routes give -0.56 miles per gallon, as Theorem 4 says.
Theorem 5 (The variance equals the variance of the estimation error)
Theorem 5 (The variance equals the variance of the estimation error) The variance of the prediction of the fitted model at \(\predvar\) equals the variance of the estimation error of that prediction:
\[ \Var{\predval} = \Var{\erf{\predval}} . \]
Proof
Proof. The mean of the estimation error is the average fit minus the true mean function value, which is the bias by Theorem 4. Subtracting the bias from the error leaves the fit minus the average fit.
\[ \begin{aligned} \erf{\predval} - \bias{\predval} &= \paren{\predval - \truemeanf{\predvar}} - \paren{\Epredval - \truemeanf{\predvar}} && \text{(definition of estimation error; @thm-bias-average-fit)} \\ &= \predval - \truemeanf{\predvar} - \Epredval + \truemeanf{\predvar} && \text{(removing parentheses)} \\ &= \predval - \Epredval + \paren{\truemeanf{\predvar} - \truemeanf{\predvar}} && \text{(reordering)} \\ &= \predval - \Epredval + 0 && \text{(a number minus itself is zero)} \\ &= \predval - \Epredval && \text{(adding zero changes nothing)} . \end{aligned} \]
The error’s variance is its expected squared deviation from its own mean, and its mean is the bias. So the variance of the error is the expected square of the difference above. By Equation 23, the variance of the fit is the expected square of the same difference. So the two variances are equal.
Example 27 (The variance as the spread around the average fit at four cylinders)
Example 27 (The variance as the spread around the average fit at four cylinders) Continue Example 25 with the same 2000 fitted lines. Compute the variance of the lines (Equation 23), and compare it with the variance of their estimation error:
# The variance from the definition: the spread of the lines around the average fit.
var_def_vaf = np.mean((preds_af - preds_af.mean()) ** 2)
# The variance from the theorem: the spread of the estimation error around its mean, the bias.
err_vaf = preds_af - f4_bv
var_thm_vaf = np.mean((err_vaf - err_vaf.mean()) ** 2)
print(np.round([var_def_vaf, var_thm_vaf], 2))[1.86 1.86]
# The variance from the definition: the spread of the lines around the average fit.
var_def_vaf <- mean((preds_af - mean(preds_af))^2)
# The variance from the theorem: the spread of the estimation error around its mean, the bias.
err_vaf <- preds_af - f4_bv
var_thm_vaf <- mean((err_vaf - mean(err_vaf))^2)
round(c(definition = var_def_vaf, theorem = var_thm_vaf), 2)definition theorem
1.86 1.86
Both routes give 1.86 squared miles per gallon, as Theorem 5 says.
Five training sets, each of five points, each get four fitted models, one for each polynomial degree from 1 to 4. Both tabs draw the training sets with the SyncRNG package [20] from the same seed, so they draw the same data, and add normal noise (standard deviation 0.13) to the true mean function:
import numpy as np
import matplotlib.pyplot as plt
from SyncRNG import SyncRNG
def truth_bv(x):
return 0.55 - 0.9 * x + 0.6 * np.sin(6 * x)
x_bv = np.array([0.1, 0.3, 0.5, 0.7, 0.9])
grid_bv = np.linspace(0.05, 0.95, 100)
rng_bv = SyncRNG(seed=37)
# The first draws from a small seed are poorly mixed, so skip the first 100.
# With seed 37 the spread rises with the degree, and the line and quadratic have about the same bias; the text below the figure depends on that.
for _ in range(100):
rng_bv.rand()0.01295785838738086
0.002371650189161304
0.2968793136533354
0.07564082206226896
3.2246112823486376e-05
0.0008095083758234991
0.13812292250804625
0.5122318337671466
0.020569282583892377
0.5711903637275109
0.4307010236661888
0.3126481119543319
0.8247087667696191
0.25056422734633127
0.01982539240270856
0.656618150183932
0.0035579456016421374
0.2656588805839423
0.005491338204592475
0.148991678375751
0.753784512402491
0.10312855453230457
0.5371983668301263
0.1669946967158469
0.4377464081626392
0.38558150036260547
0.6718784791883091
0.51529568550177
0.14854685007594548
0.754973555216567
0.5450272767338911
0.43828323250636525
0.2673391164280478
0.12641562381759305
0.15407474641688193
0.04990393551997848
0.010626258095726388
0.2968825057614599
0.7246106821112346
0.10357670765370147
0.018643392249941854
0.0019647027365863354
0.7284108900930744
0.1998202099930498
0.03204639488831167
0.5046537269372501
0.14734604465775214
0.7997305849567068
0.0631144754588605
0.2876713678706442
0.12506534811109324
0.7309028850868355
0.8767352423165007
0.919934593373911
0.504620853345842
0.016636913875117922
0.751537843141706
0.12165764183737357
0.12537119863554855
0.02983465418219571
0.4856160543859013
0.014024667674675606
0.40144105535000624
0.3228049515746539
0.32815250800922563
0.5642997468821713
0.8135610721074057
0.407059870427475
0.03990194620564586
0.37533342209644677
0.5010020500049003
0.36724307900294717
0.014961027540266536
0.09627288859337584
0.9435006731655463
0.5167076007928707
0.5061757061630495
0.3787356223911053
0.3909605515655136
0.7703797249123466
0.742255591787399
0.8178380983881665
0.17199150472879438
0.9746278689708576
0.8238326623104526
0.8628171815071268
0.020832758862525256
0.1961464814376089
0.6946366745978605
0.2967190681956713
0.07039282610639941
0.2660218474920843
0.6103706422727565
0.8512498410418643
0.5316741552669563
0.022498969919979607
0.5824551463592806
0.008310291450470698
0.3066714736633008
0.881415901705624
def std_normal_bv():
# One standard normal draw from two uniform draws (the Box-Muller transform).
u1, u2 = rng_bv.rand(), rng_bv.rand()
return np.sqrt(-2 * np.log(u1)) * np.cos(2 * np.pi * u2)
# Five training sets of five points.
samples_bv = [truth_bv(x_bv) + 0.13 * np.array([std_normal_bv() for _ in x_bv]) for _ in range(5)]
titles_bv = ["A line: high bias, low variance", "A quadratic", "A cubic", "A quartic: low bias, high variance"]
fig, axes = plt.subplots(2, 2, figsize=(6.5, 5), sharex=True, sharey=True, layout="constrained")
for degree, ax, title in zip(range(1, 5), axes.flat, titles_bv):
# One fit per training set, evaluated on the grid.
fits = np.array([np.polyval(np.polyfit(x_bv, y, degree), grid_bv) for y in samples_bv])
for fit in fits:
ax.plot(grid_bv, fit, color="#0072B2", linewidth=1);
ax.plot(grid_bv, truth_bv(grid_bv), color="black", linestyle="--", linewidth=1.2);
ax.set_title(title);
for ax in axes[1]:
ax.set_xlabel("Feature, x");
for ax in axes[:, 0]:
ax.set_ylabel("Response, y");
fig.legend(
handles=[
plt.Line2D([], [], color="#0072B2", label="One fit per training set"),
plt.Line2D([], [], color="black", linestyle="--", label="The true mean function"),
],
loc="outside lower center",
ncol=2,
frameon=False,
);
plt.show()library(ggplot2)
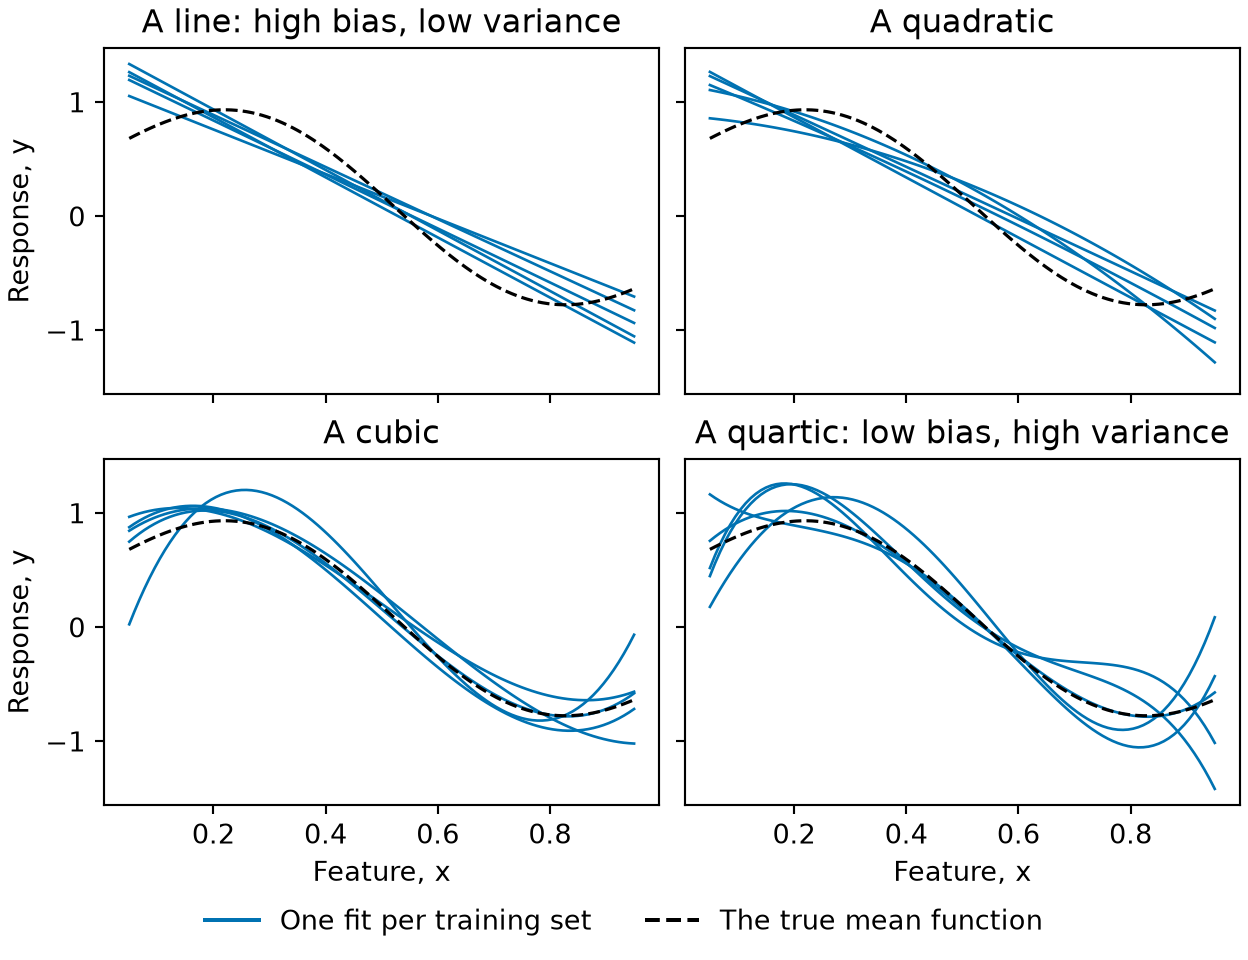
library(SyncRNG)
truth_bv <- function(x) 0.55 - 0.9 * x + 0.6 * sin(6 * x)
x_bv <- c(0.1, 0.3, 0.5, 0.7, 0.9)
grid_bv <- seq(0.05, 0.95, length.out = 100)
rng_bv <- SyncRNG(seed = 37)
# The first draws from a small seed are poorly mixed, so skip the first 100.
# With seed 37 the spread rises with the degree, and the line and quadratic have about the same bias; the text below the figure depends on that.
for (i in 1:100) rng_bv$rand()
# One standard normal draw from two uniform draws (the Box-Muller transform).
std_normal_bv <- function() {
u <- c(rng_bv$rand(), rng_bv$rand())
sqrt(-2 * log(u[1])) * cos(2 * pi * u[2])
}
# Five training sets of five points, each fitted by a polynomial of degree 1 to 4.
fits_bv <- do.call(rbind, lapply(1:5, function(set) {
y <- truth_bv(x_bv) + 0.13 * replicate(5, std_normal_bv())
do.call(rbind, lapply(1:4, function(degree) {
fit <- lm(y ~ poly(x_bv, degree, raw = TRUE))
data.frame(
set = set,
degree = factor(degree, levels = 1:4, labels = c("A line: high bias, low variance", "A quadratic", "A cubic", "A quartic: low bias, high variance")),
x = grid_bv,
fit = predict(fit, data.frame(x_bv = grid_bv))
)
}))
}))
truth_df_bv <- data.frame(x = grid_bv, fit = truth_bv(grid_bv))
# The spread of the five fits: their standard deviation at each x, averaged over the grid.
spread_bv <- sapply(split(fits_bv, fits_bv$degree), function(d) mean(tapply(d$fit, d$x, sd)))
ggplot(fits_bv, aes(x, fit)) +
geom_line(aes(group = set, colour = "One fit per training set", linetype = "One fit per training set")) +
geom_line(data = truth_df_bv, aes(colour = "The true mean function", linetype = "The true mean function")) +
facet_wrap(~degree, nrow = 2) +
scale_colour_manual(values = c("One fit per training set" = "#0072B2", "The true mean function" = "black")) +
scale_linetype_manual(values = c("One fit per training set" = "solid", "The true mean function" = "dashed")) +
labs(x = "Feature, x", y = "Response, y", colour = NULL, linetype = NULL)Five points and five parameters: each quartic passes through all five points of its own training set and swings between them, which is the variability the bottom-right panel shows. The line has two parameters and barely moves, and the quadratic and the cubic sit between the two. The spread of the five fits, averaged over the grid, is 0.08 for the line, 0.10 for the quadratic, 0.13 for the cubic and 0.18 for the quartic, so here it rises with every step in the degree.
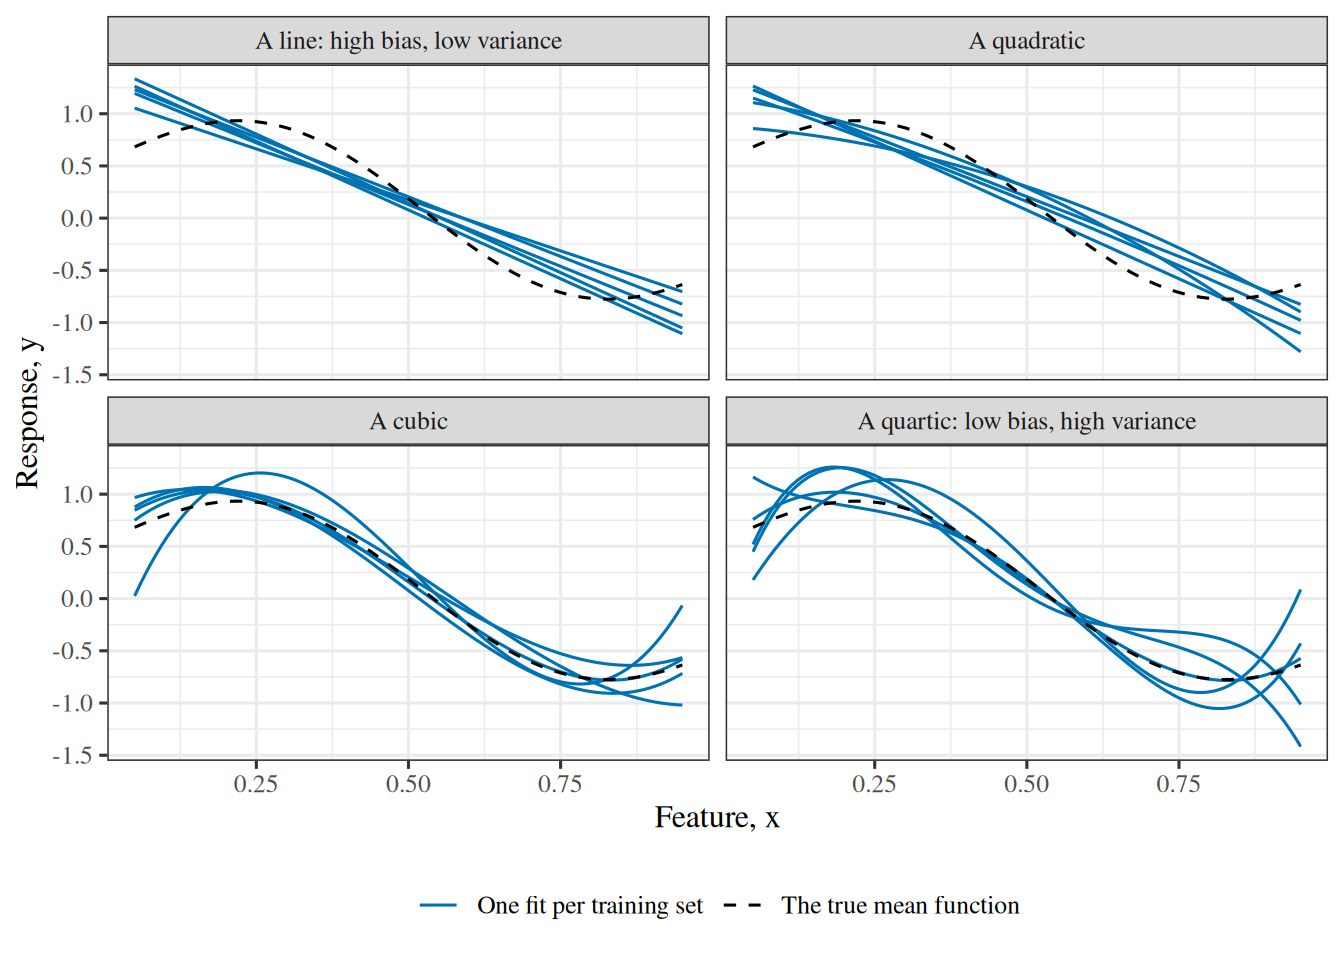
Theorem 6 (Separating the noise from the expected error)
Theorem 6 (Separating the noise from the expected error) Choose an input value \(x\), and let the output variable \(Y = \truemeanf{x} + \noise\) as in Equation 20, where \(\noise\) has mean \(0\) and variance \(\varpar\) and is independent of the training set \(\trainset\). Then the expected squared error at \(x\) is the noise variance \(\varpar\) plus the model’s own expected squared error:
\[ \Expfc{\trainset, \noise}{\sqf{Y - \predval}} = \varpar + \Expfc{\trainset}{\sqf{\truemeanf{x} - \predval}} . \tag{24}\]
Proof
Proof. This is the statistics notes’ theorem that the expected squared prediction error is the noise variance plus the expected squared estimation error, applied to the prediction \(\predval\) of the mean \(\truemeanf{x}\).
Example 28 (Separating the noise at four cylinders)
Example 28 (Separating the noise at four cylinders) Continue Example 24 with the same 2000 fitted lines, at \(x = 4\) cylinders, where \(\truemeanf{4}\) is the population mean mpg of the four-cylinder cars and the noise is how far a single car sits from that population mean. Compute the left side of Equation 24 directly, and then the noise variance plus the model’s own expected squared error:
y4_sn = mpg_af[cyl_af == 4]
f4_sn = y4_sn.mean()
# The left side: average the squared error over every line and every car.
left_sn = np.mean((y4_sn[None, :] - preds_af[:, None]) ** 2)
noise_sn = np.mean((y4_sn - f4_sn) ** 2)
model_sn = np.mean((f4_sn - preds_af) ** 2)
print(np.round([left_sn, noise_sn, model_sn, noise_sn + model_sn], 2))[34.18 31.99 2.18 34.18]
left noise model sum
34.18 31.99 2.18 34.18
The expected squared error is 34.18, and the noise variance 31.99 plus the model’s own expected squared error 2.18 add to 34.18, as Theorem 6 says.
Theorem 7 (Separating the bias from the model’s own error)
Theorem 7 (Separating the bias from the model’s own error) Choose an input value \(x\), let \(\truemeanf{x}\) be the true mean function of the outcome variable given the input value \(x\) in Equation 20, and let \(\avgfitf{x}\) be the average fit of Equation 21. Then the expected squared distance between the truth and the fitted model is the squared bias plus the variance:
\[ \Expfc{\trainset}{\sqf{\truemeanf{x} - \predval}} = \sqf{\truemeanf{x} - \Epredvalf{x}} + \Expfc{\trainset}{\sqf{\predval - \Epredvalf{x}}} . \tag{25}\]
Proof
Proof. The statistics notes work this as an exercise, separating the bias.
Example 29 (Separating the bias at four cylinders)
Example 29 (Separating the bias at four cylinders) Continue Example 24 with the same 2000 fitted lines, at \(x = 4\) cylinders, where \(\truemeanf{4}\) is the population mean mpg of the four-cylinder cars. Compute the left side of Equation 25 directly, and then the squared bias plus the variance:
f4_sb = mpg_af[cyl_af == 4].mean()
# The left side: average the squared distance from mu(4) over the lines.
left_sb = np.mean((f4_sb - preds_af) ** 2)
bias2_sb = (f4_sb - preds_af.mean()) ** 2
variance_sb = np.mean((preds_af - preds_af.mean()) ** 2)
print(np.round([left_sb, bias2_sb, variance_sb, bias2_sb + variance_sb], 2))[2.18 0.32 1.86 2.18]
left bias2 variance sum
2.18 0.32 1.86 2.18
The model’s own expected squared error is 2.18, and the squared bias 0.32 plus the variance 1.86 add to 2.18, as Theorem 7 says.
Theorem 8 (Bias–variance decomposition)
Theorem 8 (Bias–variance decomposition) Choose an input value \(x\), and let the output variable \(Y = \truemeanf{x} + \noise\) as in Equation 20, where \(\noise\), the noise in this new output, has mean \(0\) and variance \(\varpar\) and is independent of the training set \(\trainset\), whose outputs contain their own separate noise draws. Let \(\predval\) be the prediction at \(x\) of the model a learning algorithm fits to \(\trainset\), which varies with \(\trainset\), and \(\avgfitf{x}\) be the average fit of that prediction. Under squared-error loss, the expected error at \(x\) splits into three terms. They are the square of the bias \(\biassymf{\predval}\) of the prediction, the variance \(\varsymf{\predval}\) of the prediction, and the variance \(\irrerr\) of the noise. Here \(\biassymf{\predval}\) and \(\varsymf{\predval}\) are short forms of \(\bias{\predval}\) and \(\Var{\predval}\):
\[ \Expfc{\trainset, \noise}{\sqf{Y - \predval}} = \sqf{\biassymf{\predval}} + \varsymf{\predval} + \irrerr . \tag{26}\]
Proof
Proof. By Theorem 6 and Theorem 7, the expected error is the sum of the variance \(\irrerr\) of the noise, \(\sqf{\truemeanf{x} - \Epredvalf{x}}\), and \(\Expfc{\trainset}{\sqf{\predval - \Epredvalf{x}}}\). The first is \(\irrerr\) itself. The second is the square of the bias of the prediction, because that bias is the average fit of the prediction minus the value of the true mean function of \(Y\) given \(X = x\), by Theorem 4. A square does not change when its base changes sign. The third is the variance of the prediction, by Equation 23.
Remark 19 (The decomposition holds for any algorithm)
Remark 19 (The decomposition holds for any algorithm). Equation 26 holds for any learning algorithm, and \(\noise\) need not be normal. The statistics notes prove it as the bias, variance and noise decomposition of the expected squared prediction error.
Example 30 (Splitting the error of the cylinders line at four cylinders)
Example 30 (Splitting the error of the cylinders line at four cylinders) Continue Example 24 with the same 2000 fitted lines. The input is \(x = 4\) cylinders, and the output \(Y\) is the mpg of a four-cylinder car, so \(\truemeanf{4}\) is the population mean mpg of the four-cylinder cars and the noise is how far a single car sits from that population mean. Compute the three terms of Equation 26 and, separately, the expected squared error itself:
# Four-cylinder cars: their mean mpg is mu(4), and their spread is the noise.
y4_bv = mpg_af[cyl_af == 4]
bias2_bv = (y4_bv.mean() - preds_af.mean()) ** 2
variance_bv = np.mean((preds_af - preds_af.mean()) ** 2)
noise_bv = np.mean((y4_bv - y4_bv.mean()) ** 2)
# The left side: average the squared error over every line and every car.
error_bv = np.mean((y4_bv[None, :] - preds_af[:, None]) ** 2)
# Its Monte Carlo standard error: each line's mean squared error over the cars is one draw.
line_err_bv = np.mean((y4_bv[None, :] - preds_af[:, None]) ** 2, axis=1)
mc_se_bv = line_err_bv.std(ddof=1) / np.sqrt(len(line_err_bv))
print(np.round([bias2_bv, variance_bv, noise_bv, bias2_bv + variance_bv + noise_bv, error_bv], 2), round(mc_se_bv, 3))[ 0.32 1.86 31.99 34.18 34.18] 0.067
y4_bv <- auto_af$mpg[auto_af$cylinders == 4]
bias2_bv <- (mean(y4_bv) - mean(preds_af))^2
variance_bv <- mean((preds_af - mean(preds_af))^2)
noise_bv <- mean((y4_bv - mean(y4_bv))^2)
# The left side: average the squared error over every line and every car.
err_mat_bv <- outer(preds_af, y4_bv, function(h, y) (y - h)^2)
error_bv <- mean(err_mat_bv)
# Its Monte Carlo standard error: each line's mean squared error over the cars is one draw.
line_err_bv <- rowMeans(err_mat_bv)
mc_se_bv <- sd(line_err_bv) / sqrt(length(line_err_bv))
c(round(c(bias2 = bias2_bv, variance = variance_bv, noise = noise_bv,
sum = bias2_bv + variance_bv + noise_bv, error = error_bv), 2),
mc_se = round(mc_se_bv, 3)) bias2 variance noise sum error mc_se
0.320 1.860 31.990 34.180 34.180 0.067
The three terms add to 34.18, which is the expected squared error 34.18 computed directly, as Theorem 8 says. That identity is exact for the 2000 lines and the cars used here. As an estimate of the expected squared error over all training sets, 34.18 has a 95% Monte Carlo confidence interval of 34.05 to 34.31. Most of it is the noise variance, 32.0: even a model with no bias and no variance would have that expected squared error on a four-cylinder car. The squared bias is only 0.32 and the variance 1.86. The decomposition holds for any learning algorithm, so the same arithmetic would split the error of a tree or a neural network.
Watch
Abu-Mostafa derives the same decomposition in his Caltech lecture on the bias–variance trade-off, from 16:43, and he reads bias and variance from learning curves, from 46:16 [21], Lecture 8.
Watch
Hastie and Tibshirani follow the bias–variance trade-off [6], video 2.3.
Watch
Weinberger explains the bias–variance decomposition [22], Lecture 19.
Watch
Starmer explains bias and variance [23] without the algebra.
Read
GeeksforGeeks explains the bias–variance trade-off [24].
Exercise 30 (Read the three terms)
Exercise 30 (Read the three terms) Equation 26 splits the expected squared error at \(x\) into three terms. For each one, say what it measures, which panel of Figure 17 shows it large (if any), and whether a different learning algorithm or more data could make it smaller.
Solution 30. Only two of the three can be changed.
The first term, \(\sqf{\truemeanf{x} - \Epredvalf{x}}\), is the square of the bias (Definition 29) of \(\predval\) as an estimate of \(\truemeanf{x}\): how far the algorithm’s average fit is from the truth. It is a property of the family of models, not of any one fit. A straight line fitted to a curve has bias no amount of data will remove, because the average of many lines is still a line. That is the top-left panel of Figure 17, and the quadratic in the top-right panel behaves the same way: the five fits agree with each other and all differ from the truth in the same way. A different family can shrink it; more data cannot. A model whose error is mostly this term is said to underfit.
The second term, \(\Expfc{\trainset}{\sqf{\predval - \Epredvalf{x}}}\), is the variance (Definition 30) of \(\predval\): how far a single fit is from the average fit. It is a property of how strongly the algorithm reacts to its training data. The bottom-right panel of Figure 17 shows five quartics fitted to five samples from the same world, tracking the truth on average and differing strongly between the data points. More data or a less flexible family can shrink it. A model whose error is mostly this term is said to overfit.
The third term, \(\varpar\), is the noise in \(Y\) itself. No panel of Figure 17 shows it, because the figure plots only fitted curves and the truth, never the noisy data, and \(\varpar\) is the same for every family. It is not a fact about the model or the algorithm, and no method in these notes reduces it. It sets a lower limit: no model, however good, predicts better than \(\varpar\) on average. When a reported error is near that limit, little further improvement is possible; when a reported error is below it, something is wrong with how it was measured.
Definition 31 (Underfitting)
Definition 31 (Underfitting) A model is underfitting when the bias term of Equation 26 is large enough to dominate its error.
Definition 32 (Overfitting)
Definition 32 (Overfitting) A model is overfitting when the variance term of Equation 26 is large enough to dominate its error.
See overfitting in the statistics notes.
# HTML formats get an interactive plotly figure; the handout and other formats
# get the same two curves drawn with base R graphics.
set.seed(571)
truth <- function(x) sin(2 * pi * x)
noise_sd <- 0.3
# Fifteen training points and 500 fresh held-out points from the same curve.
n_train <- 15
n_held_out <- 500
x_train <- runif(n_train)
y_train <- truth(x_train) + rnorm(n_train, sd = noise_sd)
x_held <- runif(n_held_out)
y_held <- truth(x_held) + rnorm(n_held_out, sd = noise_sd)
# For each degree, fit by least squares on the training set and record the mean
# squared error on both sets, with the standard error of the held-out one.
degrees <- 1:10
errors <- sapply(degrees, function(d) {
fit <- lm(y_train ~ poly(x_train, d))
train_resid <- residuals(fit)
held_pred <- predict(fit, newdata = data.frame(x_train = x_held))
held_sq <- (y_held - held_pred)^2
c(
train = mean(train_resid^2),
held = mean(held_sq),
held_se = sd(held_sq) / sqrt(n_held_out)
)
})
errors <- as.data.frame(t(errors))
errors$degree <- degrees
if (knitr::is_html_output()) {
library(plotly)
widget <- plot_ly() |>
add_trace(
data = errors, x = ~degree, y = ~train, type = "scatter",
mode = "lines+markers", name = "training error",
line = list(color = "#1f77b4"), marker = list(color = "#1f77b4")
) |>
add_trace(
data = errors, x = ~degree, y = ~held, type = "scatter",
mode = "lines+markers", name = "held-out error (95% CI)",
line = list(color = "#d95f02", dash = "dash"),
marker = list(color = "#d95f02"),
error_y = list(type = "data", array = ~ 1.96 * held_se, color = "#d95f02")
) |>
layout(
xaxis = list(title = "polynomial degree (flexibility)", dtick = 1),
yaxis = list(title = "mean squared error", rangemode = "tozero"),
legend = list(orientation = "h", y = -0.2),
margin = list(t = 10)
) |>
config(displaylogo = FALSE, responsive = TRUE)
# The alt text: a plotly widget has none of its own.
htmltools::div(
role = "img",
`aria-label` = paste(
"Interactive plot of training error and held-out error against",
"polynomial degree. Training error falls steadily; held-out error falls,",
"bottoms out at a moderate degree and then rises."
),
widget
)
} else {
# The legend goes below the plot, in a bottom margin made wide enough for it.
op <- par(mar = c(8, 4, 1, 1))
plot(
errors$degree, errors$held, type = "b", col = "#d95f02", lty = 2, pch = 16,
ylim = c(0, max(errors$held + 1.96 * errors$held_se)),
xlab = "polynomial degree (flexibility)", ylab = "mean squared error"
)
arrows(
errors$degree, errors$held - 1.96 * errors$held_se,
errors$degree, errors$held + 1.96 * errors$held_se,
angle = 90, code = 3, length = 0.03, col = "#d95f02"
)
lines(errors$degree, errors$train, type = "b", col = "#1f77b4", pch = 16)
legend(
"bottom", c("training error", "held-out error (95% CI)"),
col = c("#1f77b4", "#d95f02"), lty = c(1, 2), pch = 16, bty = "n",
horiz = TRUE, inset = c(0, -0.5), xpd = TRUE
)
par(op)
}Read
GeeksforGeeks explains underfitting and overfitting [25].
Read
Domingos, a University of Washington professor, gives twelve lessons on generalization, overfitting and feature engineering in A Few Useful Things to Know About Machine Learning [26].
Exercise 31 (Predict weight from height)
Exercise 31 (Predict weight from height) Suppose we predict a person’s weight from their height. Could any model, given enough data, drive its expected squared error to zero?
Solution 31. No. The two are related, and yet no function of height alone will ever return weight exactly, because two people of the same height differ in ways that height does not record. That leftover spread is called the residual variance: the part of the output that the inputs do not determine.
Exercise 32 (Predict weight from height (part 2))
Exercise 32 (Predict weight from height (part 2)) Use the setup of Exercise 31.
If not, what would lower the minimum possible error?
Solution 32. Residual variance depends on the features and not on the model, so a better model leaves it unchanged. Record frame size too, and some of the spread can move out of the residual variance and into the part a model can learn. Averaged over the inputs, the residual variance does not rise when a feature is added, and it falls exactly when the feature changes the conditional mean of weight given height.
Definition 33 (Residual variance)
Definition 33 (Residual variance) The residual variance (also called the irreducible error) at \(\predvar\) is the variance of the noise \(\noise\) in the noise model: the variance of the output \(\Outvar\) around its true mean function at \(\predvar\),
\[ \varpar \eqdef \Var{\noise} = \condVar{\Outvar}{\Predvar = \predvar} = \condE{\sqf{\Outvar - \truemeanf{\predvar}}}{\Predvar = \predvar} . \tag{27}\]
Remark 20 (What “irreducible” means)
Remark 20 (What “irreducible” means). The residual variance is the part of the expected squared error in Equation 26 that no choice of model or algorithm changes. It is a variance, a component of the expected loss, and not an error.
It is irreducible only given the inputs. It depends on which inputs the model observes. Averaged over new inputs, the residual variance is \(\E{\condVar{\Outvar}{\Predvar}}\). By the law of total variance, adding a feature never raises this average, and lowers it exactly when the feature changes the conditional mean of \(\Outvar\) given the other inputs. At a single \(\predvar\), the residual variance can rise or fall when a feature is added.
Remark 21 (Estimating the residual variance)
Remark 21 (Estimating the residual variance). The residual variance is a population quantity, which \(\evarpar\), computed from the residuals of a fitted model, estimates.
Remark 22 (Residual variance in the statistics notes)
Remark 22 (Residual variance in the statistics notes). The statistics notes define the same residual variance for the prediction at one covariate value \(x\). It is the \(\varpar\) term in their bias, variance and noise decomposition of the expected squared prediction error, which they prove step by step.
# HTML formats get an interactive plotly figure; the handout and other formats
# get the same points as a static SVG from tools/make_big_ideas_figures.py.
if (knitr::is_html_output()) {
library(plotly)
truth <- function(x) 0.5 + 0.3 * sin(5 * x)
noise_sd <- 0.08
# The points of the static figure. A fixed sine-based sequence stands in for
# a random draw, so both versions show the same points; the noise is uniform
# with standard deviation noise_sd.
k <- 0:29
wobble <- function(j) {
v <- sin(j * 12.9898) * 43758.5453
2 * (v - floor(v)) - 1
}
x_obs <- 0.02 + 0.96 * k / 29
y_obs <- truth(x_obs) + noise_sd * sqrt(3) * wobble(211 + 5 * k)
x_grid <- seq(0, 1, length.out = 200)
widget <- plot_ly() |>
add_trace(
x = x_grid, y = truth(x_grid) + noise_sd, type = "scatter", mode = "lines",
line = list(color = "rgba(0,0,0,0)"), hoverinfo = "skip", showlegend = FALSE
) |>
add_trace(
x = x_grid, y = truth(x_grid) - noise_sd, type = "scatter", mode = "lines",
fill = "tonexty", fillcolor = "rgba(217,95,2,0.18)",
line = list(color = "rgba(0,0,0,0)"), hoverinfo = "skip",
name = "one noise standard deviation either side"
) |>
add_trace(
x = x_grid, y = truth(x_grid), type = "scatter", mode = "lines",
name = "the true mean function μ", line = list(color = "#222222")
) |>
add_trace(
x = x_obs, y = y_obs, type = "scatter", mode = "markers",
name = "observations", marker = list(color = "#1f77b4", size = 8)
) |>
layout(
xaxis = list(title = "Feature, x"), yaxis = list(title = "Response, y"),
legend = list(orientation = "h", y = -0.2),
margin = list(t = 10)
) |>
config(displaylogo = FALSE, responsive = TRUE)
# The alt text: a plotly widget has none of its own.
htmltools::div(
role = "img",
`aria-label` = paste(
"Interactive plot of a smooth true mean function with a band of one noise",
"standard deviation on either side and thirty noisy points scattered",
"around it."
),
widget
)
} else {
knitr::include_graphics("../images/big-ideas/irreducible-error.svg")
}Exercise 33 (Error without noise)
Exercise 33 (Error without noise) Imagine a data-generating process with no noise at all: \(\Outvar = \truemeanf{\predvar}\) exactly, with \(\truemeanf{\predvar} = \sin(2.5\pi \predvar)\) on \(-1 \le \predvar \le 1\), a curve with two and a half full waves. A student fits polynomials of degree 1, 3, 5 and 7 by least squares to training sets of \(\nobs = 8\) points, and tests each fit on new points from the same curve.
The degree-7 polynomial passes through all eight training points. Which polynomial do you expect to predict best on new points?
Solution 33. Fit each degree to 200 training sets of \(\nobs = 8\) points, each an equally spaced grid on \([-1, 1]\) shifted a little further along from one set to the next, and split the error on 401 evenly spaced test points with Equation 26. The grids are fixed, not random, so the R and Python tabs compute the same numbers.
import numpy as np
import pandas as pd
# The target, with no noise: the test labels are exactly mu(x).
def f_nn(x):
return np.sin(2.5 * np.pi * x)
n_nn, sets_nn = 8, 200
x_test_nn = np.linspace(-1, 1, 401)
rows_nn = []
for degree in (1, 3, 5, 7):
fits, train_err = [], []
for k in range(sets_nn):
# Each training set is the same equally spaced grid, shifted a little.
# Shifting by hand, rather than drawing random points,
# makes the numbers identical in the R tab.
x = -1 + 2 / n_nn * (np.arange(n_nn) + (k + 0.5) / sets_nn)
coef = np.linalg.lstsq(np.vander(x, degree + 1), f_nn(x), rcond=None)[0]
fits.append(np.vander(x_test_nn, degree + 1) @ coef)
train_err.append(np.mean((np.vander(x, degree + 1) @ coef - f_nn(x)) ** 2))
fits = np.array(fits)
avg_fit = fits.mean(axis=0)
# The three terms of the decomposition. Noise is zero, so there are only two.
bias2 = np.mean((avg_fit - f_nn(x_test_nn)) ** 2)
variance = np.mean(fits.var(axis=0))
rows_nn.append((degree, np.mean(train_err), bias2, variance, bias2 + variance))
print(pd.DataFrame(rows_nn, columns=["degree", "train", "bias2", "variance", "error"]).round(3)) degree train bias2 variance error
0 1 0.494 0.500 0.006 0.506
1 3 0.430 0.441 0.016 0.457
2 5 0.102 0.743 0.389 1.132
3 7 0.000 1.465 0.862 2.327
# The target, with no noise: the test labels are exactly mu(x).
f_nn <- function(x) sin(2.5 * pi * x)
n_nn <- 8
sets_nn <- 200
x_test_nn <- seq(-1, 1, length.out = 401)
nn_results <- do.call(rbind, lapply(c(1, 3, 5, 7), function(degree) {
# Each training set is the same equally spaced grid, shifted a little.
# Shifting by hand, rather than drawing random points,
# makes the numbers identical in the Python tab.
fits <- sapply(seq_len(sets_nn) - 1, function(k) {
x <- -1 + 2 / n_nn * (seq_len(n_nn) - 1 + (k + 0.5) / sets_nn)
design <- outer(x, 0:degree, "^")
coef <- qr.solve(design, f_nn(x))
c(test = drop(outer(x_test_nn, 0:degree, "^") %*% coef),
train = mean((design %*% coef - f_nn(x))^2))
})
test_fits <- fits[seq_along(x_test_nn), ]
avg_fit <- rowMeans(test_fits)
# The three terms of the decomposition. Noise is zero, so there are only two.
bias2 <- mean((avg_fit - f_nn(x_test_nn))^2)
variance <- mean(apply(test_fits, 1, var) * (sets_nn - 1) / sets_nn)
data.frame(degree = degree, train = mean(fits["train", ]),
bias2 = bias2, variance = variance, error = bias2 + variance)
}))
round(nn_results, 3)The cubic has the lowest error, 0.46, and the line is close behind at 0.51. The septic, which fits all eight training points exactly (training error 0.00), has the highest, 2.33.
Expect the low degrees to win, though the degree-7 fit has the best training error. With eight points, the degree-7 fit has no freedom left over, so each shifted training set bends it differently (variance 0.86).
Exercise 34 (Error without noise (part 2))
Exercise 34 (Error without noise (part 2)) Use the setup of Exercise 33.
The residual variance \(\varpar\) of Definition 33 is zero here. Where, then, does the error of the best polynomial come from?
Solution 34. The error comes from the model, not from the world. A line, or even a cubic, cannot follow two and a half waves, so every fit misses the curve in the same way (squared bias 0.50 for the line). A flexible polynomial passes through the curve at the training points and still goes wrong between them, because eight points are too few to pin it down there. Either way, the part of \(\truemean\) the model cannot learn from this much data acts on the fit like noise in the labels, which the definition of deterministic noise below makes precise.
Figure 20 draws the fits behind the table above: the curves each training set produces, their average, and the error by degree.
Definition 34 (Best member of a model family)
Definition 34 (Best member of a model family) The best member \(\bestmod\) of a mean-function model family \(\modelfam\) for a target function \(\truemean\) is the member \(\modmem\) of \(\modelfam\) with the smallest mean squared difference from \(\truemean\), \(\E{\paren{\truemeanf{\Predvar} - \modmemf{\Predvar}}^2}\), where the random predictor \(\Predvar\) is a draw of the predictor \(\predvar\) from the population.
Example 31 (The best line for a curved target)
Example 31 (The best line for a curved target) Let the target \(\truemean\) be a sine curve, and let \(\modelfam\) be the family of straight lines. No line follows a sine curve, but some lines are closer to it than others, averaging the squared gap over the population of \(\predvar\). The closest line is the best member \(\bestmod\). A line fitted to a training set is a different object, because it depends on the data and so usually differs from \(\bestmod\).
Definition 35 (Deterministic noise)
Definition 35 (Deterministic noise) The deterministic noise of a mean-function model family \(\modelfam\) at \(\predvar\) is the part of \(\truemeanf{\predvar}\) that the family cannot express: \(\truemeanf{\predvar} - \bestmodf{\predvar}\), where \(\bestmod\) is the best member of \(\modelfam\) (Definition 34).
Remark 23 (Deterministic versus stochastic noise)
Remark 23 (Deterministic versus stochastic noise). Deterministic noise differs from the label noise \(\noise\) of Equation 20, which we call stochastic noise when we need to tell the two apart, in two ways:
Watch
Abu-Mostafa separates stochastic from deterministic noise in his Caltech lecture on overfitting [21], Lecture 11; the same chapter of his book, Abu-Mostafa et al. [1, Ch. 4], gives the written treatment.
Exercise 35 (Why the ranking was wrong)
Exercise 35 (Why the ranking was wrong) Table 2 ranked the fitted polynomials by their error on the training set, and the quartic came first. Which of the three terms of Equation 26 does training-set error measure?
Solution 35. None of them. Training-set error is an optimistic estimate of the expected error on the left-hand side of Equation 26.
Exercise 36 (Why the ranking was wrong (part 2))
Exercise 36 (Why the ranking was wrong (part 2)) Use the setup of Exercise 35.
Why does the ranking by training-set error favour the most flexible family?
Remark 24 (The bias-variance tradeoff)
Remark 24 (The bias-variance tradeoff). Across the families of Figure 17, more flexibility gives lower bias but higher variance: the line and the quadratic miss the truth in the same way every time, the cubic follows it closely, and the quartics swing apart from one another. Because of that trade, model selection needs careful study and is not a routine step. For the crime data, ranking the polynomials by training error put the quartic first because it is the most flexible, not because it predicts best (Exercise 35), so choosing the degree takes more than comparing the training errors.
Exercise 37 (Changes along the tradeoff)
Exercise 37 (Changes along the tradeoff) List changes you could make to the data or the model that shrink one of the two correctable terms of Equation 26. For each, say in which direction it changes the bias term and in which direction it changes the variance term.
Solution 37. Both correctable terms change in opposite directions as flexibility changes, so the usual changes are:
Exercise 38 (Why would anyone choose the less flexible model?)
Exercise 38 (Why would anyone choose the less flexible model?) A straight line can only tilt; a high-degree polynomial can bend almost any way. Give two reasons the city of Section 2 might still prefer the straight line: one that applies if it wants to explain how crime varies with income, and one that applies even if it only wants to predict.
Solution 38.
To explain, the line is readable. Its slope says how much the predicted crime rate changes per unit of income, and its sign says in which direction. The quartic of Exercise 17 has no single number like that: each of its five coefficients multiplies a different power of income, so none of them alone says how crime changes with income, even when the curve predicts well. James et al. [27, Sec. 2.1.3] calls this the trade-off between flexibility and interpretability.
To predict, the line may simply be more accurate. With five neighbourhoods, a flexible fit spends its freedom chasing those five points. Figure 17 shows what that costs: flexible fits to different samples from the same population disagree wildly with each other, so a prediction for a sixth neighbourhood depends on which five happened to be sampled. That is the variance term of Equation 26, so the quartic’s perfect training fit in Exercise 17 was no evidence that it predicts well. James et al. [27, Sec. 2.1.3] makes the same point: even when only prediction matters, a less flexible method often predicts more accurately, because a very flexible one can overfit (Definition 32).
Neither reason makes the line the right choice by default. If the true relationship bends, the line’s bias does not shrink with more data.
Definition 36 (Regularization)
Definition 36 (Regularization) Regularization is fitting a model by minimizing its empirical risk plus a penalty on the size of its parameters [28]. With a penalty function \(\operatorname{pen}(\param) \ge 0\) and a penalty weight \(\lambda \ge 0\), regularization minimizes the objective plus the weighted penalty,
\[ J(\param) + \lambda \operatorname{pen}(\param) . \tag{28}\]
Example 32 (Regularizing the crime-data quartic)
Example 32 (Regularizing the crime-data quartic) For the polynomial fits to the crime data (Table 2), a penalty on the coefficients makes a large coefficient on \(x^4\) costly, so the fitted quartic moves closer to a flatter curve that bends to fit each of the five neighbourhoods less closely.
Definition 37 (Penalty weight (regularization strength))
Definition 37 (Penalty weight (regularization strength)) A penalty weight \(\lambda \ge 0\), also called the regularization strength, is the number that scales a penalty \(\operatorname{pen}(\param) \ge 0\), a nonnegative measure of the size of a model’s parameters, when the penalty is added to the training objective in regularization. The value \(\lambda = 0\) leaves the objective unchanged, and a larger \(\lambda\) penalizes large parameters more heavily.
# HTML formats get an interactive plotly figure (click the legend to hide a
# curve); the handout and other formats get the same curves with base R
# graphics.
set.seed(571)
truth <- function(x) sin(2 * pi * x)
n_points <- 12
x_obs <- sort(runif(n_points))
y_obs <- truth(x_obs) + rnorm(n_points, sd = 0.3)
# A degree-9 polynomial basis in a rescaled x, so that the powers are on
# comparable scales: a column of ones, then x^1 through x^9.
degree <- 9
basis <- function(x) cbind(1, outer(2 * x - 1, 1:degree, "^"))
# Penalized least squares: minimize the squared error plus the penalty weight
# times the sum of squared coefficients, leaving the intercept unpenalized. The
# tiny extra diagonal term only keeps the unpenalized fit numerically solvable.
penalized_fit <- function(penalty) {
design <- basis(x_obs)
penalty_matrix <- diag(c(0, rep(1, degree)))
solve(
crossprod(design) + penalty * penalty_matrix + 1e-10 * diag(degree + 1),
crossprod(design, y_obs)
)
}
penalties <- c(0, 0.001, 0.1)
labels <- c("no penalty", "penalty weight 0.001", "penalty weight 0.1")
colors <- c("#d95f02", "#1b9e77", "#7570b3")
x_grid <- seq(0, 1, length.out = 200)
curves <- lapply(
penalties,
function(p) drop(basis(x_grid) %*% penalized_fit(p))
)
if (knitr::is_html_output()) {
library(plotly)
widget <- plot_ly() |>
add_trace(
x = x_grid, y = truth(x_grid), type = "scatter", mode = "lines",
name = "the true curve", line = list(color = "#999999", dash = "dot")
)
for (i in seq_along(penalties)) {
widget <- widget |>
add_trace(
x = x_grid, y = curves[[i]], type = "scatter", mode = "lines",
name = labels[i], line = list(color = colors[i])
)
}
widget <- widget |>
add_trace(
x = x_obs, y = y_obs, type = "scatter", mode = "markers",
name = "observations", marker = list(color = "#1f77b4", size = 8)
) |>
layout(
xaxis = list(title = "Feature, x"),
yaxis = list(title = "Response, y", range = c(-2, 2)),
legend = list(orientation = "h", y = -0.2),
margin = list(t = 10)
) |>
config(displaylogo = FALSE, responsive = TRUE)
# The alt text: a plotly widget has none of its own.
htmltools::div(
role = "img",
`aria-label` = paste(
"Interactive plot of twelve noisy points and four curves: the",
"true curve, an unpenalized degree-9 polynomial that swings wildly",
"between the points, and two penalized fits that are progressively",
"smoother."
),
widget
)
} else {
# The legend goes below the plot, in a bottom margin made wide enough for it.
op <- par(mar = c(9, 4, 1, 1))
plot(
x_obs, y_obs, pch = 16, col = "#1f77b4", ylim = c(-2, 2),
xlab = "Feature, x", ylab = "Response, y"
)
lines(x_grid, truth(x_grid), col = "#999999", lty = 3)
for (i in seq_along(penalties)) lines(x_grid, curves[[i]], col = colors[i])
legend(
"bottom", c("the true curve", labels, "observations"), ncol = 2, cex = 0.7,
col = c("#999999", colors, "#1f77b4"), lty = c(3, 1, 1, 1, NA),
pch = c(NA, NA, NA, NA, 16), bty = "n", inset = c(0, -0.62), xpd = TRUE
)
par(op)
}Read
GeeksforGeeks explains regularization [29].
Exercise 39 (Read the response to a change, name the term)
Exercise 39 (Read the response to a change, name the term) Each of the following describes what happened when you changed one thing about a model and scored it honestly again. For each, say which term of Equation 26 the response points at, and what you would try next.
Strengthening the regularization penalty raises training error a little and lowers held-out error.
Solution 39. Variance. A stronger penalty limits how closely the fitted model can adapt to the peculiarities of one training set, so it shrinks \(\Expfc{\trainset}{\sqf{\predval - \Epredvalf{\predvar}}}\) at the cost of a little bias. Held-out error fell, so the variance removed outweighed the bias added. Keep raising the penalty while held-out error keeps falling, and stop where it starts to rise.
Exercise 40 (Read the response to a change, name the term (part 2))
Exercise 40 (Read the response to a change, name the term (part 2)) Use the setup of Exercise 39.
Doubling the training set does not change held-out error, but switching to a more flexible model family lowers training and held-out error together.
Solution 40. Bias. More data cuts variance, because each fit then depends less on the peculiarities of one training set, but it does not move the average fit \(\avgfit\) toward the truth. A held-out error that does not move with twice the data is therefore not mainly coming from variance. A more flexible family can place \(\avgfit\) closer to the truth, so both errors fell when you switched. Keep adding flexibility, or better features, while held-out error keeps falling.
Exercise 41 (Read the response to a change, name the term (part 3))
Exercise 41 (Read the response to a change, name the term (part 3)) Use the setup of Exercise 39.
Training error and held-out error are both small and roughly equal, and collecting ten times as much data changes neither.
Solution 41. Residual variance, most likely. Both errors agree, so variance is small; both are small, so bias is small; and more data moving neither says the remaining error is not a property of the model at all. There is nothing left to try on the modelling side. The remaining options are outside the model: measure the inputs more precisely, or find a feature that carries information the current ones do not.
Exercise 42 (A perfect algorithm)
Exercise 42 (A perfect algorithm) Suppose an algorithm has zero bias and zero variance at every \(x\), so every training set gives it the same fit, and that fit is \(f\). Can the risk of its fitted model still be nonzero? Use Equation 26 to say why or why not, and say what each of the two zeros means in words.
Solution 42. Yes: the expected squared error at \(x\) is then \(\varpar\), because the other two terms of Equation 26 are zero. The risk is nonzero whenever the noise is.
Zero variance means the algorithm returns the same fitted model on every training set, so it ignores its data. Zero bias means that model is the truth, \(\Epredvalf{x} = \truemeanf{x}\). Both zeros together describe an algorithm with nothing left to learn, and even that algorithm cannot predict \(Y\) more closely than the noise allows.
Remark 25 (Bias and variance for a classifier)
Remark 25 (Bias and variance for a classifier). The decomposition of Theorem 8 is for squared error, and it does not carry over to a classifier’s zero-one loss as an exact sum. For a classifier the words are an analogy. The Bayes error plays the part of the residual variance: no classifier using the same features does better. Under zero-one loss, bias and variance combine multiplicatively rather than additively [30, Sec. 6]. A classifier’s error at \(x\) depends on the bias only through the boundary bias, which records how far the average fit lies from the decision threshold and on which side. A fit that is very biased but on the correct side of the threshold is not penalized for that bias. In that case, reducing variance alone moves the error toward the Bayes error. Friedman puts it as “variance tends to dominate bias for classification” [30, Sec. 7], p. 63. He also shows the opposite case: where the average fit is on the wrong side of the threshold, reducing variance makes the error worse [30, Sec. 7], p. 62.
bvDesign = d3.range(bvN).map((i) => biXlo + (biXhi - biXlo) * i / (bvN - 1))
bvSets = d3.range(200).map((s) => {
const noise = d3.randomNormal.source(d3.randomLcg(5100 + 1000 * bvDraw + s))(0, biSigma);
return bvDesign.map((x) => [x, biTruth(x) + noise()]);
})
// Fixed decimals with thousands separators, never scientific notation.
bvFmt = (v) => v.toLocaleString("en-US", {minimumFractionDigits: 4, maximumFractionDigits: 4})
bvXs = d3.range(biXlo, biXhi + 1e-9, (biXhi - biXlo) / 60)
// For each degree: every set's fit on the grid, the average fit,
// and the squared bias and the variance averaged over the grid.
bvByDegree = d3.range(0, 10).map((degree) => {
const fits = bvSets.map((pts) => bvXs.map(biPolyfit(pts, degree)));
const avg = bvXs.map((_, j) => d3.mean(fits, (f) => f[j]));
// The middle 95% of the 200 fits at each x: the band the fits fall in.
const lo = bvXs.map((_, j) => d3.quantile(fits.map((f) => f[j]).sort(d3.ascending), 0.025));
const hi = bvXs.map((_, j) => d3.quantile(fits.map((f) => f[j]).sort(d3.ascending), 0.975));
const bias2 = d3.mean(bvXs, (x, j) => (biTruth(x) - avg[j]) ** 2);
const variance = d3.mean(bvXs, (_, j) => d3.mean(fits, (f) => (f[j] - avg[j]) ** 2));
return {degree, fits, avg, lo, hi, bias2, variance};
})
bvNow = bvByDegree[bvDegree]
bvTerms = bvByDegree.flatMap((d) => [
{degree: d.degree, term: "bias squared", value: d.bias2},
{degree: d.degree, term: "variance", value: d.variance},
{degree: d.degree, term: "noise variance", value: biSigma ** 2},
{degree: d.degree, term: "sum of the three", value: d.bias2 + d.variance + biSigma ** 2}
])In Figure 22, raise the degree and watch the fits spread out; then choose more points per training set and see which term responds.
Plot.plot({
ariaLabel: 'Twenty fitted polynomials of the chosen degree, one per training set, as thin blue curves, ' +
'with a pale blue band holding the middle 95% of all 200 fits at each x, ' +
'the true mean function dashed in black and the average of all 200 fits in orange.',
width: 320, height: 270, grid: true,
x: {domain: [0, 1], label: "x"},
y: {domain: [-1.2, 1.4], label: "y"},
marks: [
Plot.areaY(bvXs, {x: (x) => x, y1: (_, j) => bvNow.lo[j], y2: (_, j) => bvNow.hi[j],
fill: "#1f77b4", fillOpacity: 0.12, clip: true}),
bvNow.fits.slice(0, 20).map((f) =>
Plot.line(bvXs, {x: (x) => x, y: (_, j) => f[j], stroke: "#1f77b4",
strokeOpacity: 0.45, clip: true})),
Plot.line(bvXs, {x: (x) => x, y: biTruth, stroke: "#222", strokeDasharray: "5,4",
strokeWidth: 2}),
Plot.line(bvXs, {x: (x) => x, y: (_, j) => bvNow.avg[j], stroke: "#ff7f0e",
strokeWidth: 2.5, clip: true})
]
})Plot.plot({
ariaLabel: 'Squared bias, variance, noise variance and their sum, ' +
'averaged over x, against polynomial degree from 0 to 9, on a log scale, ' +
'with the chosen degree marked by a vertical line.',
width: 320, height: 270, marginLeft: 60, grid: true,
x: {domain: [0, 9], label: "degree", ticks: d3.range(0, 10)},
y: {type: "log", domain: [1e-5, 1], clamp: true, label: "averaged over x (log scale)",
ticks: biPow10(1e-5, 1), tickFormat: biExp},
color: {domain: ["bias squared", "variance", "noise variance", "sum of the three"],
range: ["#2ca02c", "#1f77b4", "#888", "#222"], legend: true},
marks: [
Plot.ruleX([bvDegree], {stroke: "#888"}),
Plot.line(bvTerms, {x: "degree", y: "value", stroke: "term", strokeWidth: 2}),
Plot.dot(bvTerms, {x: "degree", y: "value", fill: "term", r: 3})
]
})Hastie et al. [2], Chapter 2, covers the same material as this chapter at greater length and with more mathematics. Section 2.9 is the bias-variance trade-off; it is worth reading after Equation 26 rather than before.
James et al. [3], Chapter 2, covers the same material in a less technical way and is the better first read. Section 2.1.1 is the prediction-versus-inference distinction from Section 2, and Section 2.2.2 is the bias-variance decomposition.
Mitchell [31], Chapter 1, is the source of the definition of learning that most courses still quote.
Starmer [32] covers the fundamental concepts of machine learning and cross-validation with pictures and little algebra.
Stanford University [33], Lectures 3–6, are handwritten notes from a Stanford probability and inference course. They cover concentration inequalities (Hoeffding’s inequality in Lecture 3), empirical risk minimization and overfitting (Lecture 5), and uniform convergence with generalization bounds (Lecture 6), for readers who want the mathematics behind Theorem 2 in more detail. The textbook these notes recommend for this material is Shalev-Shwartz and Ben-David [34], Sections 2.1–2.3 and 4.1–4.2, which is free online.
Watch
Andrew Ng’s short lectures for DeepLearning.AI cover the same ideas for neural networks: how to split data into training, validation and test sets [37], how to read underfitting and overfitting as bias and variance [38], and a basic recipe for deciding what to change next [39]. They call the validation set the “dev set”.
Open the block to see every definition and result of this page, with prerequisites at the top. Click a box to jump to it.