rate_true <- 3
kl_div <- function(rate) {
  x <- 0:200
  log_ratio <- dpois(x, rate_true, log = TRUE) - dpois(x, rate, log = TRUE)
  sum(dpois(x, rate_true) * log_ratio)
}
h <- 1e-3
kl_values <- c(
  kl_div(rate_true - h),
  kl_div(rate_true),
  kl_div(rate_true + h)
)
c(
  second_difference = sum(kl_values * c(1, -2, 1)) / h^2,
  expected_information = 1 / rate_true
)
#>    second_difference expected_information
#> 0.333333 0.333333Introduction to Maximum Likelihood Inference
Last modified: 2026-11-07 21:34:29 (PST)
1 Overview of maximum likelihood estimation
1.1 The likelihood function
Definition 1 (Likelihood of a single observation) Let \(X\) be a random variable, with observed value \(x\), and let \(\mathbb{p}_{\Theta}(X = x)\) be a probability model for the distribution of \(X\), with parameter vector \(\Theta\). The likelihood of the parameter value \(\theta\), for model \(\mathbb{p}_{\Theta}(X = x)\) and data \(X = x\), is the probability of the event \(X = x\) when \(\Theta= \theta\):
\[\mathcal{L}(\theta) \stackrel{\text{def}}{=}\mathbb{p}_{\theta}(X = x)\]
For a continuous random variable, the likelihood is the probability density of \(X\) at \(x\) instead.
Example 1 (Likelihood of one Bernoulli observation) If \(X\) is a Bernoulli variable, \(X \sim \operatorname{Ber}(\pi)\), then
\[ \mathbb{p}_{\pi}(X = x) = \pi^x (1 - \pi)^{1 - x} \]
for \(x \in \mathopen{}\left\{0, 1\right\}\mathclose{}\). If we observe \(x = 1\), the likelihood is \(\mathcal{L}(\pi) = \pi\): for example, \(\mathcal{L}(0.2) = 0.2\) and \(\mathcal{L}(0.7) = 0.7\), so the observation \(x = 1\) is more likely under \(\pi= 0.7\) than under \(\pi= 0.2\).
Definition 2 (Likelihood of a dataset) Let \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\stackrel{\text{def}}{=}x_1, \ldots, x_n\) be a dataset with corresponding random vector \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\), and let \(\mathbb{p}_{\Theta}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}= \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\) be a probability model for the distribution of \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\), with unknown parameter vector \(\Theta\). The likelihood of the parameter value \(\theta\), for model \(\mathbb{p}_{\Theta}\) and data \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}= \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\), is the joint probability (or joint density) of \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}= \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\) when \(\Theta= \theta\):
\[ \begin{aligned} \mathcal{L}(\theta) &\stackrel{\text{def}}{=}\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}= \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \Theta= \theta) && \text{(definition of the likelihood)}\\ &= \mathbb{p}(X_1 = x_1, \ldots, X_n = x_n \mid \Theta= \theta) && \text{(write $\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}= \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}$ componentwise)} \end{aligned} \]
Source: Wikipedia contributors [4].
Notation for the likelihood function
These notes mostly write \(\mathcal{L}(\theta)\), leaving the data implicit. The notation choices page explains why, and lists the other ways sources write the likelihood function.
Exercise 1 (Likelihood of an independent sample) For mutually independent data \(X_1, \ldots, X_n\), write the likelihood \(\mathcal{L}(\theta)\) in terms of the distributions of the individual \(X_i\).
Solution 1. \[ \begin{aligned} \mathcal{L}(\theta) &\stackrel{\text{def}}{=}\mathbb{p}(X_1 = x_1, \ldots, X_n = x_n \mid \theta) && \text{(definition of likelihood)}\\ &= \prod_{i=1}^n\mathbb{p}(X_i= x_i\mid \theta) && \text{(definition of mutual independence)} \end{aligned} \]
Theorem 1 (Likelihood of an independent sample) For mutually independent data \(X_1, \ldots, X_n\):
\[\mathcal{L}(\theta) = \prod_{i=1}^n\mathbb{p}(X_i= x_i\mid \theta) \tag{1}\]
Proof. This is the solution to Exercise 1.
Definition 3 (Likelihood component (likelihood factor)) For a dataset \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\) of mutually independent observations, the likelihood component (or likelihood factor) of observation \(X_i= x_i\) is the likelihood of that observation alone:
\[\mathcal{L}_i(\theta) \stackrel{\text{def}}{=}\mathbb{p}(X_i= x_i\mid \theta)\]
Exercise 2 (Dataset likelihood from likelihood components) For mutually independent data \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\stackrel{\text{def}}{=}x_1, \ldots, x_n\), use Theorem 1 to write the likelihood of the dataset in terms of the observations’ likelihood components.
Solution 2. \[ \begin{aligned} \mathcal{L}(\theta) &= \prod_{i=1}^n\mathbb{p}(X_i= x_i\mid \theta) && \text{(likelihood of an independent sample)}\\ &= \prod_{i=1}^n\mathcal{L}_i(\theta) && \text{(definition of likelihood components)} \end{aligned} \]
Theorem 2 (Dataset likelihood as a product of observation likelihoods) For mutually independent data \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\stackrel{\text{def}}{=}x_1, \ldots, x_n\), the likelihood of the dataset is the product of the observations’ likelihood components:
\[\mathcal{L}(\theta) = \prod_{i=1}^n\mathcal{L}_i(\theta)\]
Proof. This is the solution to Exercise 2.
1.2 The maximum likelihood estimate
Definition 4 (Maximum likelihood estimate) The maximum likelihood estimate (MLE) of a parameter vector \(\Theta\), written \(\hat\theta_{\text{ML}}\), is the value of \(\Theta\) that maximizes the likelihood:
\[\hat\theta_{\text{ML}}\stackrel{\text{def}}{=}\arg \max_\Theta\mathcal{L}(\Theta) \tag{2}\]
Source: Wikipedia contributors [5].
Example 2 (MLE for one Bernoulli observation) In Example 1, the likelihood of the observation \(x = 1\) is \(\mathcal{L}(\pi) = \pi\) for \(\pi\in [0, 1]\). This function is increasing, so it is maximized at the upper edge of the parameter space: \(\hat{\pi}_{\text{ML}} = 1\).
5MinuteAI explains maximum likelihood estimation and works examples in five minutes each, following the University of Washington’s CSE 312 [6].
- Hogg et al. [7, Sec. 6.4], pp. 264–276 covers maximum likelihood and method of moments estimation.
- Casella and Berger [3, Sec. 7.2.2], pp. 315–323 covers maximum likelihood estimators.
- Rice [8, Sec. 8.5], pp. 267–284 covers the method of maximum likelihood.
1.3 Finding the maximum of a function
Definition 5 (Critical point) A critical point of a differentiable function \(f\) is an input value \(x_0\) where the derivative of \(f\) is zero, or, for a function of a vector, a point \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}_0\) where the gradient \(f'\) of \(f\) is the zero vector:
\[ \begin{aligned} f'(x_0) &= 0 && \text{(scalar input)}\\ f'(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}_0) &= \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{0}}\vphantom{0}}&& \text{(vector input)} \end{aligned} \]
Source: Wikipedia contributors [9].
From calculus: if \(f(x)\) is differentiable, its maximum over an interval of input values can occur only at an endpoint of the interval or at a critical point. At a critical point \(x_0\), \(f''(x_0) < 0\) is sufficient for \(x_0\) to be a local maximum, but not necessary: \(f(x) = -x^4\) has a maximum at \(x_0 = 0\), where \(f''(0) = 0\). For a function of a vector, a negative definite Hessian matrix at a critical point is sufficient for a local maximum.
1.4 Directly maximizing the likelihood function for independent data
To find the maximizer of the likelihood function, we solve \(\mathcal{L}'(\theta) = 0\) for \(\theta\). For mutually independent data, Equation 1 gives:
\[ \begin{aligned} \mathcal{L}'(\theta) &= \frac{\partial}{\partial \theta} \mathcal{L}(\theta) && \text{(notation for the derivative)}\\ &= \frac{\partial}{\partial \theta} \prod_{i=1}^n\mathbb{p}(X_i= x_i\mid \theta) && \text{(likelihood of mutually independent data)} \end{aligned} \tag{3}\]
Equation 3 is the derivative of a product of \(n\) factors, which takes \(n - 1\) applications of the product rule and produces \(n\) terms. The log-likelihood avoids this work.
1.5 The log-likelihood function
Definition 6 (Log-likelihood) The log-likelihood of parameter value \(\theta\), for model \(\mathbb{p}_{\Theta}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}})\) and data \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}= \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\), is the natural logarithm of the likelihood:
\[\ell\stackrel{\text{def}}{=}{\operatorname{log}\mathopen{}\left\{\mathcal{L}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}|\theta)\right\}\mathclose{}} \tag{4}\]
Example 3 (Log-likelihood of one Bernoulli observation) In Example 1, \(\mathcal{L}(\pi) = \pi\), so \(\ell(\pi) = \log \pi\); for example, \(\ell(0.7) = \log 0.7 \approx -0.357\).
Exercise 3 (Comparing likelihoods through log-likelihoods) Suppose \(\mathcal{L}(\theta) > 0\) for every \(\theta\). Determine how the parameter values that maximize the likelihood \(\mathcal{L}\) relate to the parameter values that maximize the log-likelihood \(\ell\).
Solution 3. Let \(\theta^*\) be a parameter value. The natural logarithm is strictly increasing on \((0, \infty)\), so for any \(\theta_1\) and \(\theta_2\), \(\mathcal{L}(\theta_1) \ge \mathcal{L}(\theta_2)\) if and only if \(\log \mathcal{L}(\theta_1) \ge \log \mathcal{L}(\theta_2)\), that is, \(\ell(\theta_1) \ge \ell(\theta_2)\). So \(\theta^*\) satisfies \(\mathcal{L}(\theta^*) \ge \mathcal{L}(\theta)\) for every \(\theta\) if and only if it satisfies \(\ell(\theta^*) \ge \ell(\theta)\) for every \(\theta\). So a parameter value \(\theta^*\) maximizes \(\mathcal{L}\) if and only if it maximizes \(\ell\).
Theorem 3 (Maximize the log-likelihood instead of the likelihood) If \(\mathcal{L}(\theta) > 0\) for every \(\theta\), the likelihood and log-likelihood have the same maximizers:
\[ \arg \max_\theta\mathcal{L}(\theta) = \arg \max_\theta\ell(\theta) \]
Proof. This is the solution to Exercise 3.
Exercise 4 (Log-likelihood of an independent sample) For mutually independent data \(X_1, \ldots, X_n\), use Theorem 1 to write the log-likelihood \(\ell(\theta)\) as a sum over the observations. What does each term become if the \(X_i\) also share a common distribution \(\mathbb{p}(X = x \mid \theta)\)?
Solution 4. \[ \begin{aligned} \ell(\theta) &\stackrel{\text{def}}{=}\log{\mathcal{L}(\theta)} && \text{(definition of log-likelihood)}\\ &= \log{\prod_{i=1}^n\mathbb{p}(X_i= x_i\mid \theta)} && \text{(likelihood of an independent sample)}\\ &= \sum_{i=1}^n\log{\mathbb{p}(X_i= x_i\mid \theta)} && \text{(log of a product is a sum of logs)} \end{aligned} \]
With a common distribution,
\[ \mathbb{p}(X_i= x_i\mid \theta) = \mathbb{p}(X = x_i\mid \theta), \]
so each term is \(\log{\mathbb{p}(X = x_i\mid \theta)}\).
Theorem 4 (Log-likelihood of an independent sample) For mutually independent data \(X_1, \ldots, X_n\):
\[\ell(\theta) = \sum_{i=1}^n\log{\mathbb{p}(X_i= x_i\mid \theta)} \tag{5}\]
If the \(X_i\) also share a common distribution \(\mathbb{p}(X = x \mid \theta)\), each term is \(\log{\mathbb{p}(X = x_i\mid \theta)}\).
Proof. This is the solution to Exercise 4.
Exercise 5 (Derivative of the log-likelihood for \(\operatorname{iid}\) data) For \(\operatorname{iid}\) data, use Theorem 4 to write the derivative \(\ell'(\theta)\) of the log-likelihood as a sum over the observations.
Solution 5. \[ \begin{aligned} \ell'(\theta) &= \frac{\partial}{\partial \theta} \ell(\theta) && \text{(notation for the derivative)}\\ &= \frac{\partial}{\partial \theta} \sum_{i=1}^n\log{\mathbb{p}(X = x_i\mid \theta)} && \text{(log-likelihood of an $\operatorname{iid}$ sample)}\\ &= \sum_{i=1}^n\frac{\partial}{\partial \theta} \log{\mathbb{p}(X = x_i\mid \theta)} && \text{(derivative of a sum is the sum of derivatives)} \end{aligned} \]
Unlike Equation 3, each term involves only one observation, so no product rule is needed.
Theorem 5 (Derivative of the log-likelihood function for \(\operatorname{iid}\) data) For \(\operatorname{iid}\) data:
\[\ell'(\theta) = \sum_{i=1}^n\frac{\partial}{\partial \theta} \log{\mathbb{p}(X = x_i\mid \theta)} \tag{6}\]
Proof. This is the solution to Exercise 5.
1.6 The score function
Definition 7 (Score function) The score function of a statistical model \(\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}= \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\) is the gradient (vector of first derivatives) of the model’s log-likelihood with respect to the parameters:
\[\ell'\stackrel{\text{def}}{=}\frac{\partial}{\partial \theta} \ell(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}|\theta) \tag{7}\]
Source: Wikipedia contributors [10].
Remark 1 (Notation for the score function). We often omit the arguments \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\) and \(\theta\), writing \(\ell'\stackrel{\text{def}}{=}\ell'(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \stackrel{\text{def}}{=}\ell'(\theta)\). Some sources write \(U\) or \(S\) for the score function instead of \(\ell'\); for example, Dobson and Barnett [1] write \(U\). The notation choices page explains why these notes use \(\ell'\).
Remark 2 (Why the score function is called “score”). Statisticians call the score function by that name because of its origin in genetics. Fisher [11] gave each family in a study of linkage a “score”, which summarized what the family showed about the linkage parameter. He compared that scoring rule with an “ideal score”, the derivative of the log of the probability of the data as the linkage parameter varies, which is the score function of these notes [10]. For independent observations, the log-likelihood is a sum with one contribution from each of them, so its derivative is also a sum. Rao [12], who had worked on estimating linkage parameters in Fisher’s genetics laboratory, based a test on the score function, with one score for each parameter, and called it a score test [13]. The name then spread to the derivative itself.
In other settings, “score” refers to a different quantity. These notes call a classifier’s raw output the log-odds, never a “score”, so that “score” always refers to the derivative of the log-likelihood.
Exercise 6 (Score function of a Poisson variable) Derive the score function for a single Poisson random variable \(X\), with respect to its mean parameter \({\lambda}\).
Solution 6. The log-likelihood of one Poisson observation is \(\ell= x {\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}} - {\lambda}- {\operatorname{log}\mathopen{}\left\{x!\right\}\mathclose{}}\), so:
\[ \begin{aligned} \ell' &\stackrel{\text{def}}{=}\frac{\partial}{\partial {\lambda}}\ell && \text{(definition of the score)}\\ &= \frac{\partial}{\partial {\lambda}}\mathopen{}\left(x{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}} - {\lambda}- {\operatorname{log}\mathopen{}\left\{x!\right\}\mathclose{}}\right)\mathclose{} && \text{(Poisson log-likelihood)}\\ &= \frac{\partial}{\partial {\lambda}}\mathopen{}\left(x{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}}\right)\mathclose{} - \frac{\partial}{\partial {\lambda}}{\lambda}- \frac{\partial}{\partial {\lambda}}{\operatorname{log}\mathopen{}\left\{x!\right\}\mathclose{}} && \text{(linearity of differentiation)}\\ &= \frac{\partial}{\partial {\lambda}}\mathopen{}\left(x{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}}\right)\mathclose{} - \frac{\partial}{\partial {\lambda}}{\lambda}- 0 && \text{(derivative of a constant)}\\ &= \frac{\partial}{\partial {\lambda}}\mathopen{}\left(x{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}}\right)\mathclose{} - \frac{\partial}{\partial {\lambda}}{\lambda} && \text{(drop the zero term)}\\ &= x\frac{\partial}{\partial {\lambda}}{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}} - \frac{\partial}{\partial {\lambda}}{\lambda} && \text{(constant multiple rule)}\\ &= x{\lambda}^{-1} - \frac{\partial}{\partial {\lambda}}{\lambda} && \text{(derivative of $\log {\lambda}$)}\\ &= x{\lambda}^{-1} - 1 && \text{(derivative of ${\lambda}$ with respect to itself)}\\ &= \frac{x}{{\lambda}} - 1 && \text{(write the negative power as a fraction)}\\ &= \frac{x}{{\lambda}} - \frac{{\lambda}}{{\lambda}} && \text{(write both terms over the common denominator)}\\ &= \frac{x - {\lambda}}{{\lambda}} && \text{(combine the fractions)}\\ &= \frac{x - {\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}}{{\lambda}} && \text{(${\mathbb{E}\mathopen{}\left[X\right]\mathclose{}} = {\lambda}$)}\\ &= \frac{x - {\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}}{{\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}} && \text{(${\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}} = {\lambda}$)} \end{aligned} \]
Theorem 6 (Score function of a Poisson variable) Let \(X \sim \operatorname{Pois}({\lambda})\), with mean \({\lambda}\) and observed count \(x\). The score \(\ell'\) of the single observation \(x\) is the derivative of its log-likelihood \(\ell\) with respect to \({\lambda}\). It equals the deviation of \(x\) from the mean \({\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}\), divided by the variance \({\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}\):
\[\ell'= \frac{x - {\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}}{{\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}} = \frac{x - {\lambda}}{{\lambda}}\]
Proof. This is the solution to Exercise 6, worked in Solution 6.
Exercise 7 (Score function of a Gaussian variable) Derive the score function for a single Gaussian random variable \(X\), with respect to the mean parameter \(\mu\), treating the variance \(\sigma^2\) as known.
Solution 7. \[ \begin{aligned} \ell' &\stackrel{\text{def}}{=}\frac{\partial}{\partial \mu}\ell && \text{(definition of the score)}\\ &= \frac{\partial}{\partial \mu}\mathopen{}\left(\frac{-1}{2}\mathopen{}\left({\operatorname{log}\mathopen{}\left\{2\pi\sigma^2\right\}\mathclose{}} + \frac{(x - \mu)^2}{\sigma^2}\right)\mathclose{}\right)\mathclose{} && \text{(Gaussian log-likelihood)}\\ &= \frac{-1}{2}\frac{\partial}{\partial \mu}\mathopen{}\left({\operatorname{log}\mathopen{}\left\{2\pi\sigma^2\right\}\mathclose{}} + \frac{(x - \mu)^2}{\sigma^2}\right)\mathclose{} && \text{(constant multiple rule)}\\ &= \frac{-1}{2}\mathopen{}\left(\frac{\partial}{\partial \mu}{\operatorname{log}\mathopen{}\left\{2\pi\sigma^2\right\}\mathclose{}} + \frac{\partial}{\partial \mu}\frac{(x - \mu)^2}{\sigma^2}\right)\mathclose{} && \text{(linearity of differentiation)}\\ &= \frac{-1}{2}\mathopen{}\left(0 + \frac{\partial}{\partial \mu}\frac{(x - \mu)^2}{\sigma^2}\right)\mathclose{} && \text{(derivative of a constant)}\\ &= \frac{-1}{2}\mathopen{}\left(0 + \frac{1}{\sigma^2}\frac{\partial}{\partial \mu}(x - \mu)^2\right)\mathclose{} && \text{(constant multiple rule)}\\ &= \frac{-1}{2}\mathopen{}\left(0 + \frac{1}{\sigma^2} \cdot 2(x - \mu) \frac{\partial}{\partial \mu}(x - \mu)\right)\mathclose{} && \text{(chain rule, outer function $u^2$)} \end{aligned} \]
The inner derivative is:
\[ \begin{aligned} \frac{\partial}{\partial \mu}(x - \mu) &= \frac{\partial}{\partial \mu} x - \frac{\partial}{\partial \mu} \mu && \text{(linearity of differentiation)}\\ &= 0 - \frac{\partial}{\partial \mu} \mu && \text{($x$ does not depend on $\mu$)}\\ &= 0 - 1 && \text{(derivative of $\mu$ with respect to itself)}\\ &= -1 && \text{(subtract)} \end{aligned} \]
Substituting the inner derivative back in:
\[ \begin{aligned} \ell' &= \frac{-1}{2}\mathopen{}\left(0 + \frac{1}{\sigma^2} \cdot 2(x - \mu) \cdot (-1)\right)\mathclose{} && \text{(inner derivative is $-1$)}\\ &= \frac{-1}{2}\mathopen{}\left(0 + \frac{-2(x - \mu)}{\sigma^2}\right)\mathclose{} && \text{(multiply)}\\ &= \frac{-1}{2} \cdot \frac{-2(x - \mu)}{\sigma^2} && \text{(drop the zero term)}\\ &= \frac{x - \mu}{\sigma^2} && \text{(multiply)}\\ &= \frac{x - {\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}}{\sigma^2} && \text{(${\mathbb{E}\mathopen{}\left[X\right]\mathclose{}} = \mu$)}\\ &= \frac{x - {\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}}{{\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}} && \text{(${\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}} = \sigma^2$)} \end{aligned} \]
Theorem 7 (Score function of a Gaussian variable) Let \(X \sim {\operatorname{N}\mathopen{}\left(\mu, \sigma^2\right)\mathclose{}}\), with mean \(\mu\), known variance \(\sigma^2\), and observed value \(x\). The score \(\ell'\) of the single observation \(x\) is the derivative of its log-likelihood \(\ell\) with respect to \(\mu\). It equals the deviation of \(x\) from the mean \({\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}\), divided by the variance \({\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}\):
\[\ell'= \frac{x - {\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}}{{\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}} = \frac{x - \mu}{\sigma^2}\]
Proof. This is the solution to Exercise 7, worked in Solution 7.
Exercise 8 (Score function of an exponential variable) Derive the score function for a single exponential random variable \(X\), with respect to the mean parameter \(\mu\).
Solution 8. The exponential density with mean \(\mu\) is
\[ \mathbb{p}(X = x) = \mu^{-1} e^{-x/\mu} \]
for \(x > 0\), so \(\ell= -{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}} - \frac{x}{\mu}\), and:
\[ \begin{aligned} \ell' &\stackrel{\text{def}}{=}\frac{\partial}{\partial \mu}\ell && \text{(definition of the score)}\\ &= \frac{\partial}{\partial \mu}\mathopen{}\left(-{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}} - \frac{x}{\mu}\right)\mathclose{} && \text{(exponential log-likelihood)}\\ &= \frac{\partial}{\partial \mu}\mathopen{}\left(-{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}} - x \mu^{-1}\right)\mathclose{} && \text{(write $\frac{x}{\mu}$ as $x \mu^{-1}$)}\\ &= \frac{\partial}{\partial \mu}\mathopen{}\left(-{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}}\right)\mathclose{} - \frac{\partial}{\partial \mu}\mathopen{}\left(x \mu^{-1}\right)\mathclose{} && \text{(linearity of differentiation)}\\ &= -\frac{\partial}{\partial \mu}{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}} - x \frac{\partial}{\partial \mu} \mu^{-1} && \text{(constant multiple rule)}\\ &= -\mu^{-1} - x \frac{\partial}{\partial \mu} \mu^{-1} && \text{(derivative of $\log \mu$)}\\ &= -\mu^{-1} - x \mathopen{}\left(-\mu^{-2}\right)\mathclose{} && \text{(power rule)}\\ &= -\mu^{-1} + x \mu^{-2} && \text{(multiply)}\\ &= -\frac{1}{\mu} + \frac{x}{\mu^2} && \text{(write the negative powers as fractions)}\\ &= -\frac{\mu}{\mu^2} + \frac{x}{\mu^2} && \text{(write both terms over the common denominator)}\\ &= \frac{-\mu+ x}{\mu^2} && \text{(combine the fractions)}\\ &= \frac{x - \mu}{\mu^2} && \text{(reorder the numerator)}\\ &= \frac{x - {\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}}{\mu^2} && \text{(${\mathbb{E}\mathopen{}\left[X\right]\mathclose{}} = \mu$)}\\ &= \frac{x - {\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}}{{\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}} && \text{(${\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}} = \mu^2$)} \end{aligned} \]
Theorem 8 (Score function of an exponential variable) Let \(X\) be an exponential random variable with mean \(\mu\) and observed value \(x > 0\). The score \(\ell'\) of the single observation \(x\) is the derivative of its log-likelihood \(\ell\) with respect to \(\mu\). It equals the deviation of \(x\) from the mean \({\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}\), divided by the variance \({\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}\):
\[\ell'= \frac{x - {\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}}{{\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}} = \frac{x - \mu}{\mu^2}\]
Proof. This is the solution to Exercise 8, worked in Solution 8.
Definition 8 (Score equation) The score equation is the equation that sets the score function to zero:
\[ \ell'(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}) = \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{0}}\vphantom{0}} \]
1.7 Information matrices
Definition 9 (Hessian) The Hessian matrix of the log-likelihood function (the Hessian of the log-likelihood as a function of the parameters) is the matrix of its second derivatives with respect to the parameters:
\[ \ell''\stackrel{\text{def}}{=}\frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}}\frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}^{\top}} \ell(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}| \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}) \tag{8}\]
Source: Wikipedia contributors [14].
Exercise 9 (Entries of the Hessian) If \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}\) is a \(p \times 1\) vector, find the dimensions of the Hessian \(\frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}}\frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}^{\top}}\ell\) and an expression for its \(ij\)th entry.
Solution 9. \(\frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}^{\top}}\ell\) is the \(1 \times p\) row vector whose \(j\)th entry is \(\frac{\partial}{\partial \theta_j}\ell\). Differentiating each entry with respect to the \(p \times 1\) vector \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}\) gives a \(p \times 1\) column of derivatives per entry, so \(\frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}}\frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}^{\top}}\ell\) is \(p \times p\), with \(ij\)th entry \(\frac{\partial}{\partial \theta_i}\frac{\partial}{\partial \theta_j}\ell\).
Theorem 9 (Elements of the Hessian matrix) If \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}\) is a \(p \times 1\) vector, then the Hessian is a \(p \times p\) matrix, whose \(ij\)th entry is:
\[ \ell_{ij}''= \frac{\partial}{\partial \theta_i}\frac{\partial}{\partial \theta_j} \ell(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}= \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}| \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}) \tag{9}\]
Proof. This is the solution to Exercise 9.
Exercise 10 (Hessian from the score) Express the Hessian \(\ell''\) as a derivative of the score function \(\ell'\).
Solution 10. By Definition 7, \(\ell'= \frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}}\ell\), so \({\mathopen{}\left(\ell'\right)\mathclose{}}^{\top} = \frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}^{\top}}\ell\). Then:
\[ \begin{aligned} \frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}}{\mathopen{}\left(\ell'\right)\mathclose{}}^{\top} &= \frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}}\frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}^{\top}}\ell && \text{(transpose of the score)}\\ &= \ell'' && \text{(definition of the Hessian)} \end{aligned} \]
Theorem 10 (Hessian is the derivative of the transposed score) \[ \ell''(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}) = \frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}} {\mathopen{}\left(\ell'(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}})\right)\mathclose{}}^{\top} \]
Proof. This is the solution to Exercise 10.
Definition 10 (Expected information matrix (Fisher information matrix, information matrix)) The expected information matrix, also called the Fisher information matrix or just the information matrix, is written \(\mathcal{I}\), and is the expected value of the negative Hessian of the log-likelihood, with the data \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\) treated as random:
\[\mathcal{I}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}) \stackrel{\text{def}}{=}{\mathbb{E}\mathopen{}\left[-\ell''(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\mid \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}})\right]\mathclose{}} \tag{10}\]
Source: Wikipedia contributors [15].
Definition 11 (Observed information matrix) The observed information matrix, written \(I\), is the negative of the Hessian of the log-likelihood, evaluated at the observed data:
\[I\stackrel{\text{def}}{=}-\ell''(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}|\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}) \tag{11}\]
Remark 3 (The expected information is a function of the parameter alone). The expected information is a function of the parameter alone, so it is the quantity that the observed information estimates from one data set.
Remark 4 (The observed information is the sample counterpart of the expected information). The observed information matrix is the sample counterpart of the expected information, which averages the same quantity over possible data sets.
Example 4 (Information for Poisson data) For \(X_1, \ldots, X_n \ \sim_{\operatorname{iid}}\ \operatorname{Pois}({\lambda})\), one observation’s score is \(x/{\lambda}- 1\) (Theorem 6), whose derivative with respect to \({\lambda}\) is \(-x/{\lambda}^2\). Summing over the observations (Theorem 5), the Hessian is \(\ell''= -\sum_{i=1}^nx_i/ {\lambda}^2\), so:
\[ \begin{aligned} I({\lambda}) &= -\ell'' && \text{(observed information: negative Hessian)}\\ &= -\mathopen{}\left(-\frac{\sum_{i=1}^nx_i}{{\lambda}^2}\right)\mathclose{} && \text{(substitute the Hessian)}\\ &= \frac{\sum_{i=1}^nx_i}{{\lambda}^2} && \text{(two negatives make a positive)}\\ \mathcal{I}({\lambda}) &= {\mathbb{E}\mathopen{}\left[\frac{\sum_{i=1}^nX_i}{{\lambda}^2}\right]\mathclose{}} && \text{(expected information)}\\ &= \frac{{\mathbb{E}\mathopen{}\left[\sum_{i=1}^nX_i\right]\mathclose{}}}{{\lambda}^2} && \text{(factor the constant $\tfrac{1}{{\lambda}^2}$ out of the expectation)}\\ &= \frac{\sum_{i=1}^n{\mathbb{E}\mathopen{}\left[X_i\right]\mathclose{}}}{{\lambda}^2} && \text{(linearity of expectation)}\\ &= \frac{\sum_{i=1}^n{\lambda}}{{\lambda}^2} && \text{(${\mathbb{E}\mathopen{}\left[X_i\right]\mathclose{}} = {\lambda}$)}\\ &= \frac{n{\lambda}}{{\lambda}^2} && \text{(sum of $n$ copies of ${\lambda}$)}\\ &= \frac{n}{{\lambda}} && \text{(cancel one factor of ${\lambda}$)} \end{aligned} \]
Exercise 11 (Derivative of a density through its logarithm) Let \(\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\) be a density that is positive and differentiable in a scalar parameter \(\theta\). Express \(\frac{\partial}{\partial \theta}\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\) in terms of \(\frac{\partial}{\partial \theta}\log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\).
Solution 11. By the chain rule, with outer function \(\log u\) and inner function \(u = \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\):
\[ \frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) = \left.{\mathopen{}\left(\frac{d}{du} \log u\right)\mathclose{}}\right|_{u = \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)} \frac{\partial}{\partial \theta}\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta). \]
The inner derivative \(\frac{\partial}{\partial \theta}\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\) is the quantity we want, so only the outer derivative needs working out:
\[ \begin{aligned} \frac{d}{du} \log u &= \frac{1}{u} && \text{(derivative of the natural logarithm)} \end{aligned} \]
Plugging the outer derivative back in:
\[ \begin{aligned} \frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) &= \frac{1}{\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)} \frac{\partial}{\partial \theta}\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) && \text{(outer derivative is $1/u$)}\\ \frac{\partial}{\partial \theta}\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) &= \mathopen{}\left(\frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{} \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) && \text{(multiply both sides by $\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) > 0$)} \end{aligned} \]
Lemma 1 (Derivative of a density through its logarithm) Let \(\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\) be a density that is positive and differentiable in a scalar parameter \(\theta\). Then its derivative with respect to \(\theta\) is the derivative of its logarithm times the density:
\[\frac{\partial}{\partial \theta}\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) = \mathopen{}\left(\frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{} \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\]
Proof. This is the solution to Exercise 11, worked in Solution 11.
Exercise 12 (Mean of the score) Let \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\) be continuous with density \(\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\) for a scalar parameter \(\theta\). Suppose the set of possible data values does not depend on \(\theta\), and the order of differentiation with respect to \(\theta\) and integration over the data can be exchanged. Find the mean of the score.
Solution 12. The step that rewrites the derivative of \(\log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\) uses Lemma 1:
\[ \begin{aligned} {\mathbb{E}\mathopen{}\left[\ell'\right]\mathclose{}} &= \int \ell'\, \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} && \text{(definition of expectation)}\\ &= \int \mathopen{}\left(\frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{} \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} && \text{(definition of the score)}\\ &= \int \frac{\frac{\partial}{\partial \theta} \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)}{\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)} \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} && \text{(chain rule for $\log$)}\\ &= \int \frac{\partial}{\partial \theta} \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} && \text{(cancel $\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)$)}\\ &= \frac{\partial}{\partial \theta} \int \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} && \text{(exchange derivative and integral)}\\ &= \frac{\partial}{\partial \theta} 1 && \text{(a density integrates to 1)}\\ &= 0 && \text{(derivative of a constant)} \end{aligned} \]
Theorem 11 (Mean of the score) Let \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\) be a continuous random vector with density \(\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\) for a scalar parameter \(\theta\). Suppose the set of possible data values does not depend on \(\theta\), and the order of differentiation with respect to \(\theta\) and integration over the data can be exchanged. Then the score \(\ell'\), the derivative of the log-likelihood with respect to \(\theta\), has expectation zero:
\[{\mathbb{E}\mathopen{}\left[\ell'\right]\mathclose{}} = 0\]
Proof. This is the solution to Exercise 12, worked in Solution 12. It builds on Lemma 1.
Exercise 13 (Second moment of the score) Under the assumptions of Exercise 12, show that \({\mathbb{E}\mathopen{}\left[\ell'^2\right]\mathclose{}} = \mathcal{I}(\theta)\), the expected information.
Solution 13. By Theorem 11, \(0 = \int \mathopen{}\left(\frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{} \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\) for every \(\theta\). Differentiate this identity with respect to \(\theta\); the step that substitutes for \(\frac{\partial}{\partial \theta}\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\) uses Lemma 1:
\[ \begin{aligned} \frac{\partial}{\partial \theta} 0 &= \frac{\partial}{\partial \theta} \int \mathopen{}\left(\frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{} \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} && \text{(differentiate both sides)}\\ 0 &= \frac{\partial}{\partial \theta} \int \mathopen{}\left(\frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{} \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} && \text{(derivative of a constant)}\\ &= \int \frac{\partial}{\partial \theta}\mathopen{}\left[\mathopen{}\left(\frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{} \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right]\mathclose{} d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} && \text{(exchange derivative and integral)}\\ &= \int \mathopen{}\left(\frac{\partial^2}{\partial \theta^2} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{} \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} + \int \mathopen{}\left(\frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{} \frac{\partial}{\partial \theta}\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} && \text{(product rule)}\\ &= \int \mathopen{}\left(\frac{\partial^2}{\partial \theta^2} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{} \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} + \int \mathopen{}\left(\frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{} \mathopen{}\left(\frac{\partial}{\partial \theta}\log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{} \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} && \text{($\frac{\partial}{\partial \theta}\mathbb{p}= \mathopen{}\left(\frac{\partial}{\partial \theta}\log \mathbb{p}\right)\mathclose{} \mathbb{p}$)}\\ &= \int \mathopen{}\left(\frac{\partial^2}{\partial \theta^2} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{} \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} + \int \mathopen{}\left(\frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{}^2 \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} && \text{(product of two equal factors is a square)}\\ &= {\mathbb{E}\mathopen{}\left[\frac{\partial^2}{\partial \theta^2} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\mid \theta)\right]\mathclose{}} + \int \mathopen{}\left(\frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{}^2 \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} && \text{(definition of expectation)}\\ &= {\mathbb{E}\mathopen{}\left[\ell''\right]\mathclose{}} + \int \mathopen{}\left(\frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\right)\mathclose{}^2 \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta) \, d\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} && \text{(definition of the Hessian)}\\ &= {\mathbb{E}\mathopen{}\left[\ell''\right]\mathclose{}} + {\mathbb{E}\mathopen{}\left[\mathopen{}\left(\frac{\partial}{\partial \theta} \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\mid \theta)\right)\mathclose{}^2\right]\mathclose{}} && \text{(definition of expectation)}\\ &= {\mathbb{E}\mathopen{}\left[\ell''\right]\mathclose{}} + {\mathbb{E}\mathopen{}\left[\ell'^2\right]\mathclose{}} && \text{(definition of the score)} \end{aligned} \]
Rearranging:
\[ \begin{aligned} {\mathbb{E}\mathopen{}\left[\ell'^2\right]\mathclose{}} &= -{\mathbb{E}\mathopen{}\left[\ell''\right]\mathclose{}} && \text{(subtract ${\mathbb{E}\mathopen{}\left[\ell''\right]\mathclose{}}$ from both sides)}\\ &= {\mathbb{E}\mathopen{}\left[-\ell''\right]\mathclose{}} && \text{(move the constant factor $-1$ into the expectation)}\\ &= {\mathbb{E}\mathopen{}\left[I\right]\mathclose{}} && \text{(observed information is the negative Hessian)}\\ &= \mathcal{I}(\theta) && \text{(definition of expected information)} \end{aligned} \]
Theorem 12 (Second moment of the score) Under the assumptions of Theorem 11, the second moment \({\mathbb{E}\mathopen{}\left[\ell'^2\right]\mathclose{}}\) of the score \(\ell'\) is the expected information \(\mathcal{I}(\theta)\), the expected negative second derivative of the log-likelihood:
\[{\mathbb{E}\mathopen{}\left[\ell'^2\right]\mathclose{}} = \mathcal{I}(\theta)\]
Proof. This is the solution to Exercise 13, worked in Solution 13. It builds on Theorem 11 and Lemma 1.
Theorem 13 (Mean and variance of the score) Suppose the set of possible data values does not depend on \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}\), and the order of differentiation with respect to \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}\) and integration over the data can be exchanged. Then the score has mean zero, and its variance is the expected information:
\[{\mathbb{E}\mathopen{}\left[\ell'(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\mid \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}})\right]\mathclose{}} = \mathbf{0}_{p \times 1} \tag{12}\]
\[ \begin{aligned} \mathcal{I}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}) &= {\operatorname{Cov}\mathopen{}\left(\ell'(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\mid \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}})\right)\mathclose{}}\\ &= {\mathbb{E}\mathopen{}\left[\ell'{\ell'}^{\top}\right]\mathclose{}} \end{aligned} \tag{13}\]
Proof. We give the proof for a scalar \(\theta\) and a continuous \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\) with density \(\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\); the vector case applies the same steps to each pair of entries, and a discrete \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\) replaces integrals with sums.
Equation 12 follows from Theorem 11. For Equation 13, Theorem 12 gives \(\mathcal{I}(\theta) = {\mathbb{E}\mathopen{}\left[\ell'^2\right]\mathclose{}}\), and because \({\mathbb{E}\mathopen{}\left[\ell'\right]\mathclose{}} = 0\),
\[ \begin{aligned} {\mathbb{E}\mathopen{}\left[\ell'^2\right]\mathclose{}} &= {\mathbb{E}\mathopen{}\left[\ell'^2\right]\mathclose{}} - {\mathopen{}\left({\mathbb{E}\mathopen{}\left[\ell'\right]\mathclose{}}\right)\mathclose{}}^{2} \\ &= {\operatorname{Var}\mathopen{}\left(\ell'\right)\mathclose{}}. \end{aligned} \]
Example 5 (Checking the information equality for Poisson data) For \(X_1, \ldots, X_n \ \sim_{\operatorname{iid}}\ \operatorname{Pois}({\lambda})\), the score is \(\ell'= \sum_{i=1}^nX_i/{\lambda}- n\) (Example 4). Then:
\[ \begin{aligned} {\mathbb{E}\mathopen{}\left[\ell'\right]\mathclose{}} &= {\mathbb{E}\mathopen{}\left[\frac{\sum_{i=1}^nX_i}{{\lambda}} - n\right]\mathclose{}} && \text{(Poisson score)}\\ &= {\mathbb{E}\mathopen{}\left[\frac{\sum_{i=1}^nX_i}{{\lambda}}\right]\mathclose{}} - {\mathbb{E}\mathopen{}\left[n\right]\mathclose{}} && \text{(linearity of expectation)}\\ &= {\mathbb{E}\mathopen{}\left[\frac{\sum_{i=1}^nX_i}{{\lambda}}\right]\mathclose{}} - n && \text{(the expectation of a constant is that constant)}\\ &= \frac{{\mathbb{E}\mathopen{}\left[\sum_{i=1}^nX_i\right]\mathclose{}}}{{\lambda}} - n && \text{(factor the constant $\tfrac{1}{{\lambda}}$ out of the expectation)}\\ &= \frac{\sum_{i=1}^n{\mathbb{E}\mathopen{}\left[X_i\right]\mathclose{}}}{{\lambda}} - n && \text{(linearity of expectation)}\\ &= \frac{\sum_{i=1}^n{\lambda}}{{\lambda}} - n && \text{(${\mathbb{E}\mathopen{}\left[X_i\right]\mathclose{}} = {\lambda}$)}\\ &= \frac{n{\lambda}}{{\lambda}} - n && \text{(sum of $n$ copies of ${\lambda}$)}\\ &= n - n && \text{(cancel ${\lambda}$)}\\ &= 0 && \text{(subtract)}\\ {\operatorname{Var}\mathopen{}\left(\ell'\right)\mathclose{}} &= {\operatorname{Var}\mathopen{}\left(\frac{\sum_{i=1}^nX_i}{{\lambda}} - n\right)\mathclose{}} && \text{(Poisson score)}\\ &= {\operatorname{Var}\mathopen{}\left(\frac{\sum_{i=1}^nX_i}{{\lambda}}\right)\mathclose{}} && \text{(subtracting a constant does not change a variance)}\\ &= \frac{{\operatorname{Var}\mathopen{}\left(\sum_{i=1}^nX_i\right)\mathclose{}}}{{\lambda}^2} && \text{(${\operatorname{Var}\mathopen{}\left(aY\right)\mathclose{}} = a^2 {\operatorname{Var}\mathopen{}\left(Y\right)\mathclose{}}$)}\\ &= \frac{\sum_{i=1}^n{\operatorname{Var}\mathopen{}\left(X_i\right)\mathclose{}}}{{\lambda}^2} && \text{(variance of a sum of independent variables)}\\ &= \frac{\sum_{i=1}^n{\lambda}}{{\lambda}^2} && \text{(${\operatorname{Var}\mathopen{}\left(X_i\right)\mathclose{}} = {\lambda}$)}\\ &= \frac{n{\lambda}}{{\lambda}^2} && \text{(sum of $n$ copies of ${\lambda}$)}\\ &= \frac{n}{{\lambda}} && \text{(cancel one factor of ${\lambda}$)} \end{aligned} \]
which matches \(\mathcal{I}({\lambda}) = n/{\lambda}\) from Example 4.
Example 6 (When the support depends on the parameter) Let \(X_1, \ldots, X_n \ \sim_{\operatorname{iid}}\ \text{Uniform}(0, \theta)\). The likelihood is \(\mathcal{L}(\theta) = \theta^{-n}\) for \(\theta\ge \max_i x_i\) (and 0 otherwise), so on that range \(\ell(\theta) = -n \log \theta\) and \(\ell'(\theta) = -n/\theta\). The score is a nonzero constant, so \({\mathbb{E}\mathopen{}\left[\ell'\right]\mathclose{}} = -n/\theta\ne 0\): Equation 12 fails, because the set of possible data values, \((0, \theta)\), depends on \(\theta\).
Remark 5 (The score is the negative derivative of the surprisal). For a continuous \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\) with density \(\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\), the surprisal of the data value \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\) under parameter value \(\theta\) is \(-\log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\), which is minus the log-likelihood \(-\ell(\theta)\). So the score is minus the derivative of the surprisal with respect to \(\theta\). By Theorem 13, the expected information is the expected squared derivative of the surprisal, with the expectation taken over the data \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\) when the parameter is \(\theta\): \(\mathcal{I}(\theta) = {\mathbb{E}\mathopen{}\left[\ell'^2\right]\mathclose{}}\).
Definition 12 (Kullback–Leibler divergence between two parameter values) Let \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\) be a continuous random vector with density \(\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\mid \theta)\) for a scalar parameter \(\theta\), and let \(\theta_0\) be the true parameter value. The Kullback–Leibler divergence of the model with parameter \(\theta\) from the model with parameter \(\theta_0\) is the expectation, under \(\theta_0\), of the logarithm of the ratio of the two densities. As a function of \(\theta\), it is written
\[ {{D_{\mathrm{KL}}}\mathopen{}\left(\theta_0 \,\Vert\, \theta\right)\mathclose{}} \stackrel{\text{def}}{=}\mathbb{E}_{\theta_0}\mathopen{}\left[\log \frac{\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\mid \theta_0)}{\mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\mid \theta)}\right]\mathclose{}. \]
Example 7 (Divergence between two Poisson rates) For one observation \(X\sim \operatorname{Pois}({\lambda}_0)\), \(\log \mathbb{p}(x \mid {\lambda}) = x \log {\lambda}- {\lambda}- \log x!\), so
\[ \begin{aligned} {{D_{\mathrm{KL}}}\mathopen{}\left({\lambda}_0 \,\Vert\, {\lambda}\right)\mathclose{}} &= \mathbb{E}_{{\lambda}_0}\mathopen{}\left[X\log \frac{{\lambda}_0}{{\lambda}} - {\lambda}_0 + {\lambda}\right]\mathclose{}\\ &= {\lambda}_0 \log \frac{{\lambda}_0}{{\lambda}} - {\lambda}_0 + {\lambda}. \end{aligned} \]
Exercise 14 (Derivative of the divergence) Under the assumptions of Theorem 11, show that the derivative of the divergence of Definition 12 is
\[\frac{\partial}{\partial \theta} {{D_{\mathrm{KL}}}\mathopen{}\left(\theta_0 \,\Vert\, \theta\right)\mathclose{}} = -\mathbb{E}_{\theta_0}\mathopen{}\left[\ell'(\theta)\right]\mathclose{},\]
where \(\ell'(\theta)\) is the score evaluated at \(\theta\), and the expectation is taken with the data generated under \(\theta_0\).
Solution 14. Write \(\ell(\theta) = \log \mathbb{p}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}\mid \theta)\).
\[ \begin{aligned} {{D_{\mathrm{KL}}}\mathopen{}\left(\theta_0 \,\Vert\, \theta\right)\mathclose{}} &= \mathbb{E}_{\theta_0}\mathopen{}\left[\ell(\theta_0) - \ell(\theta)\right]\mathclose{} && \text{(log of a ratio is a difference of logs)}\\ &= \mathbb{E}_{\theta_0}\mathopen{}\left[\ell(\theta_0)\right]\mathclose{} - \mathbb{E}_{\theta_0}\mathopen{}\left[\ell(\theta)\right]\mathclose{} && \text{(linearity of expectation)}\\ \frac{\partial}{\partial \theta} {{D_{\mathrm{KL}}}\mathopen{}\left(\theta_0 \,\Vert\, \theta\right)\mathclose{}} &= -\frac{\partial}{\partial \theta} \mathbb{E}_{\theta_0}\mathopen{}\left[\ell(\theta)\right]\mathclose{} && \text{(the first term does not depend on $\theta$)}\\ &= -\mathbb{E}_{\theta_0}\mathopen{}\left[\frac{\partial}{\partial \theta} \ell(\theta)\right]\mathclose{} && \text{(exchange derivative and expectation)}\\ &= -\mathbb{E}_{\theta_0}\mathopen{}\left[\ell'(\theta)\right]\mathclose{} && \text{(definition of the score)} \end{aligned} \]
Exercise 15 (Second derivative of the divergence) Under the assumptions of Exercise 14, show that the second derivative of the divergence of Definition 12 is
\[ \frac{\partial^2}{\partial \theta^2} {{D_{\mathrm{KL}}}\mathopen{}\left(\theta_0 \,\Vert\, \theta\right)\mathclose{}} = \mathbb{E}_{\theta_0}\mathopen{}\left[-\ell''(\theta)\right]\mathclose{}, \]
where \(\ell''(\theta)\) is the Hessian of the log-likelihood evaluated at \(\theta\).
Solution 15. \[ \begin{aligned} \frac{\partial^2}{\partial \theta^2} {{D_{\mathrm{KL}}}\mathopen{}\left(\theta_0 \,\Vert\, \theta\right)\mathclose{}} &= \frac{\partial}{\partial \theta} \mathopen{}\left(-\mathbb{E}_{\theta_0}\mathopen{}\left[\ell'(\theta)\right]\mathclose{}\right)\mathclose{} && \text{(@sol-kl-slope)}\\ &= -\mathbb{E}_{\theta_0}\mathopen{}\left[\frac{\partial}{\partial \theta} \ell'(\theta)\right]\mathclose{} && \text{(exchange derivative and expectation)}\\ &= -\mathbb{E}_{\theta_0}\mathopen{}\left[\ell''(\theta)\right]\mathclose{} && \text{(the Hessian is the derivative of the score)}\\ &= \mathbb{E}_{\theta_0}\mathopen{}\left[-\ell''(\theta)\right]\mathclose{} && \text{(move the sign inside the expectation)} \end{aligned} \]
Theorem 14 (The expected information is the curvature of the Kullback–Leibler divergence) Under the assumptions of Theorem 11, the second derivative at \(\theta= \theta_0\) of the divergence \({{D_{\mathrm{KL}}}\mathopen{}\left(\theta_0 \,\Vert\, \theta\right)\mathclose{}}\) of Definition 12 is the expected information:
\[\left.{\frac{\partial^2}{\partial \theta^2} {{D_{\mathrm{KL}}}\mathopen{}\left(\theta_0 \,\Vert\, \theta\right)\mathclose{}}}\right|_{\theta= \theta_0} = \mathcal{I}(\theta_0)\]
Proof. By Solution 15, the second derivative is \(\mathbb{E}_{\theta_0}\mathopen{}\left[-\ell''(\theta)\right]\mathclose{}\) at every \(\theta\). Setting \(\theta= \theta_0\) gives the expectation, under the true parameter \(\theta_0\), of minus the Hessian of the log-likelihood, which is \(\mathcal{I}(\theta_0)\) by Definition 10.
Example 8 (Curvature of the divergence for Poisson data) Differentiating the divergence of Example 7 twice with respect to \({\lambda}\) gives \(\frac{\partial}{\partial {\lambda}} {{D_{\mathrm{KL}}}\mathopen{}\left({\lambda}_0 \,\Vert\, {\lambda}\right)\mathclose{}} = 1 - {\lambda}_0 / {\lambda}\) and \(\frac{\partial^2}{\partial {\lambda}^2} {{D_{\mathrm{KL}}}\mathopen{}\left({\lambda}_0 \,\Vert\, {\lambda}\right)\mathclose{}} = {\lambda}_0 / {\lambda}^2\), so at \({\lambda}= {\lambda}_0\) the second derivative is \(1/{\lambda}_0\), which is the expected information of one observation (Example 4). A finite-difference second derivative of the divergence, summed directly over the Poisson probabilities, agrees:
These notes write the observed information as \(I\) and the expected information as \(\mathcal{I}\). Sources disagree on these symbols. The Notation Across Sources page of the macros site lists them side by side.
1.8 Asymptotic distribution of the maximum likelihood estimate
Theorem 15 (Central limit theorem for MLEs) For \(\operatorname{iid}\) data from a correctly specified model satisfying regularity conditions (including those of Theorem 13, an identifiable parameter, a true parameter value in the interior of the parameter space, and a positive definite information matrix), a consistent solution \(\hat\theta_{\text{ML}}\) of the score equation exists, and for large \(n\) it has approximately a Gaussian distribution, centered at the true parameter value \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}\), with covariance matrix equal to the inverse of the expected information:
\[ \hat\theta_{\text{ML}}\ \dot{\sim} \ {\operatorname{N}\mathopen{}\left(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}, {\mathopen{}\left(\mathcal{I}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}})\right)\mathclose{}}^{-1}\right)\mathclose{}} \tag{14}\]
Remark 6 (Consistent roots and global maximizers). These conditions guarantee a consistent root of the score equation; that root is the global maximizer of the likelihood under further conditions, for example when the log-likelihood is strictly concave, as for Poisson data, whose Hessian is negative for every \({\lambda}\) (Example 4).
Example 9 (Approximate distribution of the Poisson MLE) For \(X_1, \ldots, X_n \ \sim_{\operatorname{iid}}\ \operatorname{Pois}({\lambda})\), setting the score \(\sum_{i=1}^nX_i/{\lambda}- n\) (Example 5) to zero gives \(\hat{\lambda}_{\text{ML}} = \bar X\), and \(\mathcal{I}({\lambda}) = n/{\lambda}\) (Example 4), so Theorem 15 says that for large \(n\):
\[\hat{\lambda}_{\text{ML}} \ \dot{\sim} \ {\operatorname{N}\mathopen{}\left({\lambda}, \frac{{\lambda}}{n}\right)\mathclose{}}\]
In this example the mean and variance are exact: \({\mathbb{E}\mathopen{}\left[\bar X\right]\mathclose{}} = {\lambda}\) and \({\operatorname{Var}\mathopen{}\left(\bar X\right)\mathclose{}} = {\lambda}/n\). The approximation is in the Gaussian shape.
Theorem 15 involves the unknown \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}\), so to use it we estimate \(\mathcal{I}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}})\), by either the expected information at the MLE, \(\mathcal{I}(\hat\theta_{\text{ML}})\), or the observed information at the MLE, \(I(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}; \hat\theta_{\text{ML}})\). Either way, the estimated standard error of the \(k\)th entry of \(\hat\theta_{\text{ML}}\) is:
\[ {\mathop{\widehat{\operatorname{SE}}}\nolimits\mathopen{}\left(\hat{\theta}_k\right)\mathclose{}} = \sqrt{\mathopen{}\left[{\mathopen{}\left(\hat{\mathcal{I}}\right)\mathclose{}}^{-1}\right]\mathclose{}_{kk}} \]
where \(\hat{\mathcal{I}}\) is whichever estimate of \(\mathcal{I}(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}})\) we chose.
Remark 7 (Observed versus expected information). Using the observed information is often more convenient, and there are settings where it is provably better by some criteria [18].
- Hogg et al. [7, Sec. 6.6], pp. 285–289 covers asymptotic distributions of maximum likelihood estimators.
- Rice [8, Sec. 8.5.2], pp. 274–278 covers large-sample theory for maximum likelihood estimators.
1.9 Quantifying uncertainty about MLEs
1.9.1 Confidence intervals for MLEs
Definition 13 (Wald confidence interval) The approximate \(100(1-\alpha)\%\) Wald confidence interval for the \(k\)th entry \(\theta_k\) of a parameter vector is
\[ \hat{\theta}_k \pm z_{1 - \alpha/2} \times {\mathop{\widehat{\operatorname{SE}}}\nolimits\mathopen{}\left(\hat{\theta}_k\right)\mathclose{}} \]
where \(\hat{\theta}_k\) is the \(k\)th entry of \(\hat\theta_{\text{ML}}\), \({\mathop{\widehat{\operatorname{SE}}}\nolimits\mathopen{}\left(\hat{\theta}_k\right)\mathclose{}}\) is its estimated standard error, and \(z_{\beta}\) is the \(\beta\) quantile of the standard Gaussian distribution.
By Theorem 15, \((\hat{\theta}_k - \theta_k)/{\mathop{\widehat{\operatorname{SE}}}\nolimits\mathopen{}\left(\hat{\theta}_k\right)\mathclose{}}\) has approximately a standard Gaussian distribution in large samples, so the Wald interval is an approximate confidence interval for \(\theta_k\). For a 95% interval, \(z_{0.975} \approx 1.96\).
- Casella and Berger [3, Sec. 10.4.1], pp. 496–498 covers approximate maximum likelihood intervals.
- Rice [8, Sec. 8.5.3], pp. 279–284 covers confidence intervals from maximum likelihood estimators.
1.9.2 Wald tests
Definition 14 (Wald test) The Wald test of \(H_0: \theta_k = \theta_{k,0}\) uses the test statistic
\[Z \stackrel{\text{def}}{=}\frac{\hat{\theta}_k - \theta_{k,0}}{{\mathop{\widehat{\operatorname{SE}}}\nolimits\mathopen{}\left(\hat{\theta}_k\right)\mathclose{}}}.\]
Source: Wikipedia contributors [19].
Definition 15 (Wald statistic for several constraints) For \(q\) constraints \(H_0: \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}_{(q)} = \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}_{(q),0}\) on a \(q \times 1\) subvector, the Wald statistic is \({\mathopen{}\left(\hat{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}}_{(q)} - \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}_{(q),0}\right)\mathclose{}}^{\top}\,{\mathopen{}\left(\hat{V}_{(q)}\right)\mathclose{}}^{-1}\,\mathopen{}\left(\hat{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}}_{(q)} - \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}_{(q),0}\right)\mathclose{}\), where \(\hat V_{(q)}\) is the corresponding \(q \times q\) block of \({\mathopen{}\left(\hat{\mathcal{I}}\right)\mathclose{}}^{-1}\).
Example 10 (Wald interval and test for a Poisson rate) For \(X_1, \ldots, X_n \ \sim_{\operatorname{iid}}\ \operatorname{Pois}({\lambda})\), \(\hat{\lambda}_{\text{ML}} = \bar x\) and \(\mathcal{I}({\lambda}) = n/{\lambda}\) (Example 9), so \({\mathop{\widehat{\operatorname{SE}}}\nolimits\mathopen{}\left(\hat{\lambda}\right)\mathclose{}} = \sqrt{\bar x/n}\). With \(n = 13\) and \(\bar x = 72/13\), the 95% Wald interval for \({\lambda}\), and the Wald test of \(H_0: {\lambda}= 4\), are:
n_obs <- 13
xbar_obs <- 72 / 13
se_rate <- sqrt(xbar_obs / n_obs)
z_wald <- (xbar_obs - 4) / se_rate
c(
  lower = xbar_obs - qnorm(0.975) * se_rate,
  upper = xbar_obs + qnorm(0.975) * se_rate,
  z = z_wald,
  p_value = 2 * pnorm(-abs(z_wald))
)
#>     lower     upper         z   p_value
#> 4.2591657 6.8177574 2.3570226 0.0184221
Remark 8 (Null distributions of the Wald statistics). By Theorem 15, the statistic \(Z\) of the Wald test has approximately a standard Gaussian distribution under \(H_0\) in large samples. The Wald statistic for \(q\) constraints (Definition 15) has approximately a \(\chi^2_q\) distribution under \(H_0\).
1.9.3 Likelihood ratio tests for MLEs
Definition 16 (Likelihood ratio statistic) Suppose a null hypothesis \(H_0\) imposes \(q\) constraints on the parameter vector \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}\). Let \(\hat\theta_{\text{ML}}\) be the unrestricted MLE and \(\hat{\theta}_0\) the MLE under \(H_0\). The likelihood ratio statistic is
\[ \Lambda\stackrel{\text{def}}{=}2\mathopen{}\left(\ell(\hat\theta_{\text{ML}}) - \ell(\hat{\theta}_0)\right)\mathclose{} \]
Source: Wikipedia contributors [20].
Exercise 16 (Quadratic approximation to the log-likelihood) Let \(\theta\) be a scalar parameter, and suppose the MLE \(\hat\theta_{\text{ML}}\) maximizes \(\ell\) at an interior point of the parameter space, where \(\ell\) is twice differentiable. Use a second-order Taylor expansion around \(\hat\theta_{\text{ML}}\) to approximate \(\ell(\theta_0)\) in terms of \(\ell(\hat\theta_{\text{ML}})\) and the Hessian \(\ell''(\hat\theta_{\text{ML}})\).
Solution 16. The MLE maximizes \(\ell\) at an interior point, so \(\ell'(\hat\theta_{\text{ML}}) = 0\). A second-order Taylor expansion of \(\ell(\theta_0)\) around \(\hat\theta_{\text{ML}}\) gives:
\[ \begin{aligned} \ell(\theta_0) &\approx \ell(\hat\theta_{\text{ML}}) + \ell'(\hat\theta_{\text{ML}})(\theta_0 - \hat\theta_{\text{ML}}) + \frac{1}{2}\ell''(\hat\theta_{\text{ML}})(\theta_0 - \hat\theta_{\text{ML}})^2 && \text{(Taylor expansion)}\\ &= \ell(\hat\theta_{\text{ML}}) + 0 \cdot (\theta_0 - \hat\theta_{\text{ML}}) + \frac{1}{2}\ell''(\hat\theta_{\text{ML}})(\theta_0 - \hat\theta_{\text{ML}})^2 && \text{($\ell'(\hat\theta_{\text{ML}}) = 0$)}\\ &= \ell(\hat\theta_{\text{ML}}) + \frac{1}{2}\ell''(\hat\theta_{\text{ML}})(\theta_0 - \hat\theta_{\text{ML}})^2 && \text{(drop the zero term)} \end{aligned} \]
Lemma 2 (Quadratic approximation to the log-likelihood) Let \(\theta\) be a scalar parameter with log-likelihood \(\ell\), and suppose the MLE \(\hat\theta_{\text{ML}}\) maximizes \(\ell\) at an interior point of the parameter space, where \(\ell\) is twice differentiable with Hessian \(\ell''\). Then the log-likelihood at any nearby value \(\theta_0\) is approximately quadratic around \(\hat\theta_{\text{ML}}\):
\[\ell(\theta_0) \approx \ell(\hat\theta_{\text{ML}}) + \frac{1}{2}\ell''(\hat\theta_{\text{ML}})(\theta_0 - \hat\theta_{\text{ML}})^2\]
Proof. This is the solution to Exercise 16, worked in Solution 16.
Exercise 17 (Likelihood ratio statistic for a point null hypothesis) With a scalar parameter \(\theta\), the point null hypothesis \(H_0: \theta= \theta_0\) imposes \(q = 1\) constraint. Use Exercise 16 to approximate the likelihood ratio statistic \(\Lambda\) in terms of the observed information \(I(\hat\theta_{\text{ML}})\).
Solution 17. Under \(H_0\), the only allowed value is \(\theta_0\), so the restricted MLE is \(\hat{\theta}_0 = \theta_0\). Substituting the approximation from Lemma 2:
\[ \begin{aligned} \Lambda &= 2\mathopen{}\left(\ell(\hat\theta_{\text{ML}}) - \ell(\hat{\theta}_0)\right)\mathclose{} && \text{(definition of $\Lambda$)}\\ &= 2\mathopen{}\left(\ell(\hat\theta_{\text{ML}}) - \ell(\theta_0)\right)\mathclose{} && \text{($\hat{\theta}_0 = \theta_0$)}\\ &\approx 2\mathopen{}\left(\ell(\hat\theta_{\text{ML}}) - \mathopen{}\left(\ell(\hat\theta_{\text{ML}}) + \frac{1}{2}\ell''(\hat\theta_{\text{ML}})(\theta_0 - \hat\theta_{\text{ML}})^2\right)\mathclose{}\right)\mathclose{} && \text{(substitute the expansion)}\\ &= 2\mathopen{}\left(\ell(\hat\theta_{\text{ML}}) - \ell(\hat\theta_{\text{ML}}) - \frac{1}{2}\ell''(\hat\theta_{\text{ML}})(\theta_0 - \hat\theta_{\text{ML}})^2\right)\mathclose{} && \text{(distribute the minus sign)}\\ &= 2\mathopen{}\left(-\frac{1}{2}\ell''(\hat\theta_{\text{ML}})(\theta_0 - \hat\theta_{\text{ML}})^2\right)\mathclose{} && \text{(cancel $\ell(\hat\theta_{\text{ML}})$)}\\ &= -\ell''(\hat\theta_{\text{ML}})(\theta_0 - \hat\theta_{\text{ML}})^2 && \text{(multiply by 2)}\\ &= -\ell''(\hat\theta_{\text{ML}})(\hat\theta_{\text{ML}}- \theta_0)^2 && \text{($(a - b)^2 = (b - a)^2$)}\\ &= I(\hat\theta_{\text{ML}})(\hat\theta_{\text{ML}}- \theta_0)^2 && \text{(observed information is the negative Hessian)} \end{aligned} \]
Lemma 3 (Likelihood ratio statistic for a point null hypothesis) Under the conditions of Lemma 2, consider the point null hypothesis \(H_0: \theta= \theta_0\), which imposes \(q = 1\) constraint. Then the likelihood ratio statistic \(\Lambda\) is approximately the observed information \(I(\hat\theta_{\text{ML}})\) at the MLE \(\hat\theta_{\text{ML}}\) times the squared distance from the MLE to \(\theta_0\):
\[\Lambda\approx I(\hat\theta_{\text{ML}})(\hat\theta_{\text{ML}}- \theta_0)^2\]
Proof. This is the solution to Exercise 17, worked in Solution 17. It builds on Lemma 2.
Exercise 18 (Standardizing an approximately Gaussian estimate) Suppose \(\hat\theta_{\text{ML}}\ \dot{\sim} \ {\operatorname{N}\mathopen{}\left(\theta_0, \mathcal{I}(\theta_0)^{-1}\right)\mathclose{}}\), and define \(Z \stackrel{\text{def}}{=}\sqrt{\mathcal{I}(\theta_0)}\,(\hat\theta_{\text{ML}}- \theta_0)\). Find the approximate distributions of \(Z\) and of \(Z^2\).
Solution 18. \(Z\) is a linear function of \(\hat\theta_{\text{ML}}\), so it is approximately Gaussian, with approximate mean and variance:
\[ \begin{aligned} {\mathbb{E}\mathopen{}\left[Z\right]\mathclose{}} &= {\mathbb{E}\mathopen{}\left[\sqrt{\mathcal{I}(\theta_0)}\,(\hat\theta_{\text{ML}}- \theta_0)\right]\mathclose{}} && \text{(definition of $Z$)}\\ &= \sqrt{\mathcal{I}(\theta_0)}\,{\mathbb{E}\mathopen{}\left[\hat\theta_{\text{ML}}- \theta_0\right]\mathclose{}} && \text{(factor the constant $\sqrt{\mathcal{I}(\theta_0)}$ out of the expectation)}\\ &= \sqrt{\mathcal{I}(\theta_0)}\,\mathopen{}\left({\mathbb{E}\mathopen{}\left[\hat\theta_{\text{ML}}\right]\mathclose{}} - {\mathbb{E}\mathopen{}\left[\theta_0\right]\mathclose{}}\right)\mathclose{} && \text{(linearity of expectation)}\\ &= \sqrt{\mathcal{I}(\theta_0)}\,\mathopen{}\left({\mathbb{E}\mathopen{}\left[\hat\theta_{\text{ML}}\right]\mathclose{}} - \theta_0\right)\mathclose{} && \text{(the expectation of a constant is that constant)}\\ &\approx \sqrt{\mathcal{I}(\theta_0)}\,(\theta_0 - \theta_0) && \text{(approximate mean of $\hat\theta_{\text{ML}}$)}\\ &= \sqrt{\mathcal{I}(\theta_0)} \cdot 0 && \text{(subtract)}\\ &= 0 && \text{(multiply by zero)} \end{aligned} \]
\[ \begin{aligned} {\operatorname{Var}\mathopen{}\left(Z\right)\mathclose{}} &= {\operatorname{Var}\mathopen{}\left(\sqrt{\mathcal{I}(\theta_0)}\,(\hat\theta_{\text{ML}}- \theta_0)\right)\mathclose{}} && \text{(definition of $Z$)}\\ &= \mathcal{I}(\theta_0) {\operatorname{Var}\mathopen{}\left(\hat\theta_{\text{ML}}\right)\mathclose{}} && \text{(${\operatorname{Var}\mathopen{}\left(aY + b\right)\mathclose{}} = a^2 {\operatorname{Var}\mathopen{}\left(Y\right)\mathclose{}}$)}\\ &\approx \mathcal{I}(\theta_0) \mathcal{I}(\theta_0)^{-1} && \text{(approximate variance of $\hat\theta_{\text{ML}}$)}\\ &= 1 && \text{(a number times its inverse is 1)} \end{aligned} \]
So \(Z \ \dot{\sim} \ {\operatorname{N}\mathopen{}\left(0, 1\right)\mathclose{}}\). The square of a standard Gaussian variable has a \(\chi^2_1\) distribution, so \(Z^2\) has approximately a \(\chi^2_1\) distribution.
Lemma 4 (Standardizing an approximately Gaussian estimate) Suppose the MLE \(\hat\theta_{\text{ML}}\) is approximately Gaussian with mean \(\theta_0\) and variance \(\mathcal{I}(\theta_0)^{-1}\), the inverse of the expected information: \(\hat\theta_{\text{ML}}\ \dot{\sim} \ {\operatorname{N}\mathopen{}\left(\theta_0, \mathcal{I}(\theta_0)^{-1}\right)\mathclose{}}\). Define \(Z \stackrel{\text{def}}{=}\sqrt{\mathcal{I}(\theta_0)}\,(\hat\theta_{\text{ML}}- \theta_0)\). Then \(Z\) is approximately standard Gaussian, so \(Z^2\) is approximately \(\chi^2_1\):
\[Z^2 \ \dot{\sim} \ \chi^2_1\]
Proof. This is the solution to Exercise 18, worked in Solution 18.
Theorem 16 (Wilks’ theorem) Suppose the conditions of Theorem 15 hold, and a null hypothesis \(H_0\) imposes \(q\) constraints on the parameter vector \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}\). Then, if \(H_0\) is true, as \(n \to \infty\), the likelihood ratio statistic \(\Lambda\) satisfies:
\[ \Lambda \overset{d}{\to} \chi^2_q \]
Source: Wikipedia contributors [21].
Proof. We sketch the argument for a scalar parameter and the point null hypothesis \(H_0: \theta= \theta_0\), which imposes \(q = 1\) constraint. For the full proof, see [22] or [1, Sec. 5.7].
By Lemma 3, \(\Lambda\approx I(\hat\theta_{\text{ML}})(\hat\theta_{\text{ML}}- \theta_0)^2\). Under the regularity conditions, \(I(\hat\theta_{\text{ML}})/\mathcal{I}(\theta_0) \to 1\) in probability, by the law of large numbers and the consistency of \(\hat\theta_{\text{ML}}\); this sketch assumes that step rather than proving it. So, with \(Z\) as in Lemma 4:
\[ \begin{aligned} \Lambda &\approx I(\hat\theta_{\text{ML}})(\hat\theta_{\text{ML}}- \theta_0)^2 && \text{(quadratic approximation to $\Lambda$)}\\ &\approx \mathcal{I}(\theta_0)(\hat\theta_{\text{ML}}- \theta_0)^2 && \text{($I(\hat\theta_{\text{ML}})/\mathcal{I}(\theta_0) \to 1$)}\\ &= \mathopen{}\left(\sqrt{\mathcal{I}(\theta_0)}\,(\hat\theta_{\text{ML}}- \theta_0)\right)\mathclose{}^2 && \text{(write the product as a square)}\\ &= Z^2 && \text{(definition of $Z$)} \end{aligned} \]
By Theorem 15, \(\hat\theta_{\text{ML}}\ \dot{\sim} \ {\operatorname{N}\mathopen{}\left(\theta_0, \mathcal{I}(\theta_0)^{-1}\right)\mathclose{}}\) under \(H_0\), so by Lemma 4, \(\Lambda\approx Z^2\) has approximately a \(\chi^2_1\) distribution.
With \(q\) constraints, the same argument in matrix form makes \(\Lambda\) approximately a sum of \(q\) squared, independent standard Gaussian variables, which has a \(\chi^2_q\) distribution; this sketch does not derive the matrix form.
Remark 9 (Wilks’ theorem for nested models). Equivalently, in terms of nested models: if a full model \(M_1\) has \(p\) free parameters, and a nested model \(M_0 \subset M_1\), obtained by imposing \(q\) constraints on \(M_1\), has \(p_0 = p - q\) free parameters, then when \(M_0\) is true, \(\Lambda= 2\mathopen{}\left(\ell_{M_1}(\hat\theta_{\text{ML}}) - \ell_{M_0}(\hat{\theta}_0)\right)\mathclose{}\) converges in distribution to \(\chi^2_q\).
Example 11 (Likelihood ratio test for a Poisson rate) For \(X_1, \ldots, X_n \ \sim_{\operatorname{iid}}\ \operatorname{Pois}({\lambda})\) and \(H_0: {\lambda}= {\lambda}_0\), the log-likelihood is \(\ell({\lambda}) = n\bar x \log{\lambda}- n{\lambda}- \sum_i \log x_i!\) and \(\hat{{\lambda}}_{\text{ML}} = \bar x\), so:
\[ \begin{aligned} \Lambda &= 2\mathopen{}\left(\ell(\bar x) - \ell({\lambda}_0)\right)\mathclose{} && \text{(definition of $\Lambda$)}\\ &= 2\mathopen{}\left(\mathopen{}\left(n\bar x \log \bar x - n\bar x - \sum_i \log x_i!\right)\mathclose{} - \mathopen{}\left(n\bar x \log{\lambda}_0 - n{\lambda}_0 - \sum_i \log x_i!\right)\mathclose{}\right)\mathclose{} && \text{(substitute $\ell(\bar x)$ and $\ell({\lambda}_0)$)}\\ &= 2\mathopen{}\left(n\bar x \log \bar x - n\bar x - \sum_i \log x_i! - n\bar x \log{\lambda}_0 + n{\lambda}_0 + \sum_i \log x_i!\right)\mathclose{} && \text{(distribute the minus sign)}\\ &= 2\mathopen{}\left(n\bar x \log \bar x - n\bar x - n\bar x \log{\lambda}_0 + n{\lambda}_0\right)\mathclose{} && \text{(the $\log x_i!$ terms cancel)}\\ &= 2n\mathopen{}\left(\bar x \log \bar x - \bar x - \bar x \log{\lambda}_0 + {\lambda}_0\right)\mathclose{} && \text{(factor out $n$)}\\ &= 2n\mathopen{}\left(\bar x \log \bar x - \bar x \log{\lambda}_0 - \bar x + {\lambda}_0\right)\mathclose{} && \text{(reorder the terms)}\\ &= 2n\mathopen{}\left(\bar x \mathopen{}\left(\log \bar x - \log{\lambda}_0\right)\mathclose{} - \bar x + {\lambda}_0\right)\mathclose{} && \text{(factor $\bar x$ out of the two log terms)}\\ &= 2n\mathopen{}\left(\bar x \log\frac{\bar x}{{\lambda}_0} - \bar x + {\lambda}_0\right)\mathclose{} && \text{(log of a quotient)} \end{aligned} \]
For example, with \(n = 13\), \(\bar x = 72/13\), and \({\lambda}_0 = 4\):
- Casella and Berger [3, Sec. 10.3.1], pp. 488–491 covers asymptotic distribution of likelihood ratio tests.
- Rice [8, Sec. 9.4], pp. 339–340 covers generalized likelihood ratio tests.
1.9.4 Exact and approximate tests
| Inference goal | Exact test (Gaussian outcomes) | Null distribution | Approximate test (MLE) | Approximate null distribution |
|---|---|---|---|---|
| Single coefficient | t-test | \(T_{n-p}\) | Wald z-test | \(Z \sim N(0,1)\) |
| Linear combination of coefficients | t-test | \(T_{n-p}\) | Wald z-test | \(Z \sim N(0,1)\) |
| Nested models (\(q\) constraints) | Partial F-test | \(F_{q,\, n-p}\) | Likelihood ratio test or Wald test | \(\chi^2_q\) |
| One-sample population mean | One-sample t-test | \(T_{n-1}\) | z-test | \(Z \sim N(0,1)\) |
| Two-sample population means | Two-sample t-test (pooled variance) | \(T_{n_1+n_2-2}\) | z-test | \(Z \sim N(0,1)\) |
| \(K\)-group population means (ANOVA) | F-test | \(F_{K-1,\, n-K}\) | Likelihood ratio test or Wald test | \(\chi^2_{K-1}\) |
Remark 10 (Exact and approximate tests). The \(t\) and \(F\) distributions are defined in Statistical Inference. The exact tests assume \(Y_i\ \sim_{\perp\!\!\!\perp}\ N(\mu_i, \sigma^2)\), with a common variance. The approximate tests hold asymptotically, for any model that is correctly specified and satisfies the regularity conditions of Theorem 15, Gaussian or not.
1.9.5 Prediction intervals
Definition 17 (Prediction interval) A \(100(1-\alpha)\%\) prediction interval for a future random quantity \(Y^*\) is a pair of statistics \(L\) and \(U\), computed from the observed data, such that the interval from \(L\) to \(U\) contains \(Y^*\) with probability \(1 - \alpha\), where the probability accounts for the randomness of both the observed data and \(Y^*\):
\[ {\Pr\mathopen{}\left(L \le Y^* \le U\right)\mathclose{}} = 1 - \alpha \]
Source: Wikipedia contributors [23].
Suppose \(X_1, \ldots, X_n \ \sim_{\operatorname{iid}}\ {\operatorname{N}\mathopen{}\left(\mu, \sigma^2\right)\mathclose{}}\) with \(\sigma^2\) known, and we want to predict the sample mean \(\bar X^*\) of \(m\) new observations from the same distribution, independent of the first \(n\). The MLE of \(\mu\) is \(\hat{\mu}= \bar X\), and the difference \(\bar X^* - \hat{\mu}\) (the negative of the prediction error) is a difference of independent Gaussian variables, so:
\[ \begin{aligned} {\operatorname{Var}\mathopen{}\left(\bar X^* - \hat{\mu}\right)\mathclose{}} &= {\operatorname{Var}\mathopen{}\left(\bar X^*\right)\mathclose{}} + {\operatorname{Var}\mathopen{}\left(\hat{\mu}\right)\mathclose{}} && \text{(variance of a difference of independent variables)}\\ &= \frac{\sigma^2}{m} + \frac{\sigma^2}{n} && \text{(variance of a sample mean)} \end{aligned} \]
and \(\bar X^* - \hat{\mu}\sim {\operatorname{N}\mathopen{}\left(0, \sigma^2\mathopen{}\left(\frac{1}{m} + \frac{1}{n}\right)\mathclose{}\right)\mathclose{}}\). So a \(100(1 - \alpha)\%\) prediction interval for \(\bar X^*\) is:
\[\hat{\mu}\pm z_{1 - \alpha/2} \, \sigma\sqrt{\frac{1}{m} + \frac{1}{n}}\]
Usually \(m = 1\). The term \(1/n\) accounts for the uncertainty in \(\hat{\mu}\), and becomes negligible when \(n\) is much larger than \(m\).
Remark 11 (Prediction intervals versus confidence intervals). A confidence interval covers a fixed parameter, such as the population mean \(\mu\). A prediction interval (Definition 17) covers a random quantity, such as a new outcome, or, in the example above, the sample mean \(\bar X^*\) of \(m\) new observations. Its probability accounts for the randomness of the new observations, not only of the observed data.
In the Gaussian example above, the standard error of \(\hat{\mu}= \bar X\) is \(\sigma/ \sqrt{n}\), so the two intervals, the Wald confidence interval for \(\mu\) and the prediction interval for \(\bar X^*\), are
\[ \begin{aligned} &\hat{\mu}\pm z_{1 - \alpha/2} \, \sigma\sqrt{\frac{1}{n}} && \text{(confidence interval for $\mu$)}\\ &\hat{\mu}\pm z_{1 - \alpha/2} \, \sigma\sqrt{\frac{1}{m} + \frac{1}{n}} && \text{(prediction interval for $\bar X^*$)} \end{aligned} \]
The prediction interval is always the wider of the two, because its variance has the extra term \(\sigma^2/ m\), the variance of the new observations’ sample mean. As \(n\) grows, the width of the confidence interval shrinks to 0, but the width of the prediction interval shrinks only to \(2 z_{1 - \alpha/2} \, \sigma/ \sqrt{m}\): more data pins down \(\mu\), but cannot remove the randomness of the new observations. The same contrast holds in regression, between a confidence interval for the conditional mean \({\mathbb{E}\mathopen{}\left[Y \mid X = x\right]\mathclose{}}\) and a prediction interval for a new outcome \(Y\) at \(X = x\).
2 Example: maximum likelihood for tropical cyclones in Australia
2.0.1 Data
Table 2 records the number of tropical cyclones in northeastern Australia during 13 November-to-April cyclone seasons, from 1956/57 to 1968/69 [1, Sec. 1.6.5]. Figure 1 graphs the number of cyclones by season. Let \(X_i\) represent the number of cyclones in season \(i\), and \(x_i\) its observed value.
[Code]
| years | season | number |
|---|---|---|
| 1956/7 | 1 | 6 |
| 1957/8 | 2 | 5 |
| 1958/9 | 3 | 4 |
| 1959/60 | 4 | 6 |
| 1960/1 | 5 | 6 |
| 1961/2 | 6 | 3 |
| 1962/3 | 7 | 12 |
| 1963/4 | 8 | 7 |
| 1964/5 | 9 | 4 |
| 1965/6 | 10 | 2 |
| 1966/7 | 11 | 6 |
| 1967/8 | 12 | 7 |
| 1968/9 | 13 | 4 |
2.0.2 Exploratory analysis
Suppose we want to learn how many cyclones to expect per season.
[Code]
cyclones |>
  dplyr::mutate(years = factor(years, levels = years)) |>
  ggplot2::ggplot() +
  ggplot2::aes(x = years, y = number, group = 1) +
  ggplot2::geom_point() +
  ggplot2::geom_line() +
  ggplot2::xlab("Season") +
  ggplot2::ylab("Number of cyclones") +
  ggplot2::expand_limits(y = 0) +
  ggplot2::theme(axis.text.x = ggplot2::element_text(vjust = .5, angle = 45))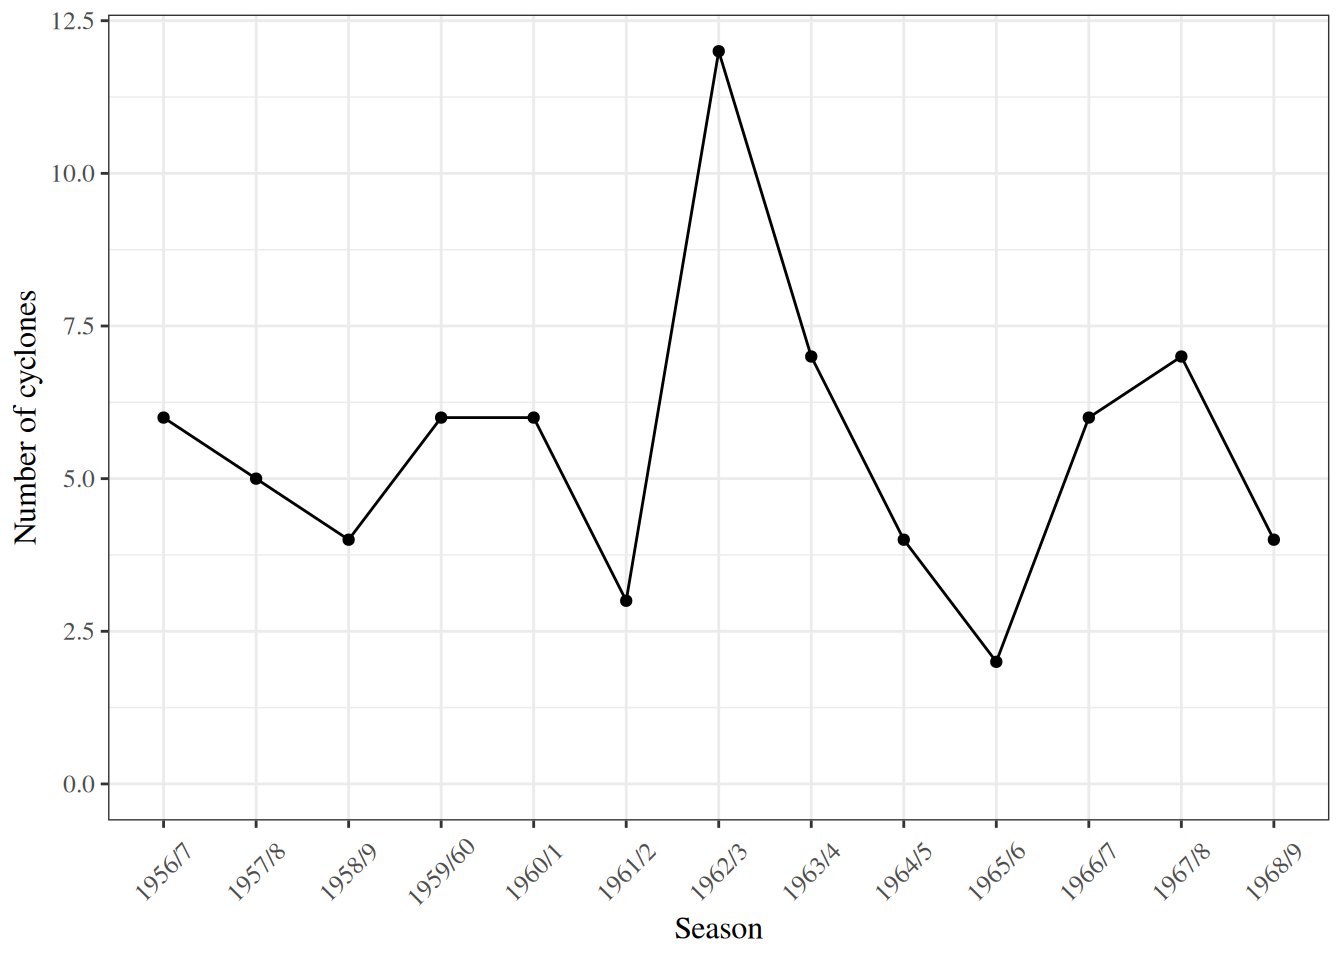
Figure 1 shows no obvious trend, and no obvious correlation between adjacent seasons, so we assume that the seasons’ counts are mutually independent. We also assume that they are identically distributed, with a common distribution \(\Pr(X = x)\); the expression has no index \(i\), because the distribution is the same for every season.
Figure 2 shows the empirical distribution of the counts.
[Code]
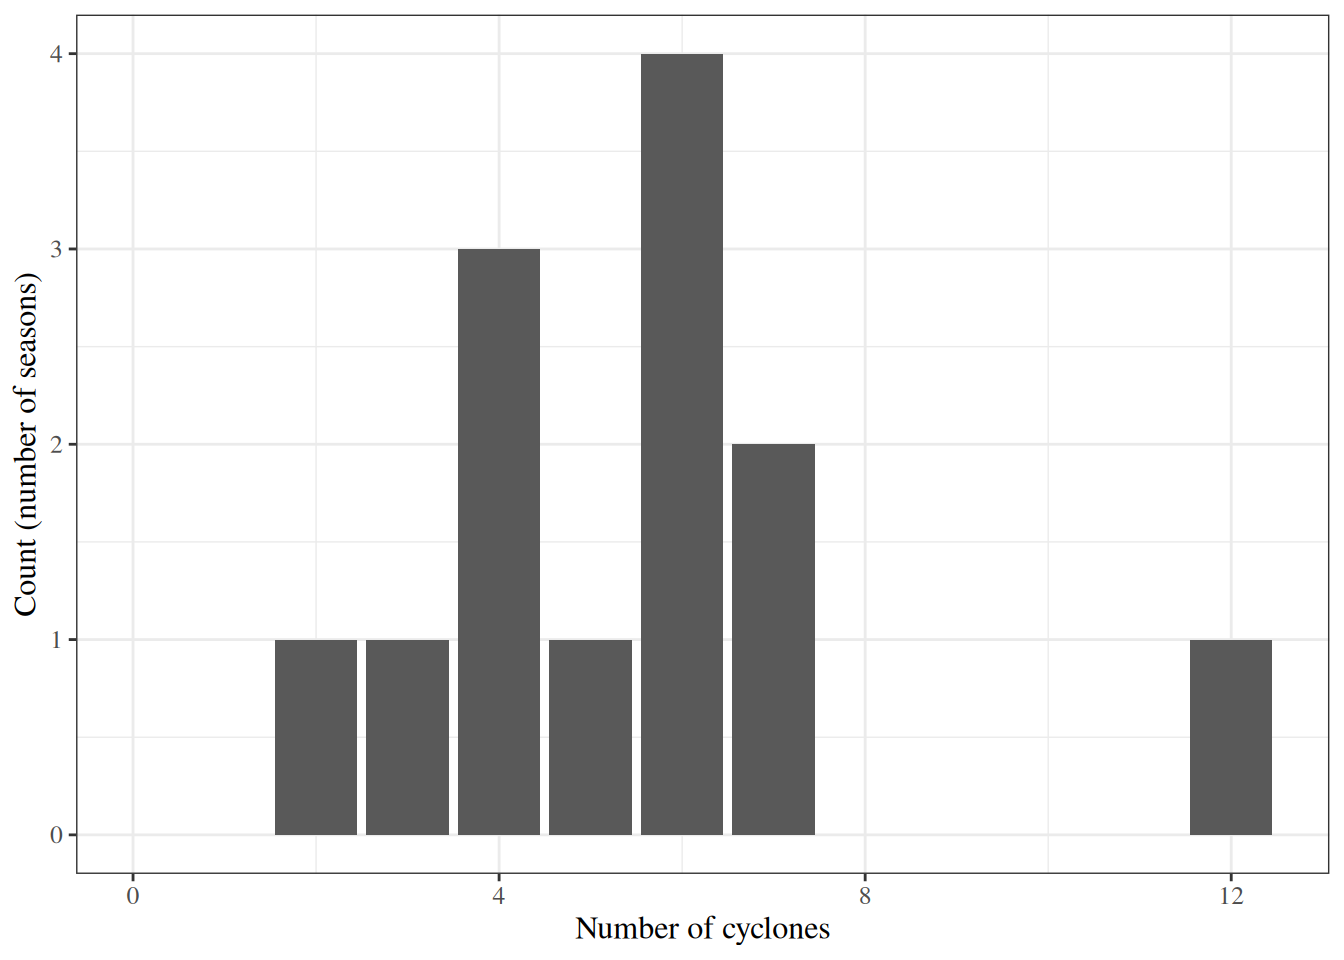
Table 3 provides summary statistics.
[Code]
cyclones data
| seasons | total | mean | variance |
|---|---|---|---|
| 13 | 72 | 5.54 | 6.1 |
2.0.3 Model
We want to estimate \(\Pr(X = x)\); that is, \(\Pr(X = x)\) is our estimand.
We could estimate \(\Pr(X = x)\) for each value of \(x\) in \(0, 1, 2, \ldots\) separately (“nonparametrically”), using the fraction of our data with \(X_i= x\); but then we would be estimating an infinite set of parameters from 13 observations, and each estimate would be imprecise. A parametric model, with a few parameters, will probably do better.
Exercise 19 (Choosing a distribution family) What parametric family of probability distributions might we use to model this empirical distribution?
Solution 19. The Poisson family. The data are counts, which can take any non-negative integer value. The binomial family also models counts, but a binomial count has an upper limit (its number of trials), and there is no natural upper limit on the number of cyclones in a season.
Exercise 20 (The Poisson probability mass function) Write down the Poisson distribution’s probability mass function.
Solution 20. \[\Pr(X = x) = \frac{{\lambda}^{x} e^{-{\lambda}}}{x!}, \quad x \in \mathopen{}\left\{0, 1, 2, \ldots\right\}\mathclose{} \tag{15}\]
2.0.4 Estimating the model parameters using maximum likelihood
We can estimate the parameter \({\lambda}\) using maximum likelihood estimation.
Exercise 21 (Likelihood of one observation) Write down the likelihood of a single observation \(x\), according to the Poisson model.
Solution 21. \[ \begin{aligned} \mathcal{L}({\lambda}; x) &\stackrel{\text{def}}{=}\Pr(X = x) && \text{(definition of likelihood)}\\ &= \frac{{\lambda}^x e^{-{\lambda}}}{x!} && \text{(Poisson PMF)} \end{aligned} \]
Exercise 22 (Model parameters) Write down the vector of parameters in the model.
Solution 22. There is only one parameter, \({\lambda}\):
\[\theta= ({\lambda})\]
Exercise 23 (Mean and variance) Write down the population mean and variance of a single observation from the model, as functions of the parameters.
Solution 23.
- Population mean: \({\mathbb{E}\mathopen{}\left[X\right]\mathclose{}} = {\lambda}\).
- Population variance: \({\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}} = {\lambda}\).
The sample mean and variance in Table 3 are of similar size, as the model implies.
Exercise 24 (Likelihood of the dataset) Write down the likelihood of the full dataset.
Solution 24. \[ \begin{aligned} \mathcal{L}({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &\stackrel{\text{def}}{=}\Pr(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{X}}\vphantom{X}}= \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) && \text{(definition of likelihood)}\\ &= \Pr(X_1 = x_1, X_2 = x_2, \ldots, X_{13} = x_{13}) && \text{(write out the vector)}\\ &= \prod_{i=1}^{13} \Pr(X_i= x_i) && \text{(independence)}\\ &= \prod_{i=1}^{13} \frac{{\lambda}^{x_i} e^{-{\lambda}}}{x_i!} && \text{(Poisson PMF)} \end{aligned} \]
Exercise 25 (Graphing the likelihood) Graph the likelihood as a function of \({\lambda}\).
Solution 25.
[Code]
# `cyclones` is defined earlier on the page:
# nolint next: object_usage_linter.
lik <- function(lambda, y = cyclones$number, n = length(y)) {
  lambda^sum(y) * exp(-n * lambda) / prod(factorial(y))
}

lik_plot <-
  ggplot2::ggplot() +
  ggplot2::geom_function(fun = lik, n = 1001) +
  ggplot2::xlim(min(cyclones$number), max(cyclones$number)) +
  ggplot2::ylab("likelihood") +
  ggplot2::xlab("lambda")

print(lik_plot)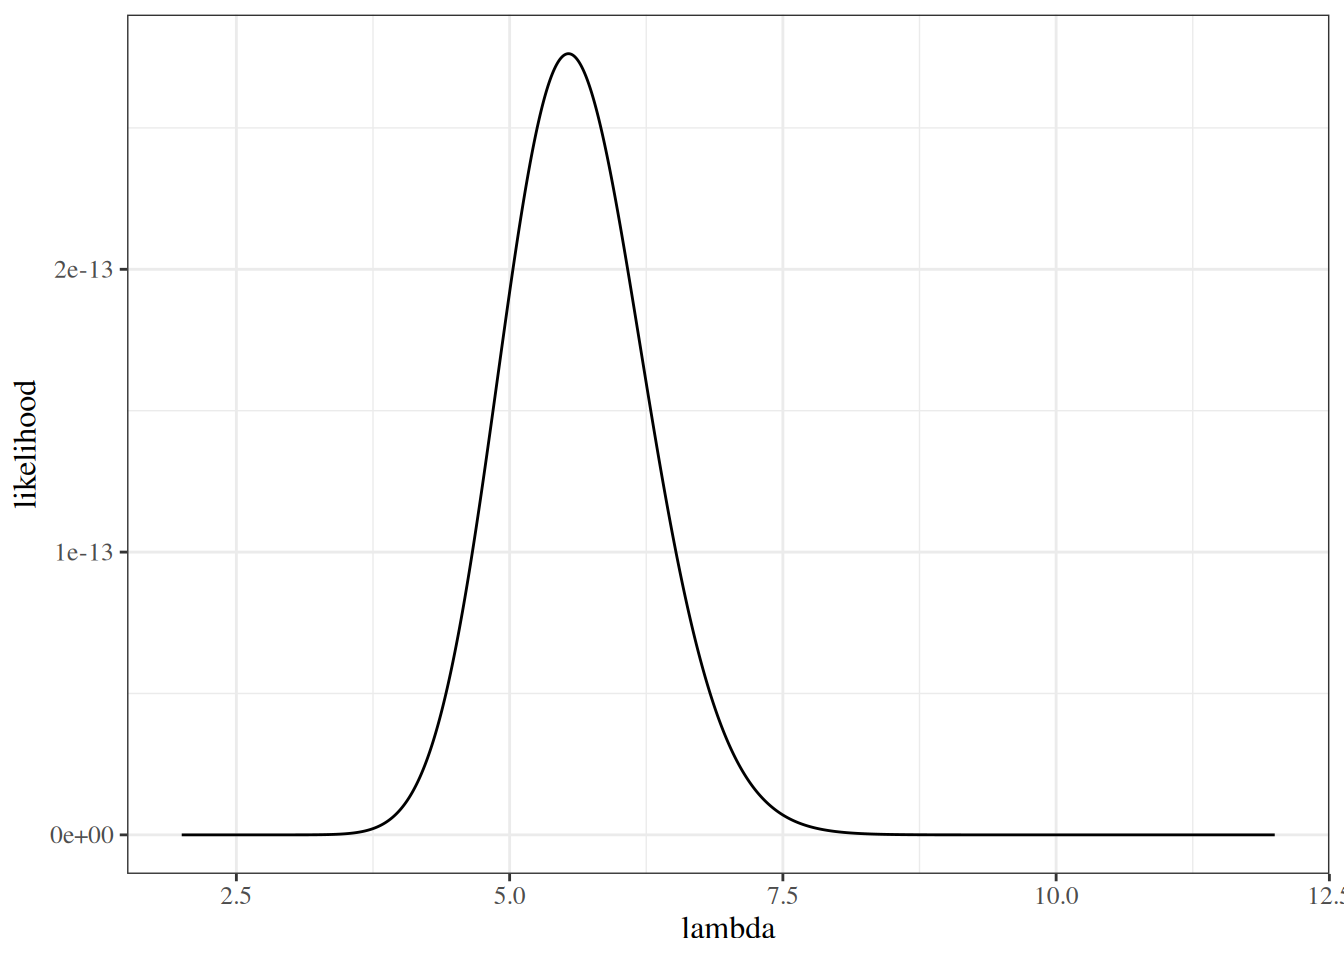
Exercise 26 (Log-likelihood of the dataset) Write down the log-likelihood of the full dataset.
Solution 26. \[ \begin{aligned} \ell({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &\stackrel{\text{def}}{=}{\operatorname{log}\mathopen{}\left\{\mathcal{L}({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\right\}\mathclose{}} && \text{(definition of log-likelihood)}\\ &= {\operatorname{log}\mathopen{}\left\{\prod_{i=1}^n\frac{{\lambda}^{x_i} e^{-{\lambda}}}{x_i!}\right\}\mathclose{}} && \text{(likelihood of the dataset)}\\ &= \sum_{i=1}^n{\operatorname{log}\mathopen{}\left\{\frac{{\lambda}^{x_i} e^{-{\lambda}}}{x_i!}\right\}\mathclose{}} && \text{(log of a product)}\\ &= \sum_{i=1}^n\mathopen{}\left({\operatorname{log}\mathopen{}\left\{{\lambda}^{x_i}\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{e^{-{\lambda}}\right\}\mathclose{}} - {\operatorname{log}\mathopen{}\left\{x_i!\right\}\mathclose{}}\right)\mathclose{} && \text{(log of a product and of a quotient)}\\ &= \sum_{i=1}^n\mathopen{}\left(x_i{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}} - {\lambda}- {\operatorname{log}\mathopen{}\left\{x_i!\right\}\mathclose{}}\right)\mathclose{} && \text{(log of a power; $\log e^{a} = a$)}\\ &= \mathopen{}\left(\sum_{i=1}^nx_i\right)\mathclose{} {\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}} - n{\lambda}- \sum_{i=1}^n{\operatorname{log}\mathopen{}\left\{x_i!\right\}\mathclose{}} && \text{(distribute the sum over the terms)} \end{aligned} \]
Exercise 27 (Graphing the log-likelihood) Graph the log-likelihood as a function of \({\lambda}\).
Solution 27.
[Code]
# `cyclones` is defined earlier on the page:
# nolint next: object_usage_linter.
loglik <- function(lambda, y = cyclones$number, n = length(y)) {
  sum(y) * log(lambda) - n * lambda - sum(lfactorial(y))
}

ll_plot <- ggplot2::ggplot() +
  ggplot2::geom_function(fun = loglik, n = 1001) +
  ggplot2::xlim(min(cyclones$number), max(cyclones$number)) +
  ggplot2::ylab("log-likelihood") +
  ggplot2::xlab("lambda")
ll_plot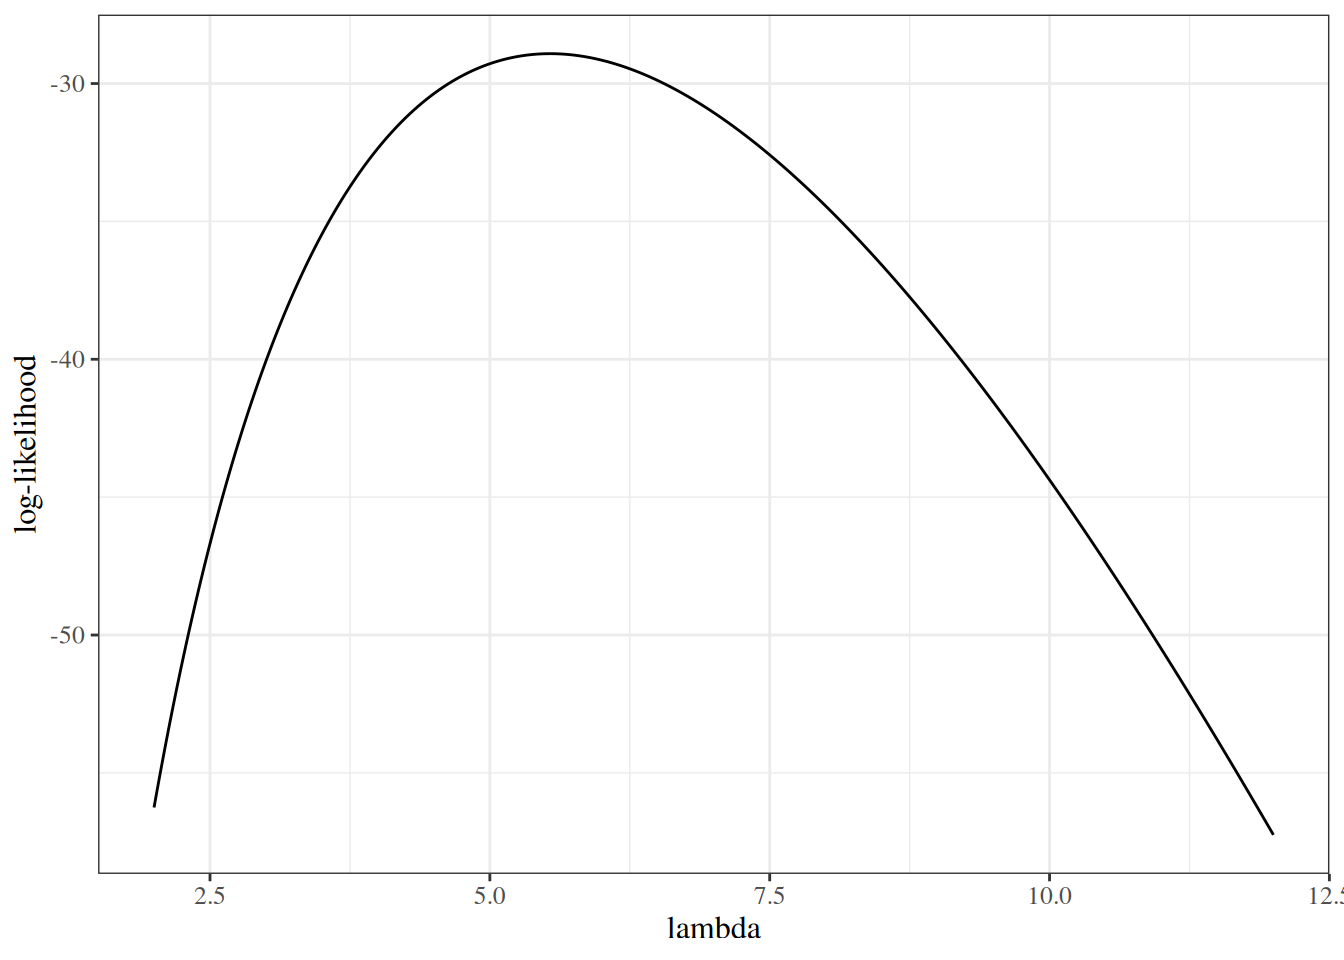
The score function
Exercise 28 (Score function of the dataset) Derive the score function for the dataset.
Solution 28. The score function is the first derivative of the log-likelihood from Exercise 26:
\[ \begin{aligned} \ell'({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &\stackrel{\text{def}}{=}\frac{\partial}{\partial {\lambda}}\mathopen{}\left(\mathopen{}\left(\sum_{i=1}^nx_i\right)\mathclose{}{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}} - n{\lambda}- \sum_{i=1}^n{\operatorname{log}\mathopen{}\left\{x_i!\right\}\mathclose{}}\right)\mathclose{} && \text{(definition of the score)}\\ &= \mathopen{}\left(\sum_{i=1}^nx_i\right)\mathclose{}\frac{\partial}{\partial {\lambda}}{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}} - n\frac{\partial}{\partial {\lambda}}{\lambda}- \frac{\partial}{\partial {\lambda}}\sum_{i=1}^n{\operatorname{log}\mathopen{}\left\{x_i!\right\}\mathclose{}} && \text{(linearity of differentiation)}\\ &= \mathopen{}\left(\sum_{i=1}^nx_i\right)\mathclose{}\frac{1}{{\lambda}} - n - 0 && \text{(derivatives of $\log {\lambda}$, ${\lambda}$, and a constant)}\\ &= \frac{n \bar x}{{\lambda}} - n && \text{($\textstyle\sum_{i=1}^nx_i= n \bar x$)} \end{aligned} \]
For the cyclone data, \(n = 13\) and \(n \bar x = 72\), so \(\ell'({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = 72/{\lambda}- 13\).
Exercise 29 (Graphing the score function) Graph the score function.
Solution 29.
[Code]
# `cyclones` is defined earlier on the page:
# nolint next: object_usage_linter.
score <- function(lambda, y = cyclones$number, n = length(y)) {
  (sum(y) / lambda) - n
}

ggplot2::ggplot() +
  ggplot2::geom_function(fun = score, n = 1001) +
  ggplot2::xlim(min(cyclones$number), max(cyclones$number)) +
  ggplot2::ylab("l'(lambda)") +
  ggplot2::xlab("lambda") +
  ggplot2::geom_hline(yintercept = 0, col = "red")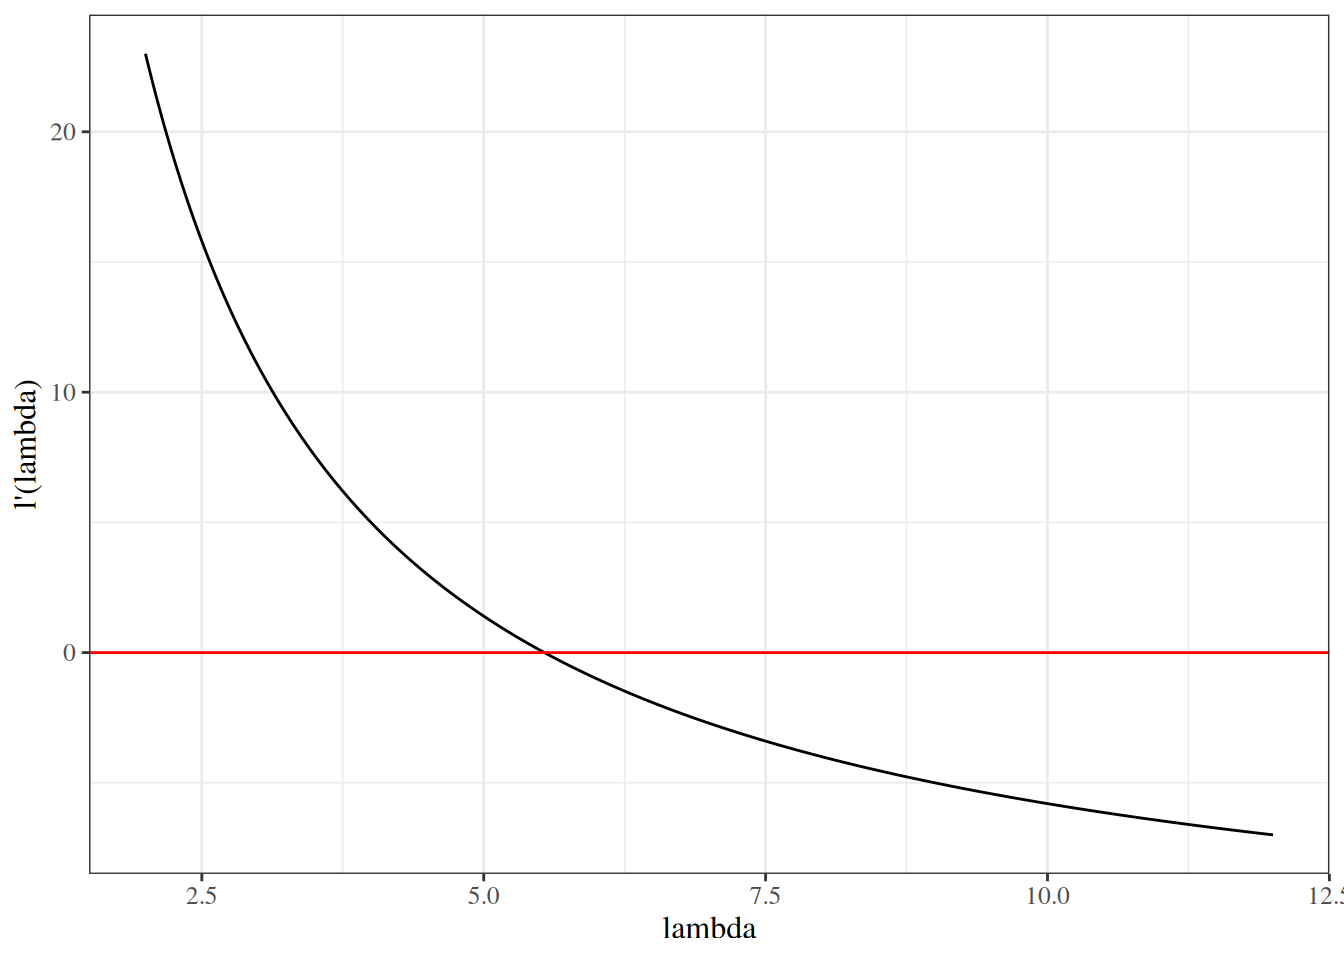
The Hessian
Exercise 30 (Hessian) Derive the Hessian.
Solution 30. With one parameter, the Hessian is the second derivative of the log-likelihood, which is the derivative of the score from Exercise 28:
\[ \begin{aligned} \ell''({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= \frac{\partial}{\partial {\lambda}}\mathopen{}\left(\frac{n \bar x}{{\lambda}} - n\right)\mathclose{} && \text{(differentiate the score)}\\ &= n \bar x \frac{\partial}{\partial {\lambda}}\frac{1}{{\lambda}} - \frac{\partial}{\partial {\lambda}} n && \text{(linearity of differentiation)}\\ &= -\frac{n \bar x}{{\lambda}^2} && \text{($\tfrac{d}{d{\lambda}}{\lambda}^{-1} = -{\lambda}^{-2}$; $n$ is constant)} \end{aligned} \]
For the cyclone data, \(\ell''({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = -72/{\lambda}^2\).
Exercise 31 (Graphing the Hessian) Graph the Hessian.
Solution 31.
[Code]
# `cyclones` is defined earlier on the page:
# nolint next: object_usage_linter.
hessian <- function(lambda, y = cyclones$number, n = length(y)) {
  -sum(y) / (lambda^2)
}

ggplot2::ggplot() +
  ggplot2::geom_function(fun = hessian, n = 1001) +
  ggplot2::xlim(min(cyclones$number), max(cyclones$number)) +
  ggplot2::ylab("l''(lambda)") +
  ggplot2::xlab("lambda") +
  ggplot2::geom_hline(yintercept = 0, col = "red")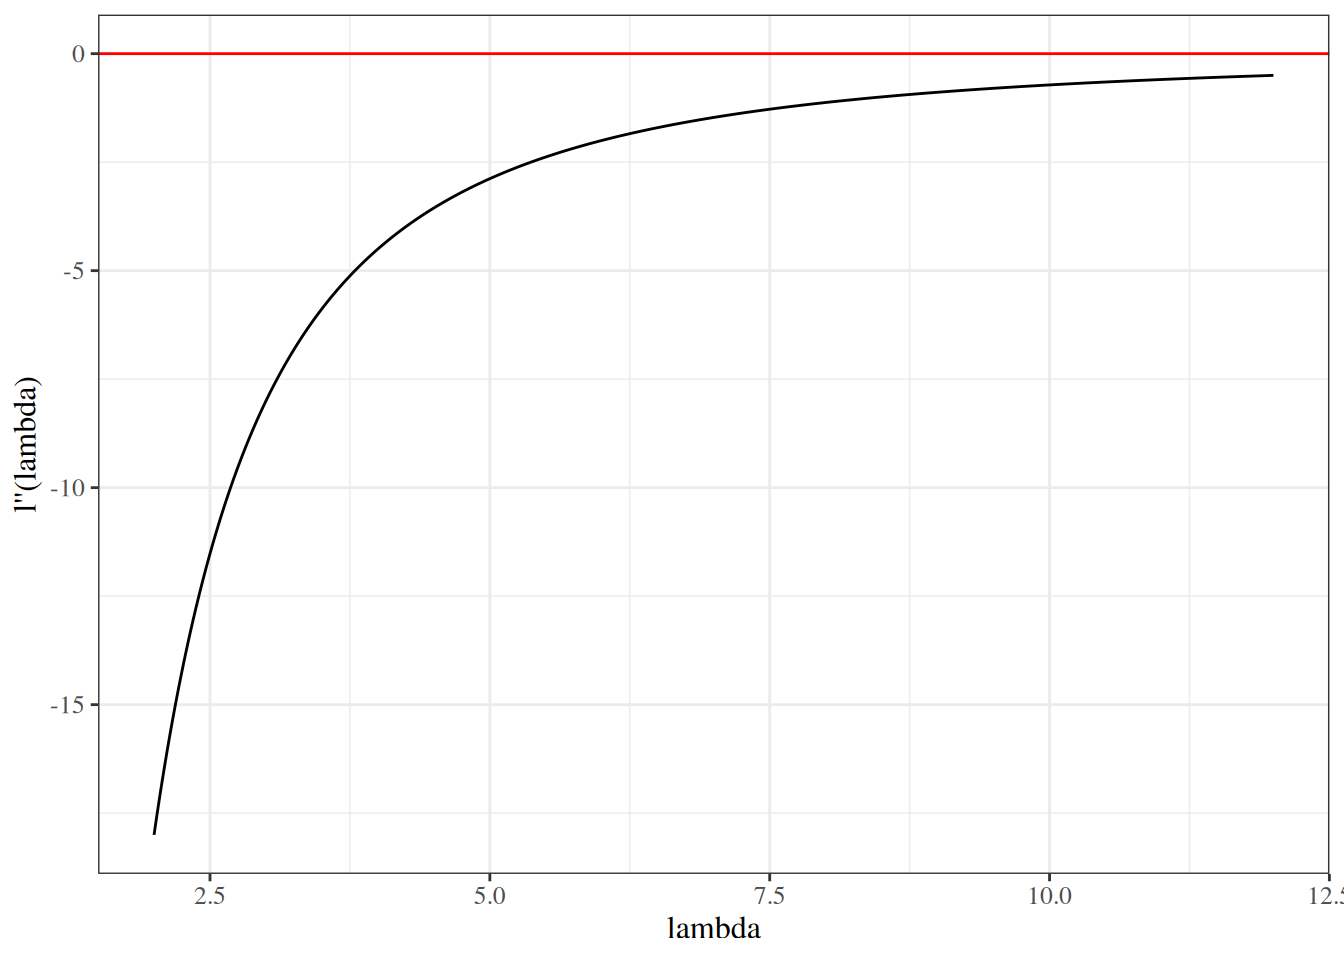
Exercise 32 (Score equation) State the score equation.
Solution 32. \[\ell'({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = 0\]
2.0.5 Finding the MLE analytically
In this example, we can find the MLE of \({\lambda}\) by solving the score equation algebraically.
Exercise 33 (Solving the score equation) Solve the score equation from Exercise 32 for \({\lambda}\), using the score from Exercise 28.
Solution 33. \[ \begin{aligned} 0 &= \frac{n \bar x}{{\lambda}} - n && \text{(score of the dataset)}\\ n &= \frac{n \bar x}{{\lambda}} && \text{(add $n$ to both sides)}\\ n{\lambda}&= n \bar x && \text{(multiply both sides by ${\lambda}> 0$)}\\ {\lambda}&= \bar x && \text{(divide both sides by $n$)} \end{aligned} \]
Call this solution of the score equation \(\tilde {\lambda}\) for now:
\[\tilde {\lambda}\stackrel{\text{def}}{=}\bar x\]
Exercise 34 (Checking the second derivative) Confirm that the Hessian \(\ell''({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\) is negative when evaluated at \(\tilde {\lambda}\), using Exercise 30.
Solution 34. \[ \begin{aligned} \ell''(\tilde{\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= -\frac{n \bar x}{\tilde{\lambda}^2} && \text{(Hessian of the log-likelihood)}\\ &= -\frac{n \bar x}{\bar x^2} && \text{(substitute $\tilde{\lambda}= \bar x$)}\\ &= -\frac{n}{\bar x} && \text{(cancel one factor of $\bar x$)}\\ &< 0 && \text{($n > 0$ and $\bar x > 0$)} \end{aligned} \]
Exercise 35 (Identifying the MLE) Draw conclusions about the MLE of \({\lambda}\).
Solution 35. Since \(\ell''(\tilde {\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) < 0\), \(\tilde {\lambda}\) is a local maximizer of the log-likelihood. Moreover, \(\ell''({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = -n\bar x/{\lambda}^2 < 0\) for every \({\lambda}> 0\), so the log-likelihood is strictly concave, and a local maximizer of a strictly concave function is its unique global maximizer. So \(\tilde {\lambda}\) maximizes \(\ell\), and therefore \(\mathcal{L}\):
\[ \begin{aligned} \hat{{\lambda}}_{\text{ML}} &= \bar x\\ &= 5.538 \end{aligned} \]
Exercise 36 (Graphing the MLE) Graph the log-likelihood with the MLE superimposed.
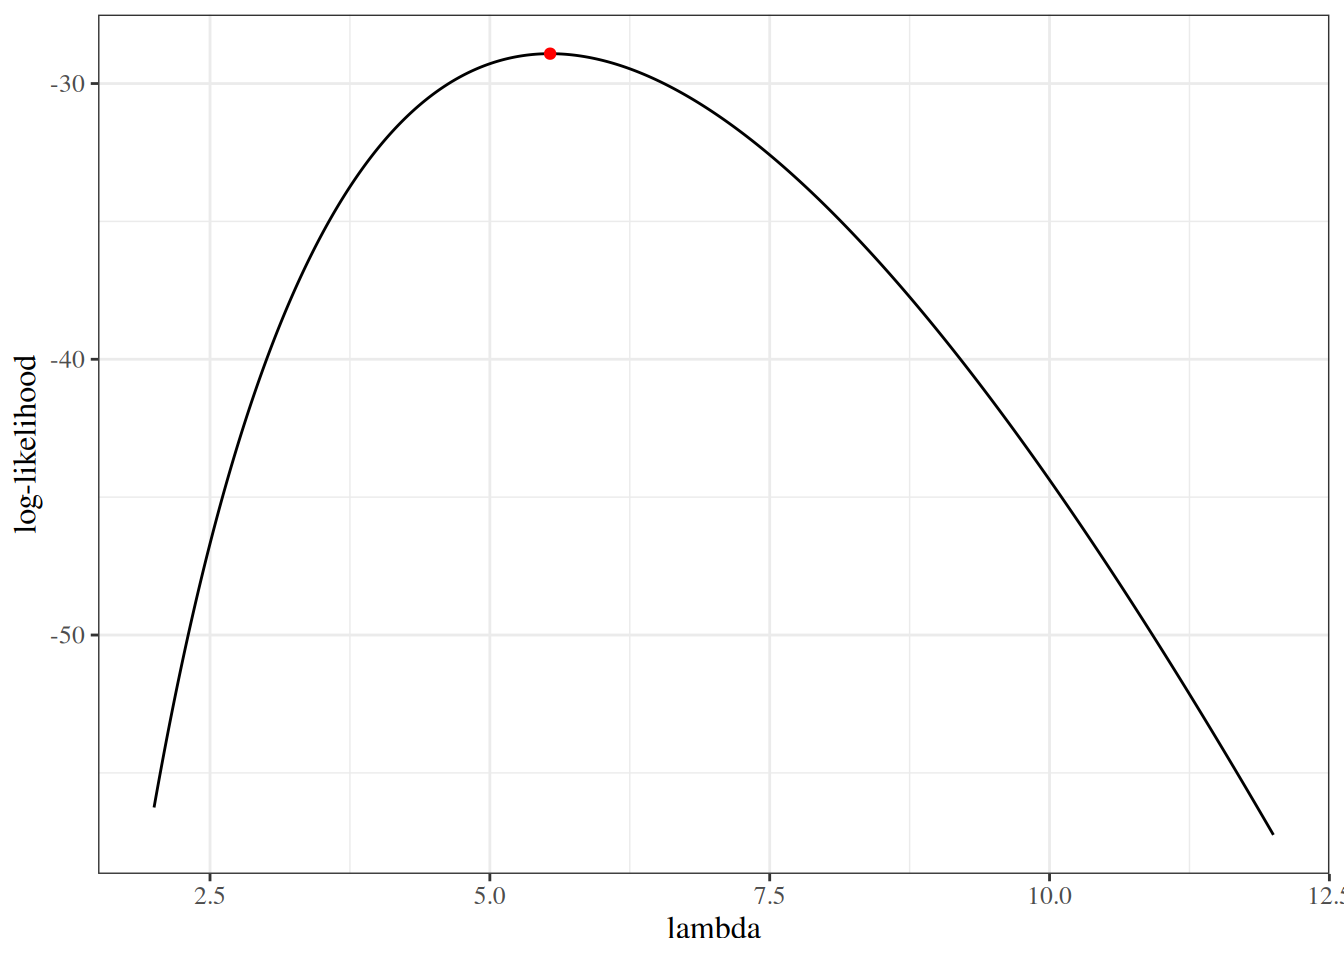
Figure 8 graphs the observed information, \(I({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = -\ell''({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\).
[Code]
obs_inf <- function(...) -hessian(...) # nolint: object_usage_linter.
ggplot2::ggplot() +
  ggplot2::geom_function(fun = obs_inf, n = 1001) +
  ggplot2::xlim(min(cyclones$number), max(cyclones$number)) +
  ggplot2::ylab("I(lambda)") +
  ggplot2::xlab("lambda") +
  ggplot2::geom_hline(yintercept = 0, col = "red")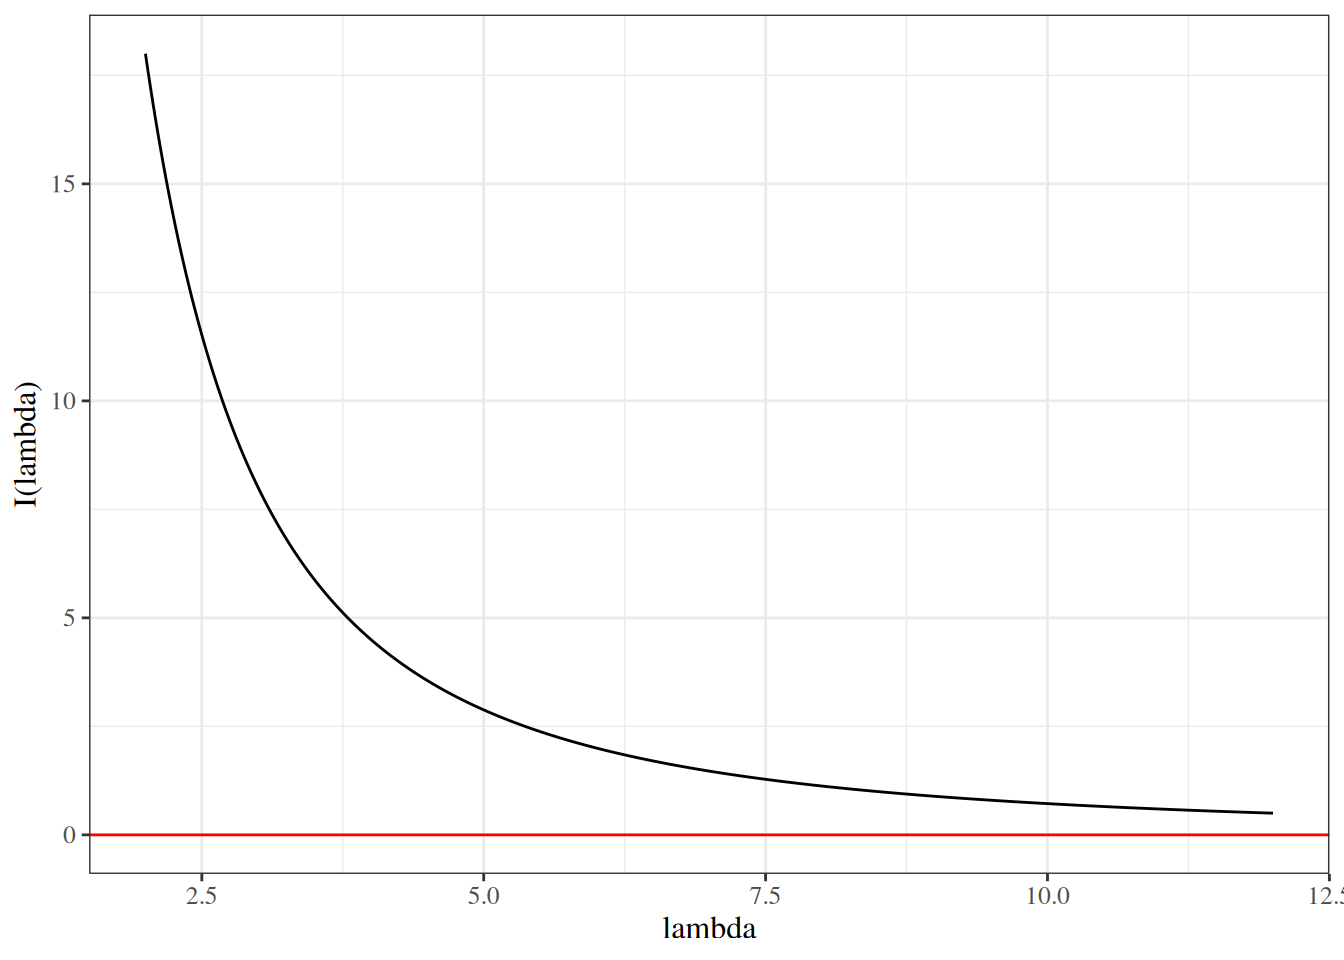
2.0.6 Finding the MLE using the Newton-Raphson algorithm
Iterative maximization
When we cannot solve the score equation \(\ell'(\theta) = 0\) algebraically, we can search for its solution numerically [1, Ch. 4].
Definition 18 (Newton-Raphson algorithm) The Newton-Raphson algorithm for solving the score equation \(\ell'(\theta) = 0\) starts from an initial guess \({\widehat{\theta}}^*\) and repeats the update
\[ \begin{aligned} {\widehat{\theta}}^* &\leftarrow {\widehat{\theta}}^* - {\mathopen{}\left({\ell''\mathopen{}\left(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}; {\widehat{\theta}}^*\right)\mathclose{}}\right)\mathclose{}}^{-1} {\ell'\mathopen{}\left(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}; {\widehat{\theta}}^*\right)\mathclose{}}\\ &= {\widehat{\theta}}^* + {\mathopen{}\left({I\mathopen{}\left(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}; {\widehat{\theta}}^*\right)\mathclose{}}\right)\mathclose{}}^{-1} {\ell'\mathopen{}\left(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}; {\widehat{\theta}}^*\right)\mathclose{}} \end{aligned} \]
until the estimate stops changing.
The second line of the update uses \(I= -\ell''\) (observed information).
The update comes from approximating the score function near \({\widehat{\theta}}^*\) by its first-order Taylor polynomial:
\[ \begin{aligned} \ell'(\theta) &\approx \ell'^*(\theta)\\ &\stackrel{\text{def}}{=}\ell'({\widehat{\theta}}^*) + \ell''({\widehat{\theta}}^*)(\theta- {\widehat{\theta}}^*) \end{aligned} \]
The approximate score function \(\ell'^*(\theta)\) is linear in \(\theta\), so the approximate score equation \(\ell'^*(\theta) = 0\) is easy to solve:
\[ \begin{aligned} 0 &= \ell'({\widehat{\theta}}^*) + \ell''({\widehat{\theta}}^*)(\theta- {\widehat{\theta}}^*) && \text{(set $\ell'^*(\theta) = 0$)}\\ -\ell'({\widehat{\theta}}^*) &= \ell''({\widehat{\theta}}^*)(\theta- {\widehat{\theta}}^*) && \text{(subtract $\ell'({\widehat{\theta}}^*)$)}\\ -{\mathopen{}\left(\ell''({\widehat{\theta}}^*)\right)\mathclose{}}^{-1}\ell'({\widehat{\theta}}^*) &= \theta- {\widehat{\theta}}^* && \text{(multiply by ${\mathopen{}\left(\ell''({\widehat{\theta}}^*)\right)\mathclose{}}^{-1}$ on the left)}\\ \theta&= {\widehat{\theta}}^* - {\mathopen{}\left(\ell''({\widehat{\theta}}^*)\right)\mathclose{}}^{-1}\ell'({\widehat{\theta}}^*) && \text{(add ${\widehat{\theta}}^*$)} \end{aligned} \]
and the solution becomes the next guess.
Definition 19 (Fisher scoring (method of scoring)) Fisher scoring (also called the method of scoring) is the Newton-Raphson algorithm with the observed information \(I(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}; {\widehat{\theta}}^*)\) in the update replaced by the expected information \(\mathcal{I}({\widehat{\theta}}^*)\):
\[ {\widehat{\theta}}^* \leftarrow {\widehat{\theta}}^* + {\mathopen{}\left({\mathcal{I}\mathopen{}\left({\widehat{\theta}}^*\right)\mathclose{}}\right)\mathclose{}}^{-1} {\ell'\mathopen{}\left(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}; {\widehat{\theta}}^*\right)\mathclose{}} \]
The expected information is sometimes simpler to compute than the observed information.
Example 12 (Fisher scoring for Poisson data) For \(X_1, \ldots, X_n \ \sim_{\operatorname{iid}}\ \operatorname{Pois}({\lambda})\), the score is \(\ell'({\lambda}) = n\bar x/{\lambda}- n\) and the expected information is \(\mathcal{I}({\lambda}) = n/{\lambda}\) (Example 4), so one Fisher scoring step from any \({\widehat{\lambda}}^*> 0\) gives:
\[ \begin{aligned} {\widehat{\lambda}}^*+ {\mathopen{}\left(\mathcal{I}({\widehat{\lambda}}^*)\right)\mathclose{}}^{-1} \ell'({\widehat{\lambda}}^*) &= {\widehat{\lambda}}^*+ \frac{{\widehat{\lambda}}^*}{n}\mathopen{}\left(\frac{n\bar x}{{\widehat{\lambda}}^*} - n\right)\mathclose{} && \text{(substitute $\mathcal{I}$ and $\ell'$)}\\ &= {\widehat{\lambda}}^*+ \bar x - {\widehat{\lambda}}^* && \text{(distribute ${\widehat{\lambda}}^*/n$)}\\ &= \bar x && \text{(cancel ${\widehat{\lambda}}^*$)} \end{aligned} \]
So Fisher scoring reaches the MLE \(\bar x\) in one step, while Newton-Raphson needs several (Table 4).
Definition 20 (Empirical information matrix) For mutually independent observations, the empirical information matrix is [2]:
\[ I_e(\theta; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) \stackrel{\text{def}}{=} \sum_{i=1}^n\ell'_i{\ell'_i}^{\top} - \frac{1}{n} \ell'{\ell'}^{\top} \]
where \(\ell'_i\) is the score of the \(i\)th observation’s log-likelihood, and \(\ell'= \sum_{i=1}^n\ell'_i\).
For \(\operatorname{iid}\) data, \(\frac{1}{n}I_e(\theta; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\) is the sample covariance matrix (with divisor \(n\)) of the observations’ scores, so it estimates the covariance matrix of one observation’s score, \(\mathcal{I}(\theta)/n\) (Theorem 13). The empirical information needs only first derivatives, so it can be easier to compute than the observed information, and it can replace the observed information in the Newton-Raphson update.
Applying Newton-Raphson to the cyclone data
Example 13 (Finding the MLE using the Newton-Raphson algorithm) We found the MLE \(\hat{{\lambda}}= {\bar{x}}\) by solving the score equation \(\ell'({\lambda}) = 0\) algebraically (Exercise 33). If we could not have solved it, we could instead start from an initial guess such as \({\widehat{\lambda}}^*= 3\) and apply the Newton-Raphson algorithm.
From Exercise 28 and Exercise 30, the score function and Hessian are:
\[ \begin{aligned} \ell'({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= \frac{72}{{\lambda}} - 13\\ \ell''({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= -\frac{72}{{\lambda}^2} \end{aligned} \]
So the first-order Taylor approximation of the score function around \({\widehat{\lambda}}^*\) is:
\[ \begin{aligned} \ell'({\lambda}) &\approx \ell'^*({\lambda})\\ &\stackrel{\text{def}}{=}\ell'({\widehat{\lambda}}^*) + \ell''({\widehat{\lambda}}^*)({\lambda}- {\widehat{\lambda}}^*)\\ &= \mathopen{}\left(\frac{72}{{\widehat{\lambda}}^*} - 13\right)\mathclose{} + \mathopen{}\left(-\frac{72}{{\mathopen{}\left({\widehat{\lambda}}^*\right)\mathclose{}}^{2}}\right)\mathclose{} ({\lambda}- {\widehat{\lambda}}^*) \end{aligned} \]
Figure 9 compares the score function and the approximate score function at \({\widehat{\lambda}}^*= 3\).
[Code]
# score(), hessian() and loglik() are defined earlier on the page
# nolint start: object_usage_linter.
approx_score <- function(lambda, lhat, ...) {
  score(lambda = lhat, ...) +
    hessian(lambda = lhat, ...) * (lambda - lhat)
}
# nolint end

point_size <- 5

plot1 <- ggplot2::ggplot() +
  ggplot2::geom_function(
    fun = score,
    ggplot2::aes(col = "score function"),
    n = 1001
  ) +
  ggplot2::geom_function(
    fun = approx_score,
    ggplot2::aes(col = "approximate score function"),
    n = 1001,
    args = list(lhat = cur_lambda_est)
  ) +
  ggplot2::geom_point(
    size = point_size,
    ggplot2::aes(
      x = cur_lambda_est, y = score(lambda = cur_lambda_est),
      col = "current estimate"
    )
  ) +
  ggplot2::geom_point(
    size = point_size,
    ggplot2::aes(x = xbar, y = 0, col = "MLE")
  ) +
  ggplot2::xlim(min(cyclones$number), max(cyclones$number)) +
  ggplot2::ylab("l'(lambda)") +
  ggplot2::xlab("lambda") +
  ggplot2::geom_hline(yintercept = 0)

print(plot1)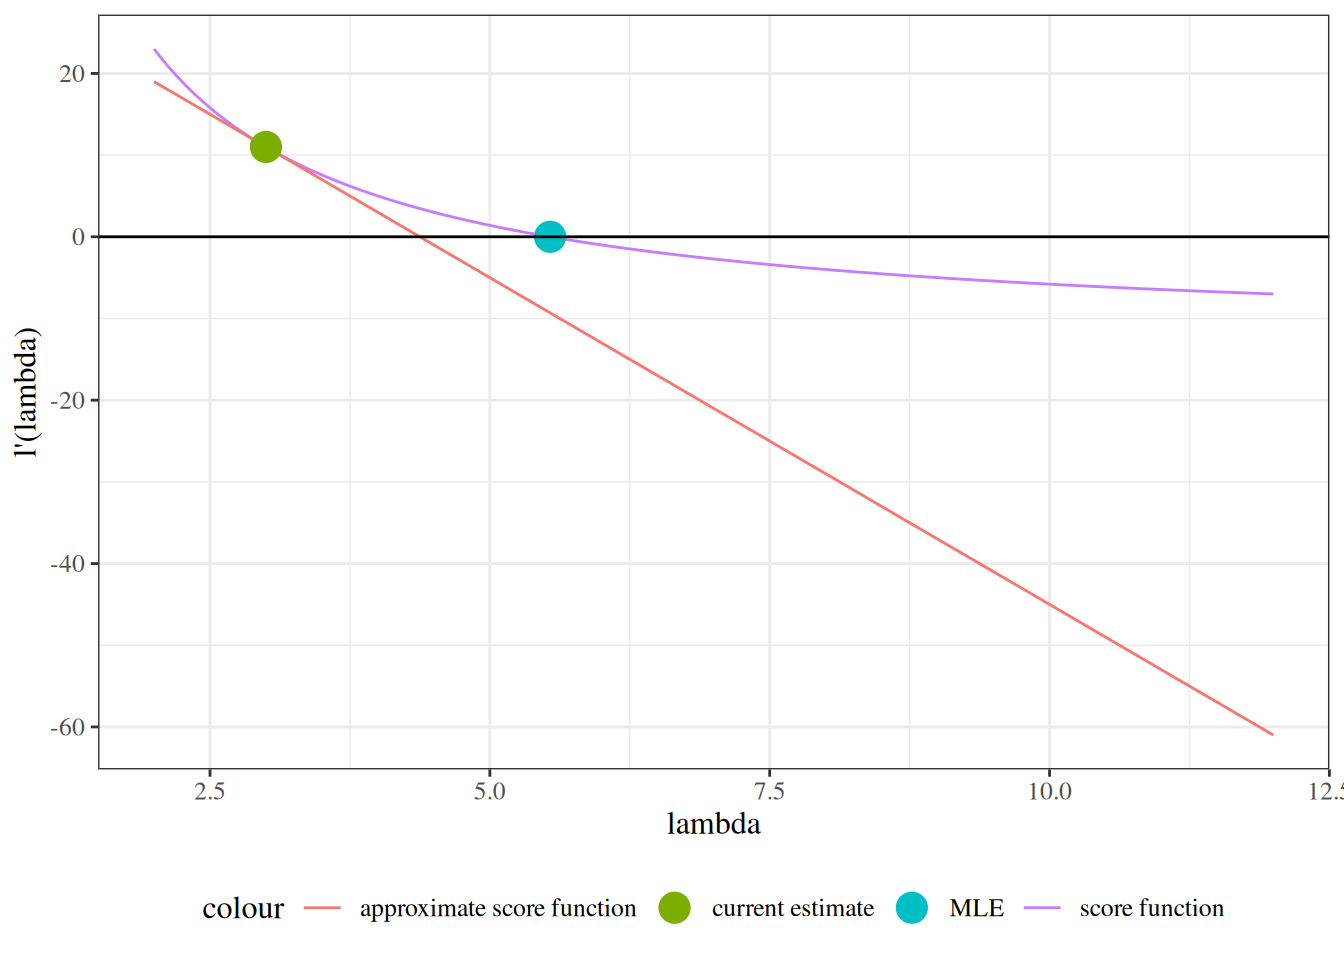
Approximating the score function by a linear function is equivalent to approximating the log-likelihood by a second-order Taylor polynomial (Figure 10):
\[ \ell^*({\lambda}) \stackrel{\text{def}}{=} \ell({\widehat{\lambda}}^*) + ({\lambda}- {\widehat{\lambda}}^*) \ell'({\widehat{\lambda}}^*) + \frac{1}{2}\ell''({\widehat{\lambda}}^*)({\lambda}- {\widehat{\lambda}}^*)^2 \]
[Code]
# nolint start: object_usage_linter.
approx_loglik <- function(lambda, lhat, ...) {
  loglik(lambda = lhat, ...) +
    score(lambda = lhat, ...) * (lambda - lhat) +
    1 / 2 * hessian(lambda = lhat, ...) * (lambda - lhat)^2
}
# nolint end

plot_loglik <- ggplot2::ggplot() +
  ggplot2::geom_function(
    fun = loglik,
    ggplot2::aes(col = "log-likelihood"),
    n = 1001
  ) +
  ggplot2::geom_function(
    fun = approx_loglik,
    ggplot2::aes(col = "approximate log-likelihood"),
    n = 1001,
    args = list(lhat = cur_lambda_est)
  ) +
  ggplot2::geom_point(
    size = point_size,
    ggplot2::aes(
      x = cur_lambda_est, y = loglik(lambda = cur_lambda_est),
      col = "current estimate"
    )
  ) +
  ggplot2::geom_point(
    size = point_size,
    ggplot2::aes(x = xbar, y = loglik(xbar), col = "MLE")
  ) +
  ggplot2::xlim(min(cyclones$number) - 1, max(cyclones$number)) +
  ggplot2::ylab("log-likelihood") +
  ggplot2::xlab("lambda")

print(plot_loglik)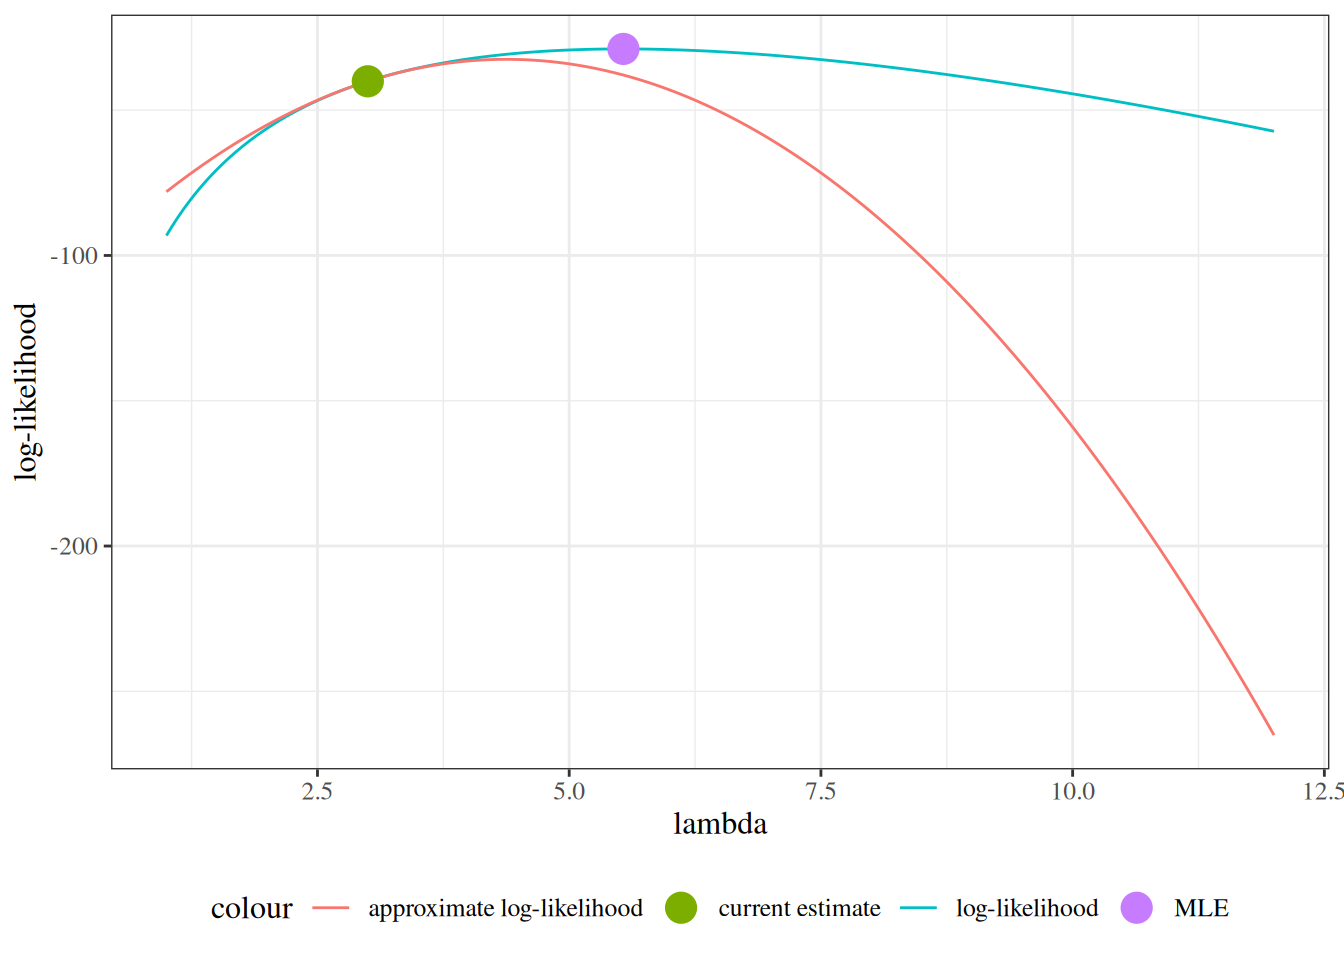
Solving the approximate score equation \(\ell'^*({\lambda}) = 0\) gives the next estimate:
\[ \begin{aligned} {\lambda} &= {\widehat{\lambda}}^*- \ell'({\widehat{\lambda}}^*) \cdot{\mathopen{}\left(\ell''({\widehat{\lambda}}^*)\right)\mathclose{}}^{-1}\\ &= 4.375 \end{aligned} \]
[Code]
plot2 <- plot1 +
  ggplot2::geom_point(
    size = point_size,
    ggplot2::aes(x = new_lambda_est, y = 0, col = "new estimate")
  ) +
  ggplot2::geom_segment(
    arrow = grid::arrow(),
    linewidth = 2,
    alpha = .7,
    ggplot2::aes(
      x = cur_lambda_est,
      y = approx_score(lhat = cur_lambda_est, lambda = cur_lambda_est),
      xend = new_lambda_est,
      yend = 0,
      col = "update"
    )
  )
print(plot2)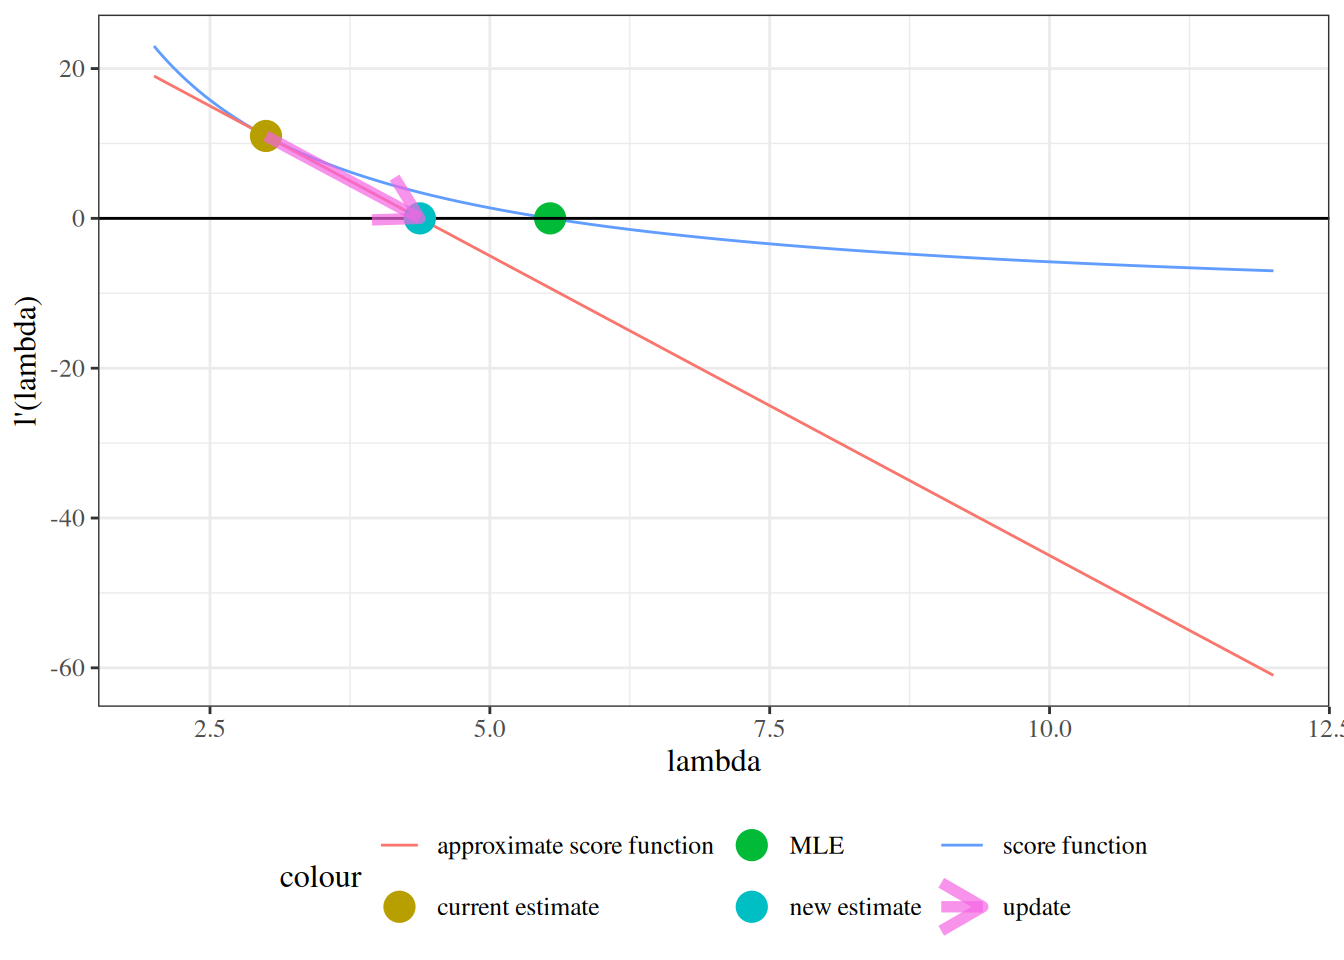
We update \({\widehat{\lambda}}^*\leftarrow 4.375\) and repeat the process (Figure 12).
[Code]
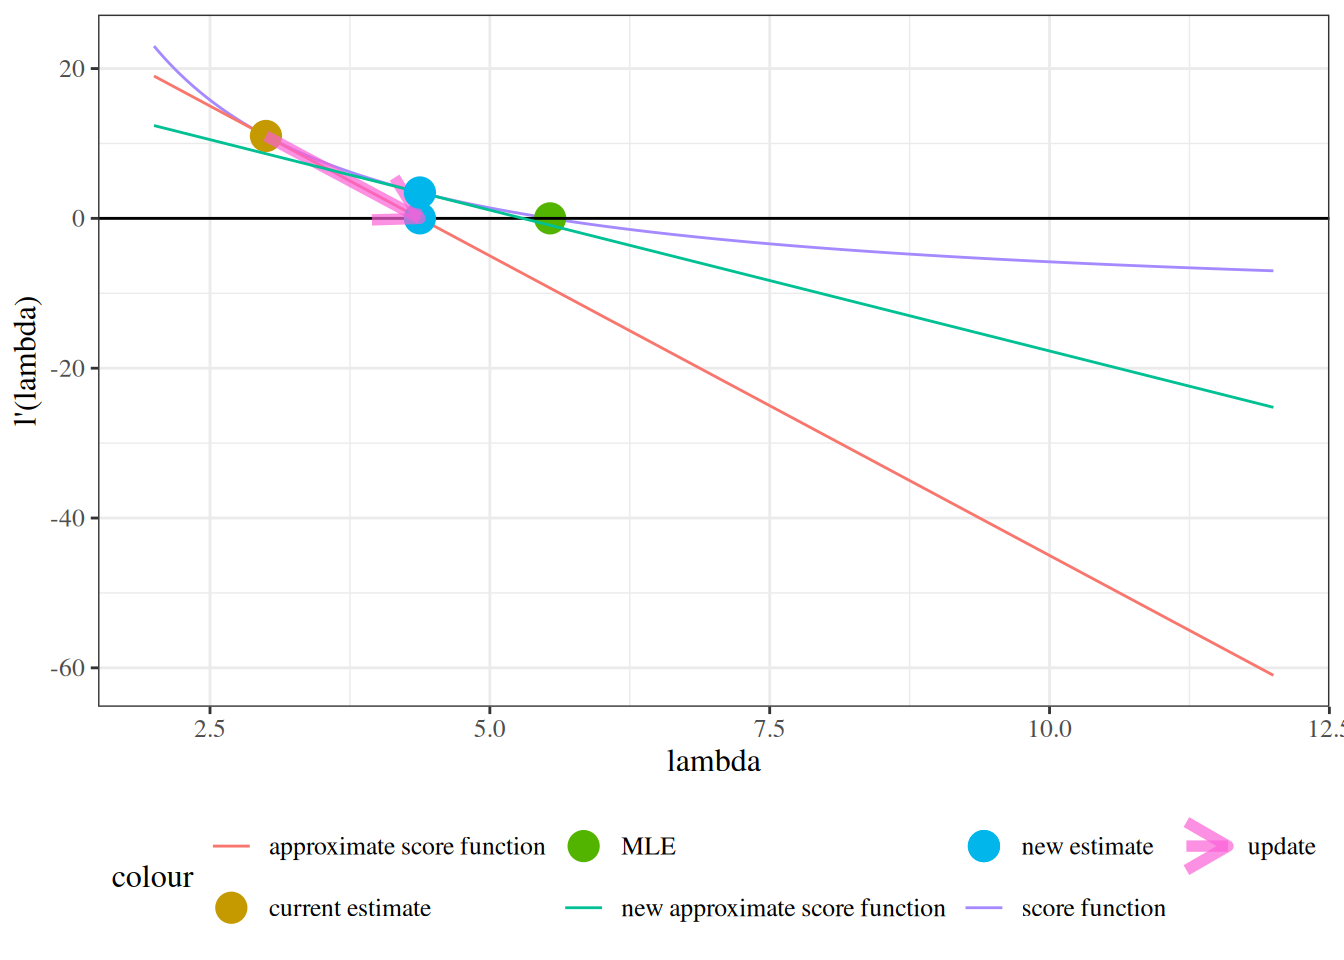
We repeat this process until the log-likelihood stops changing (Table 4).
cur_lambda_est <- 3 # restart from the initial guess
tolerance <- 10^-4
max_iter <- 100
nr_info <- tibble::tibble(
  iteration = 0,
  lambda = cur_lambda_est,
  `log(likelihood)` = loglik(cur_lambda_est),
  score = score(cur_lambda_est),
  hessian = hessian(cur_lambda_est)
)

for (cur_iter in 1:max_iter) {
  new_lambda_est <-
    cur_lambda_est - score(cur_lambda_est) / hessian(cur_lambda_est)

  diff_loglik <- loglik(new_lambda_est) - loglik(cur_lambda_est)

  nr_info <- nr_info |>
    dplyr::bind_rows(
      tibble::tibble(
        iteration = cur_iter,
        lambda = new_lambda_est,
        `log(likelihood)` = loglik(new_lambda_est),
        score = score(new_lambda_est),
        hessian = hessian(new_lambda_est),
        `diff(loglik)` = diff_loglik
      )
    )

  cur_lambda_est <- new_lambda_est

  if (abs(diff_loglik) < tolerance) {
    break
  }
}

nr_info |> knitr::kable(digits = 5)| iteration | lambda | log(likelihood) | score | hessian | diff(loglik) |
|---|---|---|---|---|---|
| 0 | 3.00000 | -40.0610 | 11.00000 | -8.00000 | NA |
| 1 | 4.37500 | -30.7708 | 3.45714 | -3.76163 | 9.29018 |
| 2 | 5.29405 | -28.9897 | 0.60016 | -2.56895 | 1.78110 |
| 3 | 5.52768 | -28.9176 | 0.02537 | -2.35639 | 0.07210 |
| 4 | 5.53844 | -28.9175 | 0.00005 | -2.34724 | 0.00014 |
| 5 | 5.53846 | -28.9175 | 0.00000 | -2.34722 | 0.00000 |
The final estimate matches the closed-form MLE, \(\bar x = 5.53846\) (Exercise 35).
[Code]
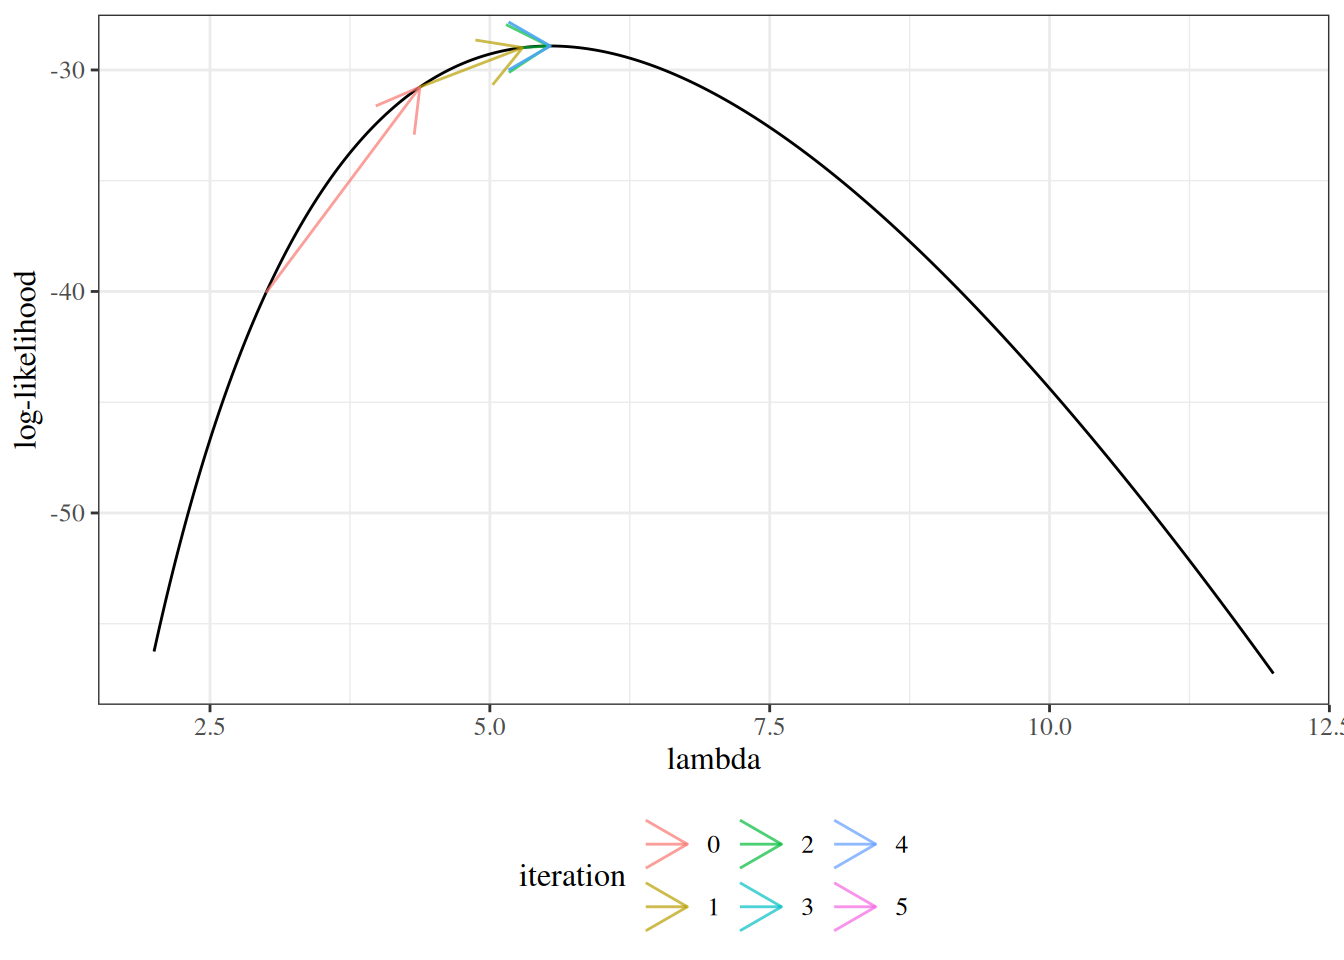
3 Maximum likelihood for a Bernoulli model without covariates
3.1 The likelihood
Exercise 37 (Likelihood of binary outcomes with one event probability) A binary outcome \(Y\) with event probability \(\pi\) has
\[ \begin{aligned} \Pr(Y = 1) &= \pi && \text{(definition of the event probability)}\\ \Pr(Y = 0) &= 1 - \pi && \text{(complement rule)}\\ \Pr(Y = y) &= \pi^y (1 - \pi)^{1 - y}, \quad y \in \mathopen{}\left\{0, 1\right\}\mathclose{} && \text{(combine the two cases)} \end{aligned} \]
Let \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}\stackrel{\text{def}}{=}(y_1, \ldots, y_n)\) be a dataset of mutually independent binary outcomes, all with the same event probability \(\pi\): \(Y_i\ \sim_{\perp\!\!\!\perp}\ \operatorname{Ber}(\pi)\). Derive the likelihood of \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}\).
Solution 37. \[ \begin{aligned} \mathcal{L}(\pi; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}) &= \prod_{i=1}^n\mathcal{L}_i(\pi) && \text{(product of likelihood components)}\\ &= \prod_{i=1}^n\Pr(Y_i= y_i) && \text{(definition of likelihood components)}\\ &= \prod_{i=1}^n\pi^{y_i} (1 - \pi)^{1 - y_i} && \text{(Bernoulli PMF)}\\ &= \mathopen{}\left(\prod_{i=1}^n\pi^{y_i}\right)\mathclose{} \mathopen{}\left(\prod_{i=1}^n(1 - \pi)^{1 - y_i}\right)\mathclose{} && \text{(regroup the factors of the product)}\\ &= \pi^{\sum_{i=1}^ny_i} (1 - \pi)^{\sum_{i=1}^n(1 - y_i)} && \text{(product of powers of a common base)}\\ &= \pi^{\sum_{i=1}^ny_i} (1 - \pi)^{\sum_{i=1}^n1 - \sum_{i=1}^ny_i} && \text{(distribute the sum over the terms in the exponent)}\\ &= \pi^{\sum_{i=1}^ny_i} (1 - \pi)^{n - \sum_{i=1}^ny_i} && \text{($\textstyle\sum_{i=1}^n1 = n$)}\\ &= \pi^{{s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}}} (1 - \pi)^{n - {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}}} && \text{(definition of ${s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} \stackrel{\text{def}}{=}\textstyle\sum_{i=1}^ny_i$)} \end{aligned} \]
Theorem 17 (Likelihood of binary outcomes with one event probability) Let \(Y_1, \dots, Y_n\) be mutually independent binary random variables, each with the same event probability \(\pi\): \(Y_i\ \sim_{\perp\!\!\!\perp}\ \operatorname{Ber}(\pi)\). For observed outcomes \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}\stackrel{\text{def}}{=}(y_1, \ldots, y_n)\), with each \(y_i\in \mathopen{}\left\{0, 1\right\}\mathclose{}\), the likelihood \(\mathcal{L}(\pi; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}})\) of \(\pi\) depends on the data only through the number of outcomes equal to 1, which is the sum of the elements \({s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} \stackrel{\text{def}}{=}\sum_{i=1}^ny_i\) of \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}\):
\[\mathcal{L}(\pi; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}) = \pi^{{s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}}} (1 - \pi)^{n - {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}}}\]
Proof. This is the solution to Exercise 37, worked in Solution 37.
3.2 Log-likelihood contributions
Exercise 38 (Log-likelihood contribution of one binary outcome) Let:
- \(Y_i\ \sim_{\perp\!\!\!\perp}\ \operatorname{Ber}(\pi)\) for \(i= 1, \dots, n\), with no covariates;
- \(y_i\in \mathopen{}\left\{0, 1\right\}\mathclose{}\) be the observed value of \(Y_i\).
Derive the log-likelihood contribution \(\ell_i(\pi)\) of observation \(i\), the log of its likelihood component.
Solution 38. \[ \begin{aligned} \ell_i(\pi) &= {\operatorname{log}\mathopen{}\left\{\Pr(Y_i= y_i)\right\}\mathclose{}} && \text{(log of the likelihood component)}\\ &= {\operatorname{log}\mathopen{}\left\{\pi^{y_i} (1 - \pi)^{1 - y_i}\right\}\mathclose{}} && \text{(Bernoulli PMF)}\\ &= {\operatorname{log}\mathopen{}\left\{\pi^{y_i}\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{(1 - \pi)^{1 - y_i}\right\}\mathclose{}} && \text{(log of a product)}\\ &= y_i{\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} + (1 - y_i) {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(log of a power)} \end{aligned} \]
Theorem 18 (Log-likelihood contribution of one binary outcome) If \(Y_i\sim \operatorname{Ber}(\pi)\) has observed value \(y_i\in \mathopen{}\left\{0, 1\right\}\mathclose{}\), its log-likelihood contribution is:
\[\ell_i(\pi) = y_i{\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} + (1 - y_i) {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}}\]
Proof. This is the solution to Exercise 38, worked in Solution 38.
Exercise 39 (Log-likelihood contribution of one binary outcome in terms of the log-odds) In the setting of Exercise 38, write the log-likelihood contribution \(\ell_i(\pi)\) using the log-odds \(\eta\stackrel{\text{def}}{=}\operatorname{logit}(\pi)\).
Solution 39. Starting from Theorem 18:
\[ \begin{aligned} \ell_i(\pi) &= y_i{\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} + (1 - y_i) {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(the contribution from the theorem above)}\\ &= y_i{\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} - y_i{\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(distribute ${\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}}$)}\\ &= y_i{\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} - y_i{\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(reorder the terms)}\\ &= y_i\mathopen{}\left({\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} - {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}}\right)\mathclose{} + {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(collect the terms in $y_i$)}\\ &= y_i{\operatorname{log}\mathopen{}\left\{\frac{\pi}{1 - \pi}\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(log of a quotient)}\\ &= y_i\eta+ {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(definition of $\eta\stackrel{\text{def}}{=}\operatorname{logit}(\pi)$)} \end{aligned} \]
Corollary 1 (Log-likelihood contribution of one binary outcome in terms of the log-odds) If \(Y_i\sim \operatorname{Ber}(\pi)\) has observed value \(y_i\in \mathopen{}\left\{0, 1\right\}\mathclose{}\), its log-likelihood contribution is, with the log-odds \(\eta\stackrel{\text{def}}{=}\operatorname{logit}(\pi)\):
\[\ell_i(\pi) = y_i\eta+ {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}}\]
Proof. This is the solution to Exercise 39, worked in Solution 39. It follows from Theorem 18.
3.3 The log-likelihood of the sample
Exercise 40 (Log-likelihood of binary outcomes with one event probability) Derive the log-likelihood of \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}\) from Exercise 37.
Solution 40. Starting from the likelihood in Theorem 17, where \({s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} \stackrel{\text{def}}{=}\sum_{i=1}^ny_i\):
\[ \begin{aligned} \ell(\pi; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}) &= {\operatorname{log}\mathopen{}\left\{\pi^{{s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}}} (1 - \pi)^{n - {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}}}\right\}\mathclose{}} && \text{(log of the likelihood)}\\ &= {\operatorname{log}\mathopen{}\left\{\pi^{{s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}}}\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{(1 - \pi)^{n - {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}}}\right\}\mathclose{}} && \text{(log of a product)}\\ &= {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} {\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} + \mathopen{}\left(n - {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}}\right)\mathclose{} {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(log of a power)}\\ &= {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} {\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} + n {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} - {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(distribute ${\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}}$)}\\ &= {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} {\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} - {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} + n {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(reorder the terms)}\\ &= {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} \mathopen{}\left({\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} - {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}}\right)\mathclose{} + n {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(collect the terms in ${s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}}$)}\\ &= {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} {\operatorname{log}\mathopen{}\left\{\frac{\pi}{1 - \pi}\right\}\mathclose{}} + n {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(log of a quotient)}\\ &= {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} \eta+ n {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(definition of $\eta\stackrel{\text{def}}{=}\operatorname{logit}(\pi)$)} \end{aligned} \]
Theorem 19 (Log-likelihood of binary outcomes with one event probability) Let \(Y_i\ \sim_{\perp\!\!\!\perp}\ \operatorname{Ber}(\pi)\) for \(i = 1, \dots, n\), with observed outcomes \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}\stackrel{\text{def}}{=}(y_1, \ldots, y_n)\), each \(y_i\in \mathopen{}\left\{0, 1\right\}\mathclose{}\). The log-likelihood \(\ell(\pi; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}})\) of the event probability \(\pi\), written with the log-odds \(\eta\stackrel{\text{def}}{=}\operatorname{logit}(\pi)\), is:
\[\ell(\pi; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}) = {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} \eta+ n {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}}\]
Proof. This is the solution to Exercise 40, worked in Solution 40. It builds on Theorem 17.
3.4 Score contributions
Example 14 (Precision of a Bernoulli variable) If \(Y\) is a Bernoulli variable, \(Y\sim \operatorname{Ber}(\pi)\) with \(\pi\in (0, 1)\), then \({\operatorname{Var}\mathopen{}\left(Y\right)\mathclose{}} = \pi(1 - \pi)\), so the precision of \(Y\) is \(\tau= 1 / \mathopen{}\left(\pi(1 - \pi)\right)\mathclose{}\).
Exercise 41 (Score function of a Bernoulli variable) Let \(X \sim \operatorname{Ber}(\pi)\) have observed value \(x \in \mathopen{}\left\{0, 1\right\}\mathclose{}\).
Derive the score of \(x\). In other words, differentiate the log-likelihood of \(x\) with respect to the event probability parameter \(\pi\), starting from the log-likelihood in terms of the log-odds \(\eta\stackrel{\text{def}}{=}\operatorname{logit}(\pi)\) in Corollary 1.
Solution 41. With \(y_i= x\), Corollary 1 gives \(\ell= x \eta+ {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}}\), so:
\[ \begin{aligned} \ell' &\stackrel{\text{def}}{=}\frac{\partial}{\partial \pi} \ell && \text{(definition of the score)}\\ &= \frac{\partial}{\partial \pi} \mathopen{}\left(x \eta+ {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}}\right)\mathclose{} && \text{(log-likelihood in terms of the log-odds)}\\ &= \frac{\partial}{\partial \pi} \mathopen{}\left(x \eta\right)\mathclose{} + \frac{\partial}{\partial \pi} {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(linearity of differentiation)}\\ &= x \frac{\partial}{\partial \pi} \eta+ \frac{\partial}{\partial \pi} {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(constant multiple rule)} \end{aligned} \]
The inner derivative in the second term is:
\[ \begin{aligned} \frac{\partial}{\partial \pi}(1 - \pi) &= \frac{\partial}{\partial \pi} 1 - \frac{\partial}{\partial \pi} \pi && \text{(linearity of differentiation)}\\ &= 0 - 1 && \text{(derivatives of a constant and of $\pi$)}\\ &= -1 && \text{(subtract)} \end{aligned} \]
The second term is then:
\[ \begin{aligned} \frac{\partial}{\partial \pi} {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} &= \frac{1}{1 - \pi} \frac{\partial}{\partial \pi}(1 - \pi) && \text{(chain rule and derivative of $\log$)}\\ &= \frac{1}{1 - \pi} (-1) && \text{(inner derivative is $-1$)}\\ &= -\frac{1}{1 - \pi} && \text{(multiply by $-1$)} \end{aligned} \]
The derivative of the log-odds is:
\[ \begin{aligned} \frac{\partial}{\partial \pi} \eta &= \frac{\partial}{\partial \pi} {\operatorname{log}\mathopen{}\left\{\frac{\pi}{1 - \pi}\right\}\mathclose{}} && \text{(definition of $\eta$)}\\ &= \frac{\partial}{\partial \pi} \mathopen{}\left({\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} - {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}}\right)\mathclose{} && \text{(log of a quotient)}\\ &= \frac{\partial}{\partial \pi} {\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} - \frac{\partial}{\partial \pi} {\operatorname{log}\mathopen{}\left\{1 - \pi\right\}\mathclose{}} && \text{(linearity of differentiation)}\\ &= \frac{1}{\pi} - \mathopen{}\left(-\frac{1}{1 - \pi}\right)\mathclose{} && \text{(derivative of $\log$, and the second term above)}\\ &= \frac{1}{\pi} + \frac{1}{1 - \pi} && \text{(subtracting a negative)}\\ &= \frac{1 - \pi}{\pi(1 - \pi)} + \frac{\pi}{\pi(1 - \pi)} && \text{(write both terms over the common denominator)}\\ &= \frac{1}{\pi(1 - \pi)} && \text{(add the numerators)} \end{aligned} \]
Substituting both derivatives back in:
\[ \begin{aligned} \ell' &= x \mathopen{}\left(\frac{1}{\pi(1 - \pi)}\right)\mathclose{} + \mathopen{}\left(-\frac{1}{1 - \pi}\right)\mathclose{} && \text{(substitute the two derivatives)}\\ &= \frac{x}{\pi(1 - \pi)} + \mathopen{}\left(-\frac{1}{1 - \pi}\right)\mathclose{} && \text{(multiply $x$ into the numerator)}\\ &= \frac{x}{\pi(1 - \pi)} - \frac{1}{1 - \pi} && \text{(adding a negative is subtracting)}\\ &= \frac{x}{\pi(1 - \pi)} - \frac{\pi}{\pi(1 - \pi)} && \text{(multiply the numerator and denominator of the second term by $\pi$)}\\ &= \frac{x - \pi}{\pi(1 - \pi)} && \text{(combine the fractions)} \end{aligned} \]
Exercise 42 (Score of a Bernoulli variable in terms of deviation and precision) In the setting of Exercise 41, let \(\mathbb{d}\stackrel{\text{def}}{=}x - {\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}\) be the deviation of \(x\) from the mean of \(X\), and let \(\tau\stackrel{\text{def}}{=}1 / {\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}\) be the precision of \(X\). Write the score using \(\mathbb{d}\) and \(\tau\).
Solution 42. Starting from Solution 41:
\[ \begin{aligned} \ell' &= \frac{x - \pi}{\pi(1 - \pi)} && \text{(score)}\\ &= \frac{x - \pi}{{\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}} && \text{(${\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}} = \pi(1 - \pi)$)}\\ &= \frac{x - {\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}}{{\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}} && \text{(${\mathbb{E}\mathopen{}\left[X\right]\mathclose{}} = \pi$)}\\ &= \frac{\mathbb{d}}{{\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}} && \text{(definition of $\mathbb{d}$)}\\ &= \tau\mathbb{d} && \text{(definition of $\tau$)} \end{aligned} \]
Theorem 20 (Score function of a Bernoulli variable) Let \(X \sim \operatorname{Ber}(\pi)\), with event probability \(\pi\) and observed value \(x \in \mathopen{}\left\{0, 1\right\}\mathclose{}\). The score \(\ell'\) of the single observation \(x\) is the derivative of its log-likelihood \(\ell\) with respect to \(\pi\). It equals the precision \(\tau= 1 / {\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}\) of \(X\) times the deviation \(\mathbb{d}\stackrel{\text{def}}{=}x - {\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}\) of \(x\) from the mean \({\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}\):
\[\ell'= \tau\mathbb{d}= \frac{\mathbb{d}}{{\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}} = \frac{x - \pi}{\pi(1 - \pi)}\]
Proof. The score as \((x - \pi) / \mathopen{}\left(\pi(1 - \pi)\right)\mathclose{}\) is the solution to Exercise 41, worked in Solution 41. Writing the score as \(\mathbb{d}/ {\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}\) and then as \(\tau\mathbb{d}\) is the solution to Exercise 42, worked in Solution 42. The proof builds on Corollary 1.
Example 15 (Score of one Bernoulli observation) For a Bernoulli variable with event probability \(\pi\) and observed value \(x \in \mathopen{}\left\{0, 1\right\}\mathclose{}\), the score in Theorem 20 is \(1 / \pi\) when \(x = 1\) and \(-1 / (1 - \pi)\) when \(x = 0\). When the event occurs, the log-likelihood increases as \(\pi\) increases. When the event does not occur, the log-likelihood decreases as \(\pi\) increases.
In all four examples (Bernoulli score, Theorem 6, Theorem 7, and Theorem 8), the score function with respect to the mean turned out to be:
\[\ell'= \frac{x - {\mathbb{E}\mathopen{}\left[X\right]\mathclose{}}}{{\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}}\]
Remark 12 (The score function in natural exponential families). This pattern is no coincidence. With the mean as the parameter, each of these four models is a one-parameter natural (or linear) exponential family, whose log-density is linear in \(x\); for every such family, the score with respect to the mean is \((x - {\mathbb{E}\mathopen{}\left[X\right]\mathclose{}})/{\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}}\). Other members of the broader exponential family, such as the Weibull distribution with known shape \(k \ne 1\), do not have this form. Exponential-family distributions share many special properties [1, Ch. 3], [7, Sec. 6.7].
Exercise 43 (Score contribution of one binary outcome) In the setting of Exercise 38, derive the score contribution \(\ell'_i(\pi) \stackrel{\text{def}}{=}\frac{\partial}{\partial \pi} \ell_i(\pi)\) of observation \(i\).
Solution 43. The score contribution is the score of the single observation \(y_i\), so Theorem 20 with \(x = y_i\) gives
\[ \begin{aligned} \ell'_i(\pi) &= \frac{\partial}{\partial \pi} \ell_i(\pi) && \text{(definition of the score contribution)}\\ &= \frac{y_i- \pi}{\pi(1 - \pi)} && \text{(score of a Bernoulli variable)} \end{aligned} \]
Exercise 44 (Score contribution in terms of deviation and precision) In the setting of Exercise 43, let:
- \(\mathbb{d}_i\stackrel{\text{def}}{=}y_i- \pi\) be the deviation of \(y_i\) from the mean \(\pi\) of \(Y_i\);
- \(\tau\stackrel{\text{def}}{=}1 / {\operatorname{Var}\mathopen{}\left(Y_i\right)\mathclose{}}\) be the precision of \(Y_i\).
Write the score contribution using \(\mathbb{d}_i\) and \(\tau\).
Solution 44. Starting from Solution 43:
\[ \begin{aligned} \ell'_i(\pi) &= \frac{y_i- \pi}{\pi(1 - \pi)} && \text{(score contribution)}\\ &= \frac{y_i- \pi}{{\operatorname{Var}\mathopen{}\left(Y_i\right)\mathclose{}}} && \text{(${\operatorname{Var}\mathopen{}\left(Y_i\right)\mathclose{}} = \pi(1 - \pi)$)}\\ &= \frac{y_i- {\mathbb{E}\mathopen{}\left[Y_i\right]\mathclose{}}}{{\operatorname{Var}\mathopen{}\left(Y_i\right)\mathclose{}}} && \text{(${\mathbb{E}\mathopen{}\left[Y_i\right]\mathclose{}} = \pi$)}\\ &= \frac{\mathbb{d}_i}{{\operatorname{Var}\mathopen{}\left(Y_i\right)\mathclose{}}} && \text{(definition of $\mathbb{d}_i$)}\\ &= \tau\mathbb{d}_i && \text{(definition of $\tau$)} \end{aligned} \]
Theorem 21 (Score contribution of one binary outcome) If \(Y_i\sim \operatorname{Ber}(\pi)\) has observed value \(y_i\in \mathopen{}\left\{0, 1\right\}\mathclose{}\) and precision \(\tau= 1 / {\operatorname{Var}\mathopen{}\left(Y_i\right)\mathclose{}} = 1 / \mathopen{}\left(\pi(1 - \pi)\right)\mathclose{}\), its score contribution is the precision times the deviation \(\mathbb{d}_i\stackrel{\text{def}}{=}y_i- \pi\) of \(y_i\) from its mean \(\pi\):
\[\ell'_i(\pi) = \tau\mathbb{d}_i\]
The precision \(\tau\) is the same for every \(i\), because all \(Y_i\) share the event probability \(\pi\).
Proof. The score contribution as \((y_i- \pi) / \mathopen{}\left(\pi(1 - \pi)\right)\mathclose{}\) is the solution to Exercise 43, worked in Solution 43. The form in terms of the deviation is the solution to Exercise 44, worked in Solution 44.
3.5 The score function of the sample
Exercise 45 (Sample mean of the deviations of a binary sample) In the setting of Exercise 43, let:
- \({\bar{y}}\stackrel{\text{def}}{=}\frac{1}{n}\sum_{i=1}^ny_i\) be the sample mean of the observed outcomes;
- \({\bar{\mathbb{d}}}\stackrel{\text{def}}{=}\frac{1}{n}\sum_{i=1}^n\mathbb{d}_i\) be the sample mean of the deviations \(\mathbb{d}_i\).
Write \({\bar{\mathbb{d}}}\) using \({\bar{y}}\) and \(\pi\).
Solution 45. \[ \begin{aligned} {\bar{\mathbb{d}}} &= \frac{1}{n}\sum_{i=1}^n\mathbb{d}_i && \text{(definition of ${\bar{\mathbb{d}}}$)}\\ &= \frac{1}{n}\sum_{i=1}^n(y_i- \pi) && \text{(definition of $\mathbb{d}_i$)}\\ &= \frac{1}{n} \mathopen{}\left(\sum_{i=1}^ny_i- \sum_{i=1}^n\pi\right)\mathclose{} && \text{(distribute the sum over the difference)}\\ &= \frac{1}{n} \mathopen{}\left({s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} - \sum_{i=1}^n\pi\right)\mathclose{} && \text{(definition of ${s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}}$)}\\ &= \frac{1}{n} \mathopen{}\left(n {\bar{y}}- n \pi\right)\mathclose{} && \text{(${s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} = n {\bar{y}}$ and $\textstyle\sum_{i=1}^n\pi= n \pi$)}\\ &= \frac{1}{n} \cdot n ({\bar{y}}- \pi) && \text{(factor out $n$)}\\ &= {\bar{y}}- \pi && \text{($\frac{1}{n} \cdot n = 1$)} \end{aligned} \]
Exercise 46 (Score function of a binary sample) In the setting of Exercise 45, assemble the score function \(\ell'(\pi)\) of the whole sample from the score contributions, and write it using \({\bar{\mathbb{d}}}\) and \(\tau\).
Solution 46. \[ \begin{aligned} \ell'(\pi) &= \sum_{i=1}^n\ell'_i(\pi) && \text{(score of an independent sample is the sum of the score contributions)}\\ &= \sum_{i=1}^n\tau\mathbb{d}_i && \text{(score contribution of a binary outcome)}\\ &= \tau\sum_{i=1}^n\mathbb{d}_i && \text{($\tau$ is the same for every $i$)}\\ &= \tau\cdot n {\bar{\mathbb{d}}} && \text{($\textstyle\sum_{i=1}^n\mathbb{d}_i= n {\bar{\mathbb{d}}}$, from the definition of ${\bar{\mathbb{d}}}$)}\\ &= n \tau{\bar{\mathbb{d}}} && \text{(reorder the factors)} \end{aligned} \]
Theorem 22 (Score function of a binary sample) If \(Y_i\ \sim_{\perp\!\!\!\perp}\ \operatorname{Ber}(\pi)\) for \(i= 1, \dots, n\), with observed sample mean \({\bar{y}}\), precision \(\tau= 1 / \mathopen{}\left(\pi(1 - \pi)\right)\mathclose{}\), and sample mean \({\bar{\mathbb{d}}}\stackrel{\text{def}}{=}\frac{1}{n}\sum_{i=1}^n\mathbb{d}_i\) of the deviations \(\mathbb{d}_i= y_i- \pi\), the score function is:
\[\ell'(\pi) = n \tau{\bar{\mathbb{d}}}= n \tau({\bar{y}}- \pi)\]
Proof. The first equality is the solution to Exercise 46, worked in Solution 46. The second is the solution to Exercise 45, worked in Solution 45.
3.6 Solving the score equation
Exercise 47 (Solving the score equation of a binary sample) In the setting of Exercise 46, assume \({\bar{y}}\in (0, 1)\): the sample has at least one event and at least one non-event. Solve the score equation \(\ell'(\pi) = 0\) for \(\pi\in (0, 1)\).
Solution 47. For \(\pi\in (0, 1)\), \(\tau= 1 / \mathopen{}\left(\pi(1 - \pi)\right)\mathclose{}\) is finite and positive, and \(n > 0\), so \(n \tau\neq 0\).
\[ \begin{aligned} 0 &= \ell'(\pi) && \text{(score equation)}\\ 0 &= n \tau({\bar{y}}- \pi) && \text{(score function of a binary sample)}\\ 0 &= {\bar{y}}- \pi && \text{(divide both sides by $n \tau\neq 0$)}\\ \pi&= {\bar{y}} && \text{(add $\pi$ to both sides)} \end{aligned} \]
Since \({\bar{y}}\in (0, 1)\), this solution lies in \((0, 1)\).
Theorem 23 (Solution of the score equation of a binary sample) If \(Y_i\ \sim_{\perp\!\!\!\perp}\ \operatorname{Ber}(\pi)\) for \(i= 1, \dots, n\) and the observed sample mean satisfies \({\bar{y}}\in (0, 1)\), then the score equation \(\ell'(\pi) = 0\) has exactly one solution in \((0, 1)\): the sample mean \(\pi= {\bar{y}}\).
Proof. This is the solution to Exercise 47, worked in Solution 47.
Example 16 (Score equation of a Bernoulli sample) For \(n\) independent Bernoulli observations with \(r = \sum_i y_i\) successes, the score is \(\sum_{i=1}^n(y_i- \pi)/\mathopen{}\left(\pi(1 - \pi)\right)\mathclose{} = (r - n\pi)/\mathopen{}\left(\pi(1-\pi)\right)\mathclose{}\) (summing Bernoulli score over the observations), so for \(0 < r < n\) the score equation \((r - n\pi)/\mathopen{}\left(\pi(1-\pi)\right)\mathclose{} = 0\) has the single solution \(\pi= r/n\).
3.7 Hessian contributions
Exercise 48 (Hessian contribution of one binary outcome) In the setting of Exercise 43, derive the Hessian contribution \(\ell''_i(\pi) \stackrel{\text{def}}{=}\frac{\partial}{\partial \pi} \ell'_i(\pi)\) of observation \(i\). Start from the score contribution written as a difference of two fractions, \(\ell'_i(\pi) = y_i/ \pi- (1 - y_i) / (1 - \pi)\), the form in Solution 41 before its fractions are combined.
Solution 48. \[ \begin{aligned} \ell''_i(\pi) &= \frac{\partial}{\partial \pi} \ell'_i(\pi) && \text{(definition of the Hessian contribution)}\\ &= \frac{\partial}{\partial \pi} \mathopen{}\left(\frac{y_i}{\pi} - \frac{1 - y_i}{1 - \pi}\right)\mathclose{} && \text{(score contribution as a difference of fractions)}\\ &= \frac{\partial}{\partial \pi} \mathopen{}\left(y_i\pi^{-1} - (1 - y_i) (1 - \pi)^{-1}\right)\mathclose{} && \text{(write each fraction as a negative power)}\\ &= y_i\frac{\partial}{\partial \pi} \pi^{-1} - (1 - y_i) \frac{\partial}{\partial \pi} (1 - \pi)^{-1} && \text{(linearity and constant multiple rule)} \end{aligned} \]
The first derivative is:
\[ \frac{\partial}{\partial \pi} \pi^{-1} = -\pi^{-2} \qquad \text{(power rule)} \]
The second derivative needs the chain rule:
\[ \begin{aligned} \frac{\partial}{\partial \pi} (1 - \pi)^{-1} &= -(1 - \pi)^{-2} \frac{\partial}{\partial \pi} (1 - \pi) && \text{(chain rule and power rule)}\\ &= -(1 - \pi)^{-2} (-1) && \text{($\frac{\partial}{\partial \pi} (1 - \pi) = -1$, as in the score exercise)}\\ &= (1 - \pi)^{-2} && \text{(multiply)} \end{aligned} \]
Substituting both derivatives back in:
\[ \begin{aligned} \ell''_i(\pi) &= y_i\mathopen{}\left(-\pi^{-2}\right)\mathclose{} - (1 - y_i) (1 - \pi)^{-2} && \text{(substitute the two derivatives)}\\ &= -\frac{y_i}{{\mathopen{}\left(\pi\right)\mathclose{}}^{2}} - \frac{1 - y_i}{{\mathopen{}\left(1 - \pi\right)\mathclose{}}^{2}} && \text{(write the negative powers as fractions)} \end{aligned} \]
Theorem 24 (Hessian contribution of one binary outcome) If \(Y_i\sim \operatorname{Ber}(\pi)\) has observed value \(y_i\in \mathopen{}\left\{0, 1\right\}\mathclose{}\), its Hessian contribution is:
\[\ell''_i(\pi) = -\frac{y_i}{{\mathopen{}\left(\pi\right)\mathclose{}}^{2}} - \frac{1 - y_i}{{\mathopen{}\left(1 - \pi\right)\mathclose{}}^{2}}\]
Proof. This is the solution to Exercise 48, worked in Solution 48.
Lemma 5 (Derivative of the Bernoulli precision) If \(Y\) is a Bernoulli variable, \(Y\sim \operatorname{Ber}(\pi)\) with \(\pi\in (0, 1)\) and precision \(\tau= 1 / \mathopen{}\left(\pi(1 - \pi)\right)\mathclose{}\), then the derivative of \(\tau\) with respect to \(\pi\) is
\[\frac{\partial}{\partial \pi} \tau= -{\mathopen{}\left(\tau\right)\mathclose{}}^{2} \mathopen{}\left(1 - 2 \pi\right)\mathclose{}\]
Proof. The derivative needs the chain rule:
\[ \begin{aligned} \frac{\partial}{\partial \pi} \tau &= \frac{\partial}{\partial \pi} \mathopen{}\left(\pi(1 - \pi)\right)\mathclose{}^{-1} && \text{(definition of $\tau$ as a negative power)}\\ &= \frac{\partial}{\partial \pi} \mathopen{}\left(\pi- {\mathopen{}\left(\pi\right)\mathclose{}}^{2}\right)\mathclose{}^{-1} && \text{(distribute $\pi$)}\\ &= -\mathopen{}\left(\pi- {\mathopen{}\left(\pi\right)\mathclose{}}^{2}\right)\mathclose{}^{-2} \frac{\partial}{\partial \pi} \mathopen{}\left(\pi- {\mathopen{}\left(\pi\right)\mathclose{}}^{2}\right)\mathclose{} && \text{(chain rule and power rule)}\\ &= -\mathopen{}\left(\pi- {\mathopen{}\left(\pi\right)\mathclose{}}^{2}\right)\mathclose{}^{-2} \mathopen{}\left(1 - 2 \pi\right)\mathclose{} && \text{(linearity and power rule)}\\ &= -\mathopen{}\left(\pi(1 - \pi)\right)\mathclose{}^{-2} \mathopen{}\left(1 - 2 \pi\right)\mathclose{} && \text{(factor $\pi- {\mathopen{}\left(\pi\right)\mathclose{}}^{2} = \pi(1 - \pi)$)}\\ &= -{\mathopen{}\left(\tau\right)\mathclose{}}^{2} \mathopen{}\left(1 - 2 \pi\right)\mathclose{} && \text{(definition of $\tau$)} \end{aligned} \]
Example 17 (Derivative of the precision at \(\pi= 1/4\)) At \(\pi= 1/4\), the precision is
\[ \begin{aligned} \tau &= \frac{1}{\pi(1 - \pi)} && \text{(definition of $\tau$)}\\ &= \frac{1}{\frac{1}{4} \cdot \frac{3}{4}} && \text{(substitute $\pi= 1/4$)}\\ &= \frac{16}{3} && \text{(multiply the fractions and take the reciprocal)} \end{aligned} \]
so by Lemma 5,
\[ \begin{aligned} \frac{\partial}{\partial \pi} \tau &= -{\mathopen{}\left(\tau\right)\mathclose{}}^{2} \mathopen{}\left(1 - 2 \pi\right)\mathclose{} && \text{(@lem-bernoulli-precision-deriv)}\\ &= -{\mathopen{}\left(\mathopen{}\left(\frac{16}{3}\right)\mathclose{}\right)\mathclose{}}^{2} \mathopen{}\left(1 - \frac{1}{2}\right)\mathclose{} && \text{(substitute $\tau= 16/3$ and $\pi= 1/4$)}\\ &= -\frac{256}{9} \cdot \frac{1}{2} && \text{(square and subtract)}\\ &= -\frac{128}{9} && \text{(multiply the fractions)} \end{aligned} \]
The precision falls as \(\pi\) rises toward \(1/2\), where it is smallest, which matches a derivative below zero.
Exercise 49 (Hessian contribution of one binary outcome in terms of the precision and deviation) In the setting of Exercise 48, derive the Hessian contribution \(\ell''_i(\pi)\) starting from the simplified score contribution \(\ell'_i(\pi) = \tau\mathbb{d}_i\) in Theorem 21, with the precision \(\tau= 1 / \mathopen{}\left(\pi(1 - \pi)\right)\mathclose{}\) and the deviation \(\mathbb{d}_i\stackrel{\text{def}}{=}y_i- \pi\). Both \(\tau\) and \(\mathbb{d}_i\) depend on \(\pi\), while the observed value \(y_i\) does not.
Solution 49. \[ \begin{aligned} \ell''_i(\pi) &= \frac{\partial}{\partial \pi} \ell'_i(\pi) && \text{(definition of the Hessian contribution)}\\ &= \frac{\partial}{\partial \pi} \mathopen{}\left(\tau\mathbb{d}_i\right)\mathclose{} && \text{(score contribution)}\\ &= \mathopen{}\left(\frac{\partial}{\partial \pi} \tau\right)\mathclose{} \mathbb{d}_i+ \tau\frac{\partial}{\partial \pi} \mathbb{d}_i && \text{(product rule)} \end{aligned} \]
The derivative of the deviation is:
\[ \begin{aligned} \frac{\partial}{\partial \pi} \mathbb{d}_i &= \frac{\partial}{\partial \pi} \mathopen{}\left(y_i- \pi\right)\mathclose{} && \text{(definition of $\mathbb{d}_i$)}\\ &= \frac{\partial}{\partial \pi} y_i- \frac{\partial}{\partial \pi} \pi && \text{(linearity of differentiation)}\\ &= 0 - 1 && \text{(derivatives of a constant and of $\pi$)}\\ &= -1 && \text{(subtract)} \end{aligned} \]
The derivative of the precision is given by Lemma 5:
\[\frac{\partial}{\partial \pi} \tau= -{\mathopen{}\left(\tau\right)\mathclose{}}^{2} \mathopen{}\left(1 - 2 \pi\right)\mathclose{}\]
Substituting both derivatives back in:
\[ \begin{aligned} \ell''_i(\pi) &= \mathopen{}\left(-{\mathopen{}\left(\tau\right)\mathclose{}}^{2} \mathopen{}\left(1 - 2 \pi\right)\mathclose{}\right)\mathclose{} \mathbb{d}_i+ \tau(-1) && \text{(substitute the two derivatives)}\\ &= -\tau- \mathopen{}\left(1 - 2 \pi\right)\mathclose{} {\mathopen{}\left(\tau\right)\mathclose{}}^{2} \mathbb{d}_i && \text{(multiply by $-1$ and reorder the terms)} \end{aligned} \]
Corollary 2 (Hessian contribution of one binary outcome in terms of the precision and deviation) If \(Y_i\sim \operatorname{Ber}(\pi)\) has observed value \(y_i\in \mathopen{}\left\{0, 1\right\}\mathclose{}\) and precision \(\tau= 1 / \mathopen{}\left(\pi(1 - \pi)\right)\mathclose{}\), its Hessian contribution is, with the deviation \(\mathbb{d}_i\stackrel{\text{def}}{=}y_i- \pi\):
\[\ell''_i(\pi) = -\tau- \mathopen{}\left(1 - 2 \pi\right)\mathclose{} {\mathopen{}\left(\tau\right)\mathclose{}}^{2} \mathbb{d}_i\]
Proof. This is the solution to Exercise 49, worked in Solution 49. It follows from Theorem 24.
Exercise 50 (Hessian contribution of one binary outcome as a squared deviation) In the setting of Exercise 49, starting from the Hessian contribution \(\ell''_i(\pi)\) in Corollary 2, write \(\ell''_i(\pi)\) with the precision \(\tau= 1 / \mathopen{}\left(\pi(1 - \pi)\right)\mathclose{}\) as a multiple of \({\mathopen{}\left(\tau\right)\mathclose{}}^{2}\) times the square of the deviation \(\mathbb{d}_i\stackrel{\text{def}}{=}y_i- \pi\). Hint: because \(y_i\in \mathopen{}\left\{0, 1\right\}\mathclose{}\), \({\mathopen{}\left(y_i\right)\mathclose{}}^{2} = y_i\).
Solution 50. Starting from Corollary 2, factor out \({\mathopen{}\left(\tau\right)\mathclose{}}^{2}\). The reciprocal of the precision is \(1 / \tau= \pi(1 - \pi)\), so:
\[ \begin{aligned} \ell''_i(\pi) &= -\tau- \mathopen{}\left(1 - 2 \pi\right)\mathclose{} {\mathopen{}\left(\tau\right)\mathclose{}}^{2} \mathbb{d}_i && \text{(the contribution from the corollary)}\\ &= -{\mathopen{}\left(\tau\right)\mathclose{}}^{2} \frac{1}{\tau} - \mathopen{}\left(1 - 2 \pi\right)\mathclose{} {\mathopen{}\left(\tau\right)\mathclose{}}^{2} \mathbb{d}_i && \text{($\tau= {\mathopen{}\left(\tau\right)\mathclose{}}^{2} / \tau$)}\\ &= -{\mathopen{}\left(\tau\right)\mathclose{}}^{2} \mathopen{}\left(\pi(1 - \pi) + \mathopen{}\left(1 - 2 \pi\right)\mathclose{} \mathbb{d}_i\right)\mathclose{} && \text{(factor out $-{\mathopen{}\left(\tau\right)\mathclose{}}^{2}$)} \end{aligned} \]
The factor in parentheses is:
\[ \begin{aligned} \pi(1 - \pi) + \mathopen{}\left(1 - 2 \pi\right)\mathclose{} \mathbb{d}_i &= \pi- {\mathopen{}\left(\pi\right)\mathclose{}}^{2} + \mathopen{}\left(1 - 2 \pi\right)\mathclose{} \mathopen{}\left(y_i- \pi\right)\mathclose{} && \text{(distribute $\pi$; definition of $\mathbb{d}_i$)}\\ &= \pi- {\mathopen{}\left(\pi\right)\mathclose{}}^{2} + y_i- \pi- 2 \pi y_i+ 2 {\mathopen{}\left(\pi\right)\mathclose{}}^{2} && \text{(distribute $1 - 2 \pi$)}\\ &= y_i- 2 \pi y_i+ \mathopen{}\left(2 {\mathopen{}\left(\pi\right)\mathclose{}}^{2} - {\mathopen{}\left(\pi\right)\mathclose{}}^{2}\right)\mathclose{} + \mathopen{}\left(\pi- \pi\right)\mathclose{} && \text{(reorder and group the terms)}\\ &= y_i- 2 \pi y_i+ {\mathopen{}\left(\pi\right)\mathclose{}}^{2} + 0 && \text{($2 a - a = a$ and $a - a = 0$)}\\ &= y_i- 2 \pi y_i+ {\mathopen{}\left(\pi\right)\mathclose{}}^{2} && \text{($a + 0 = a$)}\\ &= {\mathopen{}\left(y_i\right)\mathclose{}}^{2} - 2 \pi y_i+ {\mathopen{}\left(\pi\right)\mathclose{}}^{2} && \text{($y_i\in \mathopen{}\left\{0, 1\right\}\mathclose{}$, so $y_i= {\mathopen{}\left(y_i\right)\mathclose{}}^{2}$)}\\ &= {\mathopen{}\left(\mathopen{}\left(y_i- \pi\right)\mathclose{}\right)\mathclose{}}^{2} && \text{(square of a difference)}\\ &= {\mathopen{}\left(\mathbb{d}_i\right)\mathclose{}}^{2} && \text{(definition of $\mathbb{d}_i$)} \end{aligned} \]
Substituting the factor back in:
\[ \ell''_i(\pi) = -{\mathopen{}\left(\tau\right)\mathclose{}}^{2} {\mathopen{}\left(\mathbb{d}_i\right)\mathclose{}}^{2} \qquad \text{(substitute ${\mathopen{}\left(\mathbb{d}_i\right)\mathclose{}}^{2}$)} \]
Corollary 3 (Hessian contribution of one binary outcome as a squared deviation) If \(Y_i\sim \operatorname{Ber}(\pi)\) has observed value \(y_i\in \mathopen{}\left\{0, 1\right\}\mathclose{}\), its Hessian contribution, written with the precision \(\tau= 1 / \mathopen{}\left(\pi(1 - \pi)\right)\mathclose{}\) and the deviation \(\mathbb{d}_i\stackrel{\text{def}}{=}y_i- \pi\), is:
\[\ell''_i(\pi) = -{\mathopen{}\left(\tau\right)\mathclose{}}^{2} {\mathopen{}\left(\mathbb{d}_i\right)\mathclose{}}^{2}\]
Proof. This is the solution to Exercise 50, worked in Solution 50. It follows from Corollary 2.
3.8 The Hessian of the sample
Exercise 51 (Hessian of a binary sample) In the setting of Exercise 46, assemble the Hessian \(\ell''(\pi)\) of the whole sample from the Hessian contributions.
Solution 51. \[ \begin{aligned} \ell''(\pi) &= \sum_{i=1}^n\ell''_i(\pi) && \text{(the derivative of a sum is the sum of the derivatives)}\\ &= \sum_{i=1}^n\mathopen{}\left(-\frac{y_i}{{\mathopen{}\left(\pi\right)\mathclose{}}^{2}} - \frac{1 - y_i}{{\mathopen{}\left(1 - \pi\right)\mathclose{}}^{2}}\right)\mathclose{} && \text{(Hessian contribution of a binary outcome)}\\ &= -\frac{1}{{\mathopen{}\left(\pi\right)\mathclose{}}^{2}} \sum_{i=1}^ny_i- \frac{1}{{\mathopen{}\left(1 - \pi\right)\mathclose{}}^{2}} \sum_{i=1}^n(1 - y_i) && \text{(distribute the sum over the terms; the denominators do not depend on $i$)}\\ &= -\frac{1}{{\mathopen{}\left(\pi\right)\mathclose{}}^{2}} {s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} - \frac{1}{{\mathopen{}\left(1 - \pi\right)\mathclose{}}^{2}} \sum_{i=1}^n(1 - y_i) && \text{(definition of ${s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}}$)}\\ &= -\frac{n {\bar{y}}}{{\mathopen{}\left(\pi\right)\mathclose{}}^{2}} - \frac{1}{{\mathopen{}\left(1 - \pi\right)\mathclose{}}^{2}} \mathopen{}\left(n - n {\bar{y}}\right)\mathclose{} && \text{(${s_{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{y}}\vphantom{y}}}} = n {\bar{y}}$ and $\textstyle\sum_{i=1}^n1 = n$)}\\ &= -\frac{n {\bar{y}}}{{\mathopen{}\left(\pi\right)\mathclose{}}^{2}} - \frac{n (1 - {\bar{y}})}{{\mathopen{}\left(1 - \pi\right)\mathclose{}}^{2}} && \text{(factor out $n$)}\\ &= -n \mathopen{}\left(\frac{{\bar{y}}}{{\mathopen{}\left(\pi\right)\mathclose{}}^{2}} + \frac{1 - {\bar{y}}}{{\mathopen{}\left(1 - \pi\right)\mathclose{}}^{2}}\right)\mathclose{} && \text{(factor out $-n$)} \end{aligned} \]
Theorem 25 (Hessian of a binary sample) If \(Y_i\ \sim_{\perp\!\!\!\perp}\ \operatorname{Ber}(\pi)\) for \(i= 1, \dots, n\), with observed sample mean \({\bar{y}}\), the Hessian of the log-likelihood is the \(1 \times 1\) matrix whose only entry is:
\[\ell''(\pi) = -n \mathopen{}\left(\frac{{\bar{y}}}{{\mathopen{}\left(\pi\right)\mathclose{}}^{2}} + \frac{1 - {\bar{y}}}{{\mathopen{}\left(1 - \pi\right)\mathclose{}}^{2}}\right)\mathclose{}\]
Proof. This is the solution to Exercise 51, worked in Solution 51.
3.9 Checking that the Hessian is negative definite
Exercise 52 (Negative definiteness of the Hessian of a binary sample) In the setting of Exercise 51, show that the Hessian \(\ell''(\pi)\) is negative definite for every \(\pi\in (0, 1)\).
Solution 52. A \(1 \times 1\) matrix is negative definite exactly when its only entry is negative, so it is enough to show \(\ell''(\pi) < 0\).
Fix \(\pi\in (0, 1)\). Then:
- \({\mathopen{}\left(\pi\right)\mathclose{}}^{2} > 0\) and \({\mathopen{}\left(1 - \pi\right)\mathclose{}}^{2} > 0\);
- \({\bar{y}}\ge 0\) and \(1 - {\bar{y}}\ge 0\), because \(y_i\in \mathopen{}\left\{0, 1\right\}\mathclose{}\);
- \({\bar{y}}\) and \(1 - {\bar{y}}\) are not both zero, because they sum to \(1\).
So \({\bar{y}}/ {\mathopen{}\left(\pi\right)\mathclose{}}^{2} + (1 - {\bar{y}}) / {\mathopen{}\left(1 - \pi\right)\mathclose{}}^{2}\) is a sum of two nonnegative terms, at least one of them positive. It is therefore positive, and with \(n > 0\):
\[ \ell''(\pi) = -n \mathopen{}\left(\frac{{\bar{y}}}{{\mathopen{}\left(\pi\right)\mathclose{}}^{2}} + \frac{1 - {\bar{y}}}{{\mathopen{}\left(1 - \pi\right)\mathclose{}}^{2}}\right)\mathclose{} < 0 \]
This holds for every \(\pi\in (0, 1)\).
Theorem 26 (Negative definiteness of the Hessian of a binary sample) If \(Y_i\ \sim_{\perp\!\!\!\perp}\ \operatorname{Ber}(\pi)\) for \(i= 1, \dots, n\), the Hessian \(\ell''(\pi)\) of the log-likelihood is negative definite for every \(\pi\in (0, 1)\), whatever the observed outcomes. Hence the log-likelihood is strictly concave on \((0, 1)\).
Proof. This is the solution to Exercise 52, worked in Solution 52. It builds on Theorem 25.
3.10 The maximum likelihood estimate
Exercise 53 (Maximum likelihood estimate of a binary sample) In the setting of Exercise 47, use Theorem 26 to find the maximum likelihood estimate \(\hat{\pi}_{\text{ML}}\) of \(\pi\).
Solution 53. By Theorem 26, \(\ell\) is strictly concave on \((0, 1)\). A strictly concave function that has a critical point is maximized there, and nowhere else. With \({\bar{y}}\in (0, 1)\), Theorem 23 says the only critical point of \(\ell\) in \((0, 1)\) is \({\bar{y}}\). So \(\ell\) is maximized at \(\pi= {\bar{y}}\).
Theorem 27 (Maximum likelihood estimate of a binary sample) If \(Y_i\ \sim_{\perp\!\!\!\perp}\ \operatorname{Ber}(\pi)\) for \(i= 1, \dots, n\) and the observed sample mean satisfies \({\bar{y}}\in (0, 1)\), the maximum likelihood estimate of \(\pi\) is the sample mean:
\[\hat{\pi}_{\text{ML}} = {\bar{y}}\]
Proof. This is the solution to Exercise 53, worked in Solution 53. It builds on Theorem 23 and Theorem 26.
4 Maximum likelihood for univariate Gaussian models
Suppose \(X_1, \ldots, X_n \ \sim_{\operatorname{iid}}\ {\operatorname{N}\mathopen{}\left(\mu, \sigma^2\right)\mathclose{}}\), and let \(x_1, \ldots, x_n\) be the observed values. The parameter vector is \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\theta}}\vphantom{\theta}}= (\mu, \sigma^2)\). We treat \(\sigma^2\), rather than \(\sigma\), as the second parameter, and differentiate with respect to \(\sigma^2\) directly.
By the likelihood of independent data, the likelihood is:
\[ \mathcal{L}(\mu, \sigma^2) = \prod_{i=1}^n(2\pi\sigma^2)^{-1/2} {\operatorname{exp}\mathopen{}\left\{-\frac{(x_i- \mu)^2}{2\sigma^2}\right\}\mathclose{}} \]
and by the log-likelihood of independent data, the log-likelihood is:
\[ \begin{aligned} \ell(\mu, \sigma^2) &= \sum_{i=1}^n{\operatorname{log}\mathopen{}\left\{(2\pi\sigma^2)^{-1/2} {\operatorname{exp}\mathopen{}\left\{-\frac{(x_i- \mu)^2}{2\sigma^2}\right\}\mathclose{}}\right\}\mathclose{}} && \text{(log of each Gaussian density)}\\ &= \sum_{i=1}^n\mathopen{}\left({\operatorname{log}\mathopen{}\left\{(2\pi\sigma^2)^{-1/2}\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{{\operatorname{exp}\mathopen{}\left\{-\frac{(x_i- \mu)^2}{2\sigma^2}\right\}\mathclose{}}\right\}\mathclose{}}\right)\mathclose{} && \text{(log of a product)}\\ &= \sum_{i=1}^n\mathopen{}\left(-\frac{1}{2}{\operatorname{log}\mathopen{}\left\{2\pi\sigma^2\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{{\operatorname{exp}\mathopen{}\left\{-\frac{(x_i- \mu)^2}{2\sigma^2}\right\}\mathclose{}}\right\}\mathclose{}}\right)\mathclose{} && \text{(log of a power)}\\ &= \sum_{i=1}^n\mathopen{}\left(-\frac{1}{2}{\operatorname{log}\mathopen{}\left\{2\pi\sigma^2\right\}\mathclose{}} - \frac{(x_i- \mu)^2}{2\sigma^2}\right)\mathclose{} && \text{($\operatorname{log}$ undoes $\operatorname{exp}$)}\\ &= \sum_{i=1}^n\mathopen{}\left(-\frac{1}{2}{\operatorname{log}\mathopen{}\left\{2\pi\sigma^2\right\}\mathclose{}}\right)\mathclose{} - \sum_{i=1}^n\frac{(x_i- \mu)^2}{2\sigma^2} && \text{(distribute the sum over the terms)}\\ &= -\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\sigma^2\right\}\mathclose{}} - \sum_{i=1}^n\frac{(x_i- \mu)^2}{2\sigma^2} && \text{(sum of $n$ identical terms)}\\ &= -\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\sigma^2\right\}\mathclose{}} - \frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2 && \text{(factor the constant $\tfrac{1}{2\sigma^2}$ out of the sum)}\\ &= -\frac{n}{2}\mathopen{}\left({\operatorname{log}\mathopen{}\left\{2\pi\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}}\right)\mathclose{} - \frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2 && \text{(log of a product)}\\ &= -\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\right\}\mathclose{}} - \frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}} - \frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2 && \text{(distribute $-\tfrac{n}{2}$)} \end{aligned} \]
4.1 The score function
The score function is the vector of the two partial derivatives:
\[ \ell'(\mu, \sigma^2) = \begin{pmatrix} \frac{\partial}{\partial \mu}\ell(\mu, \sigma^2) \\ \frac{\partial}{\partial \sigma^2}\ell(\mu, \sigma^2) \end{pmatrix} \]
For the first entry, only the last term of \(\ell\) depends on \(\mu\):
\[ \begin{aligned} \frac{\partial}{\partial \mu}\ell &= \frac{\partial}{\partial \mu}\mathopen{}\left(-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\right\}\mathclose{}} - \frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}} - \frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2\right)\mathclose{} && \text{(Gaussian log-likelihood)}\\ &= \frac{\partial}{\partial \mu}\mathopen{}\left(-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\right\}\mathclose{}}\right)\mathclose{} + \frac{\partial}{\partial \mu}\mathopen{}\left(-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}}\right)\mathclose{} + \frac{\partial}{\partial \mu}\mathopen{}\left(-\frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2\right)\mathclose{} && \text{(linearity of differentiation)}\\ &= 0 + 0 + \frac{\partial}{\partial \mu}\mathopen{}\left(-\frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2\right)\mathclose{} && \text{(derivative of a constant)}\\ &= \frac{\partial}{\partial \mu}\mathopen{}\left(-\frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2\right)\mathclose{} && \text{(drop the zero terms)}\\ &= -\frac{1}{2\sigma^2}\frac{\partial}{\partial \mu}\sum_{i=1}^n(x_i- \mu)^2 && \text{(constant multiple rule)}\\ &= -\frac{1}{2\sigma^2}\sum_{i=1}^n\frac{\partial}{\partial \mu}(x_i- \mu)^2 && \text{(derivative of a sum is the sum of derivatives)}\\ &= -\frac{1}{2\sigma^2}\sum_{i=1}^n2(x_i- \mu)\frac{\partial}{\partial \mu}(x_i- \mu) && \text{(chain rule, outer function $u^2$)} \end{aligned} \]
The inner derivative is:
\[ \begin{aligned} \frac{\partial}{\partial \mu}(x_i- \mu) &= \frac{\partial}{\partial \mu} x_i- \frac{\partial}{\partial \mu} \mu && \text{(linearity of differentiation)}\\ &= 0 - \frac{\partial}{\partial \mu} \mu && \text{($x_i$ does not depend on $\mu$)}\\ &= 0 - 1 && \text{(derivative of $\mu$ with respect to itself)}\\ &= -1 && \text{(subtract)} \end{aligned} \]
Substituting the inner derivative back in:
\[ \begin{aligned} \frac{\partial}{\partial \mu}\ell &= -\frac{1}{2\sigma^2}\sum_{i=1}^n2(x_i- \mu) \cdot (-1) && \text{(inner derivative is $-1$)}\\ &= -\frac{1}{2\sigma^2}\sum_{i=1}^n-2(x_i- \mu) && \text{(multiply)}\\ &= -\frac{1}{2\sigma^2} \cdot (-2) \sum_{i=1}^n(x_i- \mu) && \text{(factor the constant $-2$ out of the sum)}\\ &= \frac{1}{\sigma^2}\sum_{i=1}^n(x_i- \mu) && \text{(multiply the constants)}\\ &= \frac{1}{\sigma^2}\mathopen{}\left(\sum_{i=1}^nx_i- \sum_{i=1}^n\mu\right)\mathclose{} && \text{(distribute the sum over the terms)}\\ &= \frac{1}{\sigma^2}\mathopen{}\left(\sum_{i=1}^nx_i- n\mu\right)\mathclose{} && \text{(sum of $n$ copies of $\mu$)} \end{aligned} \]
For the second entry, write the population variance \(\sigma^2\) as a single variable \(v\), so that the log-likelihood \(\ell\) contains \(-\frac{n}{2}\log v\) and \(-\frac{1}{2}v^{-1} S\), where the sum of squared deviations \(S = {\sum_{i=1}^n\mathopen{}\left({\mathopen{}\left(\mathbb{D}_{\mu}\mathopen{}\left(x_i\right)\mathclose{}\right)\mathclose{}}^{2}\right)\mathclose{}}\) from the mean parameter \(\mu\) does not depend on \(\sigma^2\):
\[ \begin{aligned} \frac{\partial}{\partial \sigma^2}\ell &= \frac{\partial}{\partial \sigma^2}\mathopen{}\left(-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\right\}\mathclose{}} - \frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}} - \frac{1}{2}{\mathopen{}\left(\sigma^2\right)\mathclose{}}^{-1}S\right)\mathclose{} && \text{(Gaussian log-likelihood)}\\ &= \frac{\partial}{\partial \sigma^2}\mathopen{}\left(-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\right\}\mathclose{}}\right)\mathclose{} + \frac{\partial}{\partial \sigma^2}\mathopen{}\left(-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}}\right)\mathclose{} + \frac{\partial}{\partial \sigma^2}\mathopen{}\left(-\frac{1}{2}{\mathopen{}\left(\sigma^2\right)\mathclose{}}^{-1}S\right)\mathclose{} && \text{(linearity of differentiation)}\\ &= 0 + \frac{\partial}{\partial \sigma^2}\mathopen{}\left(-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}}\right)\mathclose{} + \frac{\partial}{\partial \sigma^2}\mathopen{}\left(-\frac{1}{2}{\mathopen{}\left(\sigma^2\right)\mathclose{}}^{-1}S\right)\mathclose{} && \text{(derivative of a constant)}\\ &= \frac{\partial}{\partial \sigma^2}\mathopen{}\left(-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}}\right)\mathclose{} + \frac{\partial}{\partial \sigma^2}\mathopen{}\left(-\frac{1}{2}{\mathopen{}\left(\sigma^2\right)\mathclose{}}^{-1}S\right)\mathclose{} && \text{(drop the zero term)}\\ &= \frac{\partial}{\partial \sigma^2}\mathopen{}\left(-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}}\right)\mathclose{} + \frac{\partial}{\partial \sigma^2}\mathopen{}\left(-\frac{1}{2}S {\mathopen{}\left(\sigma^2\right)\mathclose{}}^{-1}\right)\mathclose{} && \text{(reorder the factors)}\\ &= -\frac{n}{2}\frac{\partial}{\partial \sigma^2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}} - \frac{1}{2}S \frac{\partial}{\partial \sigma^2}{\mathopen{}\left(\sigma^2\right)\mathclose{}}^{-1} && \text{(constant multiple rule)}\\ &= -\frac{n}{2}{\mathopen{}\left(\sigma^2\right)\mathclose{}}^{-1} - \frac{1}{2}S \frac{\partial}{\partial \sigma^2}{\mathopen{}\left(\sigma^2\right)\mathclose{}}^{-1} && \text{(derivative of $\log v$)}\\ &= -\frac{n}{2}{\mathopen{}\left(\sigma^2\right)\mathclose{}}^{-1} - \frac{1}{2}S \mathopen{}\left(-{\mathopen{}\left(\sigma^2\right)\mathclose{}}^{-2}\right)\mathclose{} && \text{(power rule for $v^{-1}$)}\\ &= -\frac{n}{2}{\mathopen{}\left(\sigma^2\right)\mathclose{}}^{-1} + \frac{1}{2}S {\mathopen{}\left(\sigma^2\right)\mathclose{}}^{-2} && \text{(multiply)}\\ &= -\frac{n}{2}{\mathopen{}\left(\sigma^2\right)\mathclose{}}^{-1} + \frac{1}{2}{\mathopen{}\left(\sigma^2\right)\mathclose{}}^{-2}S && \text{(reorder the factors)} \end{aligned} \]
4.2 MLE of \(\mu\)
Setting \(\frac{\partial}{\partial \mu}\ell= 0\):
\[ \begin{aligned} 0 &= \frac{1}{\sigma^2}\mathopen{}\left(\sum_{i=1}^nx_i- n\mu\right)\mathclose{} && \text{(score for $\mu$)}\\ 0 &= \sum_{i=1}^nx_i- n\mu && \text{(multiply both sides by $\sigma^2$)}\\ n\mu&= \sum_{i=1}^nx_i && \text{(add $n\mu$ to both sides)}\\ \mu&= \frac{1}{n}\sum_{i=1}^nx_i && \text{(divide by $n$)}\\ \mu&= \bar x && \text{(definition of $\bar x$)} \end{aligned} \]
This solution does not depend on \(\sigma^2\). The second derivative is
\[ \begin{aligned} \frac{\partial^2 \ell}{\partial \mu^2} &= \frac{\partial}{\partial \mu}\mathopen{}\left(\frac{1}{\sigma^2}\mathopen{}\left(\sum_{i=1}^nx_i- n\mu\right)\mathclose{}\right)\mathclose{} && \text{(differentiate the score for $\mu$)}\\ &= \frac{1}{\sigma^2}\frac{\partial}{\partial \mu}\mathopen{}\left(\sum_{i=1}^nx_i- n\mu\right)\mathclose{} && \text{(constant multiple rule)}\\ &= \frac{1}{\sigma^2}\mathopen{}\left(\frac{\partial}{\partial \mu}\sum_{i=1}^nx_i- \frac{\partial}{\partial \mu}\mathopen{}\left(n\mu\right)\mathclose{}\right)\mathclose{} && \text{(linearity of differentiation)}\\ &= \frac{1}{\sigma^2}\mathopen{}\left(0 - \frac{\partial}{\partial \mu}\mathopen{}\left(n\mu\right)\mathclose{}\right)\mathclose{} && \text{($\textstyle\sum_{i=1}^nx_i$ does not depend on $\mu$)}\\ &= \frac{1}{\sigma^2}\mathopen{}\left(0 - n\frac{\partial}{\partial \mu}\mu\right)\mathclose{} && \text{(constant multiple rule)}\\ &= \frac{1}{\sigma^2}\mathopen{}\left(0 - n\right)\mathclose{} && \text{(derivative of $\mu$ with respect to itself)}\\ &= \frac{1}{\sigma^2}\mathopen{}\left(-n\right)\mathclose{} && \text{(subtract)}\\ &= -\frac{n}{\sigma^2} && \text{(multiply)}\\ &< 0, && \text{($n > 0$ and $\sigma^2> 0$)} \end{aligned} \]
so for every fixed \(\sigma^2\), \(\ell\) is maximized over \(\mu\) at \(\bar x\), and \(\hat{\mu}_{\text{ML}} = \bar x\).
4.3 The profile log-likelihood
Definition 21 (Profile log-likelihood) Split a parameter vector into \((\psi, \lambda)\), and for each fixed value of \(\psi\) let \(\hat{\lambda}(\psi)\) maximize \(\ell(\psi, \lambda)\) over \(\lambda\). The profile log-likelihood of \(\psi\) is
\[\ell_p(\psi) \stackrel{\text{def}}{=}{\ell\mathopen{}\left(\psi, \hat{\lambda}(\psi)\right)\mathclose{}}.\]
Example 18 (Profile log-likelihood of a Gaussian variance) In the Gaussian model, \(\hat{\mu}= \bar x\) maximizes \(\ell\) over \(\mu\) for every value of \(\sigma^2\) (Gaussian MLEs), so the profile log-likelihood of \(\sigma^2\) is
\[ \begin{aligned} \ell_p(\sigma^2) &= \ell(\bar x, \sigma^2) && \text{(definition of the profile log-likelihood)}\\ &= -\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\right\}\mathclose{}} - \frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}} - \frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \bar x)^2 && \text{(Gaussian log-likelihood at $\mu= \bar x$)} \end{aligned} \]
4.4 MLE of \(\sigma^2\)
Setting \(\frac{\partial}{\partial \sigma^2}\ell= 0\):
\[ \begin{aligned} 0 &= -\frac{n}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-1} + \frac{1}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\sum_{i=1}^n(x_i- \mu)^2 && \text{(score for $\sigma^2$)}\\ \frac{n}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-1} &= \frac{1}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\sum_{i=1}^n(x_i- \mu)^2 && \text{(add $\tfrac{n}{2}(\sigma^2)^{-1}$)}\\ n\sigma^2&= \sum_{i=1}^n(x_i- \mu)^2 && \text{(multiply both sides by $2(\sigma^2)^2$)}\\ \sigma^2&= \frac{1}{n}\sum_{i=1}^n(x_i- \mu)^2 && \text{(divide both sides by $n$)} \end{aligned} \]
Substituting the maximizer \(\mu= \bar x\), which does not depend on \(\sigma^2\), maximizes the profile log-likelihood of the Gaussian example, and gives:
\[\hat{\sigma}^2_{\text{ML}} = \frac{1}{n}\sum_{i=1}^n(x_i- \bar x)^2\]
The profile log-likelihood, \(\ell_p(\sigma^2) = -\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\right\}\mathclose{}} - \frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}} - \frac{n\hat{\sigma}^2_{\text{ML}}}{2\sigma^2}\), increases for \(\sigma^2< \hat{\sigma}^2_{\text{ML}}\) and decreases for \(\sigma^2> \hat{\sigma}^2_{\text{ML}}\), because its derivative, \(\frac{n}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\mathopen{}\left(\hat{\sigma}^2_{\text{ML}} - \sigma^2\right)\mathclose{}\), has the sign of \(\hat{\sigma}^2_{\text{ML}} - \sigma^2\). So \((\bar x, \hat{\sigma}^2_{\text{ML}})\) is the global maximizer, provided the \(x_i\) are not all equal.
Remark 13 (Differentiating with respect to the variance or the precision). Differentiating with respect to \(\sigma^2\) as a single variable, rather than with respect to \(\sigma\), keeps the algebra short. Replacing \(\sigma^2\) with the precision \(\tau\stackrel{\text{def}}{=}1/\sigma^2\) and differentiating with respect to \(\tau\) can be shorter still, because \(\tau\) enters the log-likelihood as \(\frac{n}{2}\log\tau- \frac{\tau}{2}\sum_{i=1}^n(x_i- \mu)^2\). By the invariance of maximum likelihood estimates, \(\hat{\tau}_{\text{ML}} = 1/\hat{\sigma}^2_{\text{ML}}\).
Remark 14 (The Gaussian variance MLE is biased). This MLE divides by \(n\), so it is a biased estimator of \(\sigma^2\) (bias of the divide-by-\(n\) estimator).
4.5 Second derivatives
The remaining second derivatives are:
\[ \begin{aligned} \frac{\partial^2 \ell}{\partial (\sigma^2)^2} &= \frac{\partial}{\partial \sigma^2}\mathopen{}\left(-\frac{n}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-1} + \frac{1}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\sum_{i=1}^n(x_i- \mu)^2\right)\mathclose{} && \text{(differentiate the score for $\sigma^2$)}\\ &= \frac{\partial}{\partial \sigma^2}\mathopen{}\left(-\frac{n}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-1}\right)\mathclose{} + \frac{\partial}{\partial \sigma^2}\mathopen{}\left(\frac{1}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\sum_{i=1}^n(x_i- \mu)^2\right)\mathclose{} && \text{(linearity of differentiation)}\\ &= \frac{\partial}{\partial \sigma^2}\mathopen{}\left(-\frac{n}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-1}\right)\mathclose{} + \frac{\partial}{\partial \sigma^2}\mathopen{}\left(\frac{1}{2}\sum_{i=1}^n(x_i- \mu)^2 \mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\right)\mathclose{} && \text{(reorder the factors)}\\ &= -\frac{n}{2}\frac{\partial}{\partial \sigma^2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-1} + \frac{1}{2}\sum_{i=1}^n(x_i- \mu)^2 \frac{\partial}{\partial \sigma^2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2} && \text{(constant multiple rule)}\\ &= -\frac{n}{2}\mathopen{}\left(-\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\right)\mathclose{} + \frac{1}{2}\sum_{i=1}^n(x_i- \mu)^2 \frac{\partial}{\partial \sigma^2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2} && \text{(power rule for $v^{-1}$)}\\ &= -\frac{n}{2}\mathopen{}\left(-\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\right)\mathclose{} + \frac{1}{2}\sum_{i=1}^n(x_i- \mu)^2 \mathopen{}\left(-2\mathopen{}\left(\sigma^2\right)\mathclose{}^{-3}\right)\mathclose{} && \text{(power rule for $v^{-2}$)}\\ &= \frac{n}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2} - \sum_{i=1}^n(x_i- \mu)^2 \mathopen{}\left(\sigma^2\right)\mathclose{}^{-3} && \text{(multiply the constants)}\\ &= \frac{n}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2} - \mathopen{}\left(\sigma^2\right)\mathclose{}^{-3}\sum_{i=1}^n(x_i- \mu)^2 && \text{(reorder the factors)}\\ \frac{\partial^2 \ell}{\partial \mu \partial \sigma^2} &= \frac{\partial}{\partial \mu}\mathopen{}\left(-\frac{n}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-1} + \frac{1}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\sum_{i=1}^n(x_i- \mu)^2\right)\mathclose{} && \text{(differentiate the score for $\sigma^2$)}\\ &= \frac{\partial}{\partial \mu}\mathopen{}\left(-\frac{n}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-1}\right)\mathclose{} + \frac{\partial}{\partial \mu}\mathopen{}\left(\frac{1}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\sum_{i=1}^n(x_i- \mu)^2\right)\mathclose{} && \text{(linearity of differentiation)}\\ &= 0 + \frac{\partial}{\partial \mu}\mathopen{}\left(\frac{1}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\sum_{i=1}^n(x_i- \mu)^2\right)\mathclose{} && \text{(derivative of a constant)}\\ &= \frac{\partial}{\partial \mu}\mathopen{}\left(\frac{1}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\sum_{i=1}^n(x_i- \mu)^2\right)\mathclose{} && \text{(drop the zero term)}\\ &= \frac{1}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\frac{\partial}{\partial \mu}\sum_{i=1}^n(x_i- \mu)^2 && \text{(constant multiple rule)}\\ &= \frac{1}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\sum_{i=1}^n\frac{\partial}{\partial \mu}(x_i- \mu)^2 && \text{(derivative of a sum is the sum of derivatives)}\\ &= \frac{1}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\sum_{i=1}^n-2(x_i- \mu) && \text{(chain-rule result from the score for $\mu$)}\\ &= \frac{1}{2}\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2} \cdot (-2) \sum_{i=1}^n(x_i- \mu) && \text{(factor the constant $-2$ out of the sum)}\\ &= -\mathopen{}\left(\sigma^2\right)\mathclose{}^{-2}\sum_{i=1}^n(x_i- \mu) && \text{(multiply the constants)} \end{aligned} \]
At the MLE, \(\sum_{i=1}^n(x_i- \bar x) = 0\) and \(\sum_{i=1}^n(x_i- \bar x)^2 = n\hat{\sigma}^2\) (writing \(\hat{\sigma}^2\) for \(\hat{\sigma}^2_{\text{ML}}\)), so:
\[ \begin{aligned} \left.{\frac{\partial^2 \ell}{\partial (\sigma^2)^2}}\right|_{\text{MLE}} &= \frac{n}{2}\mathopen{}\left(\hat{\sigma}^2\right)\mathclose{}^{-2} - \mathopen{}\left(\hat{\sigma}^2\right)\mathclose{}^{-3}\sum_{i=1}^n(x_i- \bar x)^2 && \text{(evaluate at $\mu= \bar x$, $\sigma^2= \hat{\sigma}^2$)}\\ &= \frac{n}{2}\mathopen{}\left(\hat{\sigma}^2\right)\mathclose{}^{-2} - \mathopen{}\left(\hat{\sigma}^2\right)\mathclose{}^{-3} n\hat{\sigma}^2 && \text{(substitute $\textstyle\sum_{i=1}^n(x_i- \bar x)^2 = n\hat{\sigma}^2$)}\\ &= \frac{n}{2}\mathopen{}\left(\hat{\sigma}^2\right)\mathclose{}^{-2} - n\mathopen{}\left(\hat{\sigma}^2\right)\mathclose{}^{-3}\hat{\sigma}^2 && \text{(reorder the factors)}\\ &= \frac{n}{2}\mathopen{}\left(\hat{\sigma}^2\right)\mathclose{}^{-2} - n\mathopen{}\left(\hat{\sigma}^2\right)\mathclose{}^{-2} && \text{(cancel one factor of $\hat{\sigma}^2$)}\\ &= -\frac{n}{2}\mathopen{}\left(\hat{\sigma}^2\right)\mathclose{}^{-2} && \text{(combine like terms)}\\ \left.{\frac{\partial^2 \ell}{\partial \mu \partial \sigma^2}}\right|_{\text{MLE}} &= -\mathopen{}\left(\hat{\sigma}^2\right)\mathclose{}^{-2}\sum_{i=1}^n(x_i- \bar x) && \text{(evaluate at $\mu= \bar x$, $\sigma^2= \hat{\sigma}^2$)}\\ &= -\mathopen{}\left(\hat{\sigma}^2\right)\mathclose{}^{-2} \cdot 0 && \text{(substitute $\textstyle\sum_{i=1}^n(x_i- \bar x) = 0$)}\\ &= 0 && \text{(multiply by zero)} \end{aligned} \]
4.6 Information matrix and standard errors
Collecting the second derivatives at the MLE, the observed information is
\[ I(\hat{\mu}, \hat{\sigma}^2) = \begin{bmatrix} \frac{n}{\hat{\sigma}^2} & 0 \\ 0 & \frac{n}{2\mathopen{}\left(\hat{\sigma}^2\right)\mathclose{}^2} \end{bmatrix} \]
Its diagonal entries are positive and its off-diagonal entries are zero, so it is positive definite, consistent with the MLE being a maximum. The inverse of a diagonal matrix inverts each diagonal entry, so:
\[ {\mathopen{}\left(I(\hat{\mu}, \hat{\sigma}^2)\right)\mathclose{}}^{-1} = \begin{bmatrix} \frac{\hat{\sigma}^2}{n} & 0 \\ 0 & \frac{2\mathopen{}\left(\hat{\sigma}^2\right)\mathclose{}^2}{n} \end{bmatrix} \]
By the asymptotic distribution of the MLE, the estimated standard errors are \({\mathop{\widehat{\operatorname{SE}}}\nolimits\mathopen{}\left(\hat{\mu}\right)\mathclose{}} = \hat{\sigma}/\sqrt{n}\) and \({\mathop{\widehat{\operatorname{SE}}}\nolimits\mathopen{}\left(\hat{\sigma}^2\right)\mathclose{}} = \hat{\sigma}^2\sqrt{2/n}\), and the two estimates are approximately uncorrelated in large samples.
5 Example: hormone therapy study
This example fits a Gaussian model to real data by maximum likelihood, and then uses simulation to examine the properties of maximum likelihood estimation for that model.
5.0.1 Data
The “heart and estrogen/progestin study” (HERS) was a clinical trial of hormone therapy for prevention of recurrent heart attacks and death among 2,763 post-menopausal women with existing coronary heart disease (CHD) [24].
The trial was conducted at 20 US clinical centers. Participants were randomized to receive either conjugated equine estrogens (0.625 mg/day) plus medroxyprogesterone acetate (2.5 mg/day) or a matching placebo [24]. Women were followed for an average of 4.1 years [24].
The primary outcome was nonfatal myocardial infarction or CHD death [24].
We model the distribution of fasting glucose among HERS participants who do not have diabetes and do not exercise.
The HERS data are distributed with Vittinghoff et al. [25] on the book’s companion website:
The rmb R package includes the same file, which these notes use so that rendering does not depend on the website (Table 5):
To keep the likelihood graphs readable, we use only the first 100 eligible participants (Figure 14); with the whole subset, the likelihood would be too concentrated to graph clearly.
[Code]
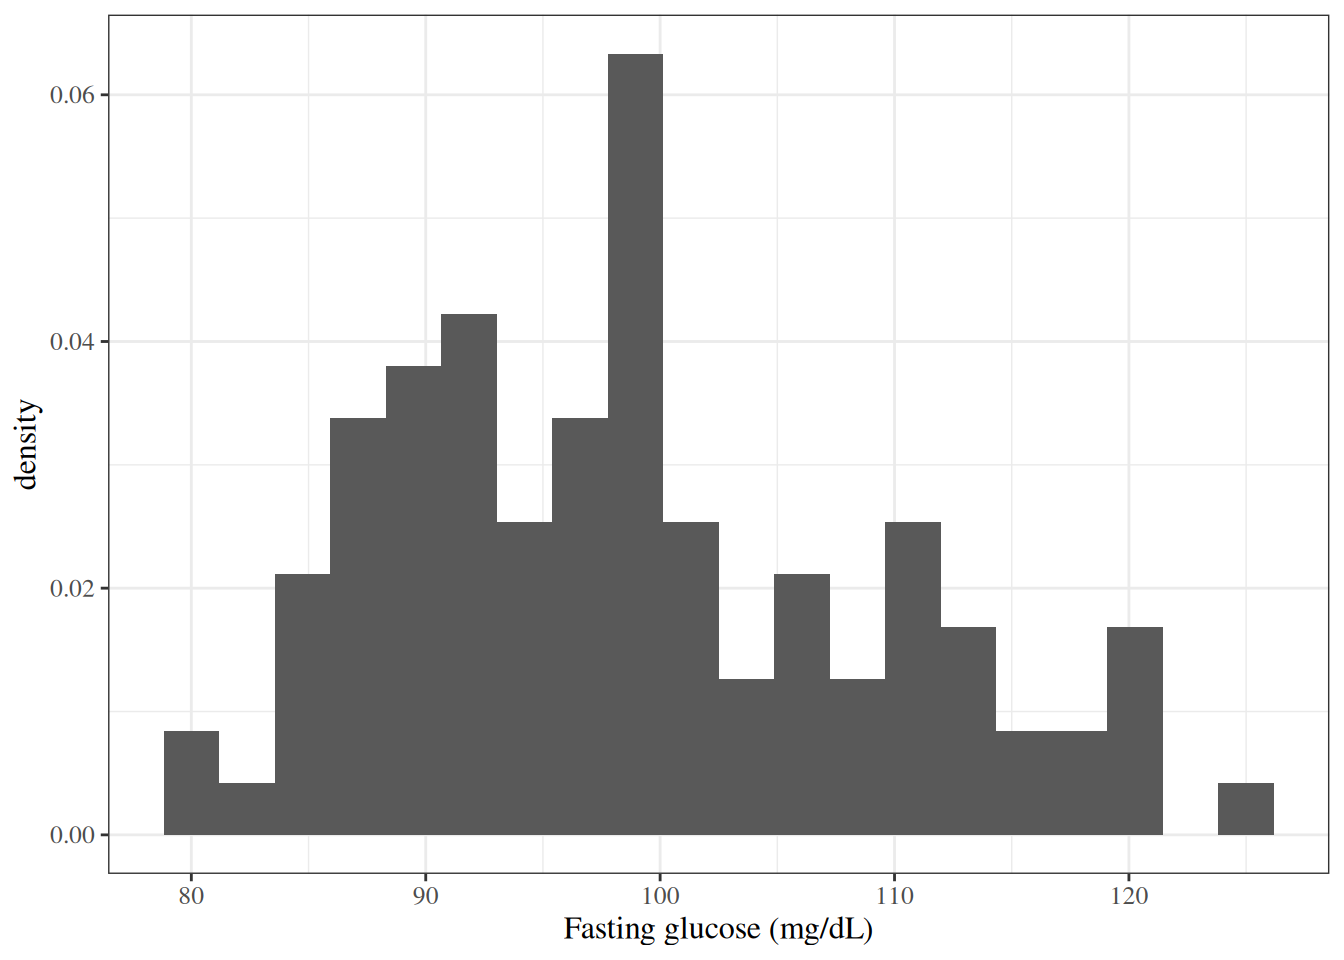
The histogram is irregular, as histograms of 100 observations often are, with a somewhat longer right tail than left tail. A Gaussian model is a rough but usable starting point.
5.0.2 Maximum likelihood estimates
By the Gaussian MLEs, \(\hat{\mu}_{\text{ML}} = \bar x\) and \(\hat{\sigma}^2_{\text{ML}} = \frac{1}{n}\sum_i (x_i- \bar x)^2\):
Figure 15 superimposes the fitted Gaussian density on the histogram.
[Code]
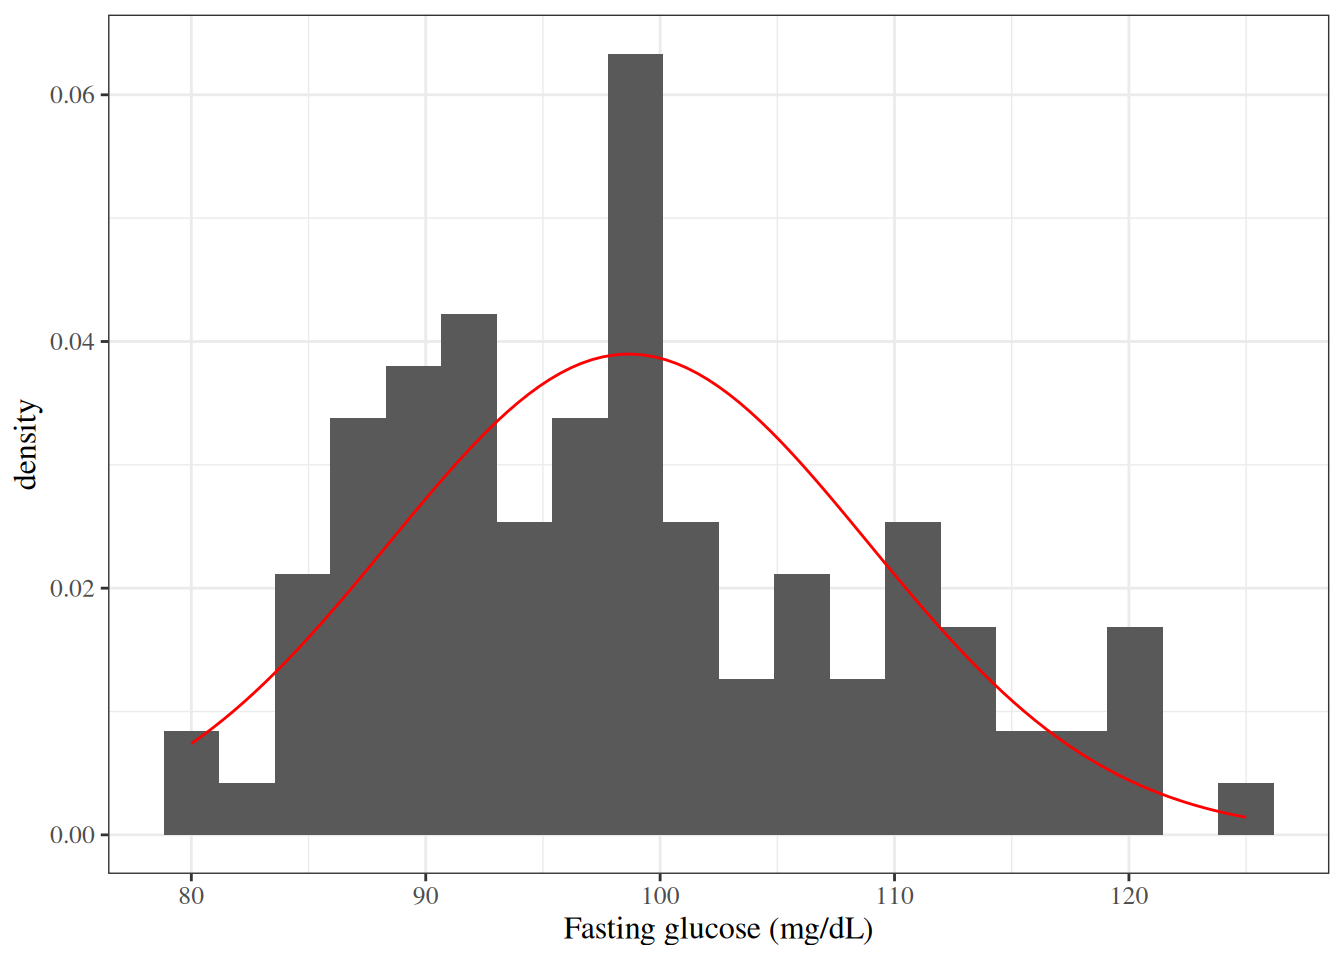
The fitted curve follows the overall shape of the histogram, but it underestimates the frequency of values between 110 and 122 mg/dL, consistent with the histogram’s longer right tail.
5.0.3 Likelihood and log-likelihood functions
It is numerically better to compute the log-likelihood first and exponentiate it to get the likelihood, because a product of 100 densities can underflow to zero:
loglik <- function(mu, sigma, x) {
  n <- length(x)
  normalizing_constant <- -n / 2 * log(2 * pi * sigma^2)
  # written with sum(x), sum(x^2) so that `mu` can be a vector of values:
  kernel <- -1 / (2 * sigma^2) * (sum(x^2) - 2 * sum(x) * mu + n * mu^2)
  normalizing_constant + kernel
}

lik <- function(...) exp(loglik(...))

# log-likelihood at the MLEs:
loglik(mu = mu_hat, sigma = sigma_hat, x = glucose_data)
#> [1] -374.47
Figure 16 graphs the likelihood and log-likelihood as functions of \(\mu\), with \(\sigma\) fixed at \(\hat{\sigma}_{\text{ML}}\).
[Code]
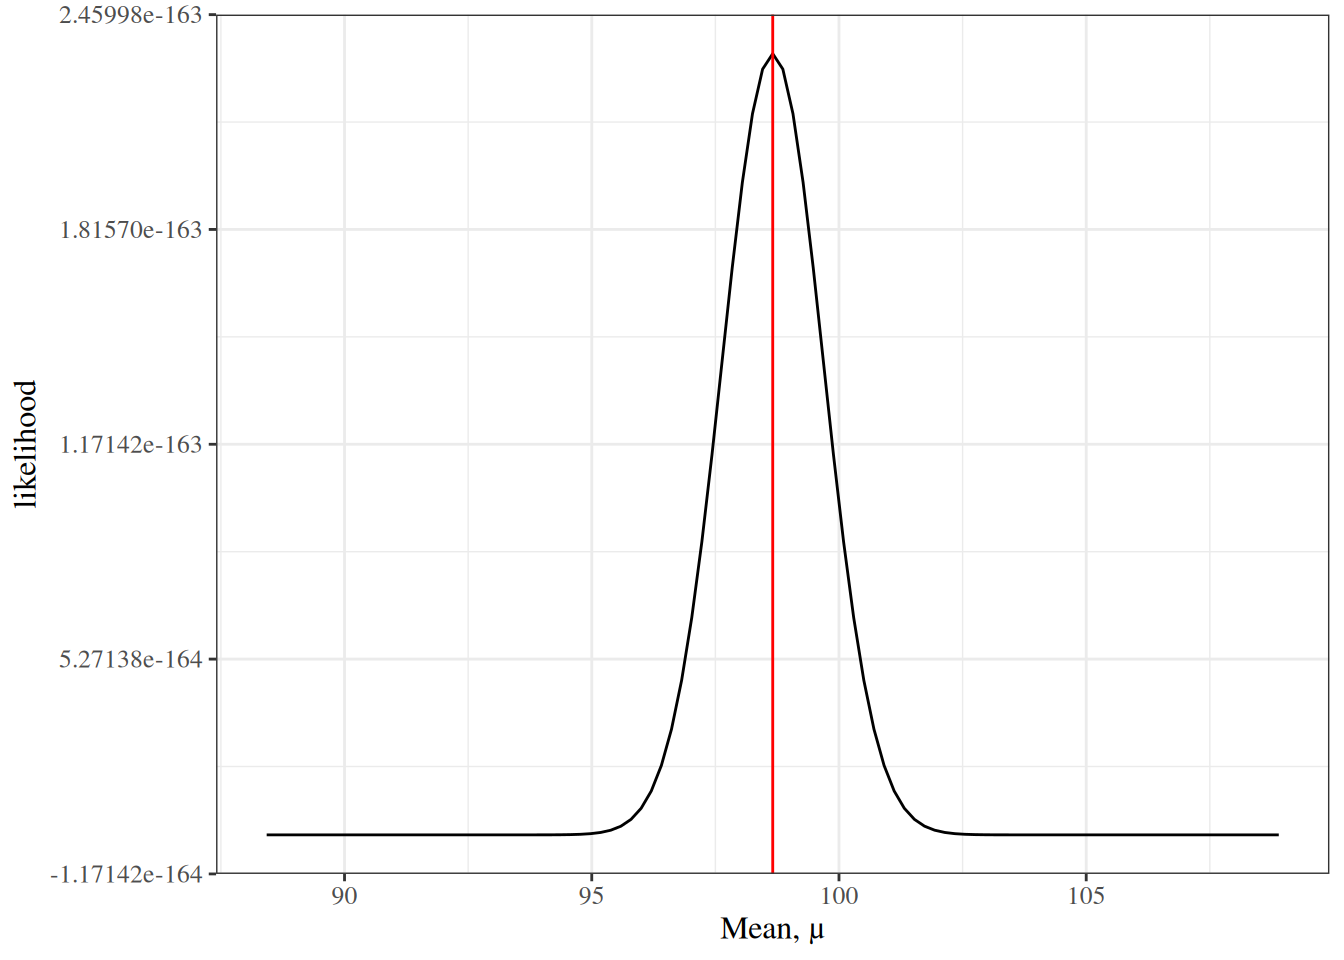
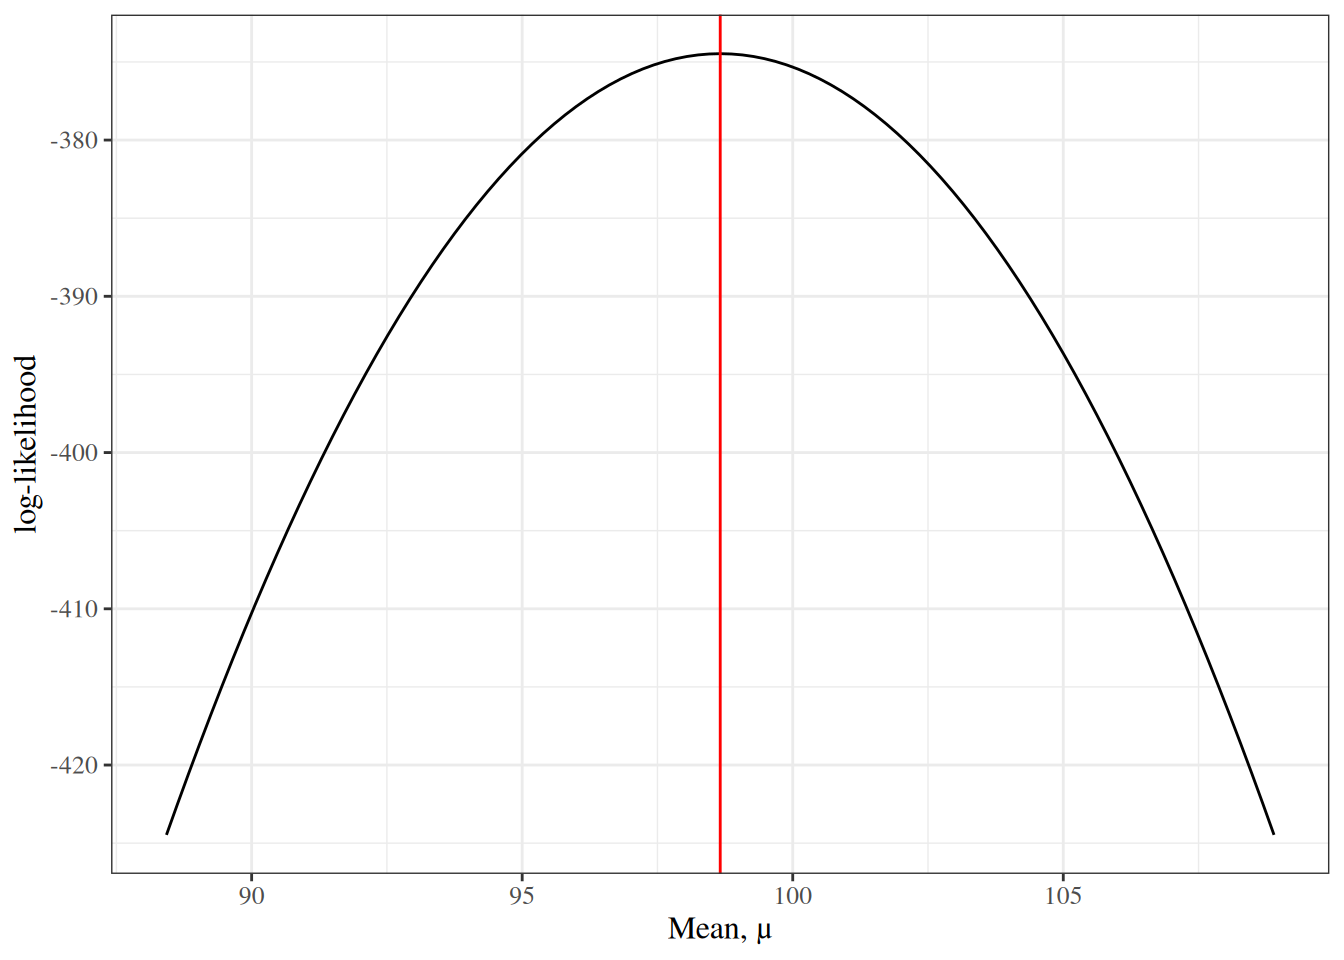
Figure 17 graphs them as functions of \(\sigma\), with \(\mu\) fixed at \(\hat{\mu}_{\text{ML}}\).
[Code]
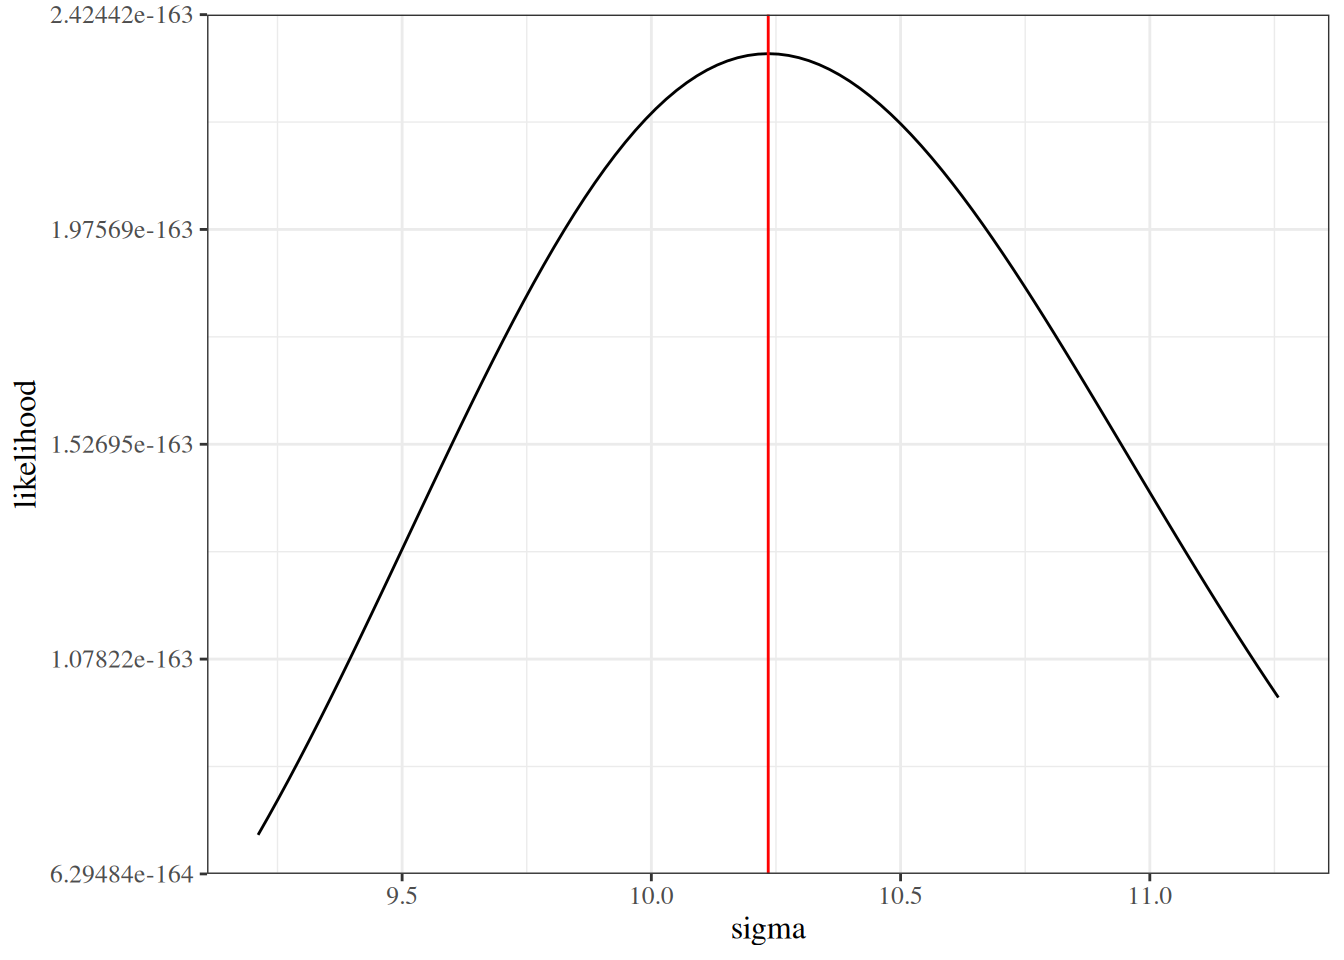
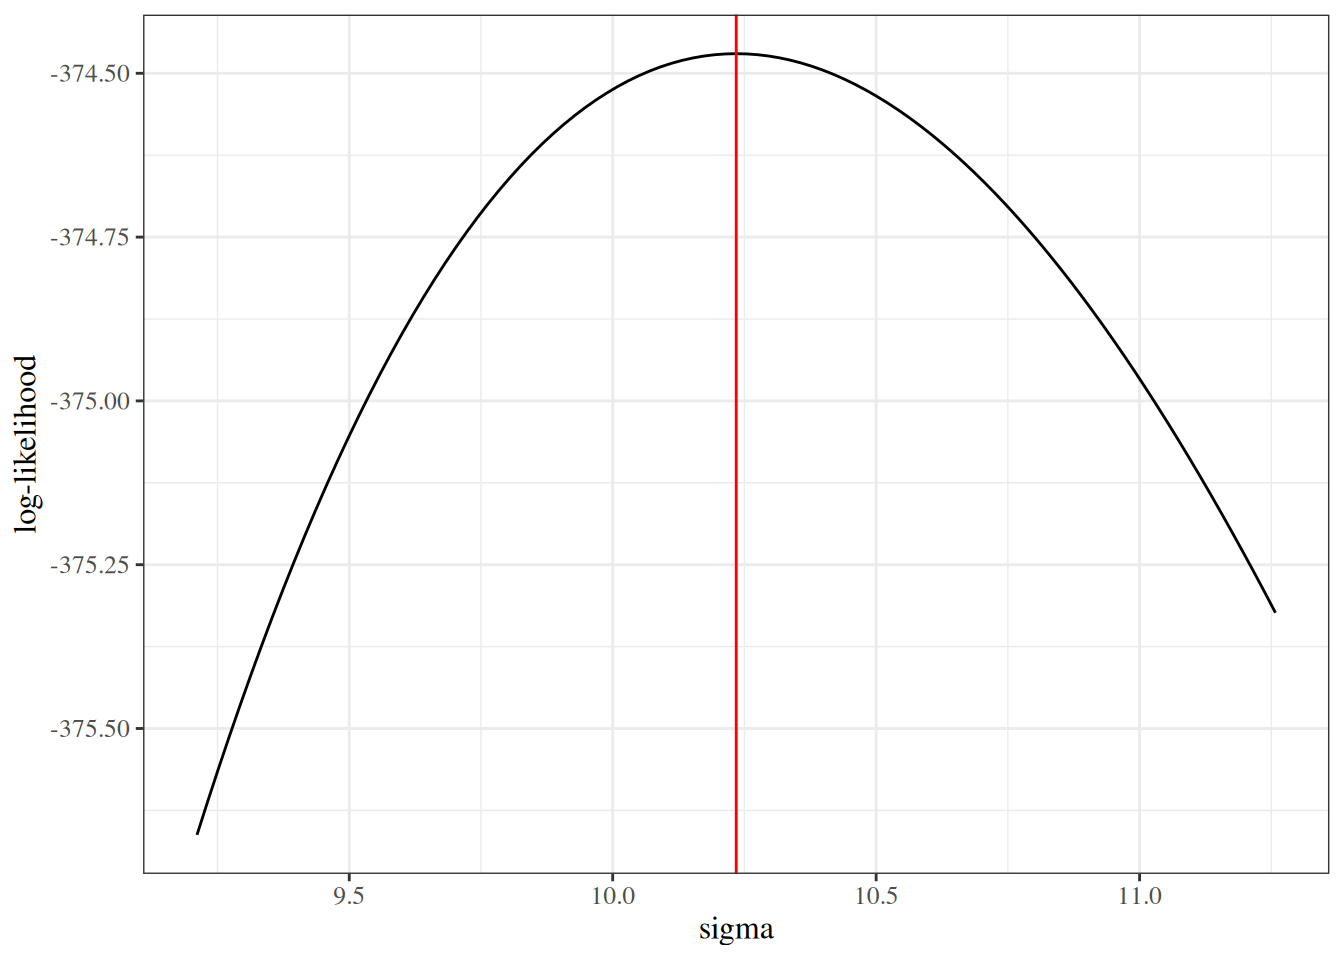
5.0.4 Log-likelihood surface
Figure 18 graphs the log-likelihood over both parameters at once.
[Code]
n_points <- 25
mu_grid <- seq(94, 104, length.out = n_points)
sigma_grid <- seq(7, 15, length.out = n_points)
lliks <- outer(mu_grid, sigma_grid, loglik, x = glucose_data)

plotly::plot_ly(
  type = "surface",
  x = ~mu_grid,
  y = ~sigma_grid,
  # plot_ly() expects rows of z to correspond to y values,
  # so the matrix is transposed;
  # see https://stackoverflow.com/questions/69472185
  z = ~ t(lliks)
) |>
  plotly::layout(
    scene = list(
      xaxis = list(title = "Mean, μ"),
      yaxis = list(title = "sigma"),
      zaxis = list(title = "log-likelihood")
    )
)5.0.5 Standard errors by sample size
By the covariance matrix of the Gaussian MLEs, the estimated standard error of \(\hat{\mu}_{\text{ML}}\) is
\[ \begin{aligned} {\mathop{\widehat{\operatorname{SE}}}\nolimits\mathopen{}\left(\hat{\mu}\right)\mathclose{}} &= \sqrt{\mathopen{}\left[{\mathopen{}\left(I(\hat{\mu}, \hat{\sigma}^2)\right)\mathclose{}}^{-1}\right]\mathclose{}_{11}} && \text{(estimated standard error from the inverse information)}\\ &= \sqrt{\frac{\hat{\sigma}^2}{n}} && \text{(first diagonal entry of the inverse information)}\\ &= \frac{\hat{\sigma}}{\sqrt{n}} && \text{(square root of a quotient)} \end{aligned} \]
which shrinks in proportion to \(1/\sqrt{n}\) (Figure 19).
[Code]
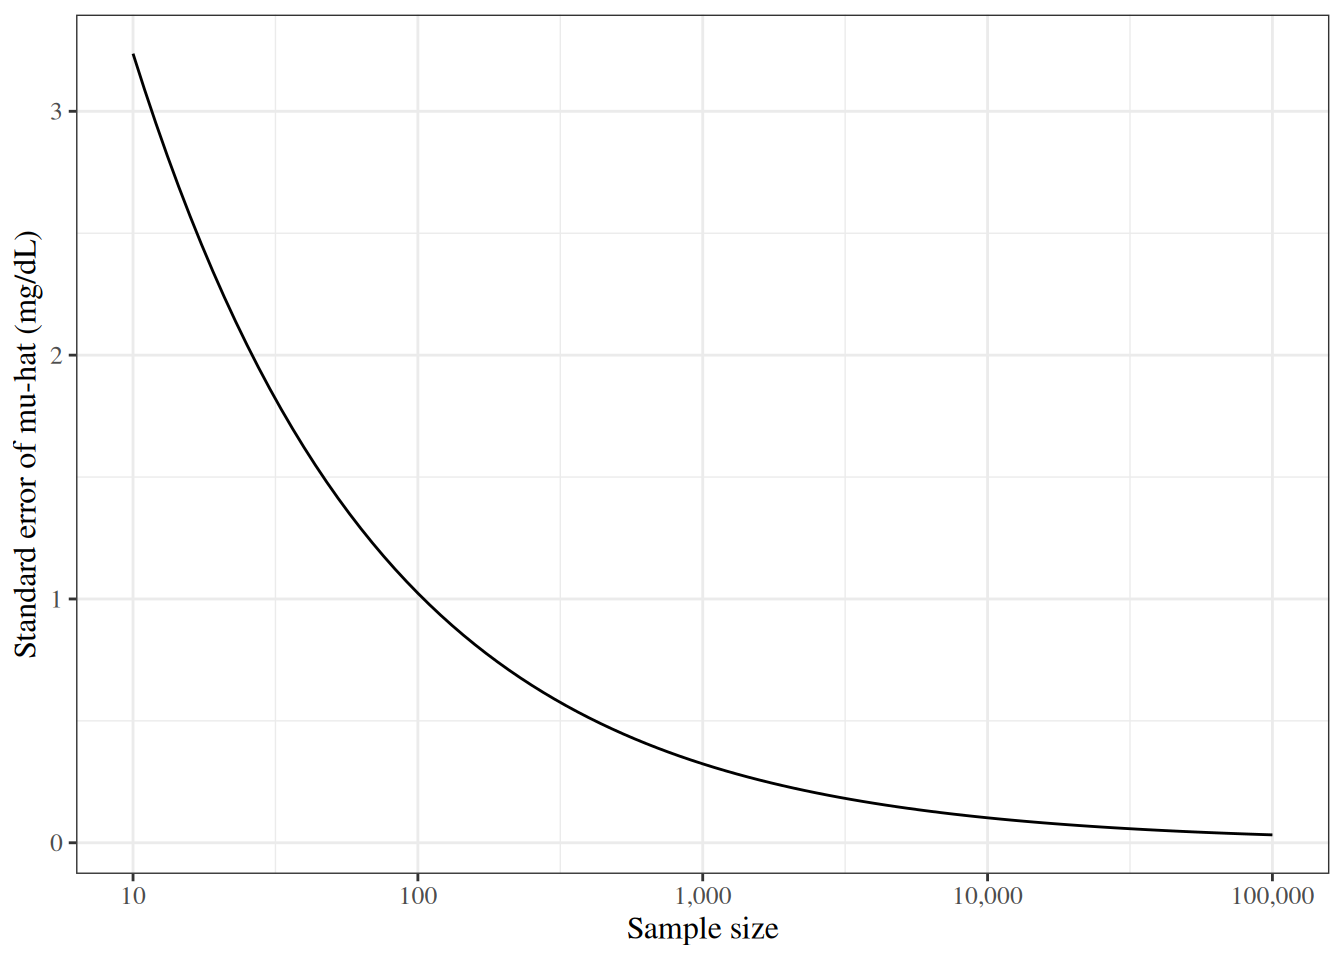
5.0.6 Power
Suppose we test the null hypothesis \(H_0: \mu= \mu_0\), with \(\mu_0 = 95\) mg/dL, at significance level \(\alpha= 0.05\), and suppose for simplicity that \(\sigma\) is known, equal to \(\hat{\sigma}_{\text{ML}}\). Then under \(H_0\), \(\bar X \sim {\operatorname{N}\mathopen{}\left(\mu_0, \sigma^2/n\right)\mathclose{}}\), and the test rejects \(H_0\) when \(\bar x\) falls outside the non-rejection interval
\[\mu_0 \pm z_{1 - \alpha/2} \frac{\sigma}{\sqrt{n}}\]
Definition 22 (Power) The power of a test of a null hypothesis \(H_0\) about a parameter \(\theta\), against an alternative value \(\theta_1\), is the probability that the test rejects \(H_0\) when \(\theta\) equals \(\theta_1\):
\[\text{power}(\theta_1) \stackrel{\text{def}}{=}{\Pr\mathopen{}\left(\text{reject } H_0 \mid \theta= \theta_1\right)\mathclose{}}.\]
For this test, under \(\mu= \mu_1\), \(\bar X \sim {\operatorname{N}\mathopen{}\left(\mu_1, \sigma^2/n\right)\mathclose{}}\), so:
\[ \text{power}(\mu_1) = \Phi\mathopen{}\left(\frac{\mu_0 - z_{1-\alpha/2}\,\sigma/\sqrt{n} - \mu_1}{\sigma/\sqrt{n}}\right)\mathclose{} + 1 - \Phi\mathopen{}\left(\frac{\mu_0 + z_{1-\alpha/2}\,\sigma/\sqrt{n} - \mu_1}{\sigma/\sqrt{n}}\right)\mathclose{} \]
where \(\Phi\) is the standard Gaussian CDF. For example, the power against \(\mu_1 = 100\) mg/dL is:
Figure 20 graphs the power as a function of the sample size.
[Code]
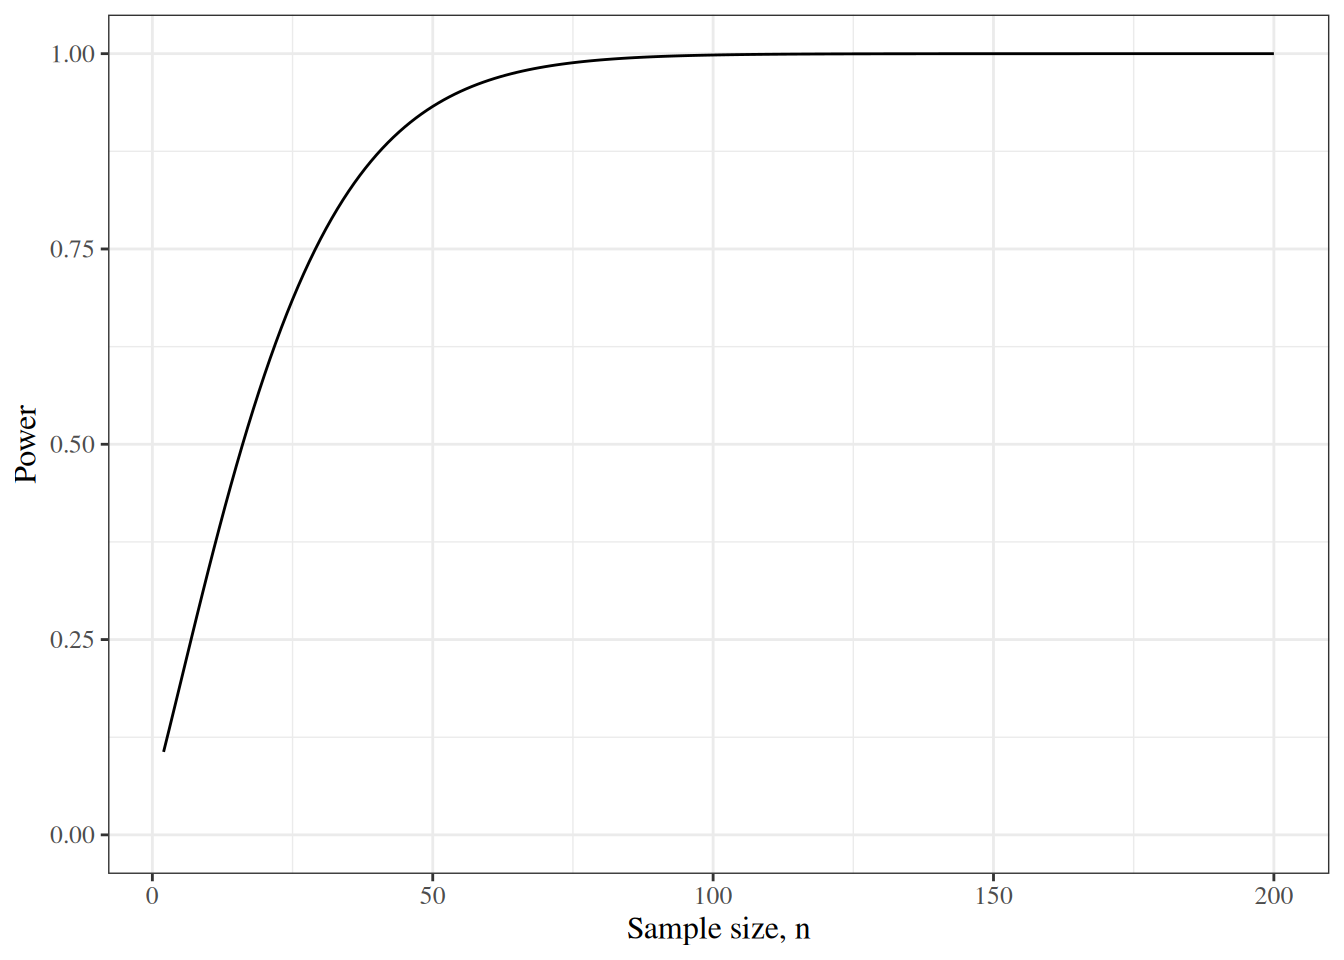
Remark 15 (Choosing the alternative, and observed power). The alternative \(\mu_1\) should be chosen before seeing the data, as a difference worth detecting. Power computed at \(\mu_1 = \hat{\mu}\) (“observed power”) is a function of the p-value, so it adds no information about the data already analyzed [26].
5.0.7 Simulation
To check how maximum likelihood estimation behaves for this model, we simulate many datasets from a Gaussian distribution whose parameters equal the HERS estimates, analyze each one, and summarize the results.
do_one_sim() simulates and analyzes one dataset: it computes \(\hat{\mu}\), its estimated standard error, a 95% \(t\)-based confidence interval for \(\mu\), and the \(t\)-test of \(H_0: \mu= \mu_0\).
do_one_sim <- function(n, mu, mu0, sigma2, return_data = FALSE) {
  # generate data
  x <- rnorm(n = n, mean = mu, sd = sqrt(sigma2))

  # analyze data
  est <- mean(x)
  se_est <- sd(x) / sqrt(n)
  confint <- est + c(-1, 1) * se_est * qt(0.975, df = n - 1)
  tstat <- abs(est - mu0) / se_est
  pval <- 2 * pt(q = tstat, df = n - 1, lower.tail = FALSE)

  results <- tibble::tibble(
    mu_hat = est,
    sigma_hat = sd(x),
    se_hat = se_est,
    confint_left = confint[1],
    confint_right = confint[2],
    tstat = tstat,
    pval = pval,
    confint_covers = dplyr::between(mu, confint[1], confint[2]),
    test_rejects = pval < 0.05
  )

  if (return_data) {
    list(data = x, results = results)
  } else {
    results
  }
}

# one small example dataset:
set.seed(0)
do_one_sim(n = 10, mu = 0, mu0 = 0, sigma2 = 1)
To check do_one_sim(), we compare its output with stats::t.test() on the same simulated data:
set.seed(1)
sim_output <- do_one_sim(
  n = 100, mu = mu_hat, mu0 = 80, sigma2 = sigma_sq_hat,
  return_data = TRUE
)
t_test <- t.test(sim_output$data, mu = 80)

dplyr::bind_rows(
  `do_one_sim()` = sim_output$results |>
    dplyr::select(mu_hat, se_hat, confint_left, confint_right, pval),
  `t.test()` = tibble::tibble(
    mu_hat = unname(t_test$estimate),
    se_hat = t_test$stderr,
    confint_left = t_test$conf.int[1],
    confint_right = t_test$conf.int[2],
    pval = t_test$p.value
  ),
  .id = "source"
)
The two rows agree.
do_n_sims() repeats the simulation n_sims times, with a different random seed for each dataset:
do_n_sims <- function(n_sims = 1000, ...) {
  lapply(seq_len(n_sims), function(i) {
    set.seed(i)
    do_one_sim(...) |>
      dplyr::mutate(sim_number = i, .before = dplyr::everything())
  }) |>
    dplyr::bind_rows()
}

sim_results <- do_n_sims(
  n_sims = 1000,
  n = 100, mu = mu_hat, mu0 = 0.9 * mu_hat, sigma2 = sigma_sq_hat
)
sim_results
summarize_sim() compares the simulation results with the true data-generating parameters:
summarize_sim <- function(sim_results, mu, sigma2, n) {
  true_se <- sqrt(sigma2 / n)
  tibble::tibble(
    bias_mu_hat = mean(sim_results$mu_hat) - mu,
    sd_mu_hat = sd(sim_results$mu_hat),
    true_se = true_se,
    bias_se_hat = mean(sim_results$se_hat) - true_se,
    coverage = mean(sim_results$confint_covers),
    power = mean(sim_results$test_rejects)
  )
}

sim_summary <- summarize_sim(
  sim_results,
  mu = mu_hat, sigma2 = sigma_sq_hat, n = 100
)
sim_summary
Across 1000 simulated datasets:
- the sample mean of the estimation error of \(\hat{\mu}\) over these datasets is -0.005 mg/dL, small relative to its standard error of 1.02 mg/dL, consistent with \(\hat{\mu}\) being unbiased;
- the standard deviation of the \(\hat{\mu}\) values, 0.996, is close to the true standard error;
- the 95% confidence intervals covered the true \(\mu\) in 95.9% of datasets, close to their nominal 95%;
- the test of \(H_0: \mu= 0.9\,\hat{\mu}\) rejected in 100% of datasets: with \(n = 100\), a 10% difference in the population mean is easy to detect.
Changing the sample size, the true \(\mu\), or \(\sigma^2\) in do_n_sims() shows how these properties depend on them.
6 Practice exercises
Exercise 54 (Binomial likelihood (adapted from Dobson and Barnett [1], Chapter 3)) Let \(Y \sim \text{Binomial}(n, \pi)\), so that
\[ \mathbb{p}(Y = y \mid \pi) = \binom{n}{y} \pi^y (1-\pi)^{n-y}, \quad y \in \{0, 1, \ldots, n\}. \]
Assume \(0 < y < n\) so the MLE lies in the interior of \((0, 1)\).
(a) Write the log-likelihood \(\ell(\pi; y)\) for a single observation \(y\).
(b) Derive the score function \(\ell'(\pi; y) \stackrel{\text{def}}{=}\frac{\partial}{\partial \pi}\ell(\pi; y)\).
(c) Set the score equal to zero and solve for \(\hat{\pi}_{ML}\). Confirm that \(\hat{\pi}_{ML} = y/n\).
(d) Compute the second derivative \(\ell''(\pi; y)\) and verify that it is negative, confirming a maximum.
Solution 54. (a)
\[ \begin{aligned} \ell(\pi; y) &= {\operatorname{log}\mathopen{}\left\{\binom{n}{y} \pi^y (1-\pi)^{n-y}\right\}\mathclose{}} && \text{(log of the binomial PMF)} \\ &= {\operatorname{log}\mathopen{}\left\{\binom{n}{y}\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{\pi^y\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{(1-\pi)^{n-y}\right\}\mathclose{}} && \text{(log of a product)} \\ &= {\operatorname{log}\mathopen{}\left\{\binom{n}{y}\right\}\mathclose{}} + y{\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} + (n-y){\operatorname{log}\mathopen{}\left\{1-\pi\right\}\mathclose{}} && \text{(log of a power)} \end{aligned} \]
The first term does not depend on \(\pi\), so it drops out of every derivative with respect to \(\pi\).
(b)
\[ \begin{aligned} \ell'(\pi; y) &= \frac{\partial}{\partial \pi}\mathopen{}\left[{\operatorname{log}\mathopen{}\left\{\binom{n}{y}\right\}\mathclose{}} + y{\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} + (n-y){\operatorname{log}\mathopen{}\left\{1-\pi\right\}\mathclose{}}\right]\mathclose{} && \text{(log-likelihood from (a))} \\ &= \frac{\partial}{\partial \pi}{\operatorname{log}\mathopen{}\left\{\binom{n}{y}\right\}\mathclose{}} + \frac{\partial}{\partial \pi}\mathopen{}\left[y{\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}}\right]\mathclose{} + \frac{\partial}{\partial \pi}\mathopen{}\left[(n-y){\operatorname{log}\mathopen{}\left\{1-\pi\right\}\mathclose{}}\right]\mathclose{} && \text{(linearity of differentiation)} \\ &= 0 + \frac{\partial}{\partial \pi}\mathopen{}\left[y{\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}}\right]\mathclose{} + \frac{\partial}{\partial \pi}\mathopen{}\left[(n-y){\operatorname{log}\mathopen{}\left\{1-\pi\right\}\mathclose{}}\right]\mathclose{} && \text{(derivative of a constant)} \\ &= \frac{\partial}{\partial \pi}\mathopen{}\left[y{\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}}\right]\mathclose{} + \frac{\partial}{\partial \pi}\mathopen{}\left[(n-y){\operatorname{log}\mathopen{}\left\{1-\pi\right\}\mathclose{}}\right]\mathclose{} && \text{(drop the zero term)} \\ &= y\frac{\partial}{\partial \pi}{\operatorname{log}\mathopen{}\left\{\pi\right\}\mathclose{}} + (n-y)\frac{\partial}{\partial \pi}{\operatorname{log}\mathopen{}\left\{1-\pi\right\}\mathclose{}} && \text{(constant multiple rule)} \\ &= y\frac{1}{\pi} + (n-y)\frac{\partial}{\partial \pi}{\operatorname{log}\mathopen{}\left\{1-\pi\right\}\mathclose{}} && \text{(derivative of $\log$)} \\ &= y\frac{1}{\pi} + (n-y)\frac{1}{1-\pi}\frac{\partial}{\partial \pi}(1-\pi) && \text{(chain rule)} \end{aligned} \]
The inner derivative is:
\[ \begin{aligned} \frac{\partial}{\partial \pi}(1-\pi) &= \frac{\partial}{\partial \pi} 1 - \frac{\partial}{\partial \pi} \pi && \text{(linearity of differentiation)} \\ &= 0 - \frac{\partial}{\partial \pi} \pi && \text{(derivative of a constant)} \\ &= 0 - 1 && \text{(derivative of $\pi$ with respect to itself)} \\ &= -1 && \text{(subtract)} \end{aligned} \]
Substituting the inner derivative back in:
\[ \begin{aligned} \ell'(\pi; y) &= y\frac{1}{\pi} + (n-y)\frac{1}{1-\pi}(-1) && \text{(inner derivative is $-1$)} \\ &= y\frac{1}{\pi} - (n-y)\frac{1}{1-\pi} && \text{(multiply by $-1$)} \\ &= \frac{y}{\pi} - \frac{n-y}{1-\pi} && \text{(multiply)} \\ &= \frac{y(1-\pi)}{\pi(1-\pi)} - \frac{(n-y)\pi}{\pi(1-\pi)} && \text{(write both terms over the common denominator)} \\ &= \frac{y(1-\pi) - (n-y)\pi}{\pi(1-\pi)} && \text{(combine the fractions)} \\ &= \frac{y - y\pi- n\pi+ y\pi}{\pi(1-\pi)} && \text{(expand the numerator)} \\ &= \frac{y - n\pi}{\pi(1-\pi)} && \text{(cancel $y\pi$)} \end{aligned} \]
(c)
Setting \(\ell'(\pi; y) = 0\):
\[ \begin{aligned} 0 &= \frac{y - n\pi}{\pi(1-\pi)} && \text{(score from (b))} \\ 0 &= y - n\pi && \text{(multiply both sides by $\pi(1-\pi)$)} \\ y &= n\pi && \text{(add $n\pi$ to both sides)} \\ \hat{\pi}_{ML} &= \frac{y}{n} && \text{(divide both sides by $n$)} \end{aligned} \]
(d)
\[ \begin{aligned} \ell''(\pi; y) &= \frac{\partial}{\partial \pi}\mathopen{}\left[\frac{y}{\pi} - \frac{n-y}{1-\pi}\right]\mathclose{} && \text{(score from (b))} \\ &= \frac{\partial}{\partial \pi}\mathopen{}\left[y\pi^{-1} - (n-y)(1-\pi)^{-1}\right]\mathclose{} && \text{(write the fractions as negative powers)} \\ &= \frac{\partial}{\partial \pi}\mathopen{}\left[y\pi^{-1}\right]\mathclose{} - \frac{\partial}{\partial \pi}\mathopen{}\left[(n-y)(1-\pi)^{-1}\right]\mathclose{} && \text{(linearity of differentiation)} \\ &= y\frac{\partial}{\partial \pi}\pi^{-1} - (n-y)\frac{\partial}{\partial \pi}(1-\pi)^{-1} && \text{(constant multiple rule)} \\ &= y\mathopen{}\left(-\pi^{-2}\right)\mathclose{} - (n-y)\frac{\partial}{\partial \pi}(1-\pi)^{-1} && \text{(power rule)} \\ &= y\mathopen{}\left(-\pi^{-2}\right)\mathclose{} - (n-y)\mathopen{}\left(-(1-\pi)^{-2}\right)\mathclose{}\frac{\partial}{\partial \pi}(1-\pi) && \text{(chain rule, outer function $u^{-1}$)} \\ &= y\mathopen{}\left(-\pi^{-2}\right)\mathclose{} - (n-y)\mathopen{}\left(-(1-\pi)^{-2}\right)\mathclose{}(-1) && \text{(inner derivative from (b) is $-1$)} \\ &= -y\pi^{-2} - (n-y)(1-\pi)^{-2} && \text{(multiply)} \\ &= -\frac{y}{\pi^2} - \frac{n-y}{(1-\pi)^2} && \text{(write the negative powers as fractions)} \end{aligned} \]
Since \(y \geq 0\), \(n - y \geq 0\), and \(y\) and \(n - y\) are not both zero, \(\ell''(\pi; y) < 0\) for every \(\pi\in (0,1)\). So \(\ell\) is strictly concave, and its critical point \(\hat{\pi}_{ML} = y/n\) is its global maximum.
Exercise 55 (Gaussian log-likelihood (adapted from Kleinbaum et al. [27], Chapter 5)) Let \(X_1, \ldots, X_n \ \sim_{\operatorname{iid}}\ \operatorname{N}(\mu, \sigma^2)\).
(a) Write the likelihood \(\mathcal{L}(\mu, \sigma^2; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\) for the observed data \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}= (x_1, \ldots, x_n)\).
(b) Write the log-likelihood \(\ell(\mu, \sigma^2; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\) in simplified form, as the sum of a term that depends on the data only through \(n\) and a term that depends on the data only through \(\sum_{i=1}^n(x_i- \mu)^2\).
(c) Derive the MLE \(\hat{\mu}_{ML}\) and \(\hat{\sigma}^2_{ML}\).
Solution 55. (a)
\[ \begin{aligned} \mathcal{L}(\mu, \sigma^2; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= \prod_{i=1}^n(2\pi\sigma^2)^{-1/2} {\operatorname{exp}\mathopen{}\left\{-\frac{(x_i- \mu)^2}{2\sigma^2}\right\}\mathclose{}} && \text{(likelihood of an $\operatorname{iid}$ sample)} \\ &= \mathopen{}\left(\prod_{i=1}^n(2\pi\sigma^2)^{-1/2}\right)\mathclose{} \mathopen{}\left(\prod_{i=1}^n{\operatorname{exp}\mathopen{}\left\{-\frac{(x_i- \mu)^2}{2\sigma^2}\right\}\mathclose{}}\right)\mathclose{} && \text{(regroup the factors of the product)} \\ &= (2\pi\sigma^2)^{-n/2} \prod_{i=1}^n{\operatorname{exp}\mathopen{}\left\{-\frac{(x_i- \mu)^2}{2\sigma^2}\right\}\mathclose{}} && \text{(product of $n$ copies of a power)} \\ &= (2\pi\sigma^2)^{-n/2} {\operatorname{exp}\mathopen{}\left\{\sum_{i=1}^n-\frac{(x_i- \mu)^2}{2\sigma^2}\right\}\mathclose{}} && \text{(product of exponentials)} \\ &= (2\pi\sigma^2)^{-n/2} {\operatorname{exp}\mathopen{}\left\{-\frac{1}{2\sigma^2}\sum_{i=1}^n(x_i-\mu)^2\right\}\mathclose{}} && \text{(factor the constant out of the sum)} \end{aligned} \]
(b)
\[ \begin{aligned} \ell(\mu, \sigma^2; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= {\operatorname{log}\mathopen{}\left\{\mathcal{L}(\mu, \sigma^2; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\right\}\mathclose{}} && \text{(definition of the log-likelihood)} \\ &= {\operatorname{log}\mathopen{}\left\{(2\pi\sigma^2)^{-n/2} {\operatorname{exp}\mathopen{}\left\{-\frac{1}{2\sigma^2}\sum_{i=1}^n(x_i-\mu)^2\right\}\mathclose{}}\right\}\mathclose{}} && \text{(likelihood from (a))} \\ &= {\operatorname{log}\mathopen{}\left\{(2\pi\sigma^2)^{-n/2}\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{{\operatorname{exp}\mathopen{}\left\{-\frac{1}{2\sigma^2}\sum_{i=1}^n(x_i-\mu)^2\right\}\mathclose{}}\right\}\mathclose{}} && \text{(log of a product)} \\ &= -\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\sigma^2\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{{\operatorname{exp}\mathopen{}\left\{-\frac{1}{2\sigma^2}\sum_{i=1}^n(x_i-\mu)^2\right\}\mathclose{}}\right\}\mathclose{}} && \text{(log of a power)} \\ &= -\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\sigma^2\right\}\mathclose{}} - \frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2 && \text{($\operatorname{log}$ undoes $\operatorname{exp}$)} \end{aligned} \]
(c)
Deriving \(\hat{\mu}_{ML}\):
\[ \begin{aligned} \frac{\partial}{\partial \mu}\ell &= \frac{\partial}{\partial \mu}\mathopen{}\left[-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\sigma^2\right\}\mathclose{}} - \frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2\right]\mathclose{} && \text{(log-likelihood from (b))} \\ &= \frac{\partial}{\partial \mu}\mathopen{}\left[-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\sigma^2\right\}\mathclose{}}\right]\mathclose{} + \frac{\partial}{\partial \mu}\mathopen{}\left[-\frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2\right]\mathclose{} && \text{(linearity of differentiation)} \\ &= 0 + \frac{\partial}{\partial \mu}\mathopen{}\left[-\frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2\right]\mathclose{} && \text{(derivative of a constant)} \\ &= \frac{\partial}{\partial \mu}\mathopen{}\left[-\frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2\right]\mathclose{} && \text{(drop the zero term)} \\ &= -\frac{1}{2\sigma^2}\frac{\partial}{\partial \mu}\sum_{i=1}^n(x_i- \mu)^2 && \text{(constant multiple rule)} \\ &= -\frac{1}{2\sigma^2}\sum_{i=1}^n\frac{\partial}{\partial \mu}(x_i- \mu)^2 && \text{(derivative of a sum is the sum of derivatives)} \\ &= -\frac{1}{2\sigma^2}\sum_{i=1}^n2(x_i- \mu)\frac{\partial}{\partial \mu}(x_i- \mu) && \text{(chain rule, outer function $u^2$)} \end{aligned} \]
The inner derivative is:
\[ \begin{aligned} \frac{\partial}{\partial \mu}(x_i- \mu) &= \frac{\partial}{\partial \mu} x_i- \frac{\partial}{\partial \mu} \mu && \text{(linearity of differentiation)} \\ &= 0 - \frac{\partial}{\partial \mu} \mu && \text{($x_i$ does not depend on $\mu$)} \\ &= 0 - 1 && \text{(derivative of $\mu$ with respect to itself)} \\ &= -1 && \text{(subtract)} \end{aligned} \]
Substituting the inner derivative back in:
\[ \begin{aligned} \frac{\partial}{\partial \mu}\ell &= -\frac{1}{2\sigma^2}\sum_{i=1}^n2(x_i- \mu) \cdot (-1) && \text{(inner derivative is $-1$)} \\ &= -\frac{1}{2\sigma^2}\sum_{i=1}^n-2(x_i- \mu) && \text{(multiply)} \\ &= -\frac{1}{2\sigma^2} \cdot (-2) \sum_{i=1}^n(x_i- \mu) && \text{(factor the constant $-2$ out of the sum)} \\ &= \frac{1}{\sigma^2}\sum_{i=1}^n(x_i- \mu) && \text{(multiply the constants)} \\ &= \frac{1}{\sigma^2}\mathopen{}\left(\sum_{i=1}^nx_i- \sum_{i=1}^n\mu\right)\mathclose{} && \text{(distribute the sum over the terms)} \\ &= \frac{1}{\sigma^2}\mathopen{}\left(\sum_{i=1}^nx_i- n\mu\right)\mathclose{} && \text{(sum of $n$ copies of $\mu$)} \end{aligned} \]
Setting this to zero: \(\hat{\mu}_{ML} = {\bar{x}}\stackrel{\text{def}}{=}\frac{1}{n}\sum_{i=1}^nx_i\).
Deriving \(\hat{\sigma}^2_{ML}\):
\[ \begin{aligned} \frac{\partial}{\partial \sigma^2}\ell &= \frac{\partial}{\partial \sigma^2}\mathopen{}\left[-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\sigma^2\right\}\mathclose{}} - \frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2\right]\mathclose{} && \text{(log-likelihood from (b))} \\ &= \frac{\partial}{\partial \sigma^2}\mathopen{}\left[-\frac{n}{2}\mathopen{}\left({\operatorname{log}\mathopen{}\left\{2\pi\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}}\right)\mathclose{} - \frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2\right]\mathclose{} && \text{(log of a product)} \\ &= \frac{\partial}{\partial \sigma^2}\mathopen{}\left[-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\right\}\mathclose{}} - \frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}} - \frac{1}{2\sigma^2}\sum_{i=1}^n(x_i- \mu)^2\right]\mathclose{} && \text{(distribute $-\tfrac{n}{2}$)} \\ &= \frac{\partial}{\partial \sigma^2}\mathopen{}\left[-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\right\}\mathclose{}} - \frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}} - \frac{1}{2}(\sigma^2)^{-1}\sum_{i=1}^n(x_i- \mu)^2\right]\mathclose{} && \text{(write $\tfrac{1}{2\sigma^2}$ as $\tfrac{1}{2}(\sigma^2)^{-1}$)} \\ &= \frac{\partial}{\partial \sigma^2}\mathopen{}\left[-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{2\pi\right\}\mathclose{}}\right]\mathclose{} + \frac{\partial}{\partial \sigma^2}\mathopen{}\left[-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}}\right]\mathclose{} + \frac{\partial}{\partial \sigma^2}\mathopen{}\left[-\frac{1}{2}(\sigma^2)^{-1}\sum_{i=1}^n(x_i- \mu)^2\right]\mathclose{} && \text{(linearity of differentiation)} \\ &= 0 + \frac{\partial}{\partial \sigma^2}\mathopen{}\left[-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}}\right]\mathclose{} + \frac{\partial}{\partial \sigma^2}\mathopen{}\left[-\frac{1}{2}(\sigma^2)^{-1}\sum_{i=1}^n(x_i- \mu)^2\right]\mathclose{} && \text{(derivative of a constant)} \\ &= \frac{\partial}{\partial \sigma^2}\mathopen{}\left[-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}}\right]\mathclose{} + \frac{\partial}{\partial \sigma^2}\mathopen{}\left[-\frac{1}{2}(\sigma^2)^{-1}\sum_{i=1}^n(x_i- \mu)^2\right]\mathclose{} && \text{(drop the zero term)} \\ &= \frac{\partial}{\partial \sigma^2}\mathopen{}\left[-\frac{n}{2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}}\right]\mathclose{} + \frac{\partial}{\partial \sigma^2}\mathopen{}\left[-\frac{1}{2}\sum_{i=1}^n(x_i- \mu)^2 (\sigma^2)^{-1}\right]\mathclose{} && \text{(reorder the factors)} \\ &= -\frac{n}{2}\frac{\partial}{\partial \sigma^2}{\operatorname{log}\mathopen{}\left\{\sigma^2\right\}\mathclose{}} - \frac{1}{2}\sum_{i=1}^n(x_i- \mu)^2 \frac{\partial}{\partial \sigma^2}(\sigma^2)^{-1} && \text{(constant multiple rule)} \\ &= -\frac{n}{2}(\sigma^2)^{-1} - \frac{1}{2}\sum_{i=1}^n(x_i- \mu)^2 \frac{\partial}{\partial \sigma^2}(\sigma^2)^{-1} && \text{(derivative of $\log$)} \\ &= -\frac{n}{2}(\sigma^2)^{-1} - \frac{1}{2}\sum_{i=1}^n(x_i- \mu)^2 \mathopen{}\left(-(\sigma^2)^{-2}\right)\mathclose{} && \text{(power rule)} \\ &= -\frac{n}{2}(\sigma^2)^{-1} + \frac{1}{2}\sum_{i=1}^n(x_i- \mu)^2 (\sigma^2)^{-2} && \text{(multiply)} \\ &= -\frac{n}{2}(\sigma^2)^{-1} + \frac{1}{2}(\sigma^2)^{-2}\sum_{i=1}^n(x_i- \mu)^2 && \text{(reorder the factors)} \end{aligned} \]
Setting this to zero and solving:
\[ \begin{aligned} 0 &= -\frac{n}{2}(\sigma^2)^{-1} + \frac{1}{2}(\sigma^2)^{-2}\sum_{i=1}^n(x_i- \mu)^2 && \text{(set the derivative to zero)} \\ \frac{n}{2}(\sigma^2)^{-1} &= \frac{1}{2}(\sigma^2)^{-2}\sum_{i=1}^n(x_i- \mu)^2 && \text{(add $\tfrac{n}{2}(\sigma^2)^{-1}$ to both sides)} \\ n(\sigma^2)^{-1}(\sigma^2)^2 &= (\sigma^2)^{-2}(\sigma^2)^2\sum_{i=1}^n(x_i- \mu)^2 && \text{(multiply both sides by $2(\sigma^2)^2$)} \\ n\sigma^2 &= (\sigma^2)^{-2}(\sigma^2)^2\sum_{i=1}^n(x_i- \mu)^2 && \text{($(\sigma^2)^{-1}(\sigma^2)^2 = \sigma^2$)} \\ n\sigma^2 &= \sum_{i=1}^n(x_i- \mu)^2 && \text{($(\sigma^2)^{-2}(\sigma^2)^2 = 1$)} \\ \sigma^2 &= \frac{1}{n}\sum_{i=1}^n(x_i- \mu)^2 && \text{(divide both sides by $n$)} \end{aligned} \]
Substituting \(\hat{\mu}_{ML} = {\bar{x}}\):
\[ \hat{\sigma}^2_{ML} = \frac{1}{n}\sum_{i=1}^n(x_i- {\bar{x}})^2 \]
Note: this maximum likelihood estimator is a biased estimator of \(\sigma^2\); the unbiased sample variance divides by \(n-1\).
Exercise 56 (Score at the MLE (adapted from Dobson and Barnett [1], Chapter 3)) Let \(X_1, \ldots, X_n \ \sim_{\operatorname{iid}}\ \operatorname{Pois}({\lambda})\).
(a) Write the log-likelihood \(\ell({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\).
(b) Derive the score function \(\ell'({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\).
(c) Find the MLE \(\hat{\lambda}_{ML}\), and evaluate the score at the MLE.
(d) Provide an intuitive interpretation of the value of the score at \(\hat{\lambda}_{ML}\).
Solution 56. (a)
\[ \begin{aligned} \ell({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= {\operatorname{log}\mathopen{}\left\{\prod_{i=1}^n\frac{{\lambda}^{x_i} e^{-{\lambda}}}{x_i!}\right\}\mathclose{}} && \text{(log of the likelihood of an $\operatorname{iid}$ sample)} \\ &= \sum_{i=1}^n{\operatorname{log}\mathopen{}\left\{\frac{{\lambda}^{x_i} e^{-{\lambda}}}{x_i!}\right\}\mathclose{}} && \text{(log of a product)} \\ &= \sum_{i=1}^n\mathopen{}\left({\operatorname{log}\mathopen{}\left\{{\lambda}^{x_i} e^{-{\lambda}}\right\}\mathclose{}} - {\operatorname{log}\mathopen{}\left\{x_i!\right\}\mathclose{}}\right)\mathclose{} && \text{(log of a quotient)} \\ &= \sum_{i=1}^n\mathopen{}\left({\operatorname{log}\mathopen{}\left\{{\lambda}^{x_i}\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{e^{-{\lambda}}\right\}\mathclose{}} - {\operatorname{log}\mathopen{}\left\{x_i!\right\}\mathclose{}}\right)\mathclose{} && \text{(log of a product)} \\ &= \sum_{i=1}^n\mathopen{}\left(x_i{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{e^{-{\lambda}}\right\}\mathclose{}} - {\operatorname{log}\mathopen{}\left\{x_i!\right\}\mathclose{}}\right)\mathclose{} && \text{(log of a power)} \\ &= \sum_{i=1}^n\mathopen{}\left(x_i{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}} - {\lambda}- {\operatorname{log}\mathopen{}\left\{x_i!\right\}\mathclose{}}\right)\mathclose{} && \text{($\operatorname{log}$ undoes $\operatorname{exp}$)} \\ &= \sum_{i=1}^nx_i{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}} - \sum_{i=1}^n{\lambda}- \sum_{i=1}^n{\operatorname{log}\mathopen{}\left\{x_i!\right\}\mathclose{}} && \text{(distribute the sum over the terms)} \\ &= \mathopen{}\left(\sum_{i=1}^nx_i\right)\mathclose{}{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}} - \sum_{i=1}^n{\lambda}- \sum_{i=1}^n{\operatorname{log}\mathopen{}\left\{x_i!\right\}\mathclose{}} && \text{(factor ${\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}}$ out of the first sum)} \\ &= \mathopen{}\left(\sum_{i=1}^nx_i\right)\mathclose{}{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}} - n{\lambda}- \sum_{i=1}^n{\operatorname{log}\mathopen{}\left\{x_i!\right\}\mathclose{}} && \text{(sum of $n$ copies of ${\lambda}$)} \end{aligned} \]
(b)
\[ \begin{aligned} \ell'({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= \frac{\partial}{\partial {\lambda}}\mathopen{}\left[\mathopen{}\left(\sum_{i=1}^nx_i\right)\mathclose{}{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}} - n{\lambda}- \sum_{i=1}^n{\operatorname{log}\mathopen{}\left\{x_i!\right\}\mathclose{}}\right]\mathclose{} && \text{(log-likelihood from (a))} \\ &= \frac{\partial}{\partial {\lambda}}\mathopen{}\left[\mathopen{}\left(\sum_{i=1}^nx_i\right)\mathclose{}{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}}\right]\mathclose{} - \frac{\partial}{\partial {\lambda}}\mathopen{}\left[n{\lambda}\right]\mathclose{} - \frac{\partial}{\partial {\lambda}}\mathopen{}\left[\sum_{i=1}^n{\operatorname{log}\mathopen{}\left\{x_i!\right\}\mathclose{}}\right]\mathclose{} && \text{(linearity of differentiation)} \\ &= \frac{\partial}{\partial {\lambda}}\mathopen{}\left[\mathopen{}\left(\sum_{i=1}^nx_i\right)\mathclose{}{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}}\right]\mathclose{} - \frac{\partial}{\partial {\lambda}}\mathopen{}\left[n{\lambda}\right]\mathclose{} - 0 && \text{(derivative of a constant)} \\ &= \frac{\partial}{\partial {\lambda}}\mathopen{}\left[\mathopen{}\left(\sum_{i=1}^nx_i\right)\mathclose{}{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}}\right]\mathclose{} - \frac{\partial}{\partial {\lambda}}\mathopen{}\left[n{\lambda}\right]\mathclose{} && \text{(drop the zero term)} \\ &= \mathopen{}\left(\sum_{i=1}^nx_i\right)\mathclose{}\frac{\partial}{\partial {\lambda}}{\operatorname{log}\mathopen{}\left\{{\lambda}\right\}\mathclose{}} - n\frac{\partial}{\partial {\lambda}}{\lambda} && \text{(constant multiple rule)} \\ &= \mathopen{}\left(\sum_{i=1}^nx_i\right)\mathclose{}{\lambda}^{-1} - n\frac{\partial}{\partial {\lambda}}{\lambda} && \text{(derivative of $\log$)} \\ &= \mathopen{}\left(\sum_{i=1}^nx_i\right)\mathclose{}{\lambda}^{-1} - n && \text{(derivative of ${\lambda}$ with respect to itself)} \\ &= \frac{\sum_{i=1}^nx_i}{{\lambda}} - n && \text{(write the negative power as a fraction)} \\ &= \frac{n{\bar{x}}}{{\lambda}} - n && \text{($\textstyle\sum_{i=1}^nx_i= n{\bar{x}}$)} \end{aligned} \]
(c)
The MLE solves \(\ell'({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = 0\), so evaluating the score there afterwards is a check on the algebra. Setting \(\ell'({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = 0\):
\[ \begin{aligned} 0 &= \frac{n{\bar{x}}}{{\lambda}} - n && \text{(score from (b))} \\ \frac{n{\bar{x}}}{{\lambda}} &= n && \text{(add $n$ to both sides)} \\ n{\bar{x}}&= n{\lambda} && \text{(multiply both sides by ${\lambda}$)} \\ \hat{\lambda}_{ML} &= {\bar{x}} && \text{(divide both sides by $n$)} \end{aligned} \]
If \({\bar{x}}> 0\) (equivalently, at least one \(x_i> 0\)), then
\[ \begin{aligned} \ell'({\bar{x}}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= \frac{n{\bar{x}}}{{\bar{x}}} - n && \text{(score from (b) at ${\lambda}= {\bar{x}}$)} \\ &= n - n && \text{(cancel ${\bar{x}}$, since ${\bar{x}}> 0$)} \\ &= 0 && \text{(subtract)} \end{aligned} \]
If instead all \(x_i= 0\), then \({\bar{x}}= 0\) and \(\hat{\lambda}_{ML} = 0\) is a boundary value. In that case, the score formula \(\ell'({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = \frac{n{\bar{x}}}{{\lambda}} - n\) is not defined at \({\lambda}= 0\), so the usual interior verification \(\ell'(\hat{\lambda}_{ML}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = 0\) does not apply.
(d)
The score measures the rate of change of the log-likelihood. When it equals zero, increasing or decreasing \({\lambda}\) slightly would not improve the fit; we are at a “flat” point. Intuitively, \(\hat{\lambda}_{ML} = {\bar{x}}\) is the value of \({\lambda}\) that makes the expected count per observation (\({\lambda}\)) exactly equal to the observed sample average count (\({\bar{x}}\)).
Exercise 57 (Standard error of an MLE (adapted from Dobson and Barnett [1], Chapter 5)) Let \(X_1, \ldots, X_n \ \sim_{\operatorname{iid}}\ \operatorname{Pois}({\lambda})\).
(a) Derive the Hessian \(\ell''({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = \frac{\partial}{\partial [}2]{{\lambda}}\ell({\lambda};\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\).
(b) Derive the observed information \(I({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = -\ell''({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\).
(c) Evaluate \(I(\hat{\lambda}_{ML}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\).
(d) Give an approximate 95% confidence interval for \({\lambda}\) using the asymptotic normal distribution of the MLE.
Solution 57. (a)
From Exercise 56, \(\ell'({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = \frac{n{\bar{x}}}{{\lambda}} - n\).
\[ \begin{aligned} \ell''({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= \frac{\partial}{\partial {\lambda}}\mathopen{}\left[\frac{n{\bar{x}}}{{\lambda}} - n\right]\mathclose{} && \text{(Poisson score)} \\ &= \frac{\partial}{\partial {\lambda}}\mathopen{}\left[n{\bar{x}}{\lambda}^{-1} - n\right]\mathclose{} && \text{(write $\tfrac{n{\bar{x}}}{{\lambda}}$ as $n{\bar{x}}{\lambda}^{-1}$)} \\ &= \frac{\partial}{\partial {\lambda}}\mathopen{}\left[n{\bar{x}}{\lambda}^{-1}\right]\mathclose{} - \frac{\partial}{\partial {\lambda}} n && \text{(linearity of differentiation)} \\ &= \frac{\partial}{\partial {\lambda}}\mathopen{}\left[n{\bar{x}}{\lambda}^{-1}\right]\mathclose{} - 0 && \text{(derivative of a constant)} \\ &= \frac{\partial}{\partial {\lambda}}\mathopen{}\left[n{\bar{x}}{\lambda}^{-1}\right]\mathclose{} && \text{(drop the zero term)} \\ &= n{\bar{x}}\frac{\partial}{\partial {\lambda}}{\lambda}^{-1} && \text{(constant multiple rule)} \\ &= n{\bar{x}}\mathopen{}\left(-{\lambda}^{-2}\right)\mathclose{} && \text{(power rule)} \\ &= -n{\bar{x}}{\lambda}^{-2} && \text{(multiply)} \\ &= -\frac{n{\bar{x}}}{{\lambda}^2} && \text{(write the negative power as a fraction)} \end{aligned} \]
(b)
\[ \begin{aligned} I({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= -\ell''({\lambda}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) && \text{(observed information is the negative Hessian)} \\ &= -\mathopen{}\left(-\frac{n{\bar{x}}}{{\lambda}^2}\right)\mathclose{} && \text{(Hessian from (a))} \\ &= \frac{n{\bar{x}}}{{\lambda}^2} && \text{(two negatives make a positive)} \end{aligned} \]
(c)
Assuming \({\bar{x}}> 0\) (i.e., at least one \(x_i> 0\)), substituting \(\hat{\lambda}_{ML} = {\bar{x}}\):
\[ \begin{aligned} I(\hat{\lambda}_{ML}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= \frac{n{\bar{x}}}{{\bar{x}}^2} && \text{(observed information at ${\lambda}= {\bar{x}}$)} \\ &= \frac{n}{{\bar{x}}} && \text{(cancel one factor of ${\bar{x}}$)} \end{aligned} \]
(d)
By the asymptotic theory of MLEs:
\[ \hat{\lambda}_{ML} \;\dot\sim\; \operatorname{N}\!\mathopen{}\left({\lambda},\; {\mathopen{}\left(\mathcal{I}({\lambda})\right)\mathclose{}}^{-1}\right)\mathclose{} \]
We estimate this asymptotic variance using the observed information evaluated at the MLE. Since \(I(\hat{\lambda}_{ML};\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})^{-1} = {\bar{x}}/n\):
\[ {\operatorname{SE}\mathopen{}\left(\hat{\lambda}_{ML}\right)\mathclose{}} \approx \sqrt{\frac{{\bar{x}}}{n}} \]
An approximate 95% CI for \({\lambda}\) is:
\[ \hat{\lambda}_{ML} \pm 1.96 \times \sqrt{\frac{{\bar{x}}}{n}} = {\bar{x}}\pm 1.96\sqrt{\frac{{\bar{x}}}{n}} \]
Exercise 58 (Exponential MLE (adapted from Dobson and Barnett [1], Chapter 3)) Let \(X_1, \ldots, X_n \ \sim_{\operatorname{iid}}\ \text{Exponential}(\mu)\), so that \[ \mathbb{p}(X = x \mid \mu) = \frac{1}{\mu} e^{-x/\mu}, \quad x > 0, \quad \mu> 0. \]
Write the log-likelihood \(\ell(\mu; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\) for the observed data \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}= (x_1, \ldots, x_n)\).
Solution 58. \[ \begin{aligned} \ell(\mu; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= {\operatorname{log}\mathopen{}\left\{\prod_{i=1}^n\frac{1}{\mu} e^{-x_i/\mu}\right\}\mathclose{}} && \text{(log of the likelihood of an $\operatorname{iid}$ sample)} \\ &= \sum_{i=1}^n{\operatorname{log}\mathopen{}\left\{\frac{1}{\mu} e^{-x_i/\mu}\right\}\mathclose{}} && \text{(log of a product)} \\ &= \sum_{i=1}^n\mathopen{}\left({\operatorname{log}\mathopen{}\left\{\frac{1}{\mu}\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{e^{-x_i/\mu}\right\}\mathclose{}}\right)\mathclose{} && \text{(log of a product)} \\ &= \sum_{i=1}^n\mathopen{}\left(-{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}} + {\operatorname{log}\mathopen{}\left\{e^{-x_i/\mu}\right\}\mathclose{}}\right)\mathclose{} && \text{(log of a reciprocal)} \\ &= \sum_{i=1}^n\mathopen{}\left(-{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}} - \frac{x_i}{\mu}\right)\mathclose{} && \text{($\operatorname{log}$ undoes $\operatorname{exp}$)} \\ &= \sum_{i=1}^n\mathopen{}\left(-{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}}\right)\mathclose{} - \sum_{i=1}^n\frac{x_i}{\mu} && \text{(distribute the sum over the terms)} \\ &= -n{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}} - \sum_{i=1}^n\frac{x_i}{\mu} && \text{(sum of $n$ identical terms)} \\ &= -n{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}} - \frac{1}{\mu}\sum_{i=1}^nx_i && \text{(factor the constant $\tfrac{1}{\mu}$ out of the sum)} \\ &= -n{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}} - \frac{n{\bar{x}}}{\mu} && \text{($\textstyle\sum_{i=1}^nx_i= n{\bar{x}}$)} \end{aligned} \]
Exercise 59 (Score function of the exponential) In the setting of Exercise 58, derive the score function \(\ell'(\mu; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = \frac{\partial}{\partial \mu}\ell(\mu; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\).
Solution 59. \[ \begin{aligned} \ell'(\mu; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= \frac{\partial}{\partial \mu}\mathopen{}\left(-n{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}} - \frac{n{\bar{x}}}{\mu}\right)\mathclose{} && \text{(log-likelihood)} \\ &= \frac{\partial}{\partial \mu}\mathopen{}\left(-n{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}} - n{\bar{x}}\mu^{-1}\right)\mathclose{} && \text{(write $\tfrac{n{\bar{x}}}{\mu}$ as $n{\bar{x}}\mu^{-1}$)} \\ &= \frac{\partial}{\partial \mu}\mathopen{}\left(-n{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}}\right)\mathclose{} - \frac{\partial}{\partial \mu}\mathopen{}\left(n{\bar{x}}\mu^{-1}\right)\mathclose{} && \text{(linearity of differentiation)} \\ &= -n\frac{\partial}{\partial \mu}{\operatorname{log}\mathopen{}\left\{\mu\right\}\mathclose{}} - n{\bar{x}}\frac{\partial}{\partial \mu}\mu^{-1} && \text{(constant multiple rule)} \\ &= -n\mu^{-1} - n{\bar{x}}\frac{\partial}{\partial \mu}\mu^{-1} && \text{(derivative of $\log$)} \\ &= -n\mu^{-1} - n{\bar{x}}\mathopen{}\left(-\mu^{-2}\right)\mathclose{} && \text{(power rule)} \\ &= -n\mu^{-1} + n{\bar{x}}\mu^{-2} && \text{(multiply)} \\ &= -\frac{n}{\mu} + \frac{n{\bar{x}}}{\mu^2} && \text{(write the negative powers as fractions)} \\ &= -\frac{n\mu}{\mu^2} + \frac{n{\bar{x}}}{\mu^2} && \text{(write both terms over the common denominator)} \\ &= \frac{-n\mu+ n{\bar{x}}}{\mu^2} && \text{(combine the fractions)} \\ &= \frac{n{\bar{x}}- n\mu}{\mu^2} && \text{(reorder the numerator)} \\ &= \frac{n}{\mu^2}\mathopen{}\left({\bar{x}}- \mu\right)\mathclose{} && \text{(factor out $\tfrac{n}{\mu^2}$)} \end{aligned} \]
Exercise 60 (Maximum likelihood estimate of the exponential mean) In the setting of Exercise 58, solve the score equation \(\ell'(\mu; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = 0\) with the score from Exercise 59, to show that \(\hat\mu_{ML} = {\bar{x}}\).
Solution 60. Setting \(\ell'(\mu; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = 0\):
\[ \begin{aligned} 0 &= \frac{n}{\mu^2}\mathopen{}\left({\bar{x}}- \mu\right)\mathclose{} && \text{(score)} \\ 0 &= {\bar{x}}- \mu && \text{(multiply both sides by $\tfrac{\mu^2}{n}$)} \\ \hat\mu_{ML} &= {\bar{x}} && \text{(add $\mu$ to both sides)} \end{aligned} \]
Exercise 61 (Second derivative of the exponential log-likelihood) In the setting of Exercise 58, compute the second derivative \(\ell''(\mu; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\) of the log-likelihood.
Solution 61. The second derivative is:
\[ \begin{aligned} \ell''(\mu; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= \frac{\partial}{\partial \mu}\mathopen{}\left(-\frac{n}{\mu} + \frac{n{\bar{x}}}{\mu^2}\right)\mathclose{} && \text{(score, before factoring)} \\ &= \frac{\partial}{\partial \mu}\mathopen{}\left(-n\mu^{-1} + n{\bar{x}}\mu^{-2}\right)\mathclose{} && \text{(write the fractions as negative powers)} \\ &= \frac{\partial}{\partial \mu}\mathopen{}\left(-n\mu^{-1}\right)\mathclose{} + \frac{\partial}{\partial \mu}\mathopen{}\left(n{\bar{x}}\mu^{-2}\right)\mathclose{} && \text{(linearity of differentiation)} \\ &= -n\frac{\partial}{\partial \mu}\mu^{-1} + n{\bar{x}}\frac{\partial}{\partial \mu}\mu^{-2} && \text{(constant multiple rule)} \\ &= -n\mathopen{}\left(-\mu^{-2}\right)\mathclose{} + n{\bar{x}}\frac{\partial}{\partial \mu}\mu^{-2} && \text{(power rule for $\mu^{-1}$)} \\ &= -n\mathopen{}\left(-\mu^{-2}\right)\mathclose{} + n{\bar{x}}\mathopen{}\left(-2\mu^{-3}\right)\mathclose{} && \text{(power rule for $\mu^{-2}$)} \\ &= n\mu^{-2} - 2n{\bar{x}}\mu^{-3} && \text{(multiply)} \\ &= \frac{n}{\mu^2} - \frac{2n{\bar{x}}}{\mu^3} && \text{(write the negative powers as fractions)} \end{aligned} \]
Exercise 62 (Check the critical point is a maximum) In the setting of Exercise 58, use the second derivative from Exercise 61 to verify that the critical point \(\hat\mu_{ML}\) from Exercise 60 is a maximum.
Solution 62. Evaluated at \(\hat\mu_{ML} = {\bar{x}}\):
\[ \begin{aligned} \ell''({\bar{x}}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= \frac{n}{{\bar{x}}^2} - \frac{2n{\bar{x}}}{{\bar{x}}^3} && \text{(second derivative at $\mu= {\bar{x}}$)} \\ &= \frac{n}{{\bar{x}}^2} - \frac{2n}{{\bar{x}}^2} && \text{(cancel one factor of ${\bar{x}}$)} \\ &= -\frac{n}{{\bar{x}}^2} && \text{(combine like terms)} \end{aligned} \]
Since \(n > 0\) and \({\bar{x}}^2 > 0\), the second derivative is negative, so \(\hat\mu_{ML} = {\bar{x}}\) is a maximum.
Exercise 63 (Observed information for the exponential mean) In the setting of Exercise 58, use the second derivative from Exercise 61 to derive the observed information \(I(\mu; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = -\ell''(\mu; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\).
Solution 63. The observed information is:
\[ \begin{aligned} I(\mu; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= -\ell''(\mu; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) && \text{(observed information is the negative Hessian)} \\ &= -\mathopen{}\left(\frac{n}{\mu^2} - \frac{2n{\bar{x}}}{\mu^3}\right)\mathclose{} && \text{(second derivative)} \\ &= -\frac{n}{\mu^2} + \frac{2n{\bar{x}}}{\mu^3} && \text{(distribute the minus sign)} \\ &= \frac{2n{\bar{x}}}{\mu^3} - \frac{n}{\mu^2} && \text{(reorder the terms)} \end{aligned} \]
Exercise 64 (Observed information at the MLE) In the setting of Exercise 58, evaluate the observed information from Exercise 63 at \(\hat\mu_{ML}\) from Exercise 60.
Solution 64. Evaluated at \(\hat\mu_{ML} = {\bar{x}}\):
\[ \begin{aligned} I(\hat\mu_{ML}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= \frac{2n{\bar{x}}}{{\bar{x}}^3} - \frac{n}{{\bar{x}}^2} && \text{(observed information at $\mu= {\bar{x}}$)} \\ &= \frac{2n}{{\bar{x}}^2} - \frac{n}{{\bar{x}}^2} && \text{(cancel one factor of ${\bar{x}}$)} \\ &= \frac{n}{{\bar{x}}^2} && \text{(combine like terms)} \end{aligned} \]
So \({\operatorname{SE}\mathopen{}\left(\hat\mu_{ML}\right)\mathclose{}} \approx \sqrt{I(\hat\mu_{ML}; \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})^{-1}} = \frac{{\bar{x}}}{\sqrt{n}}\).
Exercise 65 (Approximate confidence interval for the exponential mean) In the setting of Exercise 58, use the observed information at the MLE from Exercise 64 to give an approximate 95% confidence interval for \(\mu\).
Solution 65. An approximate 95% CI for \(\mu\) is:
\[ \hat\mu_{ML} \pm 1.96 \times \frac{{\bar{x}}}{\sqrt{n}} = {\bar{x}}\pm \frac{1.96{\bar{x}}}{\sqrt{n}} \]
Note: the exponential distribution has \({\operatorname{Var}\mathopen{}\left(X\right)\mathclose{}} = \mu^2\), so \({\operatorname{SE}\mathopen{}\left(\hat\mu_{ML}\right)\mathclose{}} = \mu/\sqrt{n}\), which is estimated by \({\bar{x}}/\sqrt{n}\). More generally, the standard error of a sample mean is \({\operatorname{SD}\mathopen{}\left(X\right)\mathclose{}}/\sqrt{n}\); here the standard error reduces to \(\mu/\sqrt{n}\) because \({\operatorname{SD}\mathopen{}\left(X\right)\mathclose{}} = \mu\) for the exponential distribution.
References
[1]
A. J. Dobson and A. G. Barnett, An introduction to generalized linear models, 4th ed. CRC press, 2018. doi: 10.1201/9781315182780.
[2]
G. J. McLachlan and T. Krishnan, The EM algorithm and extensions, 2nd ed. John Wiley & Sons, 2007. doi: 10.1002/9780470191613.
[3]
G. Casella and R. Berger, Statistical inference, 2nd ed. Cengage Learning, 2002. Available: https://www.cengage.com/c/statistical-inference-2e-casella-berger/9780534243128/
[4]
Wikipedia contributors, “Likelihood function — Wikipedia, the free encyclopedia.” 2026. Available: https://en.wikipedia.org/wiki/Likelihood_function
[5]
Wikipedia contributors, “Maximum likelihood estimation — Wikipedia, the free encyclopedia.” 2026. Available: https://en.wikipedia.org/wiki/Maximum_likelihood_estimation
[6]
5MinuteAI, “Probability & statistics.” Video playlist on YouTube. Accessed: Oct. 12, 2026. [Online]. Available: https://www.youtube.com/playlist?list=PLeB45KifGiuHesi4PALNZSYZFhViVGQJK
[7]
R. V. Hogg, E. A. Tanis, and D. L. Zimmerman, Probability and statistical inference, Tenth edition. Boston: Pearson, 2019.
[8]
J. A. Rice, Mathematical statistics and data analysis, 3rd ed. Belmont, CA: Cengage Learning, 2007.
[9]
Wikipedia contributors, “Critical point (mathematics) — Wikipedia, the free encyclopedia.” 2026. Available: https://en.wikipedia.org/wiki/Critical_point_%28mathematics%29
[10]
Wikipedia contributors, “Informant function — Wikipedia, the free encyclopedia.” 2026. Available: https://en.wikipedia.org/wiki/Informant_function
[11]
R. A. Fisher, “The detection of linkage with ‘dominant’ abnormalities,” Annals of Eugenics, vol. 6, no. 2, pp. 187–201, 1935, doi: 10.1111/j.1469-1809.1935.tb02227.x.
[12]
C. R. Rao, “Large sample tests of statistical hypotheses concerning several parameters with applications to problems of estimation,” Mathematical Proceedings of the Cambridge Philosophical Society, vol. 44, no. 1, pp. 50–57, 1948, doi: 10.1017/S0305004100023987.
[13]
A. K. Bera and Y. Bilias, “Three score and 15 years (1948–2023) of Rao’s score test: A brief history.” arXiv:2406.19956, 2024. doi: 10.48550/arXiv.2406.19956.
[14]
Wikipedia contributors, “Hessian matrix — Wikipedia, the free encyclopedia.” 2026. Available: https://en.wikipedia.org/wiki/Hessian_matrix
[15]
Wikipedia contributors, “Fisher information — Wikipedia, the free encyclopedia.” 2026. Available: https://en.wikipedia.org/wiki/Fisher_information
[16]
E. L. Lehmann, Elements of large-sample theory. in Springer texts in statistics. New York: Springer, 1999. doi: 10.1007/b98855.
[17]
W. K. Newey and D. McFadden, “Large sample estimation and hypothesis testing,” in Handbook of econometrics, vol. 4, R. Engle and D. McFadden, Eds., Elsevier, 1994, pp. 2111–2245. doi: 10.1016/S1573-4412(05)80005-4.
[18]
B. Efron and D. V. Hinkley, “Assessing the accuracy of the maximum likelihood estimator: Observed versus expected Fisher information,” Biometrika, vol. 65, no. 3, pp. 457–483, 1978, doi: 10.1093/biomet/65.3.457.
[19]
Wikipedia contributors, “Wald test — Wikipedia, the free encyclopedia.” 2026. Available: https://en.wikipedia.org/wiki/Wald_test
[20]
Wikipedia contributors, “Likelihood-ratio test — Wikipedia, the free encyclopedia.” 2026. Available: https://en.wikipedia.org/wiki/Likelihood-ratio_test
[21]
Wikipedia contributors, “Wilks’ theorem — Wikipedia, the free encyclopedia.” 2026. Available: https://en.wikipedia.org/wiki/Wilks%27_theorem
[22]
S. S. Wilks, “The large-sample distribution of the likelihood ratio for testing composite hypotheses,” The Annals of Mathematical Statistics, vol. 9, no. 1, pp. 60–62, 1938, doi: 10.1214/aoms/1177732360.
[23]
Wikipedia contributors, “Prediction interval — Wikipedia, the free encyclopedia.” 2026. Available: https://en.wikipedia.org/wiki/Prediction_interval
[24]
S. Hulley et al., “Randomized trial of estrogen plus progestin for secondary prevention of coronary heart disease in postmenopausal women,” JAMA : the journal of the American Medical Association, vol. 280, no. 7, pp. 605–613, 1998, doi: 10.1001/jama.280.7.605.
[25]
E. Vittinghoff, D. V. Glidden, S. C. Shiboski, and C. E. McCulloch, Regression methods in biostatistics: Linear, logistic, survival, and repeated measures models, 2nd ed. Springer, 2012. doi: 10.1007/978-1-4614-1353-0.
[26]
J. M. Hoenig and D. M. Heisey, “The abuse of power: The pervasive fallacy of power calculations for data analysis,” The American Statistician, vol. 55, no. 1, pp. 19–24, 2001, doi: 10.1198/000313001300339897.
[27]
D. G. Kleinbaum, L. L. Kupper, A. Nizam, K. Muller, and E. Rosenberg, Applied regression analysis and other multivariable methods, 5th ed. Cengage Learning, 2014. Available: https://www.cengage.com/c/applied-regression-analysis-and-other-multivariable-methods-5e-kleinbaum/9781285051086/