Newton’s Method
Last modified: 2026-11-03 15:17:03 (PST)
Source
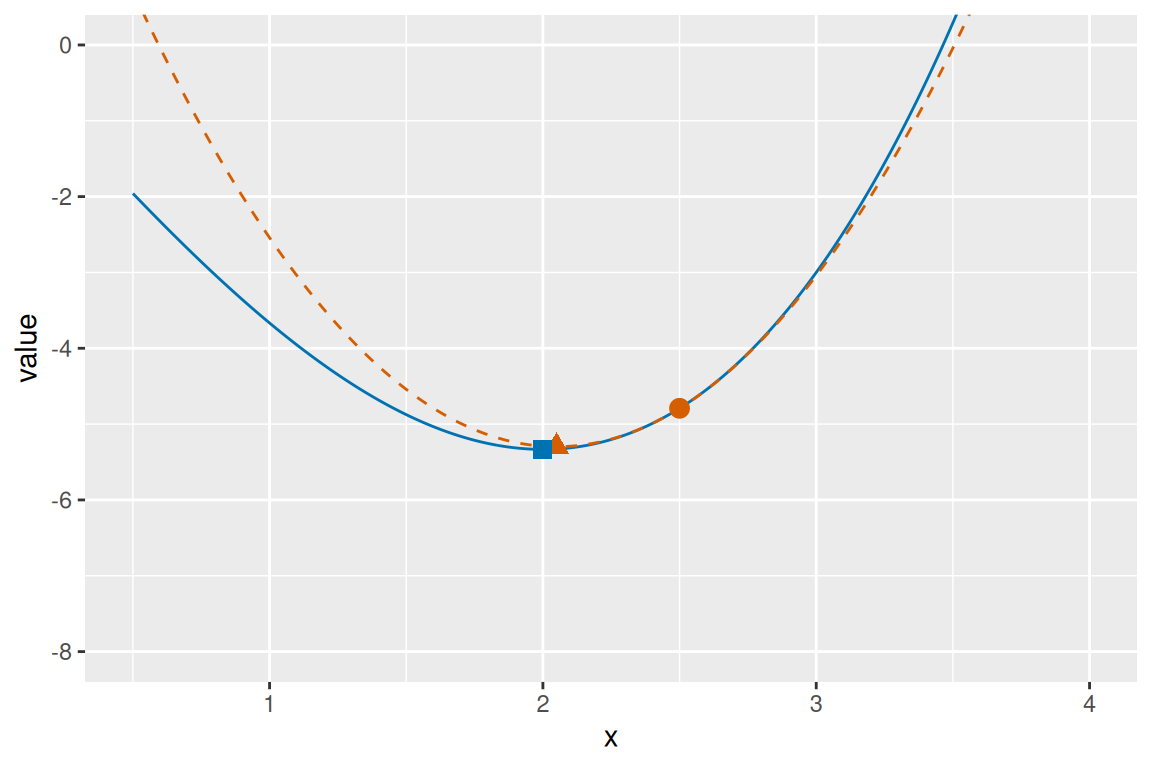
This section is adapted from the Newton-Raphson and gradient descent parts of Zhou [1], used under the MIT License (see the license text in Linear Algebra). The source motivates the Newton step by minimizing a quadratic approximation; here that step is proved to be the exact minimizer of the quadratic model. In the source’s zigzag example the starting value of the objective is \(\tfrac{1}{2}(b^2 + b)\), not \(\tfrac{1}{2}(1 + b^2)\) as the source writes; the ratio of successive values is unaffected. In the same example the source’s formula for \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(1)}\) has \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(1)}\) on its right side where \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)}\) is meant. These parts of the source are not part of this section:
- the quadratic convergence theorem for Newton’s method in general, and its remedies for instability (a positive definite substitute for the Hessian, and shortening the Newton step by a search along its direction)
- its remark that Hessians are expensive to compute
- the convergence-rate theorem for strongly convex functions
- gradient descent with momentum, and its optimal parameters
- Nesterov acceleration, and stochastic gradient descent
- its code and animations
Definition 1 (Iterative method) An iterative method [2] starts from a point \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)}\) and computes \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t+1)}\) from \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)}\) by a fixed rule, for \(t = 0, 1, 2, \ldots\).
Definition 2 (Iterate) In an iterative method (Definition 1), the points \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)}\) are its iterates.
Definition 3 (Error of an iterate) For a point \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^*\) that an iterative method (Definition 1) is meant to reach, \(\mathopen{}\left\lVert\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)} - \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^*\right\rVert\mathclose{}\) is the error of the iterate \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)}\) (Definition 2).
Definition 4 (Convergence of a sequence of vectors) A sequence \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)}, \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(1)}, \ldots\) in \(\mathbb{R}^p\) converges to \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^* \in \mathbb{R}^p\) if the sequence of distances \(\mathopen{}\left\lVert\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)} - \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^*\right\rVert\mathclose{}\) converges to \(0\). For \(p = 1\), \(\mathopen{}\left\lVert x^{(t)} - x^*\right\rVert\mathclose{} = \mathopen{}\left|x^{(t)} - x^*\right|\mathclose{}\), and this is the convergence of a sequence of numbers to \(x^*\).
Example 1 (Halving a vector) The iterative method \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t+1)} = \tfrac{1}{2}\,\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)}\) from \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)} = {(4, 2)}^{\top}\) has iterates \({(4, 2)}^{\top}, {(2, 1)}^{\top}, {(1, 0.5)}^{\top}, \ldots\), that is, \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)} = 2^{-t}\,{(4, 2)}^{\top}\). With \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^* = \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{0}}\vphantom{0}}\), the error of \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)}\) is
\[ \begin{aligned} \mathopen{}\left\lVert 2^{-t}\,{(4, 2)}^{\top} - \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{0}}\vphantom{0}}\right\rVert\mathclose{} &= 2^{-t}\,\mathopen{}\left\lVert{(4, 2)}^{\top}\right\rVert\mathclose{} && \text{(norm of a multiple)} \\ &= 2^{-t} \sqrt{20}, && \text{(} 4^2 + 2^2 = 20 \text{)} \end{aligned} \]
which converges to \(0\), so the iterates converge to \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{0}}\vphantom{0}}\).
Definition 5 (Newton’s method for minimization) Let \(f : \mathbb{R}^p \to \mathbb{R}\) have first and second partial derivatives, and let \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)}\) be a starting point. Newton’s method [3] computes, for \(t = 0, 1, 2, \ldots\), as long as \(\mathbf{H}_f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)})\) is invertible,
\[ \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t+1)} \stackrel{\text{def}}{=}\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)} - \mathopen{}\left[\mathbf{H}_f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)})\right]\mathclose{}^{-1} \frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}} f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)}). \]
Definition 6 (Newton step) In Newton’s method (Definition 5), the vector \(-\mathopen{}\left[\mathbf{H}_f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)})\right]\mathclose{}^{-1} \frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}} f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)})\) is the Newton step at \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)}\).
Example 2 (Newton’s method for a cubic) Let \(f(x) = \tfrac{1}{3} x^3 - 4x\), so \(f'(x) = x^2 - 4\) and \(f''(x) = 2x\). For \(x^{(t)} \ne 0\), one Newton step gives
\[ \begin{aligned} x^{(t+1)} &= x^{(t)} - \frac{(x^{(t)})^2 - 4}{2 x^{(t)}} && \text{(Newton's method with } p = 1 \text{)} \\ &= \frac{2 (x^{(t)})^2 - (x^{(t)})^2 + 4}{2 x^{(t)}} && \text{(common denominator)} \\ &= \frac{1}{2} \mathopen{}\left(x^{(t)} + \frac{4}{x^{(t)}}\right)\mathclose{}. && \text{(simplify)} \end{aligned} \]
From \(x^{(0)} = 2.5\):
\[ \begin{aligned} x^{(1)} &= \tfrac{1}{2} (2.5 + 1.6) \\ &= 2.05; \end{aligned} \]
-
\[ \begin{aligned} x^{(2)} &= \tfrac{1}{2} (2.05 + 1.951219\ldots) \\ &= 2.000610 \end{aligned} \]
(to six decimals);
\(x^{(3)} = 2.0000001\) (to seven decimals).
The iterates (Definition 2) approach \(2\), the local minimizer of \(f\) (a stationary point, since \(f'(2) = 0\), with \(f''(2) = 4 > 0\); Theorem 7 in Critical Points and Optimality Conditions).
Definition 7 (Quadratic model, second-order Taylor polynomial) Let \(f\) be as in Definition 5 and let \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\) be a point, with \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}} \stackrel{\text{def}}{=}\frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}} f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\) and \(\mathbf{H} \stackrel{\text{def}}{=}\mathbf{H}_f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\). The quadratic model of \(f\) at \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\) is the function of a step \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}\in \mathbb{R}^p\)
\[ q(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}) \stackrel{\text{def}}{=}f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) + \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}} \cdot \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}} + \tfrac{1}{2}\,{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}}^{\top} \mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}, \]
also called the second-order Taylor polynomial of \(f\) at \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\).
Example 3 (The model at \(x = 2.5\)) For \(f(x) = \tfrac{1}{3} x^3 - 4x\) at \(x = 2.5\) (Example 2),
\[ \begin{aligned} g &= 2.5^2 - 4 \\ &= 2.25 \end{aligned} \]
and
\[ \begin{aligned} H &= [2 \cdot 2.5] \\ &= [5], \end{aligned} \]
so \(q(\delta) = f(2.5) + 2.25\,\delta+ 2.5\,\delta^2\). For \(f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = \tfrac{1}{2} (x_1^2 + 3 x_2^2)\), whose Hessian is \(\begin{bmatrix} 1 & 0 \\ 0 & 3 \end{bmatrix}\) at every point, the model at any \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\) equals \(f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}+ \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}})\) exactly (Example 12 in Critical Points and Optimality Conditions with \(\mathbf{S} = \begin{bmatrix} 1/2 & 0 \\ 0 & 3/2 \end{bmatrix}\)).
Remark 1 (The quadratic model and Taylor’s theorem). When the second partial derivatives of \(f\) are continuous, Theorem 6 in Critical Points and Optimality Conditions says that \(f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}+ \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}})\) equals the expression for \(q(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}})\) in Definition 7 with the Hessian evaluated at a point between \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\) and \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}+ \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}\).
Theorem 1 (The Newton step minimizes the quadratic model) Let \(q\) be the quadratic model of \(f\) at \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\) (Definition 7), with \(\mathbf{H} = \mathbf{H}_f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}})\) positive definite. Its unique minimizer is the Newton step \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* = -\mathbf{H}^{-1} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}}\).
Proof. \(\mathbf{H}\) is symmetric, by the definition of positive definite, and invertible, so \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^*\) exists and \(\mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* = -\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}}\). For any \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}} \in \mathbb{R}^p\), first
\[ \begin{aligned} {\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}}}^{\top} \mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* &= -\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}} \cdot \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}} && \text{(} \mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* = -\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}} \text{)} \\ &= -\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}} \cdot \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}}, && \text{(a } 1 \times 1 \text{ matrix equals its transpose)} \end{aligned} \]
and \({\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^*{}}^{\top} \mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}} = {\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}}}^{\top} \mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^*\) in the same way, using \({\mathbf{H}}^{\top} = \mathbf{H}\). Then
\[ \begin{aligned} q(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* + \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}}) &= f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) + \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}} \cdot (\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* + \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}}) +\tfrac{1}{2}\,{(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* + \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}})}^{\top} \mathbf{H} (\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* + \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}}) && \text{(definition of } q \text{)} \\ &= f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) + \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}} \cdot \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* + \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}} \cdot \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}} + \tfrac{1}{2} \mathopen{}\left({\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^*{}}^{\top} \mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* + {\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^*{}}^{\top} \mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}} + {\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}}}^{\top} \mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* + {\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}}}^{\top} \mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}}\right)\mathclose{} && \text{(distribute)} \\ &= f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) + \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}} \cdot \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* + \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}} \cdot \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}} + \tfrac{1}{2}\,{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^*{}}^{\top} \mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* - \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}} \cdot \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}} + \tfrac{1}{2}\,{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}}}^{\top} \mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}} && \text{(both cross terms equal } -\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}} \cdot \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}} \text{)} \\ &= f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) + \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}} \cdot \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* + \tfrac{1}{2}\,{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^*{}}^{\top} \mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^* + \tfrac{1}{2}\,{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}}}^{\top} \mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}} && \text{(cancel } \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{g}}\vphantom{g}} \cdot \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}} \text{)} \\ &= q(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^*) + \tfrac{1}{2}\,{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}}}^{\top} \mathbf{H} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}}, && \text{(definition of } q \text{)} \end{aligned} \]
which is greater than \(q(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{\delta}}\vphantom{\delta}}^*)\) for every \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{d}}\vphantom{d}} \ne \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{0}}\vphantom{0}}_{p \times 1}\), since \(\mathbf{H}\) is positive definite.
Example 4 (The Newton step at \(x = 2.5\)) For the model \(q(\delta) = f(2.5) + 2.25\,\delta+ 2.5\,\delta^2\) of Example 3, \(H = [5]\) is positive definite, so by Theorem 1 its minimizer is
\[ \begin{aligned} \delta^* &= -H^{-1} g \\ &= -2.25 / 5 \\ &= -0.45. \end{aligned} \]
Setting the derivative \(2.25 + 5 \delta\) to \(0\) gives the same \(\delta^*\), and
\[ \begin{aligned} 2.5 - 0.45 &= 2.05 \\ &= x^{(1)} \end{aligned} \]
(Example 2).
[Code]
nm_x_nm <- seq(0.5, 4, length.out = 301)
nm_f_nm <- nm_x_nm^3 / 3 - 4 * nm_x_nm
nm_f0_nm <- 2.5^3 / 3 - 4 * 2.5
nm_q_nm <- nm_f0_nm + 2.25 * (nm_x_nm - 2.5) + 2.5 * (nm_x_nm - 2.5)^2
nm_q_step_nm <- nm_f0_nm + 2.25 * (2.05 - 2.5) + 2.5 * (2.05 - 2.5)^2
nm_f_min_nm <- 2^3 / 3 - 4 * 2
nm_curve_nm <- tibble::tibble(x = nm_x_nm, y = nm_f_nm)
nm_model_nm <- tibble::tibble(x = nm_x_nm, y = nm_q_nm)
nm_start_nm <- tibble::tibble(x = 2.5, y = nm_f0_nm)
nm_step_nm <- tibble::tibble(x = 2.05, y = nm_q_step_nm)
nm_min_nm <- tibble::tibble(x = 2, y = nm_f_min_nm)
nm_aes_nm <- ggplot2::aes(x, y)
nm_ylim_nm <- c(-8, 0)
ggplot2::ggplot(nm_curve_nm, nm_aes_nm) +
  ggplot2::geom_line(colour = "#0072B2") +
  ggplot2::geom_line(
    data = nm_model_nm, colour = "#D55E00", linetype = "dashed"
  ) +
  ggplot2::geom_point(data = nm_start_nm, colour = "#D55E00", size = 3) +
  ggplot2::geom_point(
    data = nm_step_nm, colour = "#D55E00", size = 3, shape = 17
  ) +
  ggplot2::geom_point(
    data = nm_min_nm, colour = "#0072B2", size = 3, shape = 15
  ) +
  ggplot2::coord_cartesian(ylim = nm_ylim_nm) +
  ggplot2::labs(x = "x", y = "value")
[Code]
import matplotlib.pyplot as plt
import numpy as np

nm_x_fn = np.linspace(0.5, 4, 301)
nm_f_fn = lambda x: x**3 / 3 - 4 * x
nm_q_fn = lambda x: nm_f_fn(2.5) + 2.25 * (x - 2.5) + 2.5 * (x - 2.5) ** 2
fig, ax = plt.subplots(figsize=(6, 4), layout="constrained")
ax.plot(nm_x_fn, nm_f_fn(nm_x_fn), color="#0072B2")
ax.plot(nm_x_fn, nm_q_fn(nm_x_fn), "--", color="#D55E00")
ax.plot(2.5, nm_f_fn(2.5), "o", color="#D55E00", markersize=8)
ax.plot(2.05, nm_q_fn(2.05), "^", color="#D55E00", markersize=8)
ax.plot(2, nm_f_fn(2), "s", color="#0072B2", markersize=8)
ax.set_ylim(-8, 0)
#> (-8.0, 0.0)
ax.set_xlabel("x")
ax.set_ylabel("value")
plt.show();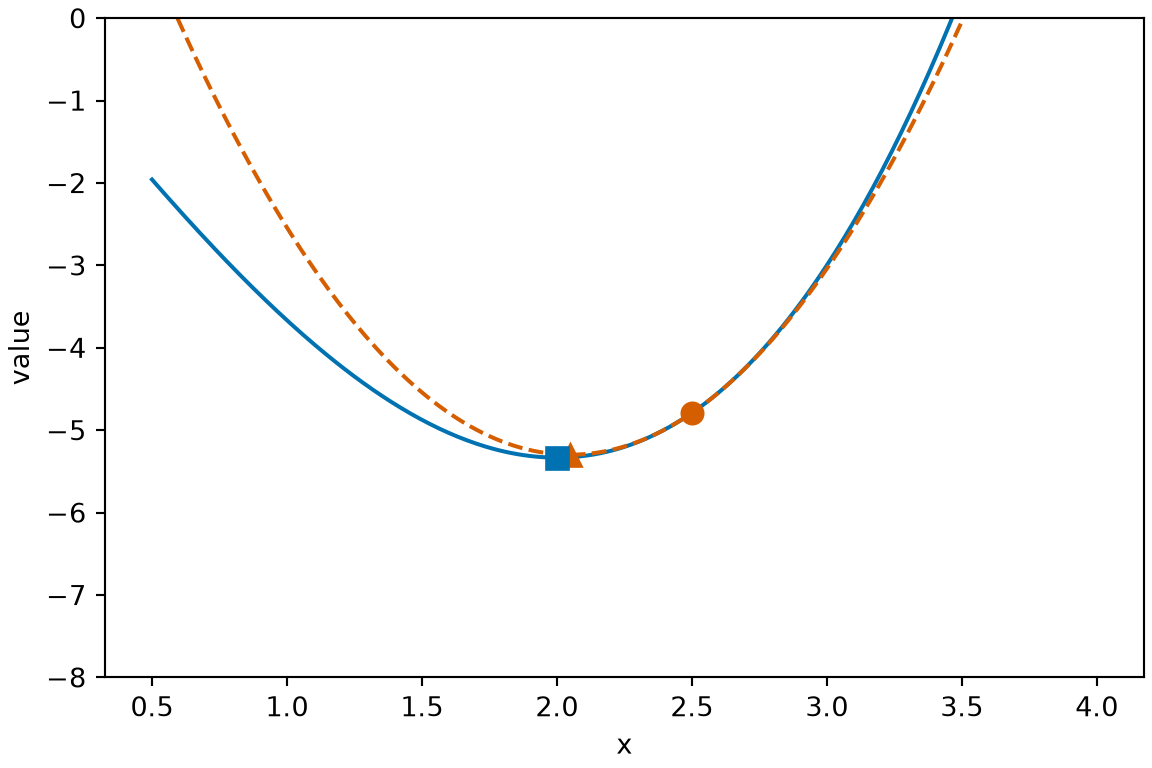
Definition 8 (Quadratic convergence) A sequence \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)}, \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(1)}, \ldots\) in \(\mathbb{R}^p\) that converges (Definition 4) to \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^*\) converges quadratically [4] if there is a constant \(C\) with
\[ \mathopen{}\left\lVert\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t+1)} - \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^*\right\rVert\mathclose{} \le C\,\mathopen{}\left\lVert\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(t)} - \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^*\right\rVert\mathclose{}^2 \qquad \text{for every } t. \]
Example 5 (Halving the error is not quadratic convergence) \(x^{(t)} = 2^{-t}\) converges to \(0\), but it does not converge quadratically: the bound would need \(2^{-(t+1)} \le C\,(2^{-t})^2 = C\,2^{-2t}\), that is, \(2^{t - 1} \le C\), which fails once \(t > 1 + \log_2 C\). Each step only halves the error.
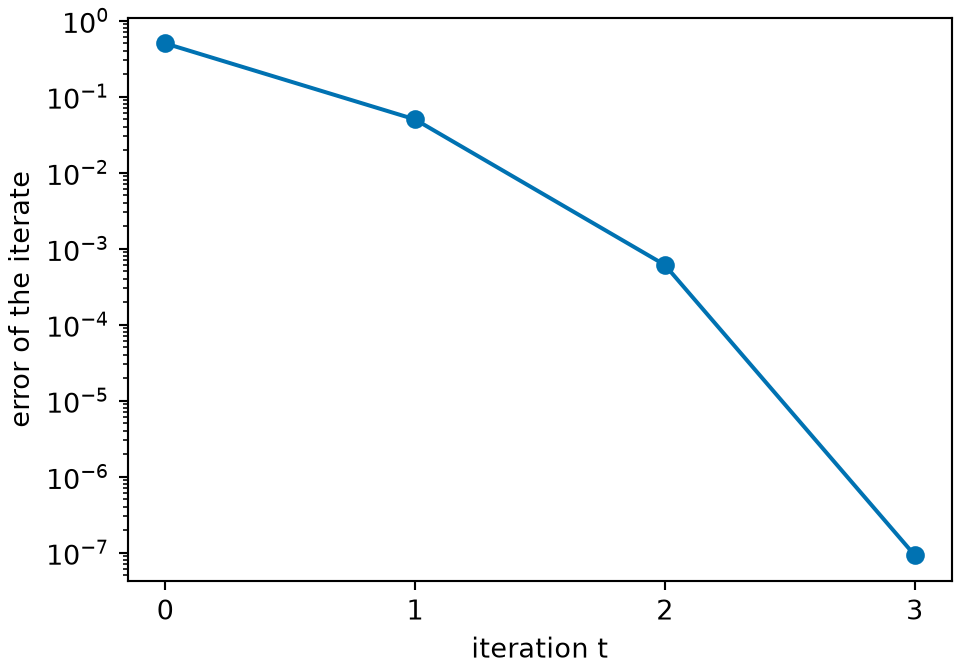
Example 6 (The error squares at each step) For the iteration \(x^{(t+1)} = \tfrac{1}{2} (x^{(t)} + 4 / x^{(t)})\) of Example 2,
\[ \begin{aligned} x^{(t+1)} - 2 &= \frac{1}{2} \mathopen{}\left(x^{(t)} + \frac{4}{x^{(t)}}\right)\mathclose{} - 2 && \text{(the iteration)} \\ &= \frac{(x^{(t)})^2 + 4 - 4 x^{(t)}}{2 x^{(t)}} && \text{(common denominator)} \\ &= \frac{(x^{(t)} - 2)^2}{2 x^{(t)}}. && \text{(the numerator is a perfect square)} \end{aligned} \]
So near \(2\) the error is roughly squared and divided by \(4\) at each step: the errors are \(0.05\), then \(0.00061\), then \(0.000000093\), and \(0.05^2 / (2 \cdot 2.05) \approx 0.00061\). The iterates converge quadratically (Definition 8): \(C = \tfrac{1}{2}\) works for every \(x^{(t)} \ge 1\), since then \(\tfrac{1}{2 x^{(t)}} \le \tfrac{1}{2}\), and every iterate from \(2.5\) is at least \(2\), since the identity makes \(x^{(t+1)} - 2 \ge 0\) whenever \(x^{(t)} > 0\). Zhou [1] states such a bound for Newton’s method in general; it holds from starting points close enough to a minimizer where the Hessian is positive definite, when near that minimizer the Hessian changes by at most a constant times the distance moved, which is not proved here.
[Code]
nc_x_nc <- numeric(4)
nc_x_nc[1] <- 2.5
for (nc_t_nc in 1:3) {
  nc_prev_nc <- nc_x_nc[nc_t_nc]
  nc_x_nc[nc_t_nc + 1] <- 0.5 * (nc_prev_nc + 4 / nc_prev_nc)
}
nc_steps_nc <- tibble::tibble(t = 0:3, error = nc_x_nc - 2)
ggplot2::ggplot(nc_steps_nc, ggplot2::aes(t, error)) +
  ggplot2::geom_line(colour = "#0072B2") +
  ggplot2::geom_point(colour = "#0072B2", size = 3) +
  ggplot2::scale_y_log10() +
  ggplot2::labs(x = "iteration t", y = "error of the iterate")
[Code]
import matplotlib.pyplot as plt

nc_x_ax = [2.5]
for _ in range(3):
    nc_x_ax.append(0.5 * (nc_x_ax[-1] + 4 / nc_x_ax[-1]))
nc_err_ax = [x - 2 for x in nc_x_ax]
fig, ax = plt.subplots(figsize=(5, 3.5), layout="constrained")
ax.semilogy(range(4), nc_err_ax, "o-", color="#0072B2")
#> [<matplotlib.lines.Line2D object at 0x7f384cd06490>]
ax.set_xlabel("iteration t")
#> Text(0.5, 0, 'iteration t')
ax.set_ylabel("error of the iterate")
#> Text(0, 0.5, 'error of the iterate')
ax.set_xticks(range(4))
#> [<matplotlib.axis.XTick object at 0x7f384ef0bed0>, <matplotlib.axis.XTick object at 0x7f384ef0b610>, <matplotlib.axis.XTick object at 0x7f384cd06c10>, <matplotlib.axis.XTick object at 0x7f384cd07390>]
plt.show();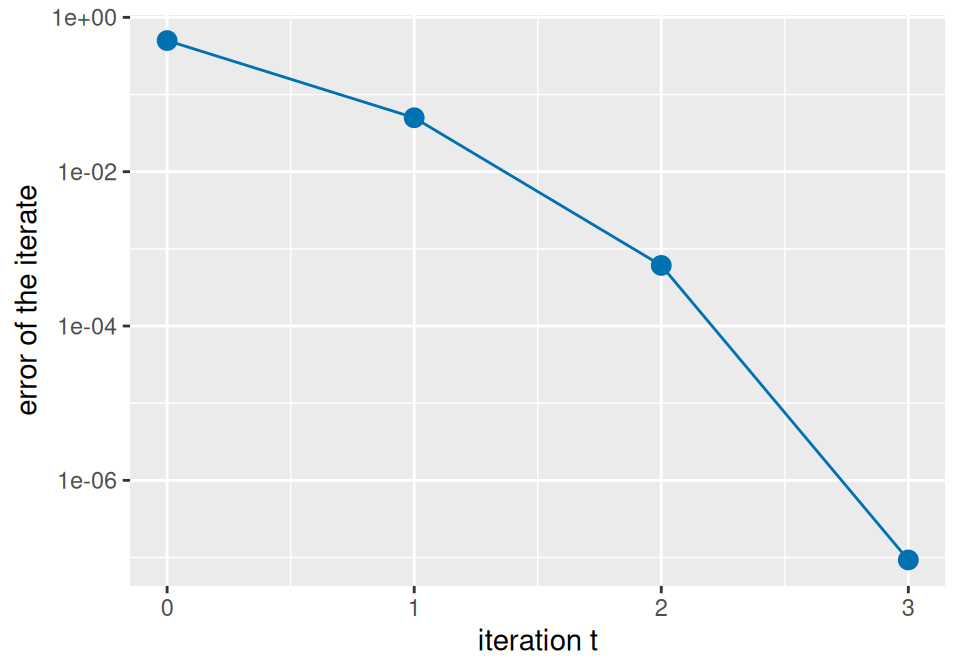
Example 7 (Newton’s method can find a maximum) From \(x^{(0)} = -2.5\) the same iteration gives \(-2.05\), \(-2.000610\), \(-2.0000001\), approaching \(-2\). But \(-2\) is not a minimizer of \(f\): it is a stationary point of \(-f\), whose second derivative there is \(-f''(-2) = 4 > 0\), so it is a strict local minimizer of \(-f\) (Theorem 7 in Critical Points and Optimality Conditions), that is, \(f\) is strictly larger at \(-2\) than at all nearby points. Newton’s method looks only for a stationary point, and here the Hessian \(f''(x) = 2x\) is negative along the way, so the quadratic model has no minimizer (with \(H < 0\), \(q(\delta) = f + g\,\delta+ \tfrac{1}{2} H \delta^2\) decreases without bound) and Theorem 1 does not apply: the positive definite hypothesis there is needed.
Theorem 2 (Newton’s method minimizes a quadratic in one step) Let \(\mathbf{S}\) be a \(p \times p\) positive definite matrix, \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}} \in \mathbb{R}^p\), and \(f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = \tfrac{1}{2}\,{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}}^{\top} \mathbf{S} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}} - \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}} \cdot \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\). From any \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)}\), Newton’s method (Definition 5) gives \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(1)} = \mathbf{S}^{-1} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}}\), the unique minimizer of \(f\).
Proof. Partial derivatives of a sum or of a constant multiple are the sum or multiple of the partial derivatives, so the derivative of a quadratic form applies to \(\tfrac{1}{2}\,{\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}}^{\top} \mathbf{S} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\) and the derivative of a linear combination to \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}} \cdot \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}\):
\[ \begin{aligned} \frac{\partial}{\partial \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}} f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) &= \tfrac{1}{2} (2 \mathbf{S} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) - \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}} \\ &= \mathbf{S} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}- \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}}; \end{aligned} \]
by the Hessian of a quadratic form with \(\tfrac{1}{2} \mathbf{S}\) in place of \(\mathbf{S}\), and because the gradient \(-\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}}\) of the linear term is constant, \(\mathbf{H}_f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = \mathbf{S}\), which is invertible. So
\[ \begin{aligned} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(1)} &= \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)} - \mathbf{S}^{-1} (\mathbf{S} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)} - \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}}) && \text{(definition of Newton's method)} \\ &= \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)} - \mathbf{S}^{-1} \mathbf{S} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)} + \mathbf{S}^{-1} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}} && \text{(distribute)} \\ &= \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)} - \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)} + \mathbf{S}^{-1} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}} && \text{(} \mathbf{S}^{-1} \mathbf{S} = \mathbf{I}_p \text{)} \\ &= \mathbf{S}^{-1} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}}. && \text{(cancel)} \end{aligned} \]
The gradient at \(\mathbf{S}^{-1} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}}\) is \(\mathbf{S} \mathbf{S}^{-1} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}} - \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}} = \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{0}}\vphantom{0}}_{p \times 1}\), and \(f\) is strictly convex (Theorem 5 in Convexity in Several Variables, part 2), so \(\mathbf{S}^{-1} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}}\) is a global minimizer (Corollary 1 in Convexity in Several Variables). It is the only one: a strictly convex function has at most one global minimizer, since the midpoint of two distinct global minimizers, which have equal values, would have a strictly smaller value (Definition 3 in Convexity in Several Variables with \(t = \tfrac{1}{2}\)).
Example 8 (One step to the minimizer) Let \(f(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}) = \tfrac{1}{2} (x_1^2 + 3 x_2^2)\), so \(\mathbf{S} = \begin{bmatrix} 1 & 0 \\ 0 & 3 \end{bmatrix}\) and \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{c}}\vphantom{c}} = \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{0}}\vphantom{0}}_{2 \times 1}\). From \(\mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)} = {(3, 1)}^{\top}\) the gradient is \(\mathbf{S} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(0)} = {(3, 3)}^{\top}\), and \(\mathbf{S}^{-1} = \begin{bmatrix} 1 & 0 \\ 0 & 1/3 \end{bmatrix}\), so the Newton step is \(-\mathbf{S}^{-1} {(3, 3)}^{\top} = -{(3, 1)}^{\top}\) and
\[ \begin{aligned} \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{x}}\vphantom{x}}^{(1)} &= {(3, 1)}^{\top} - {(3, 1)}^{\top} \\ &= \mathord{\smash[b]{\underset{\raise.3ex\hbox{$\scriptstyle\sim$}}{0}}\vphantom{0}}_{2 \times 1}, \end{aligned} \]
the minimizer.
[1]
H. Zhou, “Optimization and multivariate calculus.” Lecture notes for Biostat 216, Mathematical Methods for Biostatistics, University of California, Los Angeles, 2024. Accessed: Oct. 05, 2026. [Online]. Available: https://ucla-biostat-216.github.io/2024fall/slides/13-optim/13-optim.html
[2]
Wikipedia contributors, “Iterative method — Wikipedia, the free encyclopedia.” 2026. Available: https://en.wikipedia.org/wiki/Iterative_method
[3]
Wikipedia contributors, “Newton’s method in optimization — Wikipedia, the free encyclopedia.” 2026. Available: https://en.wikipedia.org/wiki/Newton%27s_method_in_optimization
[4]
Wikipedia contributors, “Rate of convergence — Wikipedia, the free encyclopedia.” 2026. Available: https://en.wikipedia.org/wiki/Rate_of_convergence